30 秒でわかる
Matthew Berman introduces LLM Colosseum, an open-source project that uses a fighting-game emulator to pit language models against each other. He reviews the project’s historical ranking, speculates that response speed matters and demonstrates the installation and one match. The displayed results are specific to this real-time game harness and do not establish a general ranking of model capability.
- 1A real-time matchBerman shows Mistral Small against Mistral Medium and speculates that faster responses can matter.
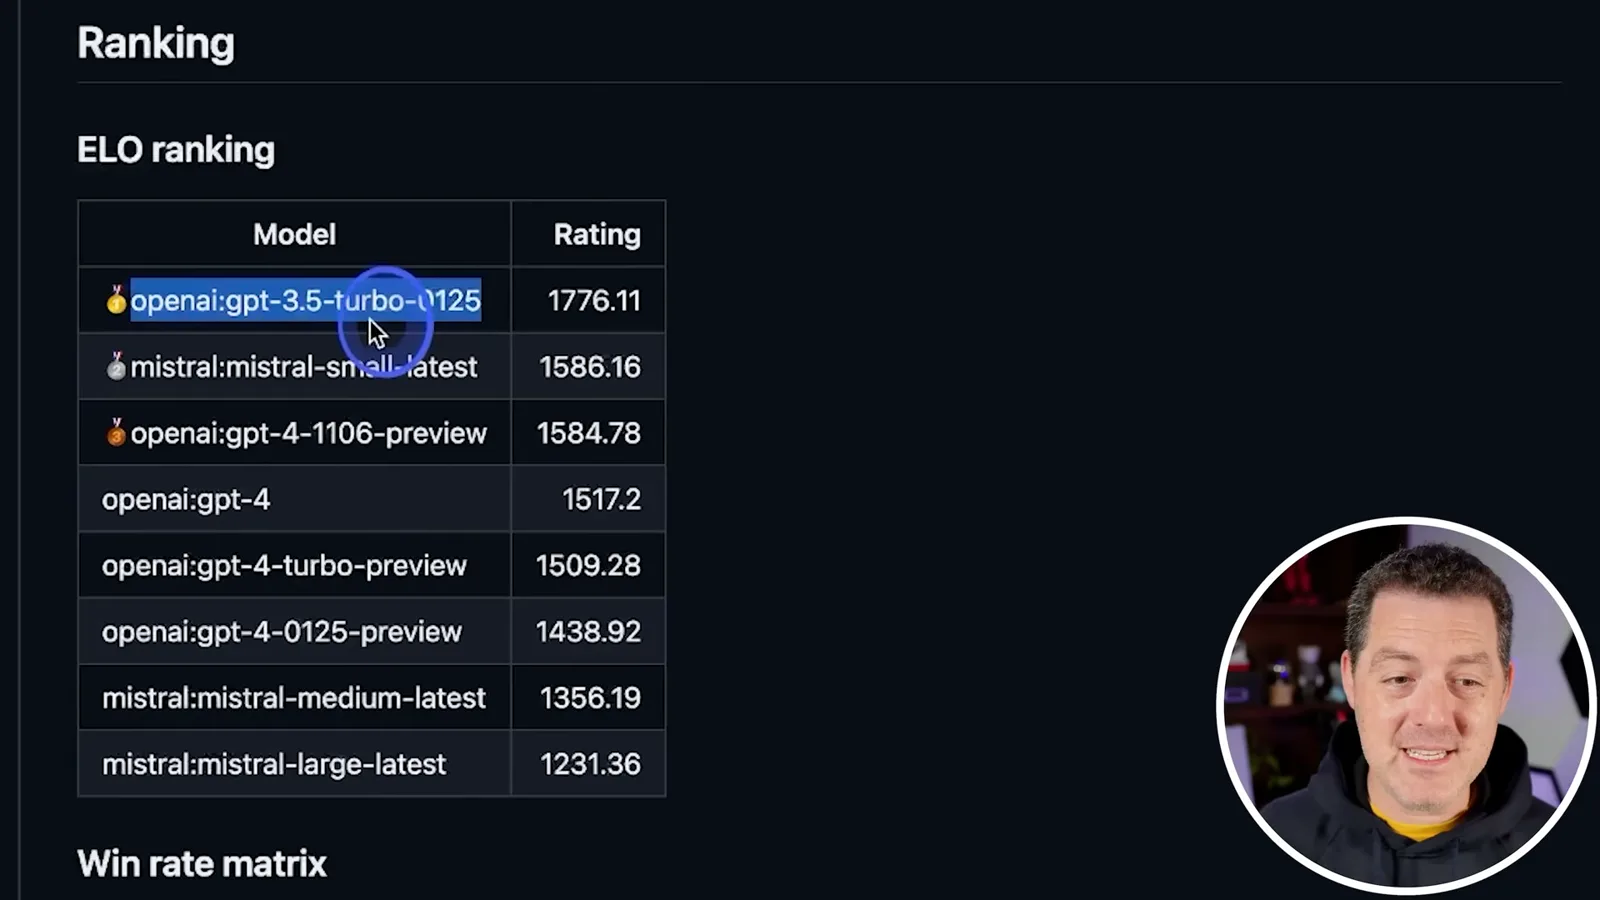
- 2A historical leaderboardThe snapshot ranks GPT-3.5 Turbo above the other displayed models for this game, not for all tasks.
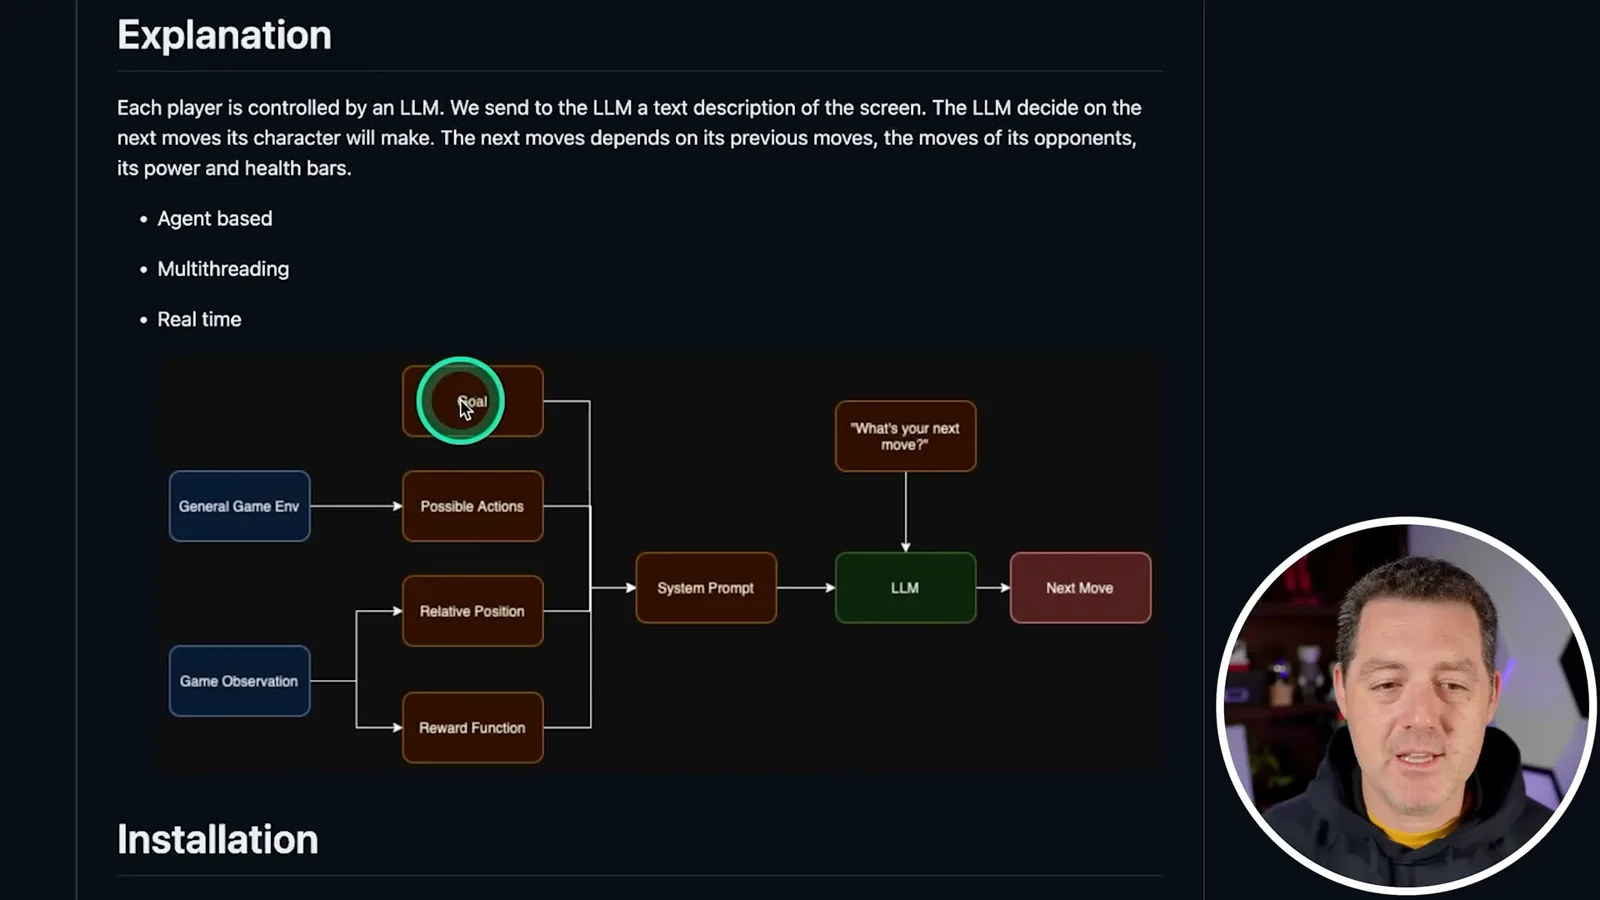
- 3Game state to next moveThe harness turns observations and possible actions into a text prompt, then executes the model’s chosen move.
- 4Setting up the emulatorThe walkthrough uses DIAMBRA Arena, Docker and a Python environment before configuring model APIs.
- 5One demonstration resultBerman reports a Mistral win in the displayed match; one game does not establish broad model superiority.
ポイント
- LLM Colosseum sends text descriptions of game state to models and executes their selected moves.
- The displayed 2024 leaderboard is specific to the project’s fighting-game evaluation.
- Berman suspects inference speed affects outcomes, but does not isolate it experimentally.
- The walkthrough uses DIAMBRA Arena, Docker, Python, a compatible ROM and model API credentials.
- A single demo match does not determine general model quality.
チャプターごとに整えた全文を読む
Models fight in Street Fighter III
Berman introduces LLM Colosseum, a match and the historical ranking. He speculates about the importance of response speed.
LLM Colosseum pits language models against each other in Street Fighter III, with each model choosing moves during the game. Stan Girard and the Quivr team created the open-source project. It is an entertaining alternative way to compare model behavior, and I will also show the setup used in April 2024.
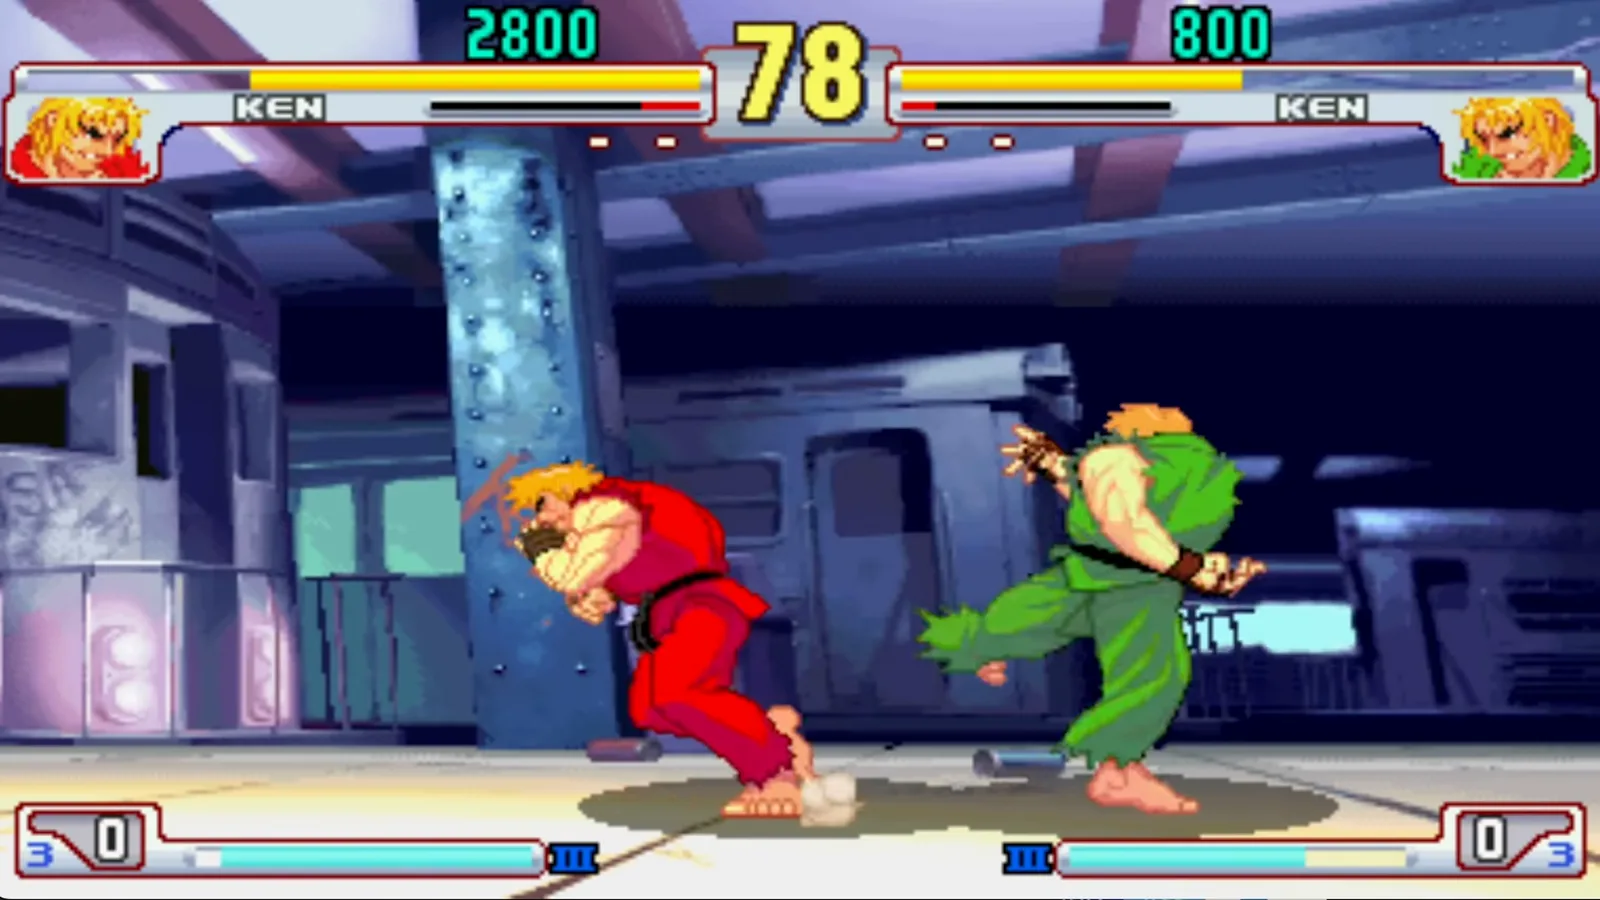
In the opening match, I identify red Ken as Mistral Small and green Ken as Mistral Medium; Small wins. I suspect response speed plays a major role in a real-time fighting game and may help explain why smaller models sometimes win. That is my interpretation, not an isolated measurement proving speed caused the result.
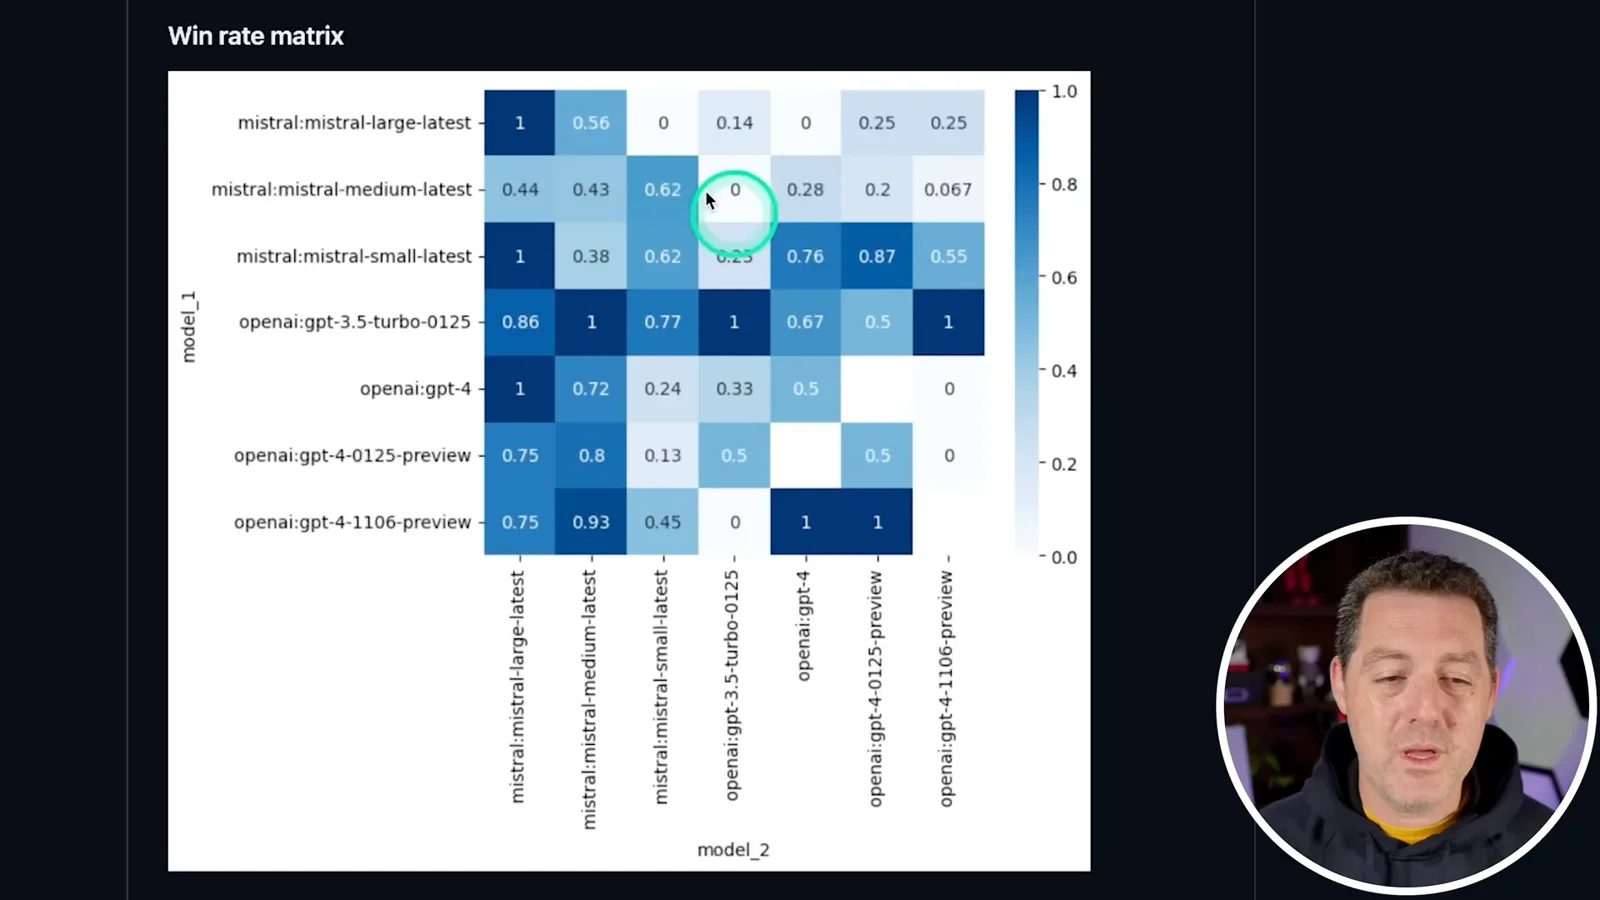
The project presents Elo rankings and a head-to-head win-rate matrix. In the snapshot shown, GPT-3.5 Turbo leads several GPT-4 and Mistral models. I find that surprising, but I am not sure exactly what the benchmark measures; rankings in this particular game should not be treated as a general ranking of language-model intelligence.
How the game harness works
The project turns game observations and possible actions into text prompts for each model. The emulator then executes the selected moves.
The creators propose speed, strategic thinking, adaptability and resilience as relevant traits. The system turns game observations, available actions and goals into a prompt; each model receives a text description of the game state and selects the next move. A game emulator executes those actions in real time.
Installation and a demo match
Berman walks through DIAMBRA, Docker, Python and API setup. He configures models and shows one match, whose outcome is specific to that run.
To set it up, I clone the LLM Colosseum repository in VS Code and install the DIAMBRA Arena emulator. I register for its service, install Docker and create a conda environment with Python 3.10. After activating the environment, I install DIAMBRA Arena and list supported ROMs to check the installation.
The tutorial requires a compatible game ROM placed as a ZIP file in the emulator’s ROMs folder. I do not provide a download location and discuss game ownership. Rights to obtain and use a ROM depend on the applicable license and law; owning a physical copy alone does not establish permission to download any copy.
I install the LLM Colosseum requirements, reopen the project and reactivate the conda environment. I rename the example environment file to .env and configure API credentials for OpenAI and Mistral. The recording’s keys are described as being revoked before publication; the tutorial’s service interfaces and model names reflect 2024.
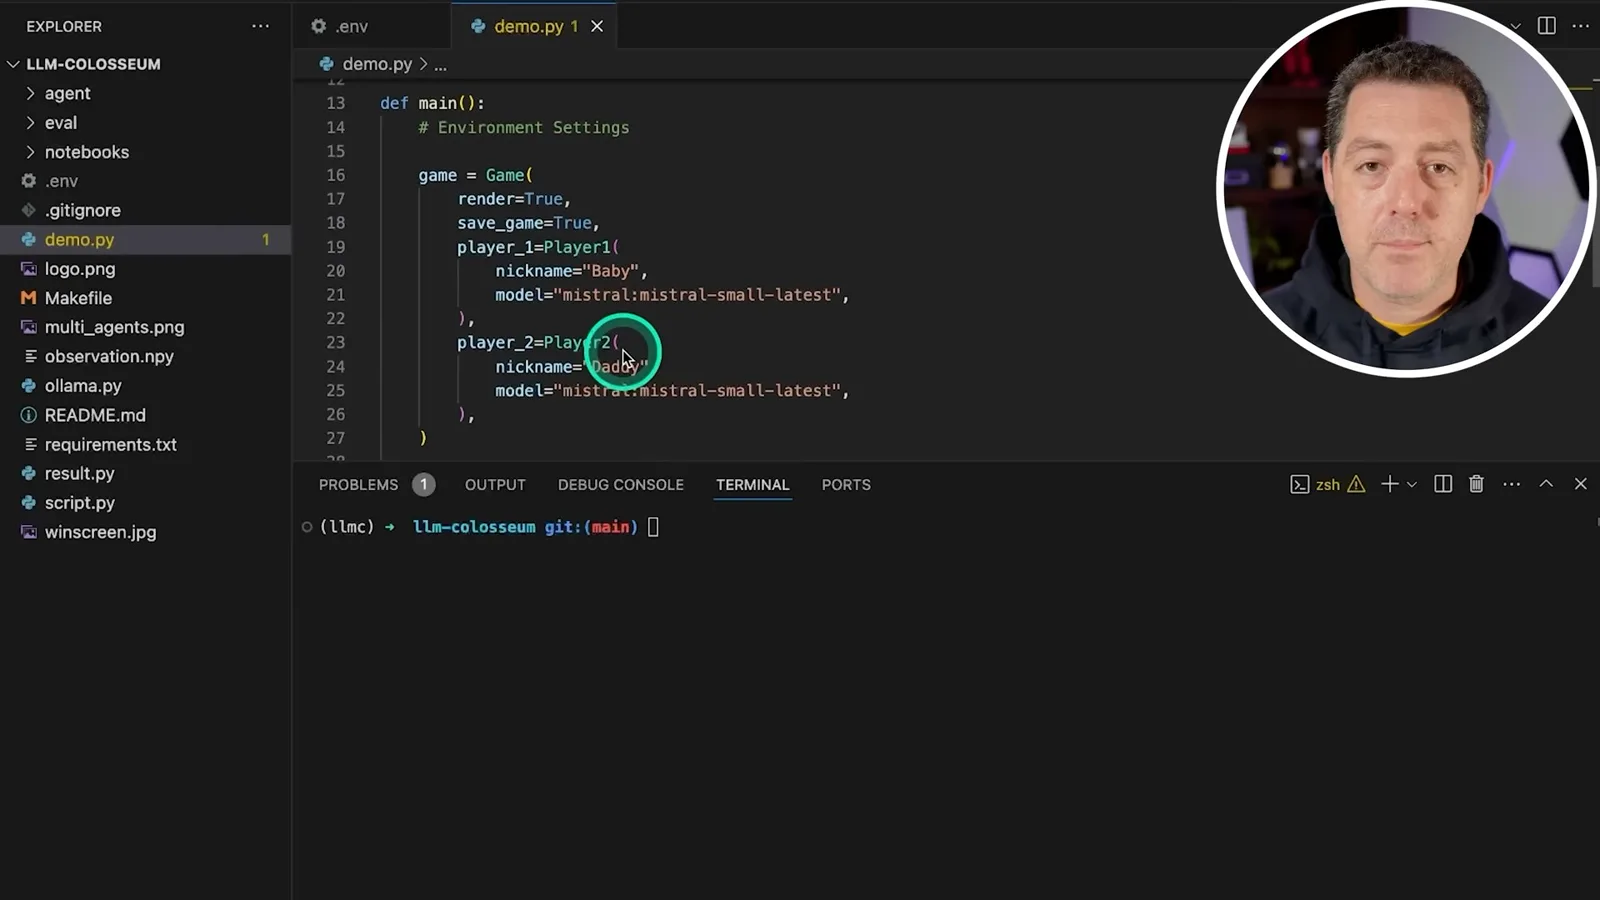
In demo.py I configure one player to use a Mistral model and the other GPT-3.5 Turbo, then run the demo. A first run may require a DIAMBRA login, and the emulator takes some time to start. In the match shown, I initially mix up the player colors before correcting myself.
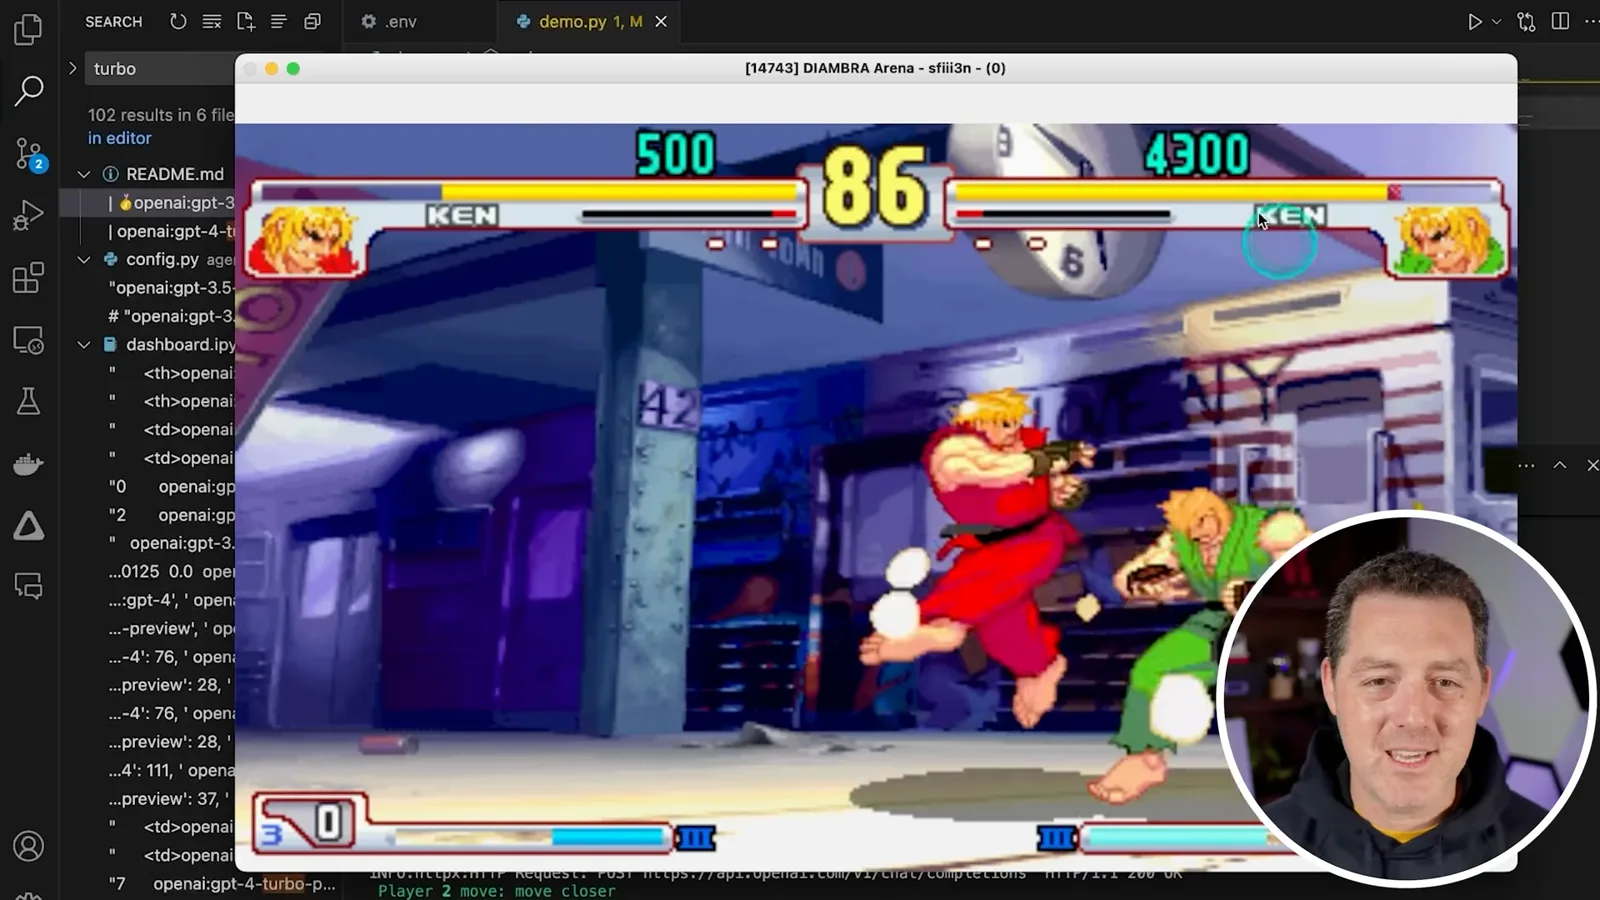
The models choose moves as the two Ken characters fight. I say Mistral wins this particular match and note that the project at the time offers only Ken in this setup. One match and the displayed leaderboard are examples of this game harness, not controlled evidence that a model is better at other tasks.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026年10月21日A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.