30 秒でわかる
Berman reviews the Pixtral 12B launch and tests image description, screenshot reading, code generation and visual localization. He finds several useful results and several failures; his tests are informal, and Vultr sponsored the video and hosted the model.
- 1Pixtral’s launchThe 12B model combines text and image inputs under an Apache 2.0 release.
- 2Text tests failA Tetris program raises an error and a letter-count question is answered incorrectly.
- 3Screenshot readingThe model reads some storage totals but misinterprets a download icon.
- 4A harder pageThe generated page misses images and the original horizontal layout.
- 5Visual localizationAfter follow-up, the host judges approximate coordinates for Waldo to be correct.
ポイント
- Pixtral 12B was presented as an Apache 2.0 multimodal model with support for varying image sizes.
- Mistral’s reported benchmark results and the host’s examples cover particular 2024 models and tasks.
- The model reads some screenshot content but misinterprets a download icon.
- Generated code works for a simple mockup but misses important details in a more complex page.
- Individual CAPTCHA or localization examples cannot establish performance across all such tasks.
チャプターごとに整えた全文を読む
Pixtral and the test setup
Berman introduces Mistral’s release and the sponsor-provided cloud GPU. He reviews reported benchmarks and tries two text tasks.
In this September 2024 video I try Mistral AI’s Pixtral 12B, a vision-language model, using a cloud GPU hosted by Vultr, the video’s sponsor. I review the release and run a set of informal text and image prompts; the sponsorship is relevant context for the hosting demonstration.
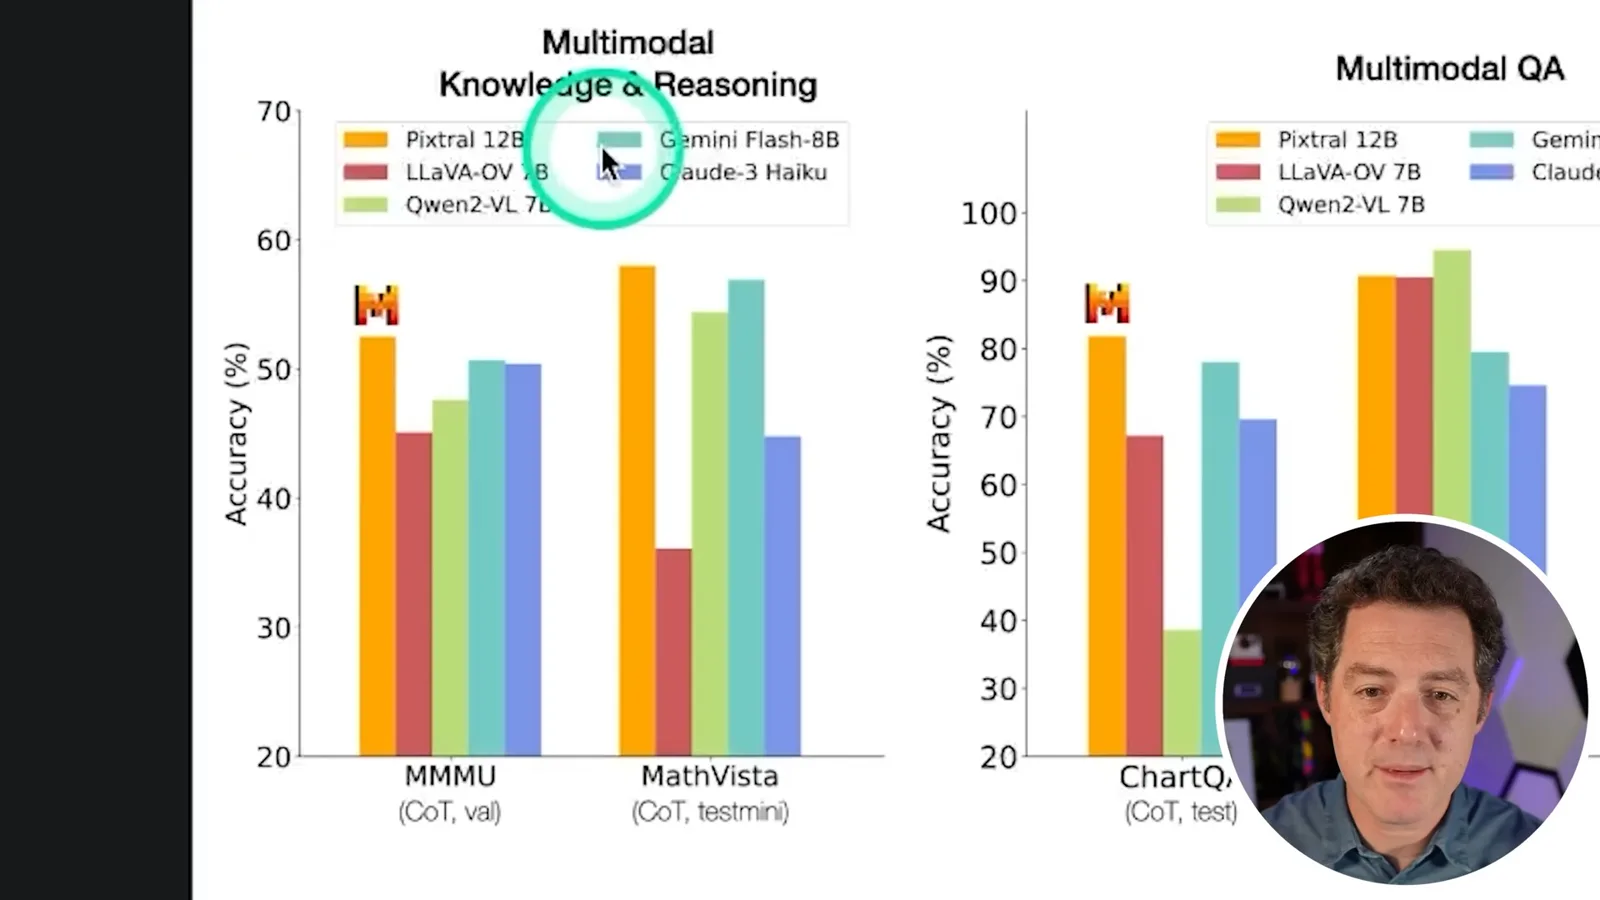
Mistral describes Pixtral as a 12-billion-parameter multimodal model released under Apache 2.0, supporting images of varying sizes and multiple images in a long context. I review company-provided benchmark comparisons with contemporary models; those figures are limited to the reported tests and settings.
I run the model on a 48 GB Nvidia L40 through an API-compatible backend with Open WebUI. This is a cloud-hosted test rather than a measurement of performance on an ordinary local device.
A text-only request for a Python Tetris game produces code that fails with an attribute error. The model also miscounts the letters in “strawberry.” Two isolated failures are not a complete assessment of its coding or reasoning ability.
Image understanding
He tests descriptions, screenshot reading and a meme. The results include both correct-looking answers and a missed icon.
For image description, the model describes a llama resting in a field. It also identifies a public figure in another picture, according to my test; such a result is a single example, not a guarantee that visual identification is reliable.
The video includes a CAPTCHA-reading test and I report an apparent success. That individual example does not show that CAPTCHAs as a category are defeated or that a model will perform similarly across challenges.
Using a phone-storage screenshot, I ask about capacity and used space, and the model reads the displayed totals. I then ask which app is not downloaded; it answers incorrectly, failing to interpret the cloud icon in the way I expected.
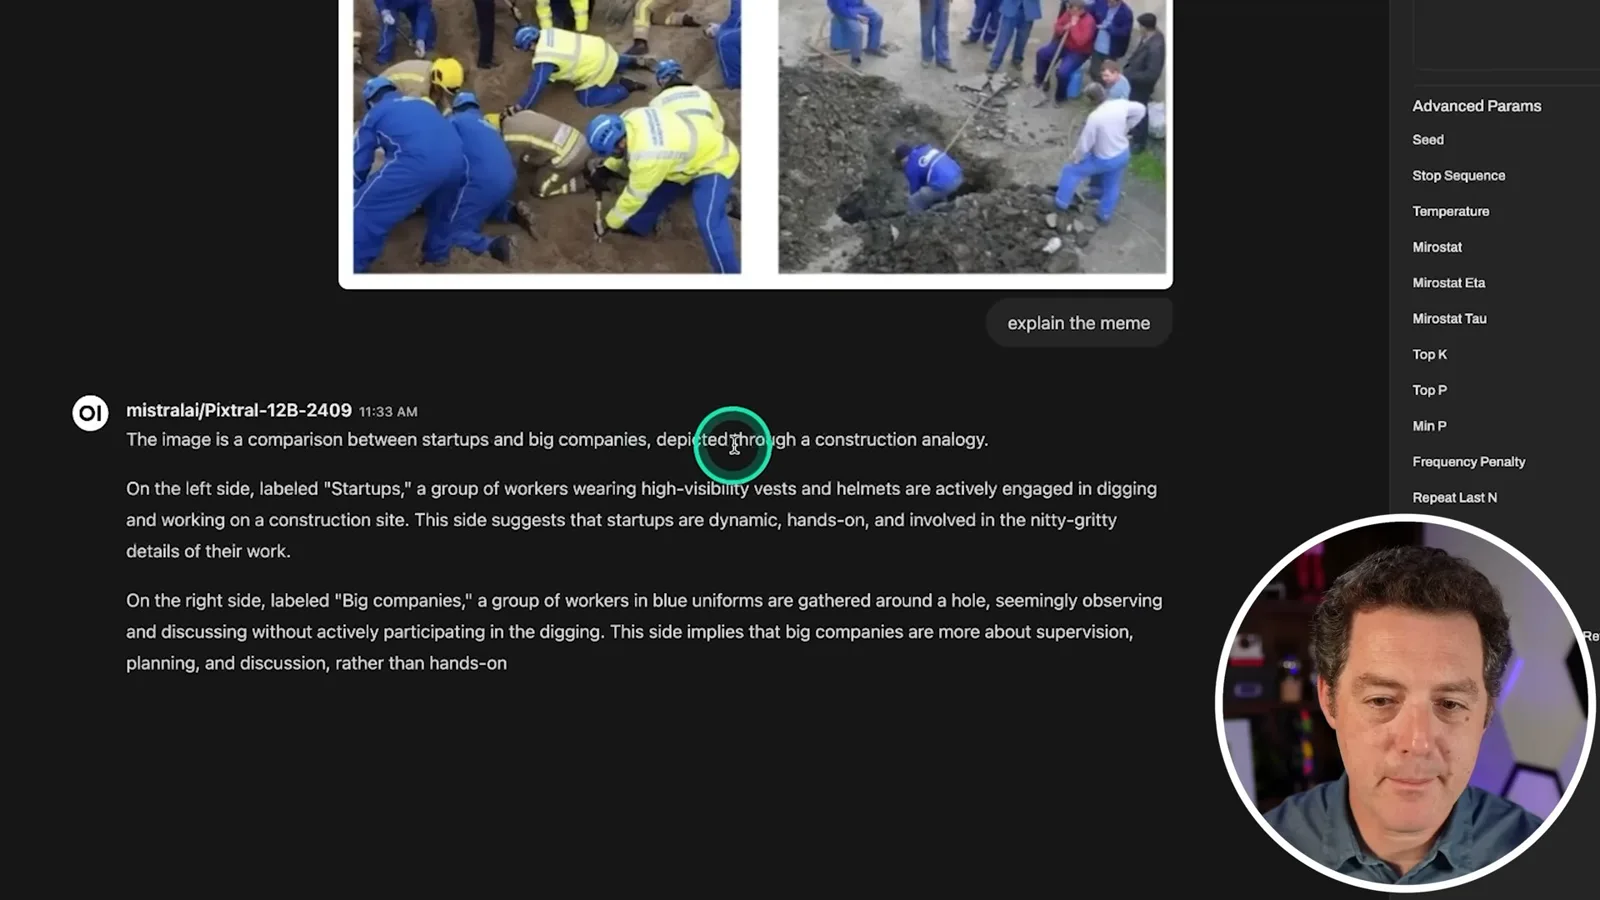
The model lists applications and storage amounts from the screenshot, then describes a meme contrasting workers at startups and large companies. I find its explanation of the visual joke plausible; this remains a small, subjective sample.
I speculate that people may increasingly route work to specialized models: vision to one, reasoning or coding to another, depending on capability, cost and latency. This is my forecast, not a result demonstrated by a single model test.
Tables, interfaces and localization
He tries a QR code, a table, two interface mockups and a crowded image. Results vary substantially across the examples.
When asked what URL a QR code resolves to, the model says it cannot determine the destination from the image. In another test, it converts a screenshot of a table to CSV, which I judge largely correct.
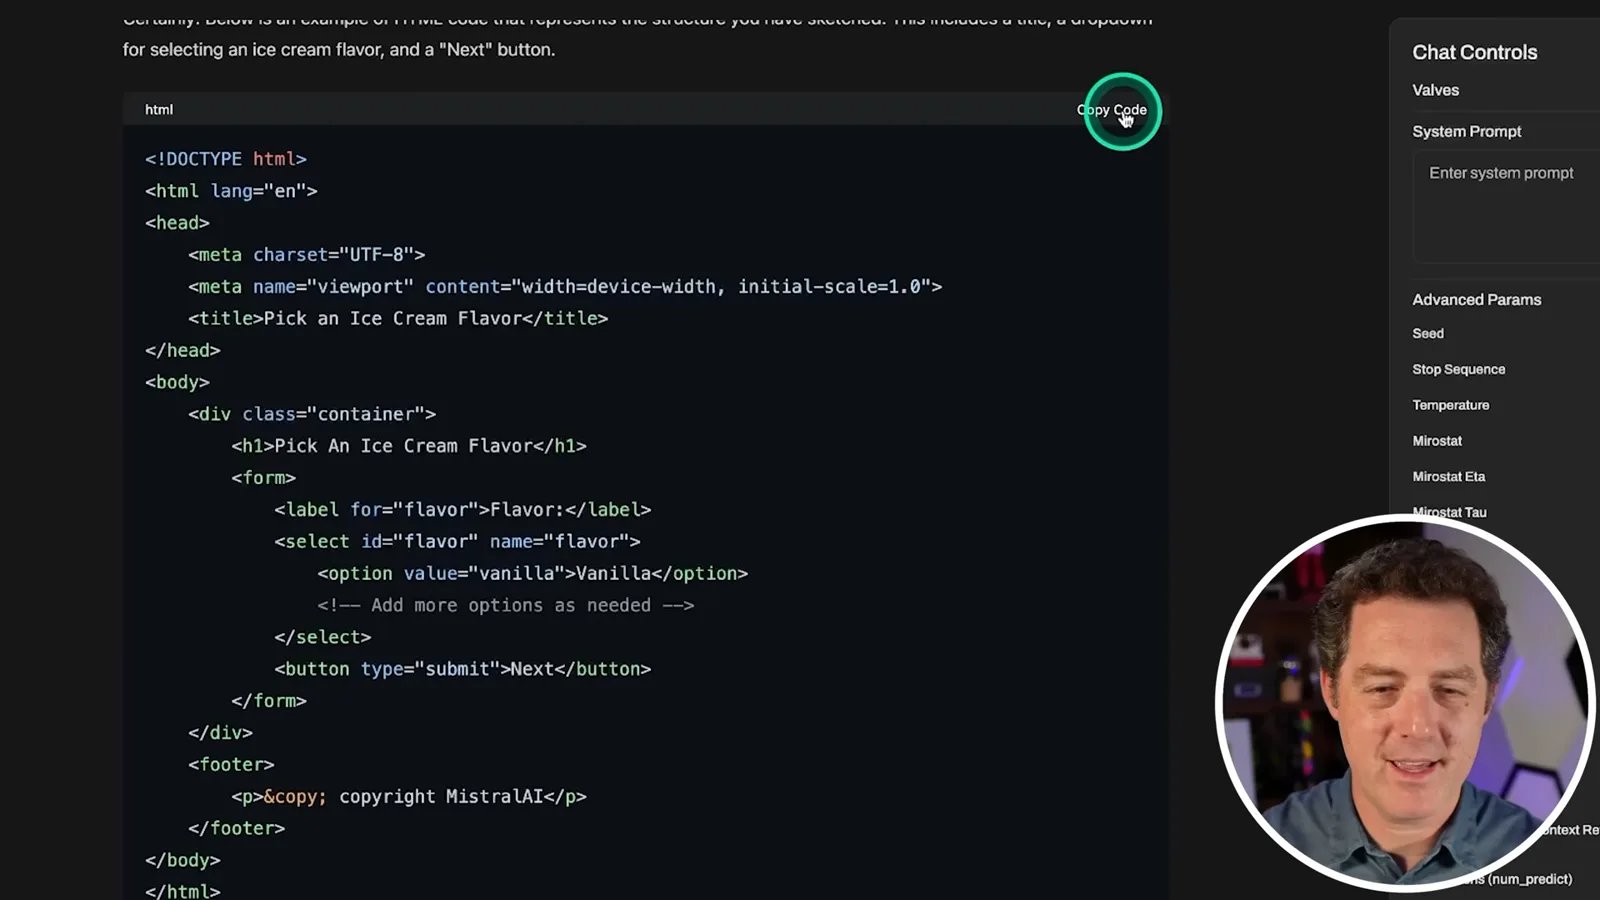
I ask Pixtral to generate HTML from a hand-drawn interface. The resulting simple page includes a dropdown and button and appears to work in my brief test, although this does not establish production-ready code.
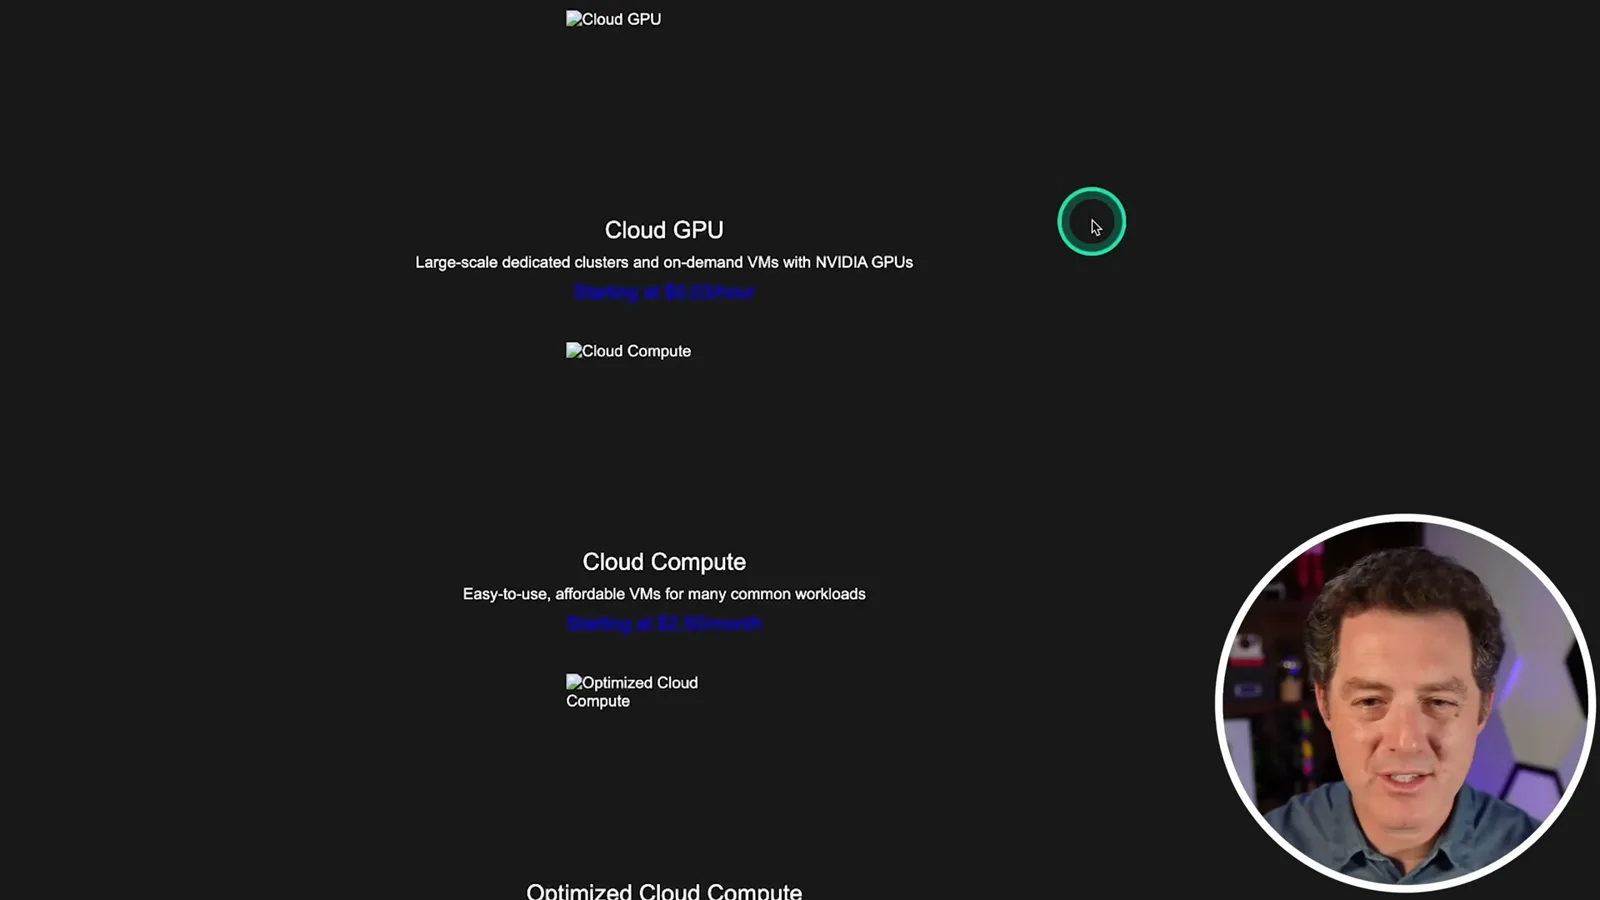
A more complicated website screenshot leads to a weaker reproduction: the generated page captures some text but lacks images and arranges items vertically rather than in the original layout. I regard that attempt as only partially successful.
For a crowded Where’s Waldo image, the first answer explains the game rather than locating the character. After follow-up prompts, the model proposes approximate coordinates; I believe they point to Waldo, though a single low-resolution example is not a robust localization benchmark.
I conclude that Pixtral’s visual capabilities are promising while noting the text and interface-generation failures. The results are anecdotal and specific to the 2024 model version, prompts and deployment shown in the video.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026年10月25日Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026年10月25日Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026年10月24日An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.