30 秒でわかる
Berman discusses the August 2025 release of gpt-oss models and a reported competitive-coding chart. The figures are benchmark-specific and do not establish general programming ability or that all training materials are open.
- 1Two model sizesBerman introduces the 120B and 20B variants.
- 2Coding comparisonThe launch chart compares models under tool-enabled settings.
- 3Smaller modelThe 20B model’s reported rating is lower than the larger model’s but competitive in this chart.
ポイント
- The release included 120B and 20B open-weight model variants.
- The chart reports Codeforces-style ratings with and without tools.
- Benchmark results depend on the evaluation setup and are not universal measures of coding.
- Open weights do not necessarily mean that the complete training data and process were released.
チャプターごとに整えた全文を読む
Open-weight release
Berman introduces gpt-oss and its model sizes.
OpenAI has released gpt-oss in 120-billion- and 20-billion-parameter versions. I call them open-weight models: their weights are available, though that alone does not imply that every part of their training data or process was released.
Reported coding scores
He compares Codeforces ratings shown in the release chart.
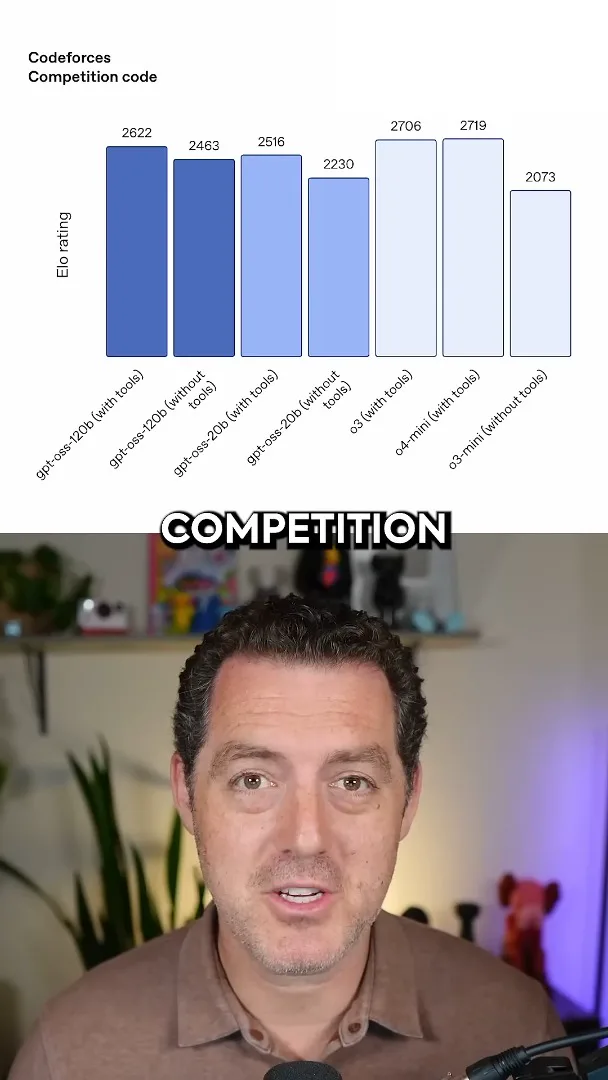
The launch chart reports Codeforces-style ratings of 2,622 for gpt-oss-120b with tools and 2,706 for o3 with tools. I regard the results as close, but they concern this particular competitive-coding evaluation and setup.
The chart also gives gpt-oss-20b a 2,516 rating with tools. I find that impressive for its size. The chart does not independently establish a model’s performance across all coding tasks or its standing against the entire human population.
同じチャンネルの記事
 34:21EN
 Matthew Berman· 2026年10月27日Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· 2026年10月24日Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026年10月23日Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 2026年10月23日Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 2026年10月22日Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· 2026年10月21日A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.