En 30 segundos
Berman discusses the August 2025 release of gpt-oss models and a reported competitive-coding chart. The figures are benchmark-specific and do not establish general programming ability or that all training materials are open.
- 1Two model sizesBerman introduces the 120B and 20B variants.
- 2Coding comparisonThe launch chart compares models under tool-enabled settings.
- 3Smaller modelThe 20B model’s reported rating is lower than the larger model’s but competitive in this chart.
Conclusiones
- The release included 120B and 20B open-weight model variants.
- The chart reports Codeforces-style ratings with and without tools.
- Benchmark results depend on the evaluation setup and are not universal measures of coding.
- Open weights do not necessarily mean that the complete training data and process were released.
Lee el texto editado por capítulos
Open-weight release
Berman introduces gpt-oss and its model sizes.
OpenAI has released gpt-oss in 120-billion- and 20-billion-parameter versions. I call them open-weight models: their weights are available, though that alone does not imply that every part of their training data or process was released.
Reported coding scores
He compares Codeforces ratings shown in the release chart.
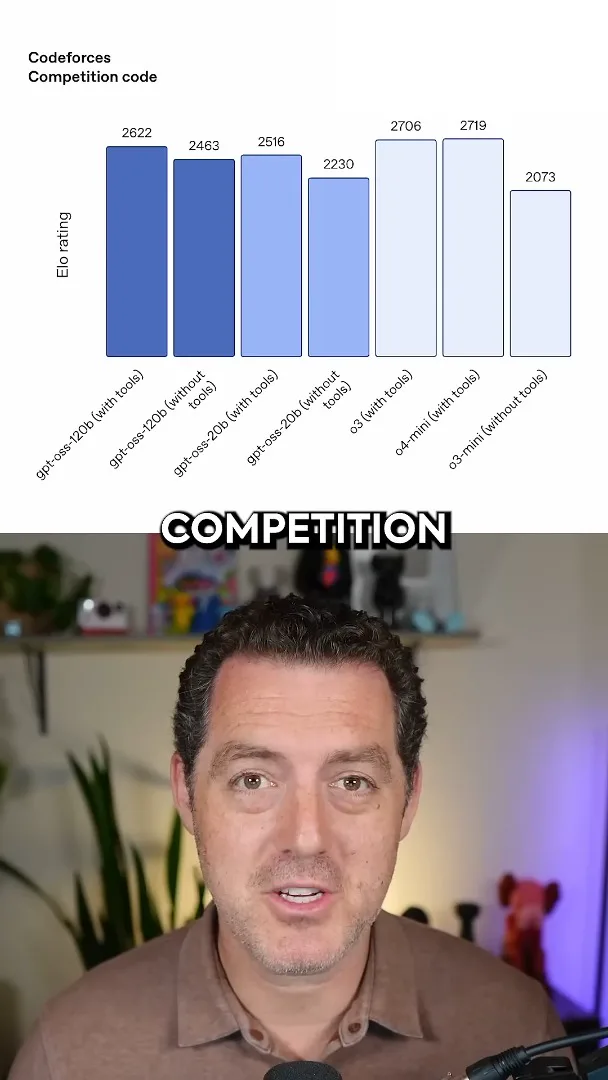
The launch chart reports Codeforces-style ratings of 2,622 for gpt-oss-120b with tools and 2,706 for o3 with tools. I regard the results as close, but they concern this particular competitive-coding evaluation and setup.
The chart also gives gpt-oss-20b a 2,516 rating with tools. I find that impressive for its size. The chart does not independently establish a model’s performance across all coding tasks or its standing against the entire human population.
Más de este canal
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 1:02EN