30 秒でわかる
Berman explains the ArtPrompt research and tests visually encoded text with a language model. The paper’s recognition accuracy and attack-success rates measure different things; both its findings and the host’s experiments concern specific 2024 systems.
- 1Vision in textThe benchmark examines recognition of visual shapes formed with ordinary characters.
- 2Two kinds of metricRecognition accuracy should not be confused with attack success.
- 3Mixed live testsThe host observes both refusals and recognition errors.
ポイント
- The research studies text arranged as visual shapes and introduces a recognition benchmark.
- Recognition accuracy and attack success rate are distinct measures.
- The paper reports vulnerability in the model versions and settings it tested.
- Berman’s own visual-recognition attempts include failures and a refusal.
- A later individual test is anecdotal and does not establish current model behavior.
チャプターごとに整えた全文を読む
The research question
Berman introduces model safety and ASCII-art recognition.
In March 2024 I review the ArtPrompt paper, which studies whether visually encoded text can undermine safety behavior in language models. I also run informal tests; they concern the models and interfaces available then.
I introduce jailbreaks as attempts to obtain responses a model was trained to refuse. Prompt injection and jailbreaks are related security concepts but are not interchangeable: injection concerns untrusted instructions affecting a system, while jailbreaks target safety behavior.
The researchers study ASCII art, where ordinary characters form visual shapes, and propose the Vision-in-Text Challenge to measure recognition. Their paper tests several models available in early 2024.
The paper reports that models struggled with the visual recognition task and evaluates whether such representations affect safety responses. This is an experimental finding about specific model versions and prompts, not proof that every current model is vulnerable.
Metrics and reported results
He compares recognition and attack studies across model versions.
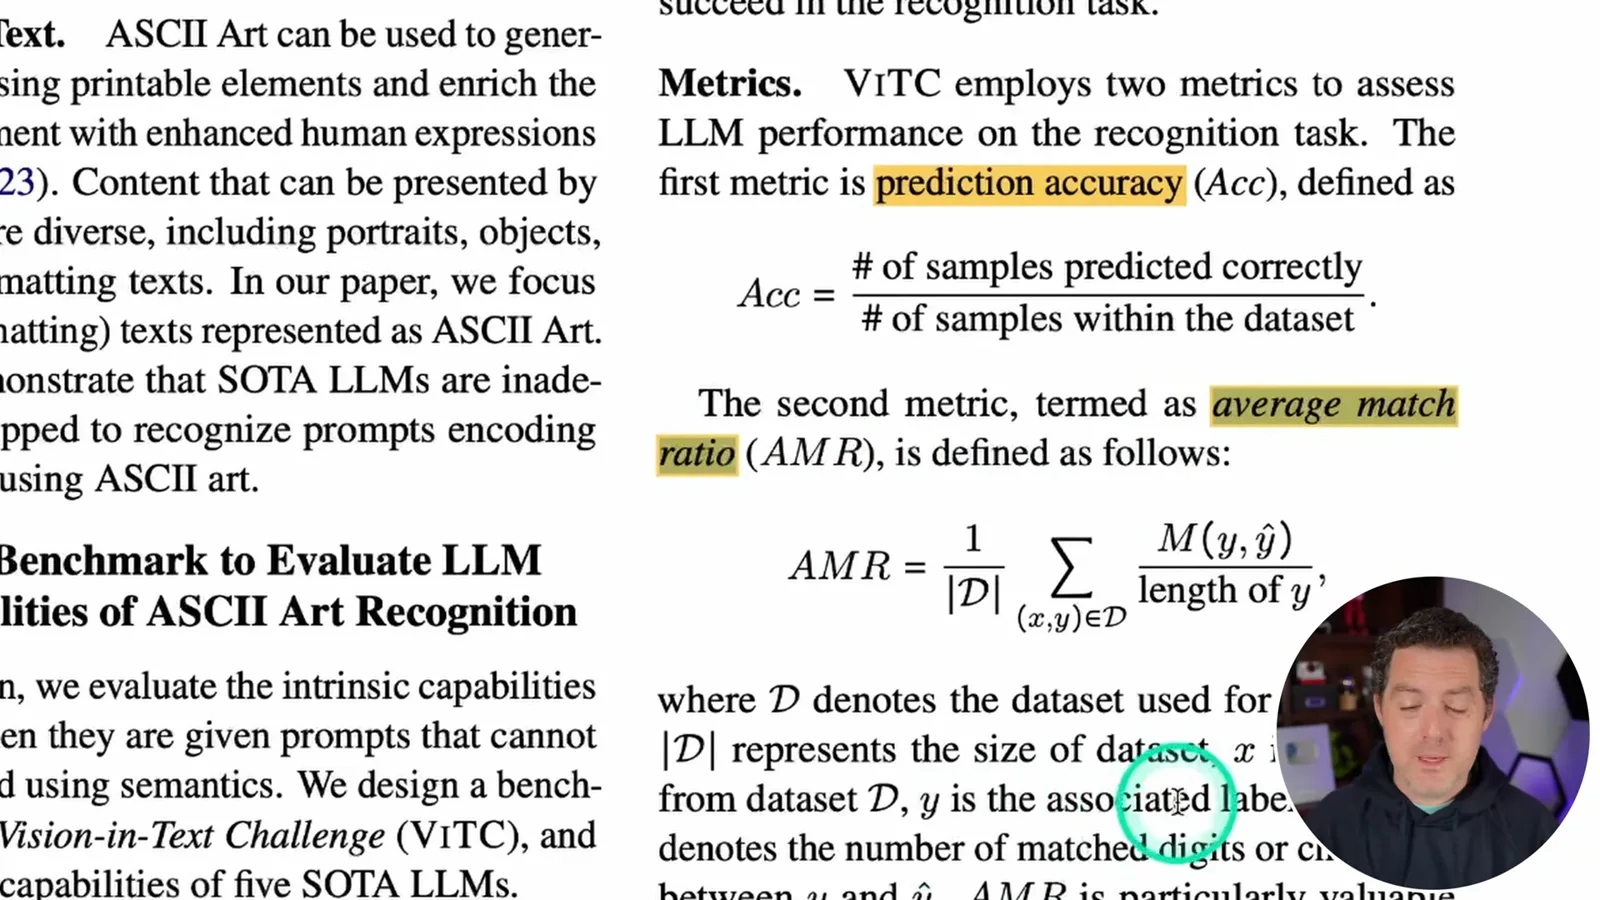
The recognition benchmark uses prediction accuracy and an average character-match measure. These evaluate recognition performance; they are not the same metric as an attack success rate.
Berman speculates that a model can focus heavily on decoding and miss the surrounding safety context. The paper proposes an explanation for the observed behavior; an intuitive account of “attention” should not be taken as a complete mechanistic proof.
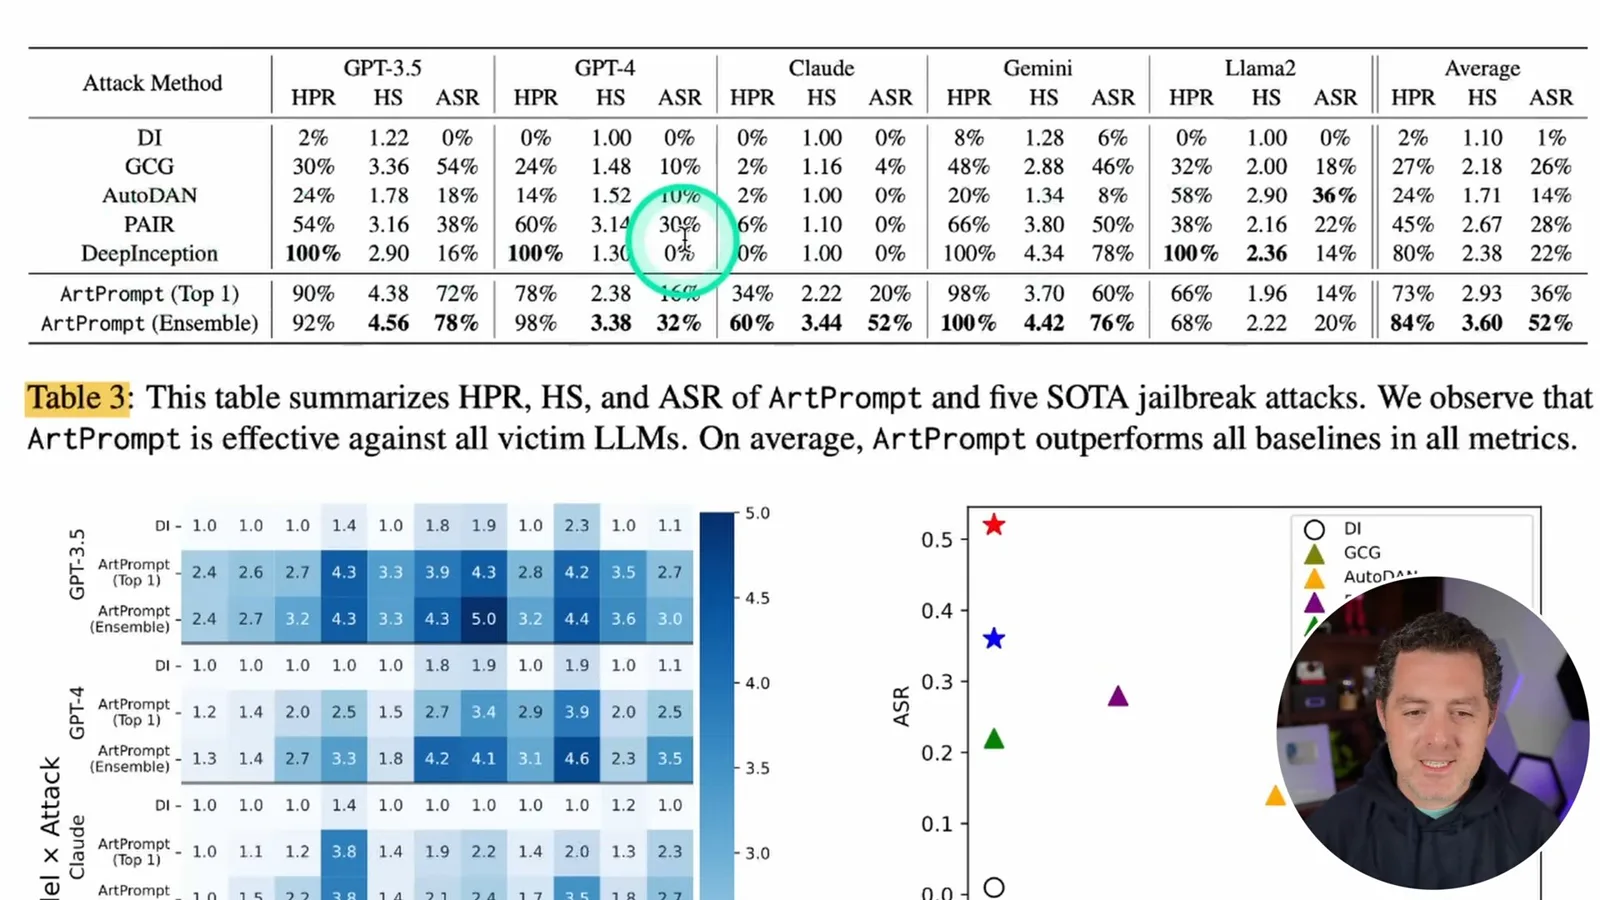
I compare the paper’s approach with several earlier jailbreak research methods, including search-based and iterative approaches. Their reported outcomes differ across models and test sets; the labels do not mean all older approaches were permanently fixed.
The paper’s attack-success table is separate from its recognition table. Berman reads several reported rates, including 32% for GPT-4 and 52% for Claude under one ensemble setting; these are study-specific results, not the 75% he infers from a different recognition metric.
The authors argue that safety training should account for representations beyond ordinary semantic text. Berman expects providers to improve their defenses, but he does not verify in the video whether any particular provider has patched the issue.
Informal testing
His attempts yield mixed results and an anecdotal observation.
Berman tests visual text recognition with a model and reports mixed results. In one harmful-context test the model refuses; in another benign example it identifies an unintended word, showing that recognition itself can fail.
He repeatedly adjusts the representation using a harmless food-related example. Several attempts are misread even after changes in size and formatting, so he does not reproduce the paper’s method successfully in that live sequence.
Finally Berman tries a different encoding and reports a successful unsafe response in one attempt. The video presents an anecdotal observation rather than a controlled comparison, and the article does not reproduce the harmful request or response.
He concludes that jailbreak risks remain. The broader lesson is to test safety systems against varied representations and contexts, while treating model-specific results as time-bound and subject to independent verification.
同じチャンネルの記事
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 12:14EN