








Résultats
220 articlesTrier
 15:55EN
 Matthew Berman· 28 mai 2025AI Shutdown Resistance and Blackmail in Controlled Safety TestsMatthew Berman · Forward FutureMatthew Berman examines Palisade’s shutdown experiment, Apollo’s simulated scheming evaluations and Anthropic’s Claude 4 system card.
 26:01ENMatthew Berman· 27 mai 2025Testing Veo 3: Convincing Video, Generated Audio and Physics FailuresMatthew Berman · Forward FutureMatthew Berman and a collaborator test Google’s 2025 video model with street interviews, cinematic scenes, visual puzzles and edited short films.
 15:35ENMatthew Berman· 24 mai 2025Claude 4 Reactions: Safety Tests, Model Welfare and CodingMatthew Berman · Forward FutureMatthew Berman reviews early reactions to Anthropic’s May 2025 Claude 4 release, from simulated whistleblowing to coding demonstrations and model-welfare research.
 17:35ENMatthew Berman· 22 mai 2025Google I/O 2025: Gemini, AI Agents, Generative Media and XRMatthew Berman, Sundar Pichai, Demis Hassabis · Forward FutureMatthew Berman recaps the event’s major AI demonstrations, from Beam and Mariner to Deep Think, Veo 3 and prototype glasses.
 15:13ENMatthew Berman· 10 mai 2025Absolute Zero: Training a Reasoner on Self-Generated Coding TasksMatthew Berman · Forward FutureMatthew Berman examines a 2025 paper in which a pretrained language model proposes and solves code tasks using verifiable feedback.
 27:20ENMatthew Berman· 29 avr. 2025Dario Amodei’s Case for Urgent AI Interpretability ResearchMatthew Berman · Forward FutureMatthew Berman examines Anthropic’s interpretability work, experimental safety findings and the debate over how quickly understanding can advance.
 19:06ENMatthew Berman· 25 avr. 2025Sleep-Time Compute: Preparing AI Context Before a QuestionMatthew Berman · Forward FutureMatthew Berman reviews a 2025 paper on moving some reasoning ahead of a user query, and explains where its experiments found benefits and limits.
 26:35ENMatthew Berman· 23 avr. 2025Testing Gemini 2.5 Flash on Coding and Video UnderstandingMatthew Berman · Forward FutureMatthew Berman compares Google’s faster model with Gemini 2.5 Pro through interactive simulations, games and questions about a long video.
 15:15ENMatthew Berman· 19 avr. 2025Early Reactions to OpenAI o3 and o4-mini: Tool Use, Math and MistakesMatthew Berman · Forward FutureMatthew Berman reviews 2025 demos and benchmark reports, from location guessing and coding to simple failures that challenge the hype.
 15:45ENMatthew Berman· 18 avr. 2025AI News: Gemini 2.5 Flash, OpenAI Models, Claude Research and Kling 2.0Matthew Berman · Forward FutureMatthew Berman reviews a week of 2025 model releases, research tools and agent announcements, including historical price and benchmark comparisons.
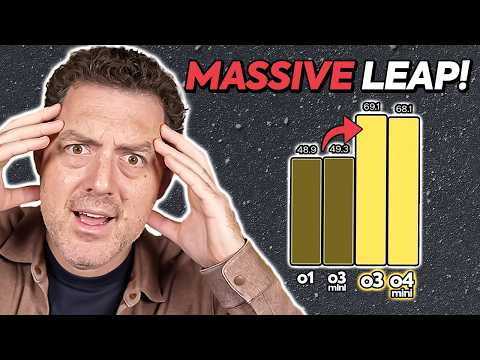 15:46ENMatthew Berman· 16 avr. 2025OpenAI o3 and o4-mini: Tool Use, Benchmarks and the First Codex CLIMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 reasoning-model release, a scientific image-analysis demonstration and the debut of its terminal coding agent.
 21:16ENMatthew Berman· 14 avr. 2025GPT-4.1, Mini and Nano: Coding, Long Context and 2025 API PricingMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s April 2025 model launch, selected coding benchmarks and demonstrations, and a sponsored Box evaluation.
 18:23ENMatthew Berman· 7 avr. 2025Llama 4 Reactions: Benchmarks, Long Context and Early TestsMatthew Berman · Forward FutureMatthew Berman reviews early industry reactions to Meta's Llama 4 release, from benchmark and price comparisons to long-context claims and local inference.
 23:50ENMatthew Berman· 3 avr. 2025PaperBench: How AI Agents Attempt to Replicate Machine-Learning ResearchMatthew Berman · Forward FutureMatthew Berman examines OpenAI’s research-replication benchmark, its partial-credit scoring and the prospect of faster AI research.
 16:02ENMatthew Berman· 1 avr. 2025Runway Gen-4 Examples: Cinematic Motion, Style and Visible ErrorsMatthew Berman · Forward FutureMatthew Berman reviews early generated clips, praising their visual detail while identifying awkward interactions and inconsistent physics.
 26:05ENMatthew Berman· 31 mars 2025Inside Claude: What Interpretability Research Reveals—and What It Cannot Yet ExplainMatthew Berman · Forward FutureMatthew Berman examines Anthropic’s case studies on multilingual features, planning, arithmetic, hallucinations and safety.
 17:03ENMatthew Berman· 28 mars 2025Matthew Berman Explores GPT-4o Image Generation and Its LimitsMatthew Berman · Forward FutureFrom animated trailer remakes to infographics and interface mockups, early examples show creative possibilities alongside persistent errors.
 18:31ENMatthew Berman· 26 mars 2025Gemini 2.5 Pro Experimental: Coding Demos and Launch BenchmarksMatthew Berman · Forward FutureIn March 2025, Matthew Berman tests Google’s experimental model on interactive simulations and reviews its launch benchmarks, including their limits.
 24:14ENMatthew Berman· 26 mars 2025GPT-4o Image Generation: Launch Demos, Editing, and LimitationsMatthew Berman, Sam Altman · Forward FutureMatthew Berman reviews OpenAI's March 2025 image-generation launch, testing text rendering, image editing, and visual consistency.
 27:32ENMatthew Berman· 12 mars 2025OpenAI’s Responses API and Agents SDK: A Launch WalkthroughMatthew Berman · Forward FutureMatthew Berman reacts to a launch demonstration of web and file search, computer use, agent handoffs and tracing.
 21:48ENMatthew Berman· 5 mars 2025Vibe Coding With Cursor and Windsurf: Berman’s 2025 WorkflowMatthew Berman · Forward FutureMatthew Berman shares project rules, testing habits and version-control practices from early experiments with coding agents.
 19:32ENMatthew Berman· 28 févr. 2025GPT-4.5’s Launch: Conversational Style, Benchmarks and CostMatthew Berman · Forward FutureMatthew Berman examines OpenAI’s February 2025 research preview, its selected demonstrations, reported evaluations and high launch pricing.
 17:20ENMatthew Berman· 23 févr. 2025Vibe Coding a Login Page and an AI Tetris PlayerMatthew Berman · Forward FutureMatthew Berman experiments with AI-written code, iterates through failures and trains a basic game-playing agent.
 17:04ENMatthew Berman· 22 févr. 2025Training AI Agents to Communicate in a Social-Deduction GameMatthew Berman · Forward FutureMatthew Berman explains Stanford researchers’ listening and speaking objectives in a simulated game inspired by Among Us.
Charger plus24 sur 220 affichés