En 30 secondes
Matthew Berman reviews GPT-4.1, mini and nano, focusing on coding, instruction following, long-context tests and launch pricing. His video includes a Box-sponsored segment and discloses a small investment in CrewAI. OpenAI’s and partners’ scores apply to their stated tests. The video’s API-only description reflects launch day; OpenAI later added GPT-4.1 to ChatGPT in May 2025.
- 1Three models and long contextOpenAI launched GPT-4.1, mini and nano with up to one million tokens of context.
- 2Coding benchmark scopeThe reported 54.6% on SWE-bench Verified excludes 23 unrun problems; scoring them as failures yields 52%.
- 3A sponsored enterprise testBox compares document extraction on its own evaluation; it sponsored the segment.
- 4Instruction-following limitsOpenAI’s hard-subset result was 49%, despite a presenter’s broad claim of strict instruction following.
- 5Long-log demonstrationThe launch demo finds one inserted sentence in a roughly 450,000-token log, a specific retrieval example.
- 6Launch pricingThe April 2025 API table lists separate input, cached input and output rates; blended prices depend on usage.
À retenir
- The GPT-4.1 family launched with up to one million tokens of context, but window size is not a guarantee of perfect comprehension.
- OpenAI’s SWE-bench result depends on its evaluation setup and excludes 23 problems that could not run on its infrastructure.
- The Box document-extraction comparison is a sponsor’s own test; partner coding results also have specific scopes.
- OpenAI’s hard instruction-following evaluation reported 49% for GPT-4.1, not perfect compliance.
- April 2025 API prices and initial availability are historical; GPT-4.1 was later added to ChatGPT.
Lire le texte remanié, chapitre par chapitre
The GPT-4.1 launch and benchmarks
Berman introduces the three models, coding results and the proposed deprecation of GPT-4.5 Preview in the API.
OpenAI has released GPT-4.1, GPT-4.1 mini and GPT-4.1 nano for developers. At the April 2025 launch, the family was available through the API rather than directly in ChatGPT. That changed later: [OpenAI added GPT-4.1 to ChatGPT on May 14, 2025](https://help.openai.com/en/articles/6825453-chatgpt-release-notes).
All three models support up to one million tokens of context, and OpenAI says they improve coding and instruction following relative to GPT-4o and GPT-4o mini on the evaluations it presents. Their stated knowledge cutoff is June 2024. A large context window is a capacity limit; it does not guarantee perfect understanding of every document.
OpenAI reports GPT-4.1 scoring 54.6% on SWE-bench Verified, 21.4 percentage points above GPT-4o and 26.6 points above GPT-4.5 in its stated setup. The company notes that 23 of 500 problems could not run on its infrastructure; treating those as failures would make the GPT-4.1 score 52%. Results depend on the evaluation setup and do not establish performance on all programming tasks.
On Scale’s MultiChallenge instruction-following benchmark, OpenAI reports 38.3% for GPT-4.1, an improvement of 10.5 percentage points over GPT-4o. On Video-MME’s long-video, no-subtitles category it reports 72%. These are provider-reported results for specific tests, rather than universal measures of compliance or video understanding.
OpenAI also says it would deprecate the GPT-4.5 Preview API on July 14, 2025, after a transition period. I worry that asking developers to migrate soon after a release is disruptive. My suggestion that GPT-4.5 might be used for later distillation or return in another form is speculation, not a disclosed training fact.
Latency, cost and enterprise documents
He compares model sizes and discusses a Box-sponsored document-extraction test and demo.
I discuss model latency and cost. OpenAI’s chart places nano, mini and the full model at different performance and speed points, but does not label exact latency values on the displayed axes. The chart therefore supports a relative comparison in that evaluation, not an exact response-time claim for every application.
OpenAI says GPT-4.1 mini matches or exceeds GPT-4o on many benchmarks, with lower latency and cost in its comparisons. I think mini could be a particularly useful choice for developers making many programmatic calls, where even small differences in per-call cost can accumulate.
OpenAI says it did not add a separate long-context surcharge for GPT-4.1 at launch. Users still pay for the input and output tokens they use, so processing a very long document can be expensive even at the same per-token rate. Pricing and model availability in this discussion are historical.
Box, the sponsor of this video and an early partner, presents its own enterprise document-extraction evaluation comparing GPT-4.1 and GPT-4o. The displayed categories include insurance, warranty and contract clauses. Those are Box-reported results for its test, not independently established performance on all enterprise documents.
Box demonstrates asking its system to summarize an NVIDIA earnings call, including revenue and data-center trends. The example illustrates document synthesis, but a viewer cannot independently verify every extracted number from the brief demonstration. Box sponsored this part of the video.
Agents, availability and coding
Berman discusses nano, coding agents, the historical API launch and coding benchmarks. GPT-4.1 later became available in ChatGPT.
OpenAI positions the smaller nano model for tasks such as classification and autocomplete. The company reports scores including 80.1% on MMLU and 9.8% on Aider’s polyglot coding test; these figures concern the specified evaluations and should not be confused with a success rate across all uses.
I see stronger instruction following and long-context handling as useful for agent workflows, including coding tools. The video also mentions CrewAI; I disclose in the video description that I am a small investor in that company. A model still needs tools, integration and appropriate checks to work effectively as an agent.
At the time of recording, GPT-4.1 was an API release and OpenAI said some improvements were being incorporated into GPT-4o in ChatGPT. The later May 2025 ChatGPT release makes the video’s API-only description a launch-time snapshot, not a permanent availability statement.
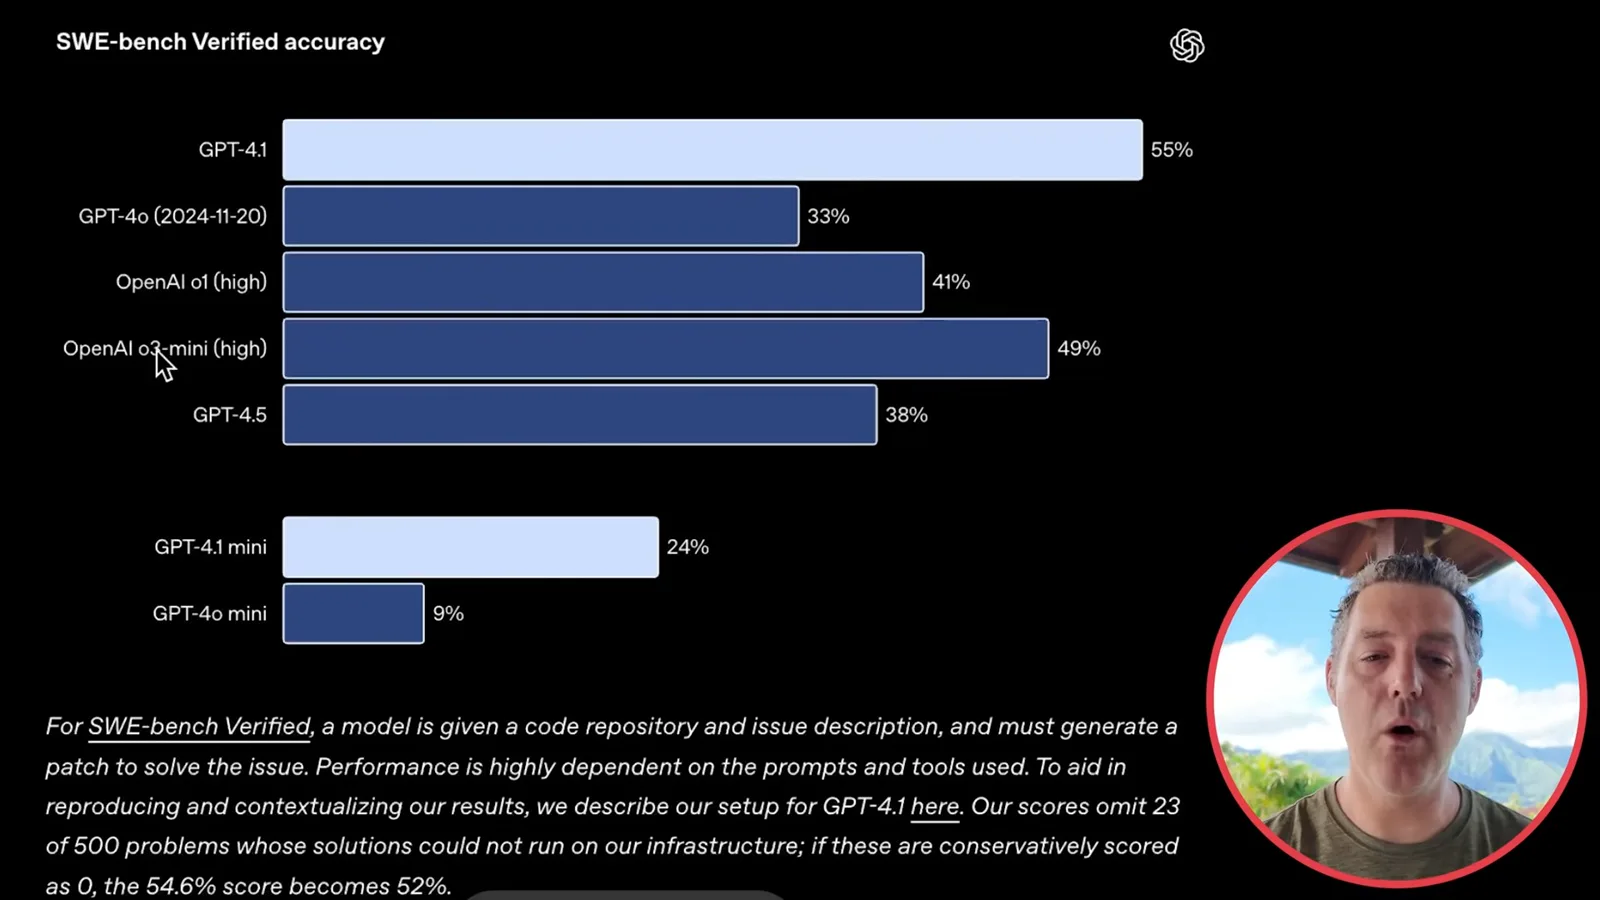
I compare the SWE-bench Verified results for the new family with earlier models, including o3-mini high. The task asks a model to produce a patch for an issue in a code repository. Performance depends on prompts, tools and infrastructure, so a lead on this benchmark does not prove superiority for every coding workflow.
Another coding comparison looks at editing with diffs rather than rewriting whole files. Targeted changes can reduce unnecessary output and help preserve unrelated code, although the displayed Aider results are a benchmark comparison rather than a guarantee that any edit will be correct.
Demonstrations and instruction following
OpenAI and partners show a flashcard app and report coding and instruction results. The evaluations are task-specific.
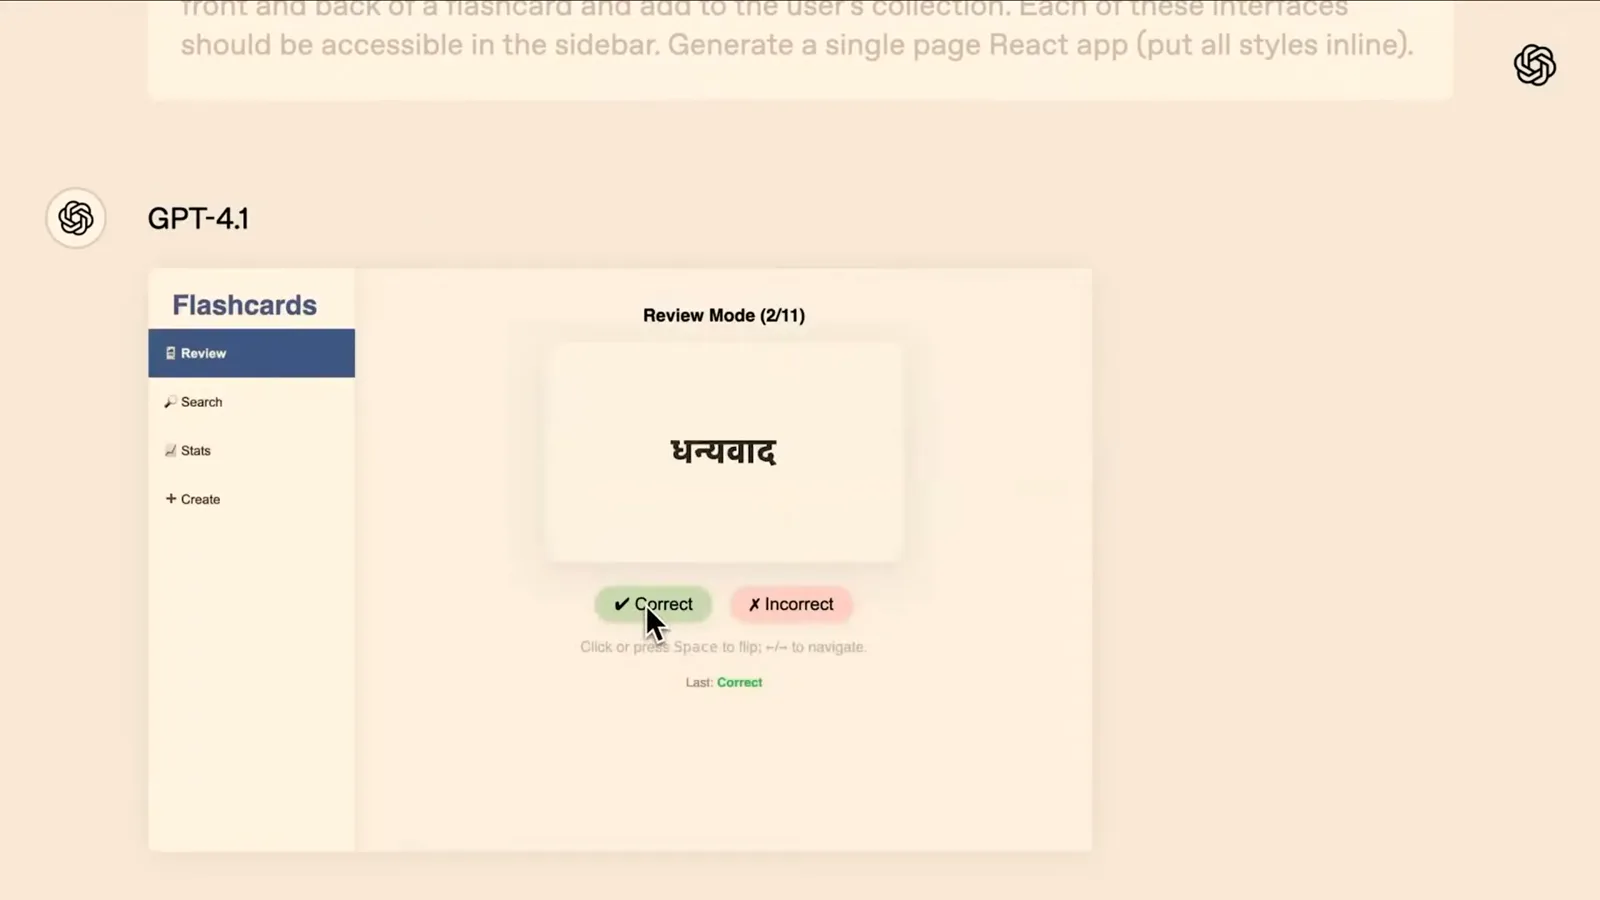
In an OpenAI launch clip, presenters compare a generated flashcard application in GPT-4o and GPT-4.1. The latter example includes colors and a card-flip animation. It is a useful illustration of a particular prompt and output, not a broad independent usability study.
Windsurf reports that GPT-4.1 scored higher than GPT-4o on its internal coding benchmark and needed fewer repeated edits in its observations. Another partner, Qodo, reports preferring GPT-4.1’s suggestions in 55% of 200 evaluated pull requests. These are partner-reported findings under their own tests.
The OpenAI presenters demonstrate an instruction-following evaluation with complex formatting requirements, such as producing a trip itinerary in a specified table. They describe the model as more reliable; the hard-subset chart shows 49% for GPT-4.1 versus 29% for GPT-4o, so it does not support a claim of perfect adherence.
Long-context retrieval and pricing
A long-log demonstration illustrates retrieval. Berman closes with multimodal tests and April 2025 API prices.
The launch materials also show a needle-in-a-haystack test across long contexts. A perfect result on the shown retrieval test is encouraging but does not demonstrate perfect comprehension of every million-token input or complex reasoning task.
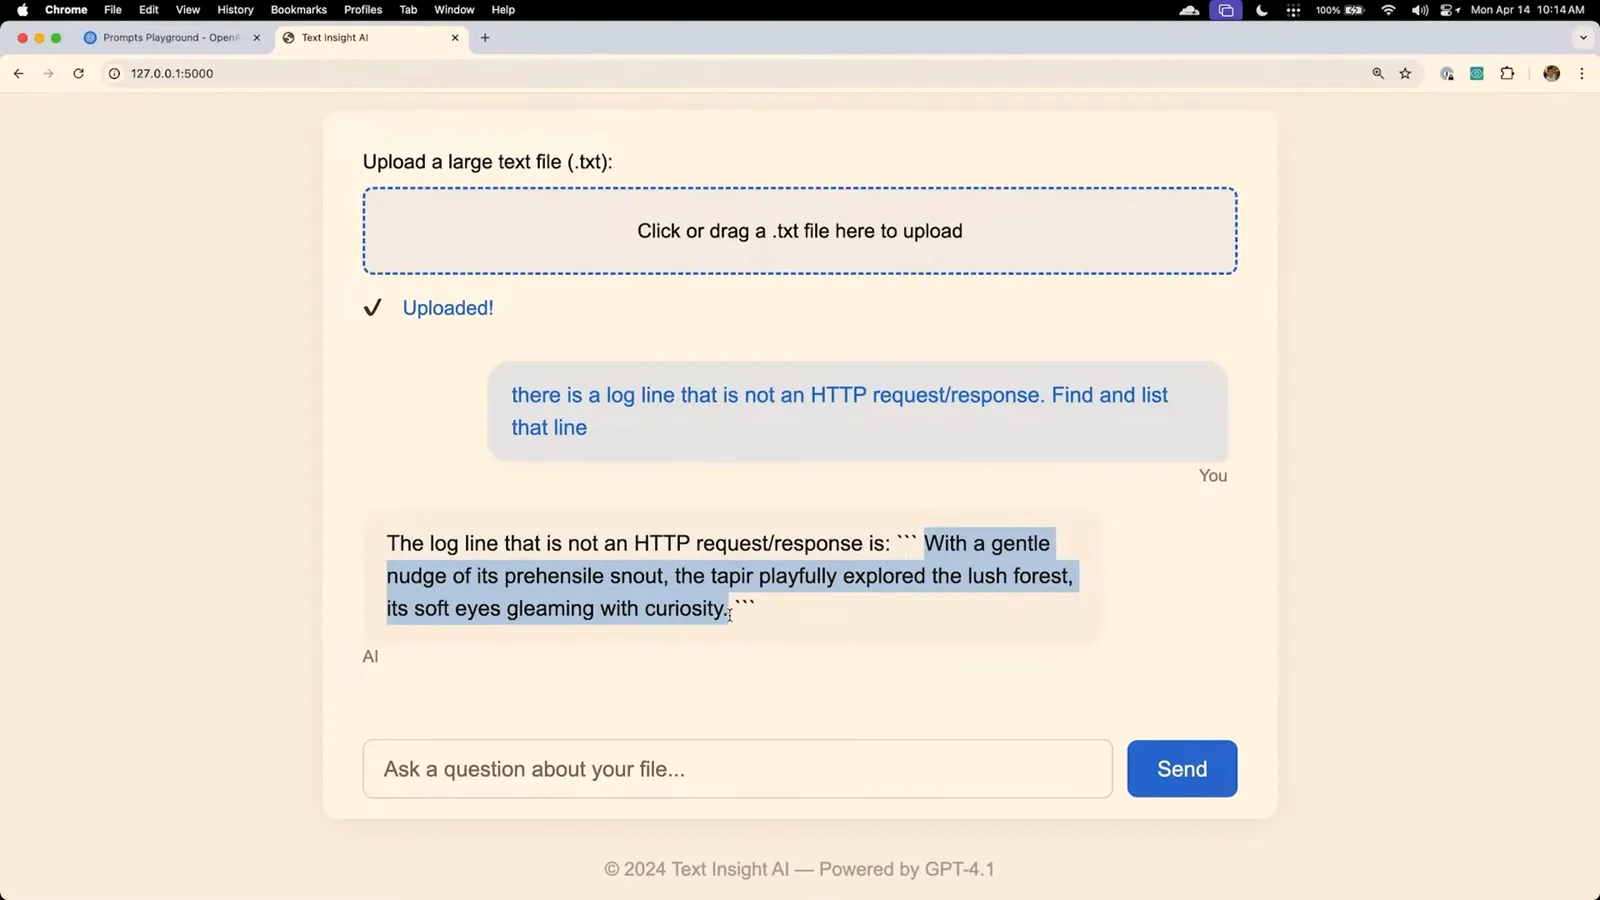
In another OpenAI demonstration, a presenter inserts a non-log sentence into a roughly 450,000-token NASA server log and asks the model to find it. The model identifies the unusual line and the presenter verifies that it appears in the file. This is one controlled example of retrieval in a long input.
I review additional multimodal and chart-reasoning comparisons. The broad pattern in OpenAI’s selected results is that GPT-4.1 often improves on GPT-4o and sometimes approaches more expensive models, but actual performance varies by task and benchmark.
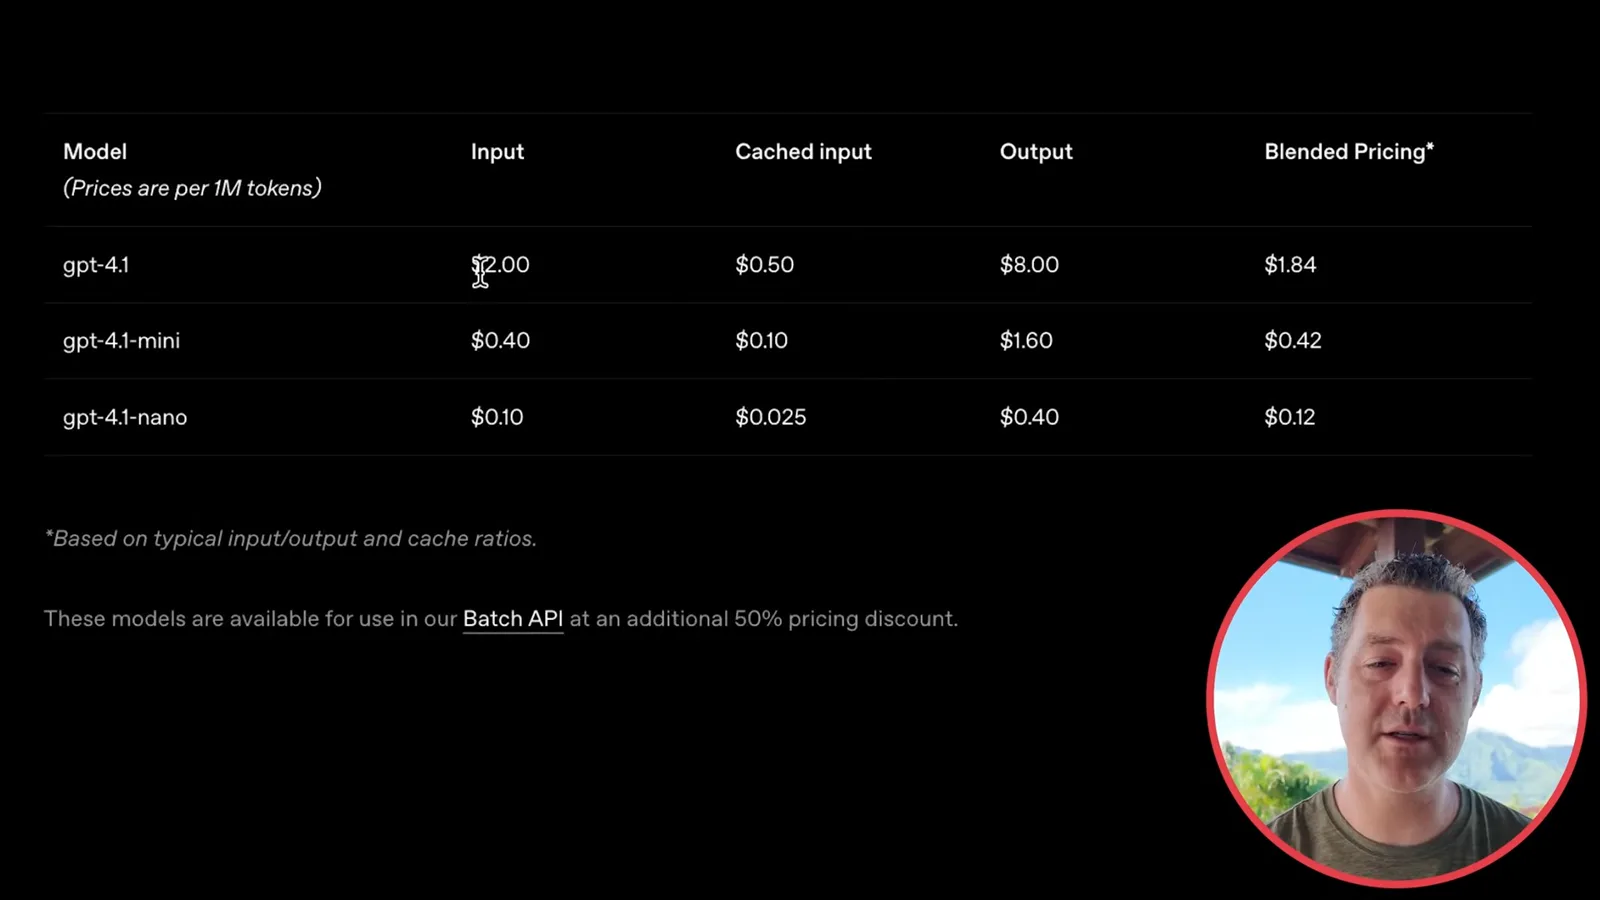
The April 2025 API pricing table lists GPT-4.1 at $2 per million input tokens, $0.50 cached input and $8 output. Mini is $0.40, $0.10 and $1.60 respectively; nano is $0.10, $0.025 and $0.40. The displayed blended prices assume particular input, output and caching ratios, so an individual bill can differ.
Sur la même chaîne
 34:21EN
 Matthew Berman· 27 oct. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct. 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.