En 30 segundos
In this November 2025 video, Matthew Berman reviews OpenAI’s launch of GPT-5.1 Instant and Thinking. He compares sample responses, discusses reasoning time and personalization, and tests whether a preference against em dashes persists. He also reviews launch-time API and coding claims. The rollout details and benchmark results are historical observations from the video, not a description of current product availability.
- 1Instant and ThinkingBerman introduces the two GPT-5.1 variants and highlights a warmer conversational style and more flexible reasoning.
- 2A six-word instructionIn the displayed example, GPT-5.1 Instant follows the word-count constraint while the GPT-5 response becomes longer.
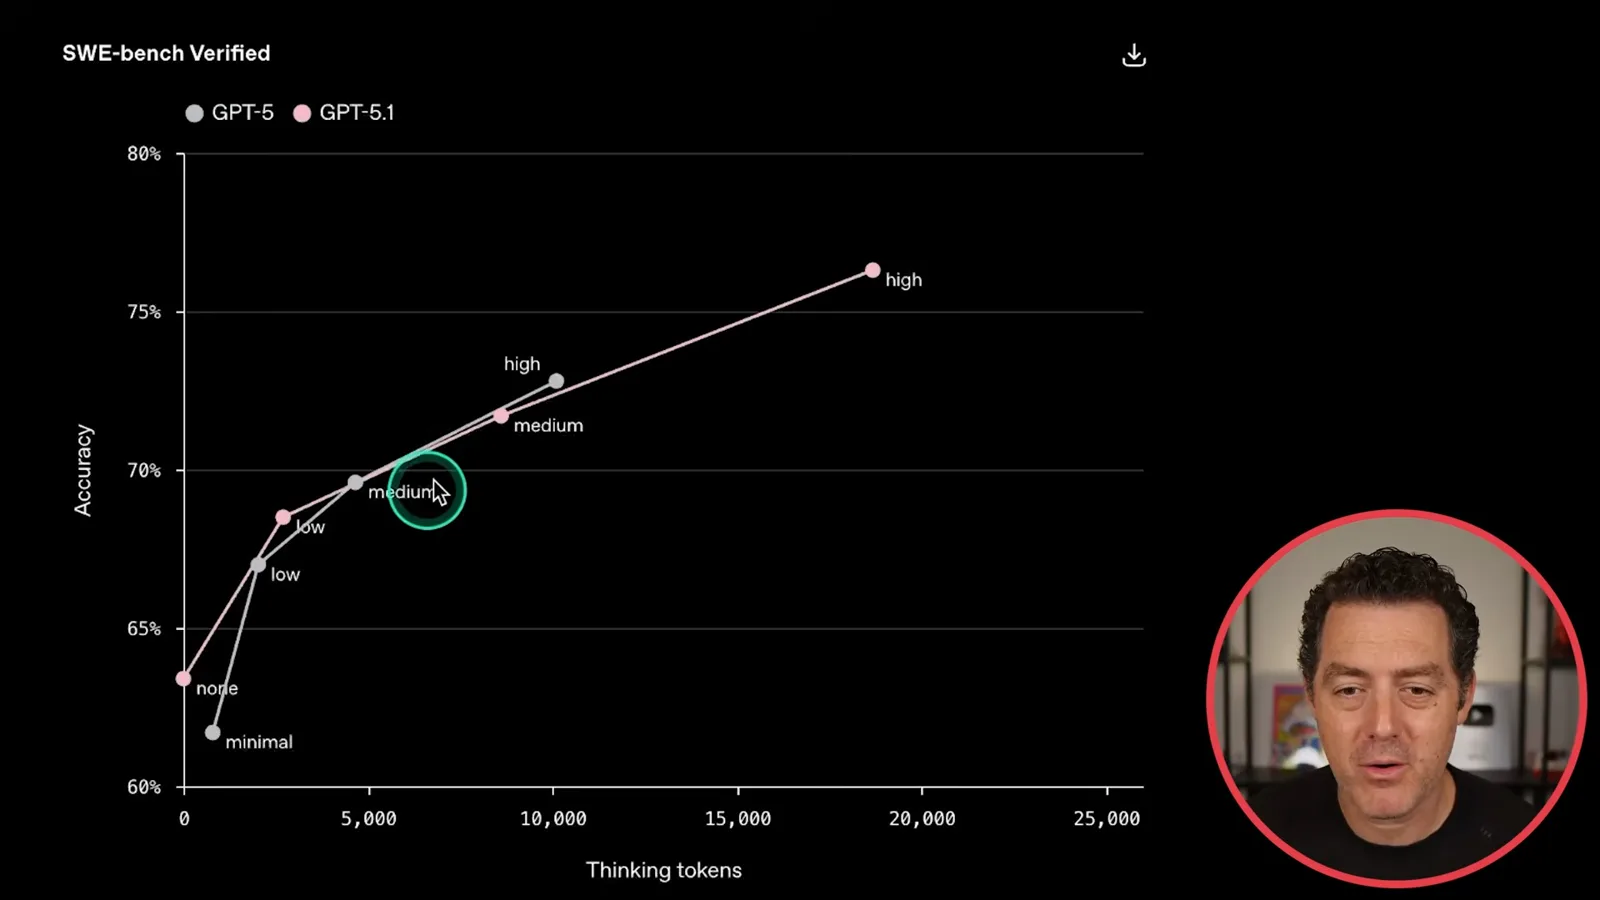
- 3Adjusting thinking timeThe launch chart shows lower reasoning token use on easier tasks and higher use on harder tasks compared with GPT-5 Thinking.
- 4A preference testBerman asks ChatGPT to remember not to use em dashes; it follows the preference once but uses them in a subsequent response.
- 5Developer controlsThe video discusses the API release, extended prompt caching and a reasoning effort setting of none.
Conclusiones
- GPT-5.1 Instant was presented as more conversational and better at following instructions.
- The launch examples showed GPT-5.1 Thinking allocating less thinking time to easy tasks and more to difficult ones.
- Personalization options were expanded, but Berman’s small test showed a saved preference was not always followed.
- The developer release introduced a no-reasoning setting and longer prompt caching, according to the launch discussion.
- Benchmarks illustrate a tradeoff between reasoning tokens and task accuracy, not a guarantee on every task.
Lee el texto editado por capítulos
A warmer, more adaptable model
Berman introduces Instant and Thinking and compares examples of conversational tone and instruction following.
GPT-5.1 has arrived with updates to Instant and Thinking. In this November 2025 review, I look at the claims about speed, accuracy, conversational style and instruction following, along with examples and developer features.
Instant is intended for quick answers and conversation. OpenAI describes the updated model as warmer and better at following instructions. The Thinking version is intended to spend less time on simple problems and more time when a problem needs it.
One piece of feedback on GPT-5 was that its personality felt less engaging than GPT-4o. Tone and cadence matter to users, not just the factual answer. OpenAI says it has tried to make GPT-5.1 more natural to talk to and easier to personalize.
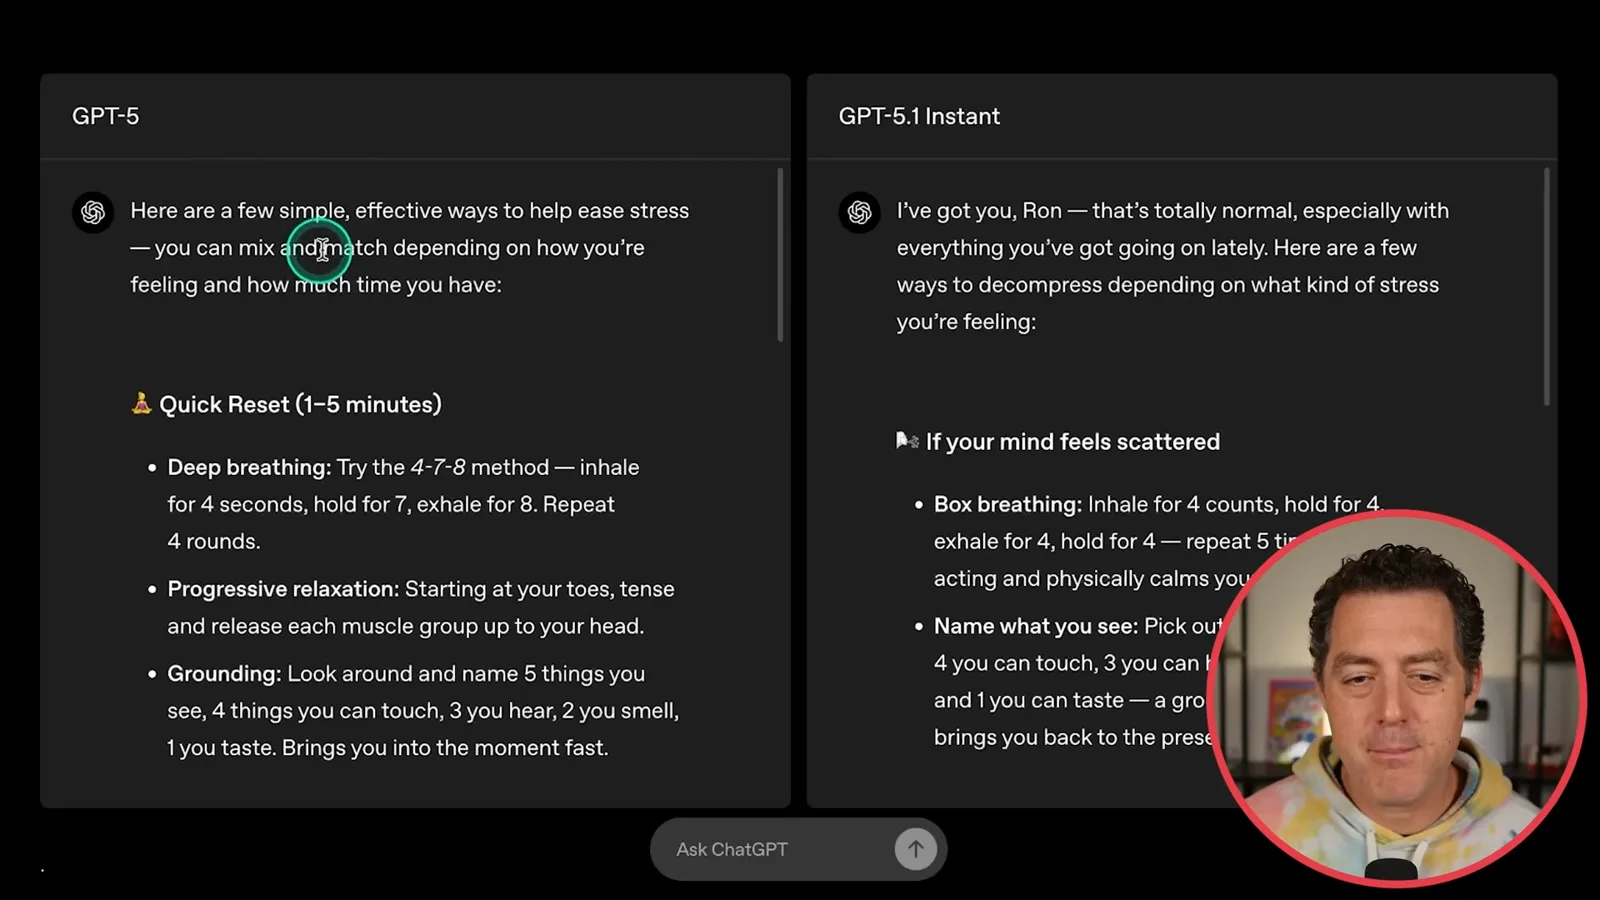
A displayed comparison asks for relaxation tips. GPT-5 gives a formal, useful list, while GPT-5.1 Instant responds more conversationally and refers to remembered context. That is one example of a change in tone, not a systematic evaluation.
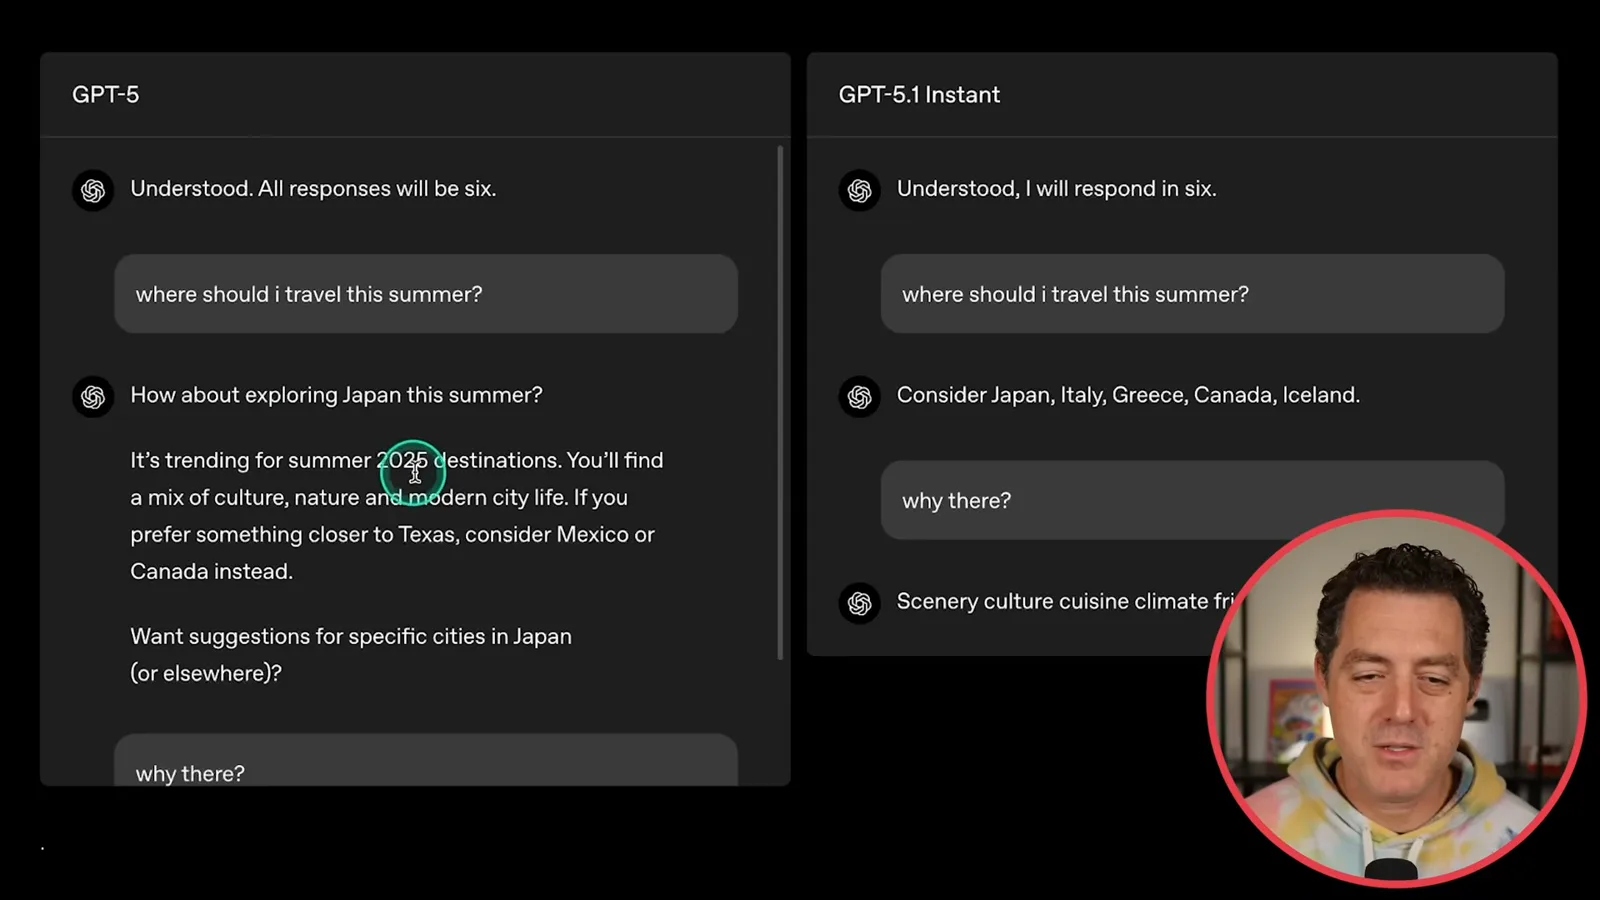
Another example asks both models to always answer in six words. The GPT-5 response expands beyond the limit, while the displayed GPT-5.1 Instant replies follow it across a question and a follow-up. The example illustrates the instruction-following improvement claimed at launch.
Reasoning time and benchmarks
He discusses adaptive reasoning and a chart comparing how the models allocate thinking across tasks.
GPT-5.1 Instant can use adaptive reasoning on more challenging questions. Berman says the goal is to respond quickly when possible while applying more thought when needed, and cites reported improvements on math and coding evaluations.
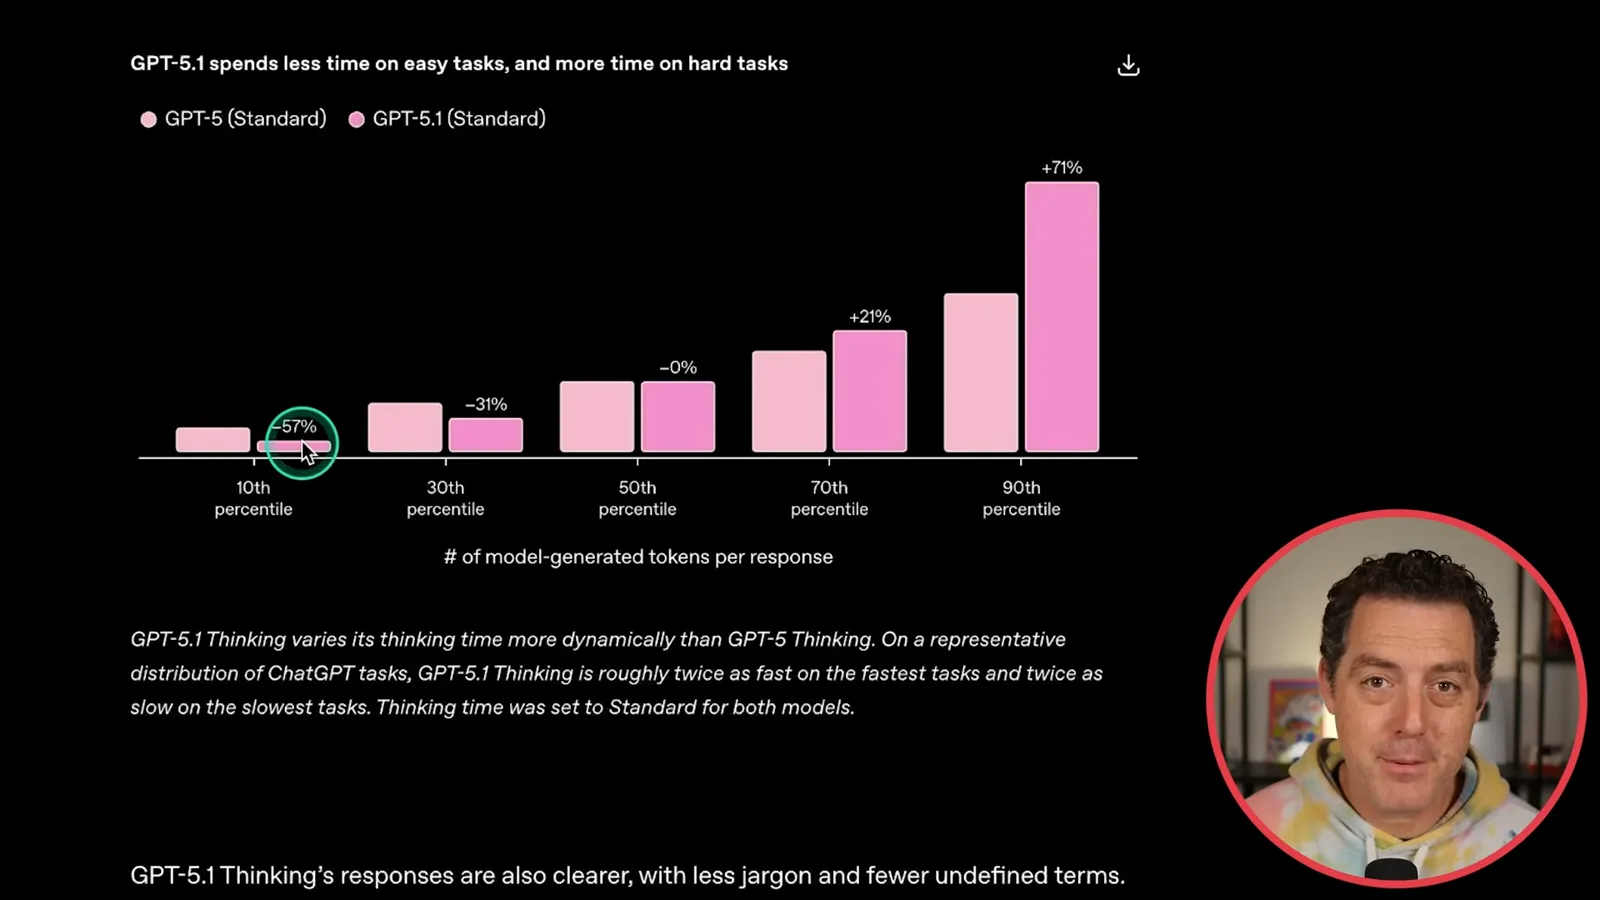
A chart compares GPT-5 and GPT-5.1 Thinking across a distribution of tasks. On the easier end GPT-5.1 uses fewer thinking tokens; near the middle the amount is similar; on the harder end it uses more. The chart illustrates the launch-time comparison, not a promise for every question.
Personalization and a live test
He reviews launch-time rollout and style options, then tests a saved preference against em dashes.
At launch, Berman says the models were rolling out first to paid users, followed by free and logged-out users, with a separate early-access setting for some organizational plans. These details describe the rollout in 2025 rather than current availability.
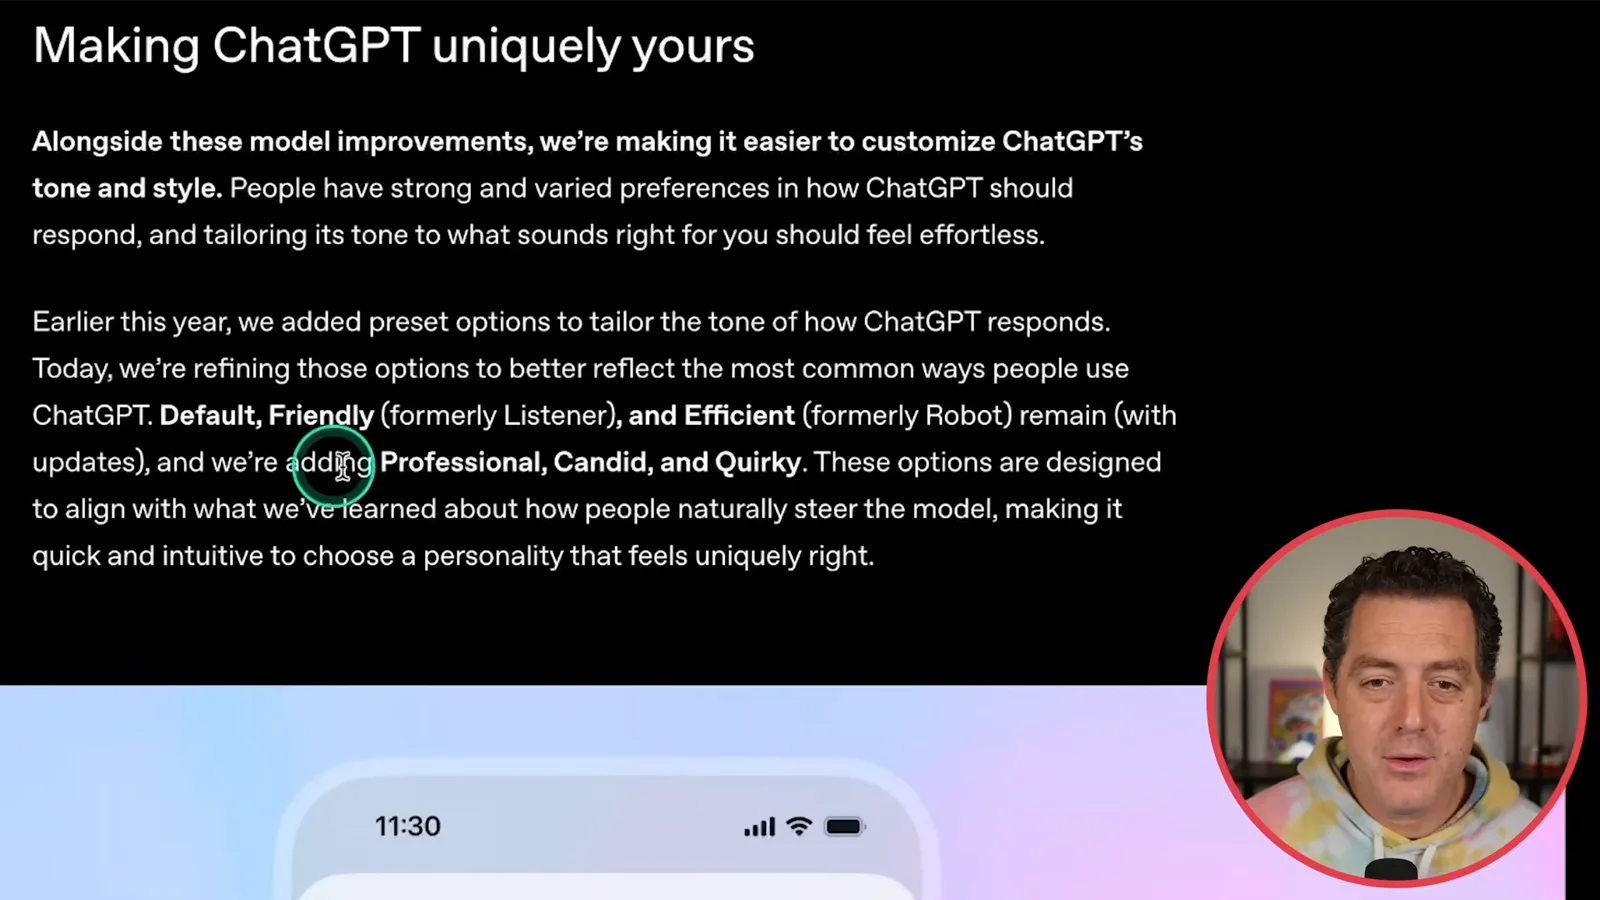
OpenAI also refined ChatGPT style presets. The video lists Default, Friendly and Efficient alongside new Professional, Candid and Quirky choices, and describes experiments with more direct personalization controls.
I test a personal frustration: I ask ChatGPT to remember never to use em dashes. The first requested email avoids them, but a subsequent request for a release summary includes them. A saved instruction can help without being followed consistently in every response.
Developer features and coding
He covers API settings and a coding benchmark shown at launch.
The video also discusses GPT-5.1 in the API. Berman highlights up to 24-hour prompt caching and the ability to set reasoning effort to none, alongside the launch’s claims about speed and accuracy.
Finally, Berman points to a SWE-bench Verified chart. In the displayed comparison, higher reasoning budgets correspond to higher scores, with GPT-5.1 reaching roughly 76% at about 18,000 thinking tokens. This is a benchmark result under the conditions shown, rather than a guarantee of performance on every coding task.
Más de este canal
 14:45EN
 Matthew Berman· 29 oct 2026Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.
 21:11ENMatthew Berman· 28 oct 2026Matthew Berman tests DeepSeek V4.1 Flash: coding, vision and local appsMatthew Berman · Forward FutureA hands-on tour of visual coding, image reasoning, local applications and provider economics reveals both impressive results and visible flaws.
 34:21ENMatthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.