En 30 segundos
In April 2024, Matthew Berman introduces OSWorld, an open research environment for evaluating agents using real desktop and web applications. Its original benchmark contains 369 Ubuntu tasks with configured starting states and executable evaluators; the paper reports 12.24% for its best tested agent and 72.36% for a human baseline. These historical scores are tied to that experiment, not current universal performance. The video is sponsored by Deepchecks.
- 1From instruction to actionThe furniture analogy distinguishes knowing the steps from grounding them in an environment and responding to feedback.
- 2The agent loopAn agent receives an instruction and observations, chooses actions and observes the resulting state.
- 3Real application workflowsA bookkeeping example combines receipt images and a spreadsheet; OSWorld supplies an environment and evaluator for such tasks.
- 4Observations and actionsScreenshots, accessibility trees and set-of-marks provide different views; agents can issue mouse and keyboard actions.
- 5Execution-based evaluationTask-specific scripts inspect resulting state, such as cookies or spreadsheet content, rather than grading only a textual response.
- 6Historical baseline resultsThe original paper reports 12.24% for its best tested agent and 72.36% for humans under its 2024 benchmark conditions.
Conclusiones
- OSWorld evaluates agents in real applications running in controlled virtual-machine environments; it is a benchmark and environment, not a model that automatically masters computer use.
- The original benchmark has 369 Ubuntu tasks, including multi-application workflows, and the paper describes an additional Windows subset.
- Tasks include an initial setup and custom execution-based checks against resulting application or system state.
- Screenshots, accessibility trees and annotated set-of-marks inputs expose different information; no one input mode is universally best.
- The paper’s 2024 baseline reports 12.24% for its strongest tested agent and 72.36% for humans, not present-day results.
- A benchmark score measures the defined tasks and evaluators, not general safety or reliability on arbitrary computers.
Lee el texto editado por capítulos
Grounding instructions in action
Berman introduces the benchmark and uses furniture assembly and desktop settings to explain grounding. A plan must be translated into actions and checked against feedback.
I introduce OSWorld, a research project designed to test multimodal agents in interactive computer environments. The team released its paper, code and data. It is not the first attempt to evaluate agents, but it addresses the challenge of testing a range of desktop tasks against actual application state.
The researchers’ presentation uses an IKEA assembly analogy. A set of instructions and an image of a finished chair do not themselves assemble it: an actor needs to connect each instruction to the physical parts, perform actions and observe what happened.
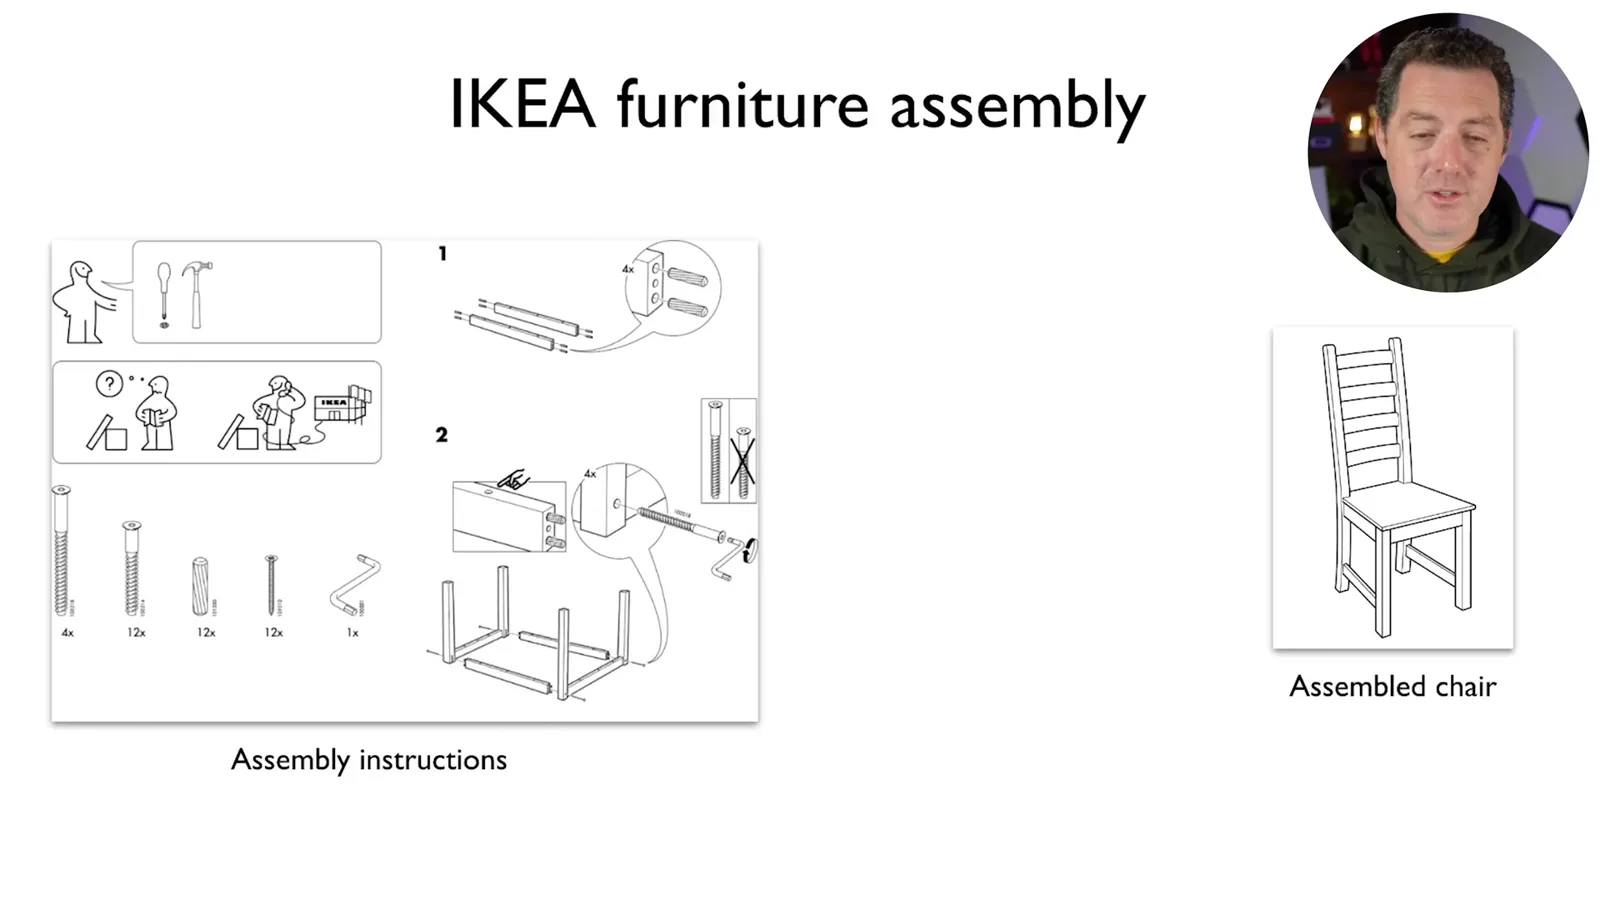
The same distinction applies to changing a desktop background. An assistant can describe steps, but executing them requires grounding those steps in the current interface using actions such as mouse movement and keyboard input.
In 2024 I found computer control difficult and discuss screenshot-based tools such as Open Interpreter. There are multiple ways to interact with computers, including accessibility APIs, structured interfaces and other tools; screenshots and grids are not the only possible implementation.
A language model may generate useful instructions without being connected to a computer or a physical environment. Whether it can execute a task depends on its tools and feedback, not on a blanket inability of all models or systems to interact.
Agents, tools and environments
He discusses the observation–action loop and related research. The video includes a Deepchecks sponsor segment.
The presentation depicts an agent receiving a user request, selecting actions and observing results. Depending on the setup, actions can include code, API calls or interface control. The environment can return information that informs the next step.
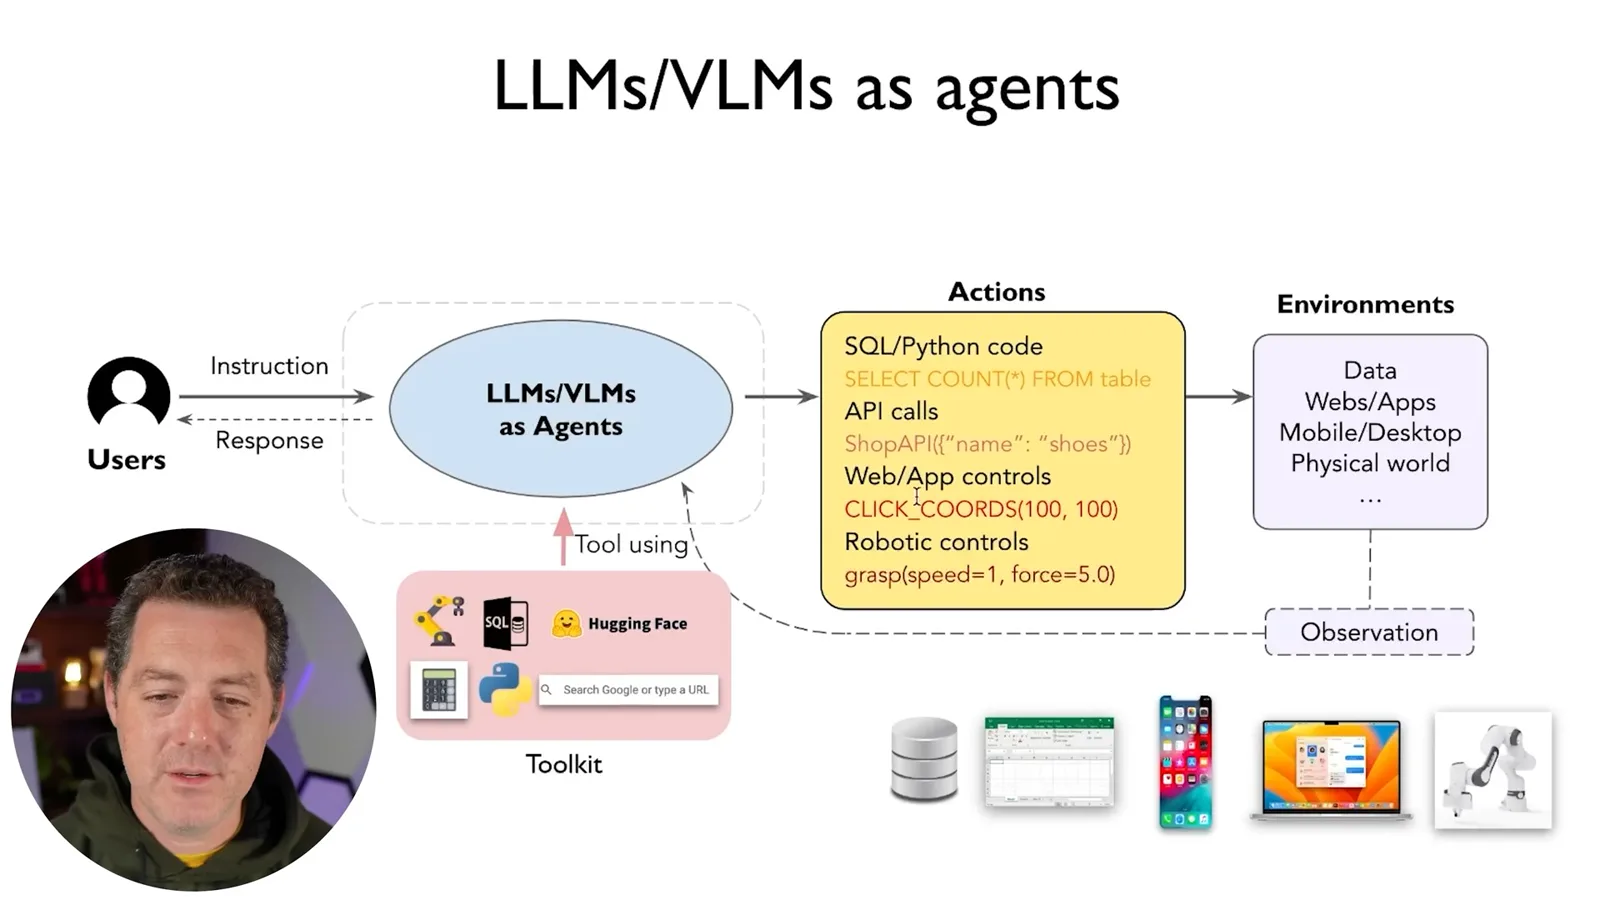
The general agent analogy uses sensors, observations and effectors: the agent perceives its environment and takes actions toward a goal. The discussion of physical robots is a general analogy; OSWorld evaluates computer tasks, not physical robot manipulation.
I connect this loop to agent frameworks and examples of cameras, screenshots or other sensors. A robotic example stacks blocks, illustrating how plans must be translated into actions and revised using feedback.
The presentation lists interpreting instructions, using tools, planning over multiple steps and responding to feedback as desired agent abilities. I discuss related work from the XLang research group; XLang is a research group and collection of projects, not a single OSWorld translation language.
The video is sponsored by Deepchecks, which offers tools for evaluating and monitoring language-model applications. The described capabilities and free trial are promotional claims, not independent test results.
I mention related research projects including InstructAgent, Binder, Lemur, OpenAgents and Text2Reward. These are distinct projects, while OSWorld is the computer-use environment and benchmark examined here.
OSWorld tasks, observations and evaluators
An example spans receipts and spreadsheets. The environment supplies task setup, observations, actions and execution-based checks.
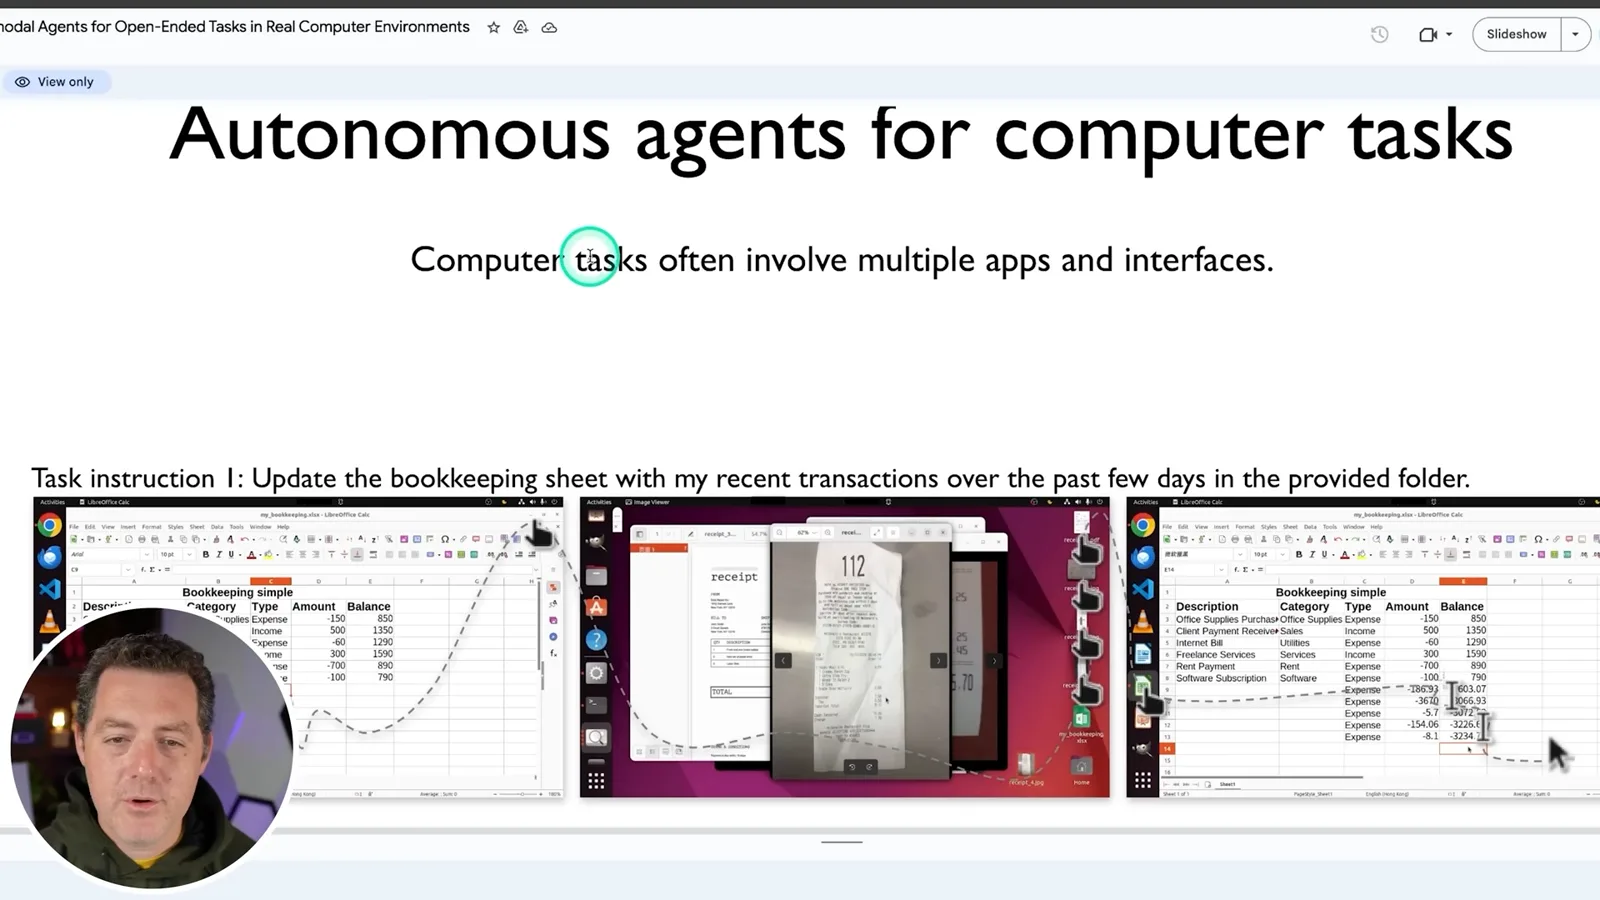
An example asks an agent to update a bookkeeping spreadsheet using recent receipts stored as images. The agent must locate the files, interpret relevant amounts and modify the spreadsheet across applications; this illustrates the task rather than demonstrating that every tested model completes it.
OSWorld uses virtual machines with real operating systems and applications. The platform is intended to support different operating systems, but the original main benchmark comprises 369 Ubuntu tasks; the paper also describes an additional Windows subset. It does not prove equally complete coverage of every app on every operating system.
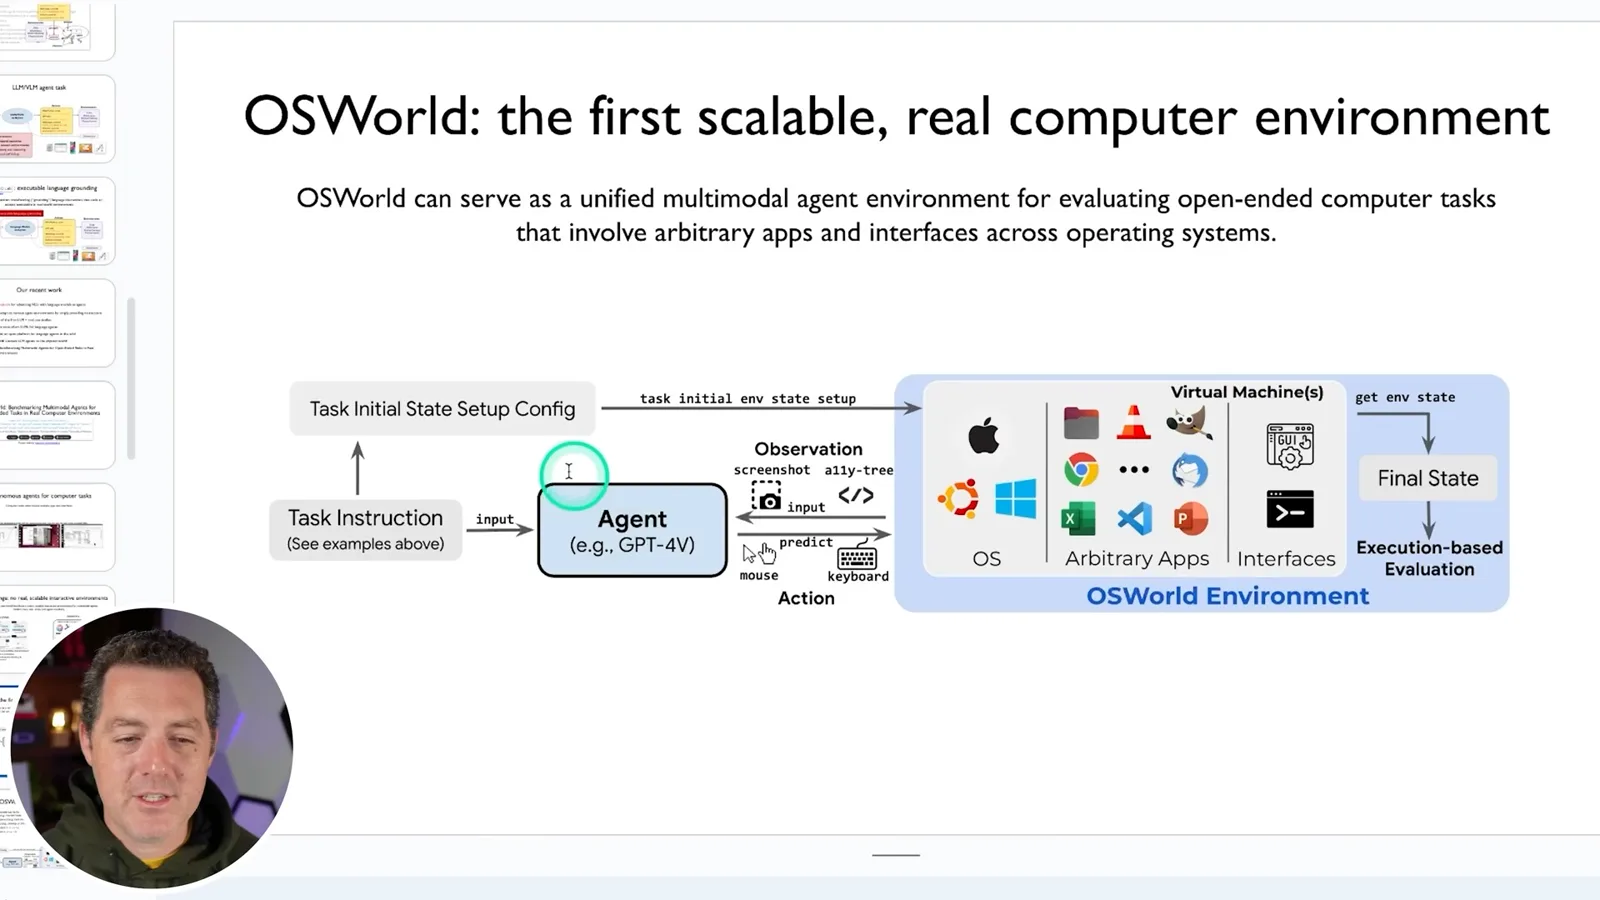
Each task includes an instruction and an initial-state configuration. The agent receives observations, produces actions and receives new observations as the environment changes. Researchers describe the task as a partially observable Markov decision process: the agent does not necessarily see the whole machine state.
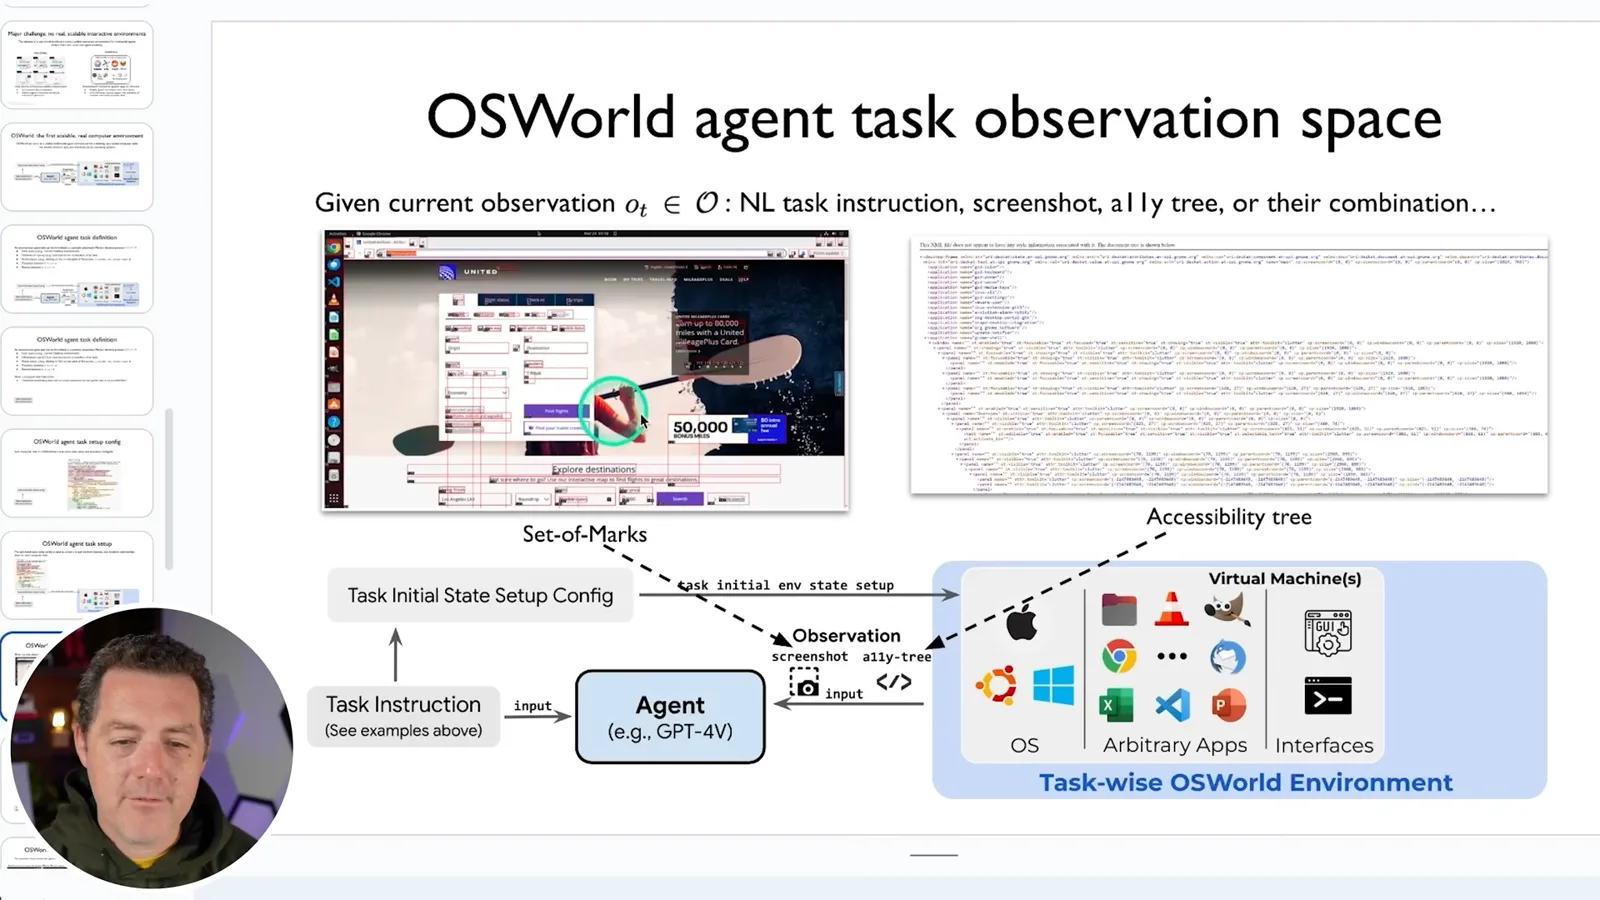
Observations can include screenshots, accessibility-tree information or a combination. In the original set-of-marks setup, numbered boxes are placed around elements using filtered accessibility information; the agent can choose an index that is mapped to an action. It is not merely a uniform grid and may not expose every element.
The action interface covers mouse movements, clicks, typing, keyboard shortcuts, scrolling and dragging, as well as signals such as waiting, completion or failure. A benchmark environment provides these interfaces, but does not by itself solve grounding or supply a universally capable agent.
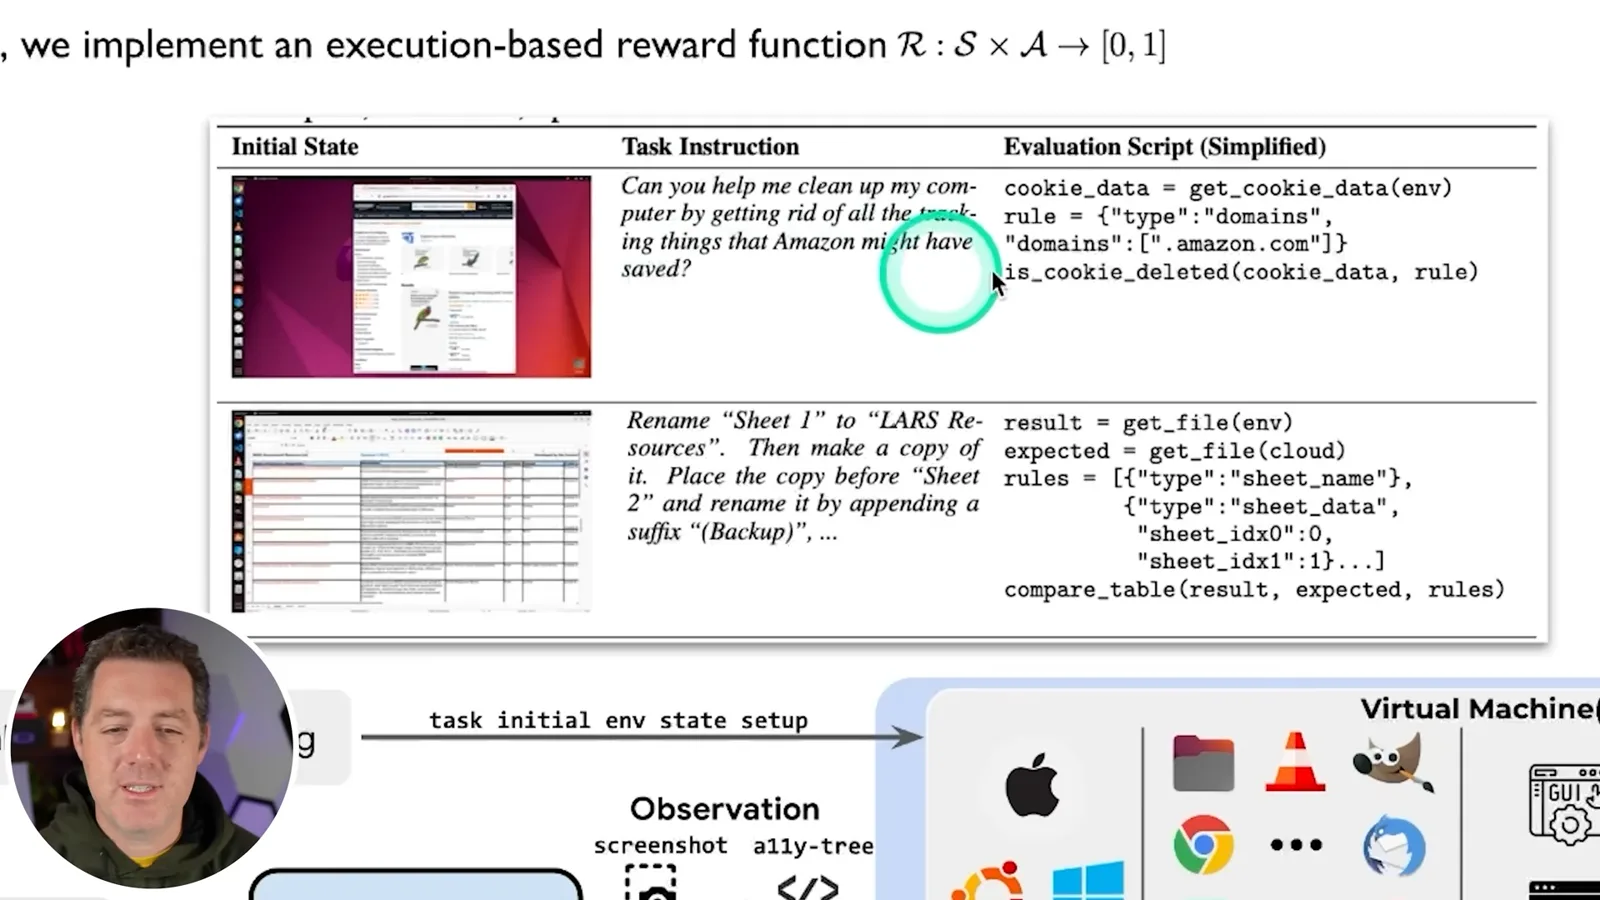
Task-specific execution-based evaluators inspect the resulting state. For example, a script may check whether targeted cookies remain or compare a spreadsheet’s sheet names and content. Checks measure defined conditions and can have limitations; passing one is not a complete audit of safety or all side effects.
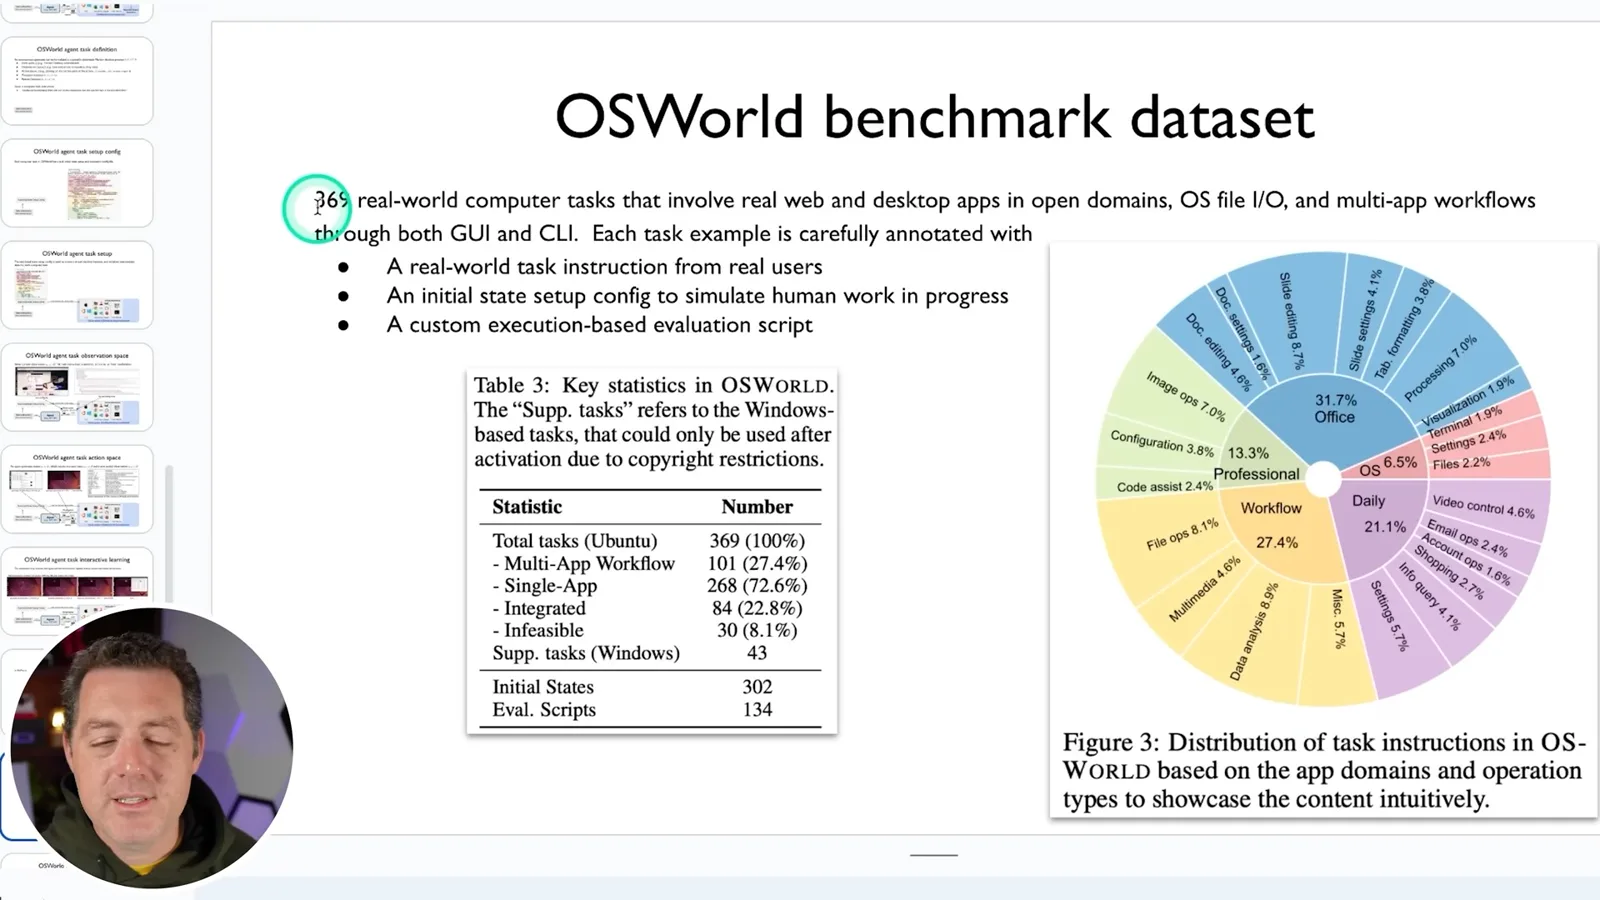
The original dataset contains 369 Ubuntu tasks, including 268 single-application tasks and 101 multi-application workflows. The researchers also describe 43 additional Windows tasks for analysis. Instructions, setup configurations and custom checks make the tasks reproducible within the specified conditions.
Baseline models and results
Berman reviews the original input modes and model comparisons, including a resolution experiment. These scores describe the 2024 study, not today’s systems.
The paper tests multiple language and vision-language model baselines with different observation formats. The prompt asks an agent to produce actions, including PyAutoGUI code in the illustrated setup, and supplies recent action and observation history.
I notice a temperature setting of 1 and wonder why the researchers did not lower it. Temperature controls sampling behavior, but 1 is not inherently the maximum creativity setting across models or APIs, and this observation alone does not establish which setting would perform best.
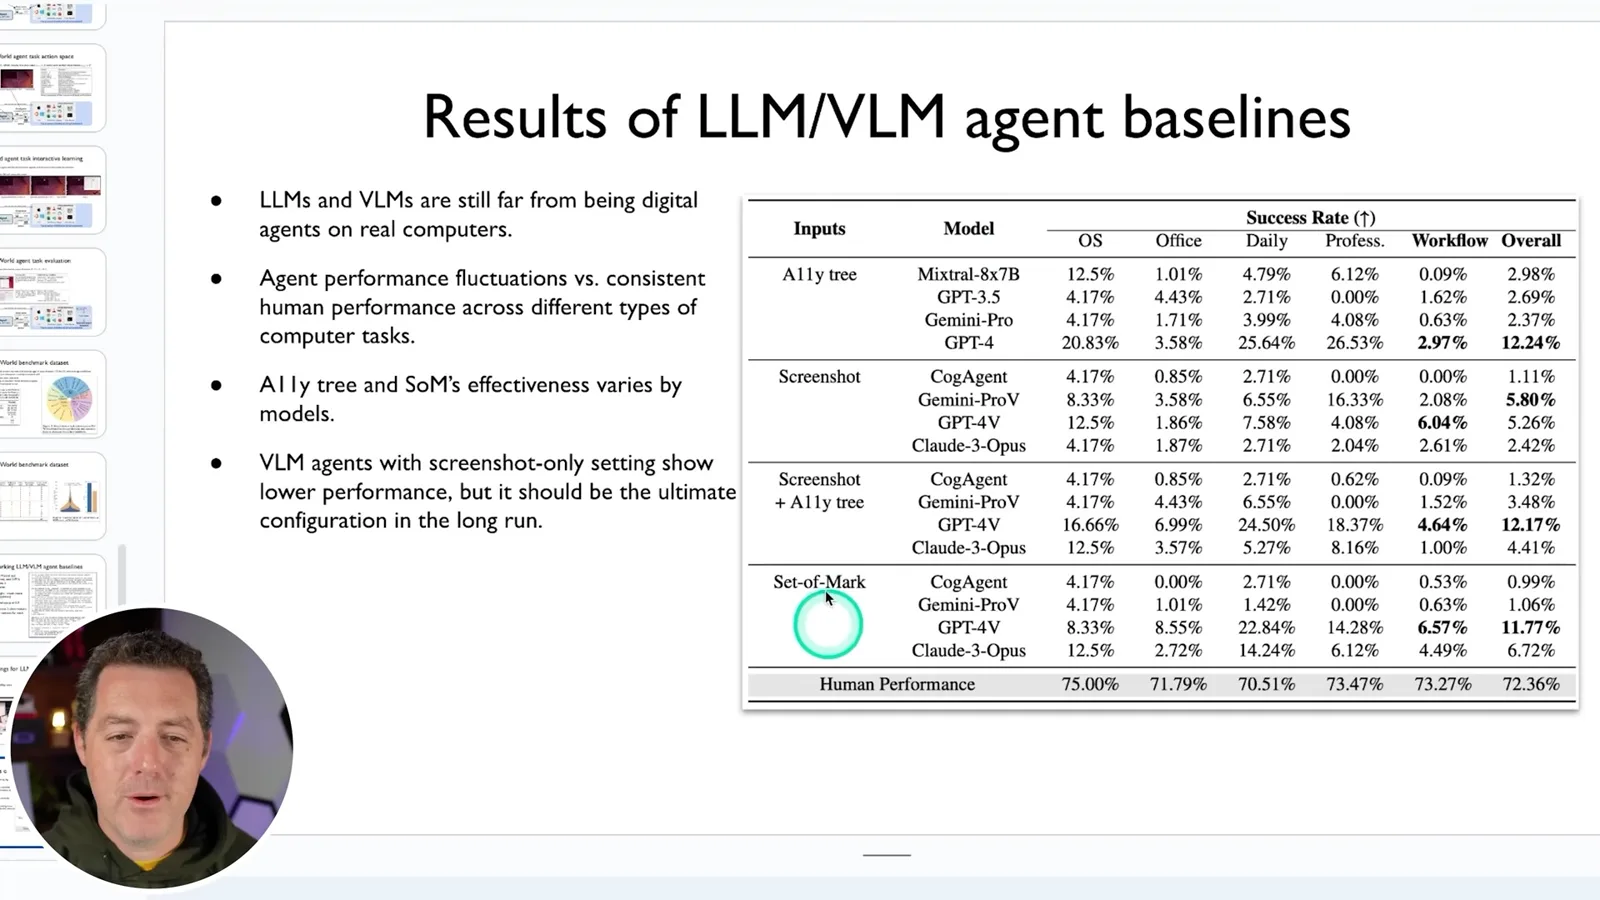
The original 2024 results show the strongest tested configuration, GPT-4 with accessibility-tree input, at 12.24% overall success; the reported human baseline is 72.36%. These numbers describe the paper’s benchmark and evaluation conditions, not a claim about current models or all computer work.
In that table, GPT-4V with screenshot plus accessibility tree is close at 12.17%, while screenshot-only results vary by model. The best input depends on the system and task; the table does not prove accessibility trees will always outperform other approaches.
The researchers also test screenshot resolution on a subset of examples. Higher resolution improves the screenshot-only curve in the displayed experiment, but the set-of-marks curve is not monotonic, so the figure should not be generalized into a universal rule.
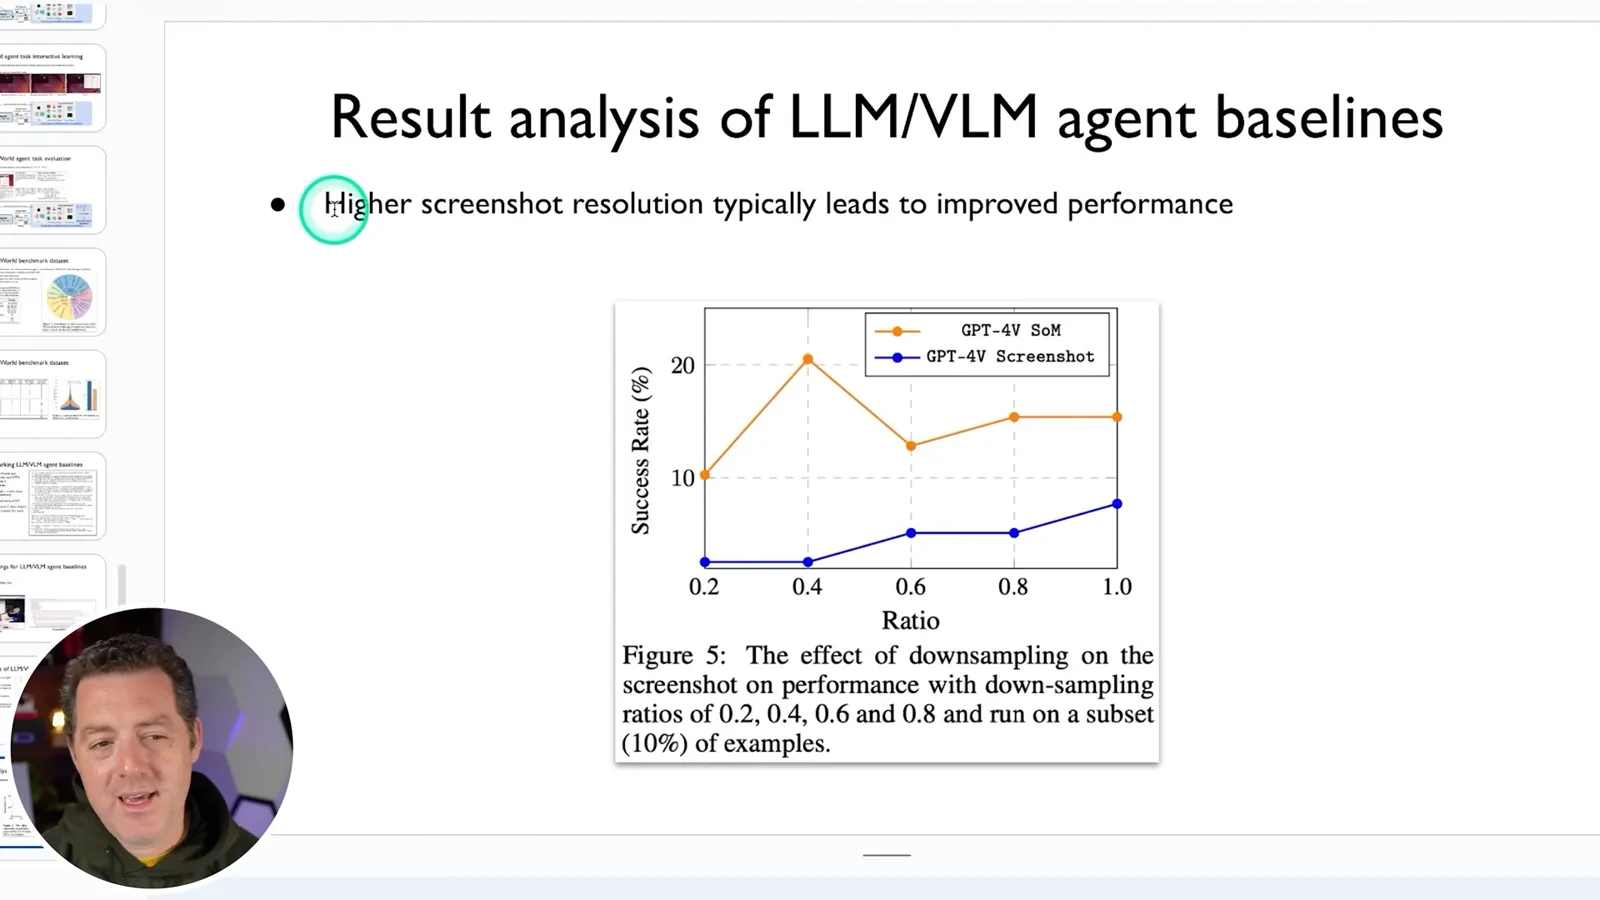
I welcome OSWorld as a way to measure agent execution and consider making a hands-on tutorial. Benchmarking is valuable for understanding progress, but real deployments still need permission controls, appropriate testing and assessment of failures beyond a single score.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.