En 30 segundos
Matthew Berman tests OpenAI o1-preview shortly after its September 2024 release, running prompts on Python Tetris, envelope dimensions, word counting and physical reasoning. He praises several answers while identifying a North Pole problem in which the model confuses the original starting point with the later turning point. The video also shows a subjective ethical question and an advanced mathematics answer that Berman does not independently verify. These are illustrative one-off tests, not a comprehensive evaluation or current ranking.
- 1Preview and TetrisThe model generates a playable Tetris demo in the run shown; Berman reports a previous run needed a correction.
- 2Envelope dimensionsThe model converts and checks the given dimensions, including their orientation.
- 3Cup and marbleThe model explains that the marble can remain on the table when the inverted cup alone is lifted.
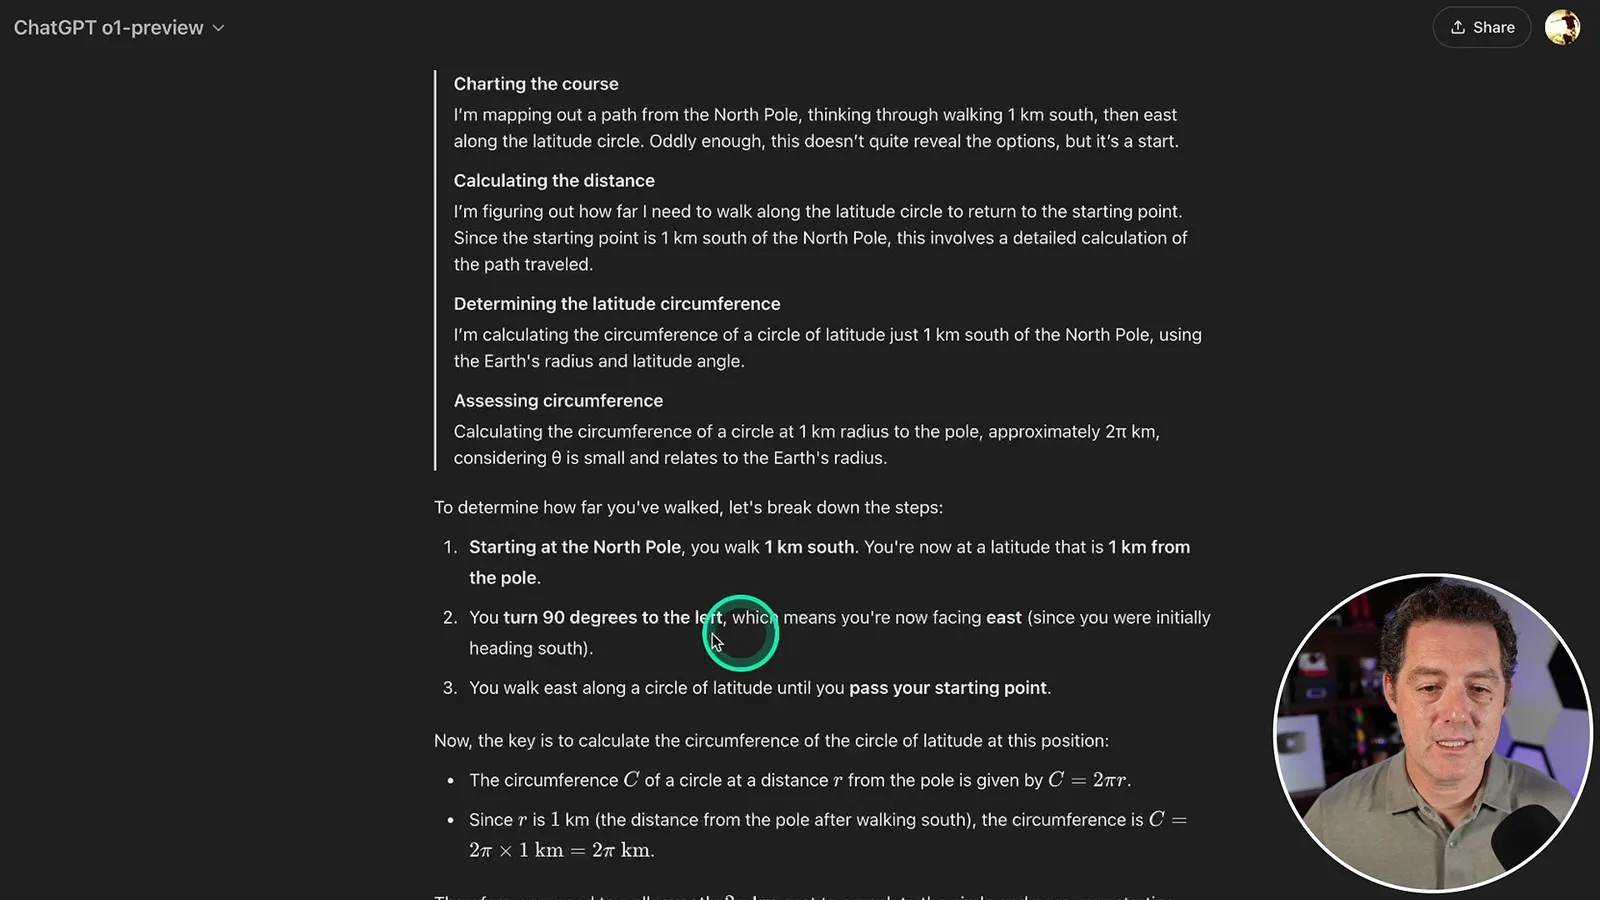
- 4North Pole errorIts latitude-circle explanation returns to the turning point rather than the original pole.
- 5Unverified math answerThe preview returns 721 for a harder prompt; Berman does not independently check it.
Conclusiones
- The demonstrated Tetris program runs in a brief first-attempt play test, although that does not verify every game mechanic.
- The model checks the orientation of an envelope against the dimensions supplied in the prompt.
- Its inverted-cup answer distinguishes an object resting on the table from the cup that is lifted.
- In the North Pole test, the model mistakes the later turning point for the original starting point.
- The visible thinking text is a summary, while a subjective ethics judgment and an unchecked math answer require different evaluation from objective tasks.
Lee el texto editado por capítulos
An early o1-preview coding test
Berman notes the similarity between an OpenAI example and his marble question, then tests a generated Tetris game. The displayed reasoning is a summary.
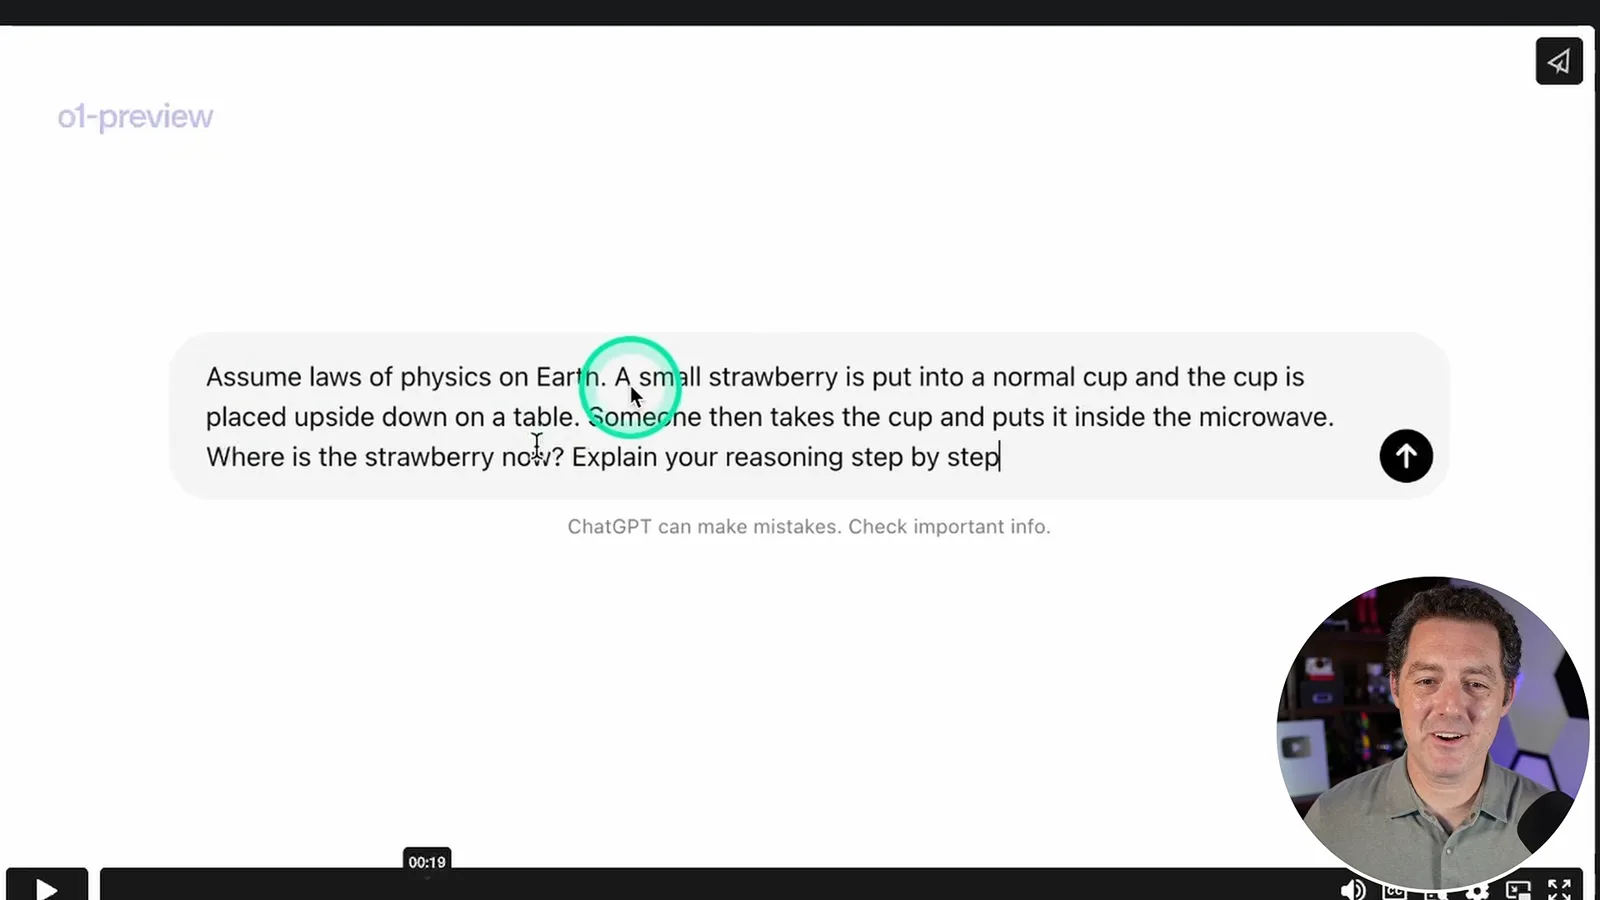
In September 2024, Matthew Berman tries OpenAI’s newly released o1-preview against his informal language-model rubric. He notices an OpenAI launch example involving a strawberry beneath an inverted cup that closely resembles his own marble question. He speculates that the company may have seen his videos, but does not establish that connection.
Berman chooses o1-preview in ChatGPT and begins with a request for Tetris in Python. He notes that the visible thinking text is a summary rather than the model’s raw internal reasoning. This run takes about 35 seconds before output; he says a prior run took longer and initially produced code that needed a correction.
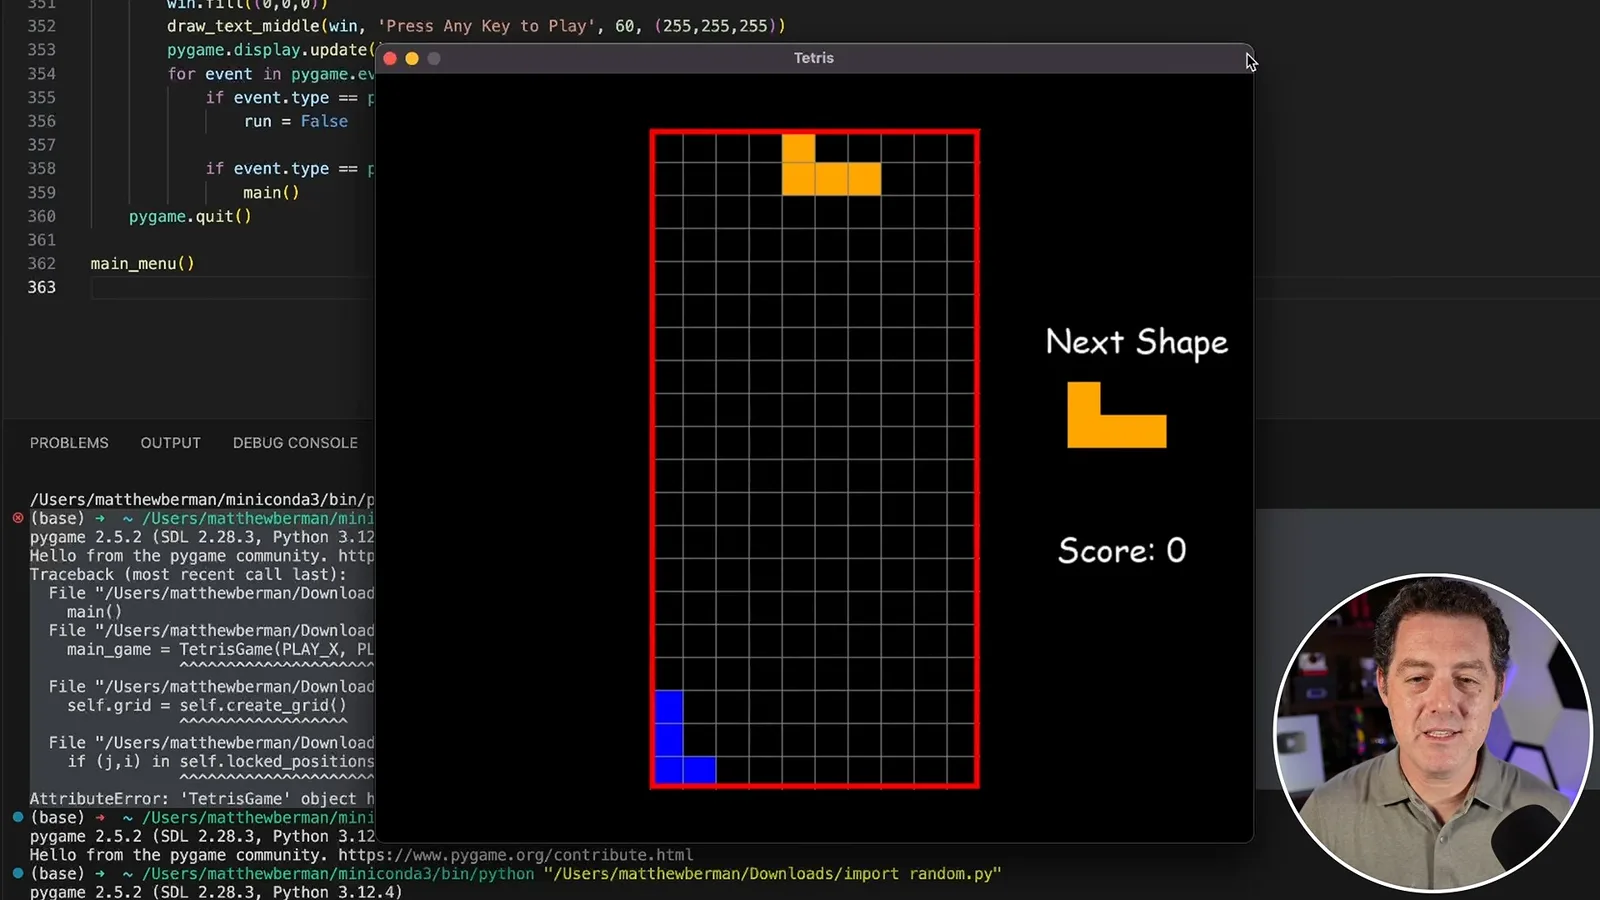
The new Tetris program runs on his first attempt, displays the next piece and score, and appears playable during the short demonstration. Berman considers it a pass and stronger than his previous test. A brief play session does not establish that all game mechanics are correct.
Dimensions, word count and puzzles
The model checks an envelope, counts its own words and considers the killers and inverted-cup scenarios. Berman scores individual outputs.
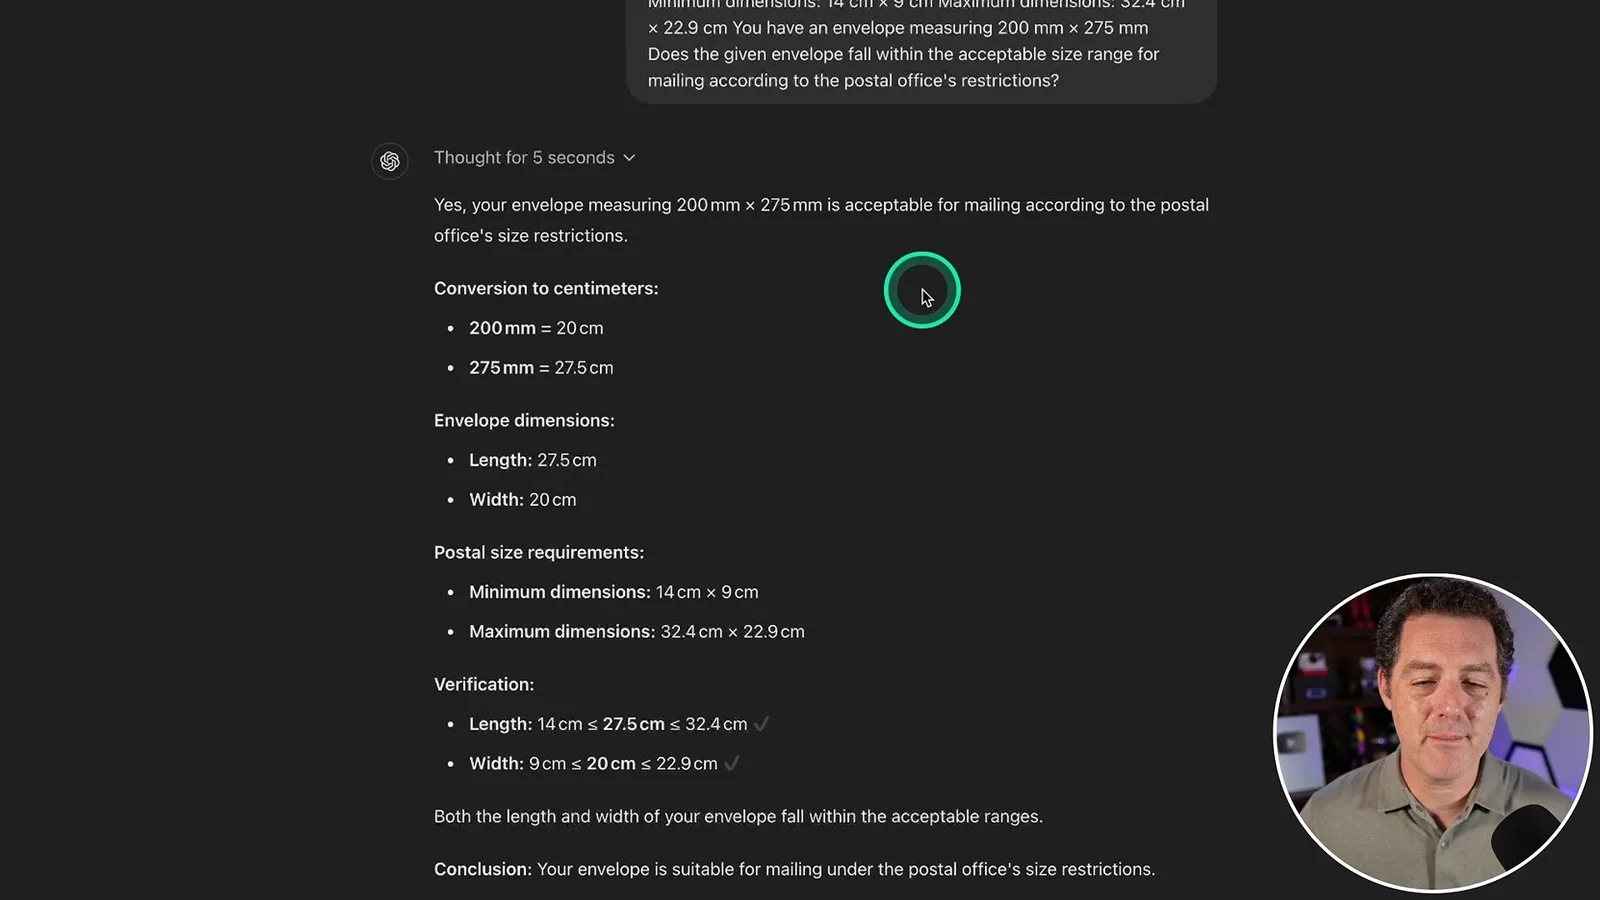
Next he asks whether a 200 × 275 mm envelope fits specified postal limits. The model converts the measurements, compares 27.5 cm and 20 cm with the given minimum and maximum dimensions, and answers yes. Berman praises it for considering orientation; the result applies to the restrictions in the prompt, not a current postal rule.
Asked how many words its response contains, the model returns “This response contains five words,” which Berman counts as five. He notes a previous correct run as well and interprets the result as evidence of reasoning, though two examples alone cannot establish how consistently it will succeed.
In the three-killers puzzle, a newcomer kills one person and nobody leaves. The model counts three living killers: two original survivors and the newcomer. It also notes that counting the dead person as a killer changes the interpretation, a nuance Berman welcomes.
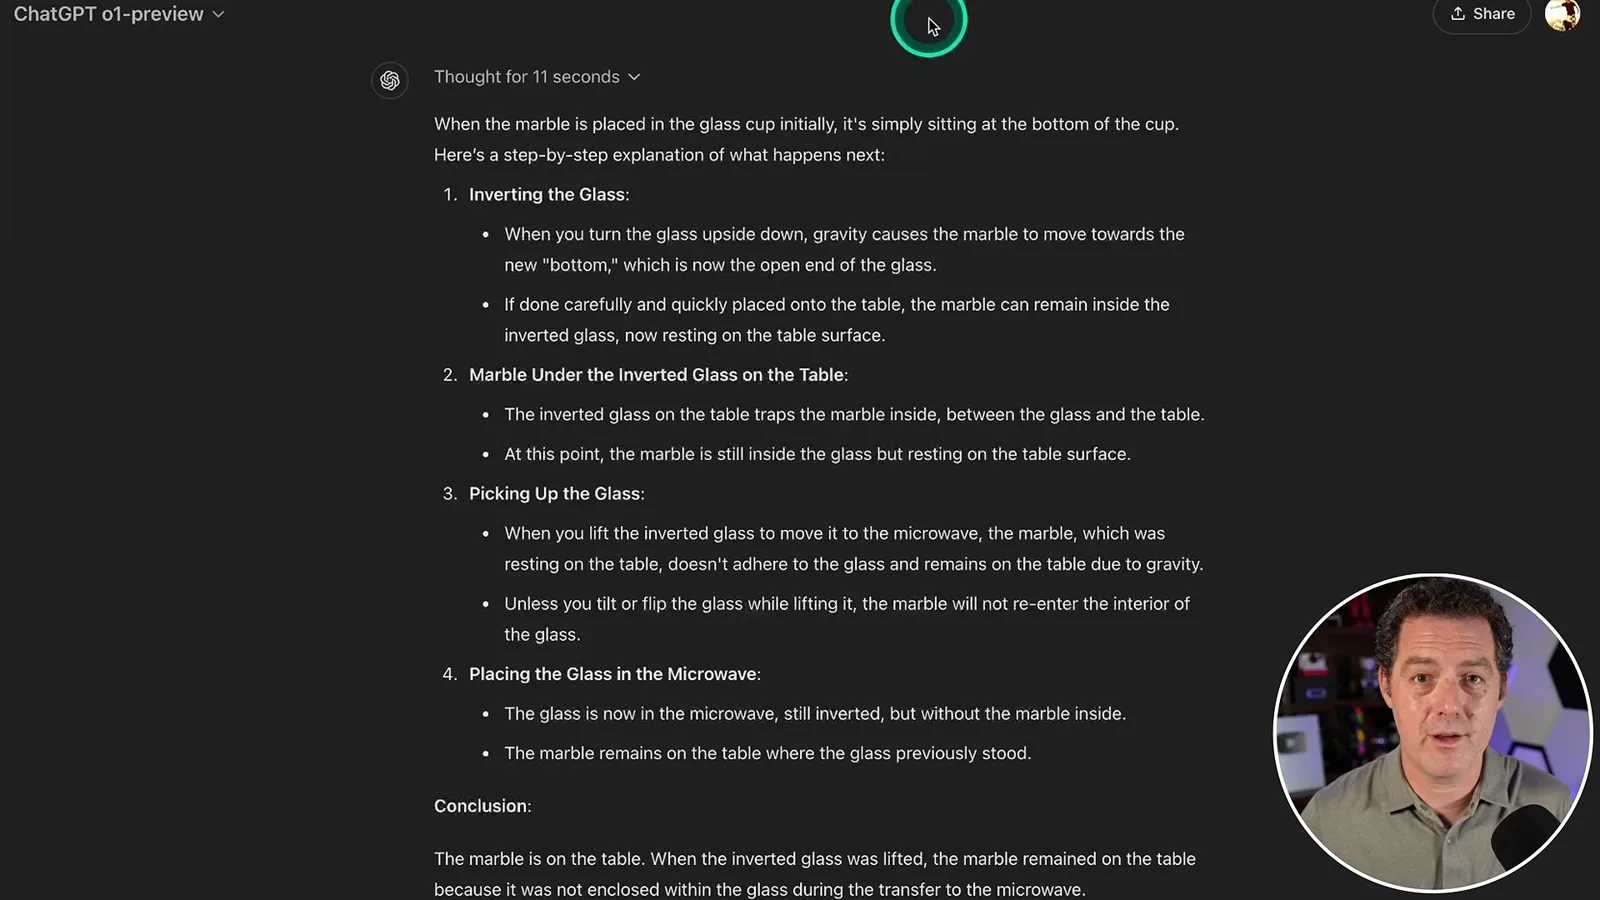
The marble question places a marble in a cup, inverts the cup onto a table, and moves the cup to a microwave. The model recognizes that the marble could remain under the inverted cup if placed carefully and, if the cup alone is lifted, remain on the table. Berman praises the response for identifying assumptions rather than treating every physical step as unambiguous.
A North Pole mistake and more tests
The model confuses the original starting point with a later location. Berman then tries spelling, decimals, an ethics hypothetical and a mathematical prompt.
A North Pole question asks a person to travel one kilometer, turn left 90 degrees and walk until passing the original starting point. The model assumes an eastward latitude circle and computes roughly 2π km, but conflates the pole with the point one kilometer south. Berman marks the answer wrong: circling that latitude returns to the turn point, not the original pole.
The model supplies ten sentences ending in “apple,” counts three instances of the letter r in “strawberry,” and identifies 9.9 as greater than 9.11. Berman marks these as passes in the runs shown, without claiming a formal repeated evaluation.
For a hypothetical ethics question about gently pushing a person to prevent human extinction, the model initially discusses different ethical frameworks. When pressed for a yes-or-no answer, it says yes. Berman agrees with that judgment, while the test is an opinion about a hypothetical case rather than an objectively scored mathematics problem.
Berman tries a suggested advanced mathematics prompt. The model returns a formatted derivation and an answer of 721 after about 52 seconds; he says he cannot readily solve the problem himself, so the video does not independently verify the result.
Asked whether the chicken or the egg came first, the model answers that eggs existed before chickens in evolutionary history. Berman concludes that o1-preview is the strongest model he has personally tested and says it missed the North Pole problem. His conclusion reflects a small set of prompts and the September 2024 preview, not a current ranking or proof of overall reliability.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25 oct 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24 oct 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.