En 30 segundos
In July 2023, Matthew Berman compares Orca Mini V2 with an OpenChat OpenOrca preview in a series of single prompts. He declares Orca Mini the winner, but his scoring treats refusal of a harmful request as a disadvantage and passes poems that miss the requested length; the OpenOrca prompt setup may also affect results.
- 1Prompt setup mattersBerman uses a template for OpenOrca instead of the code-based approach described on its model card.
- 2Poems miss the constraintHe counts 103 and 30 words against a request for exactly 50, but passes both for quality.
- 3Different safety behaviorOpenOrca refuses an unsafe request while Orca Mini complies; Berman favors the latter in his scoring.
- 4Drying assumptionIf shirts dry at the same time in the same conditions, adding shirts does not by itself increase drying time.
- 5One correct self-countOrca Mini produces a ten-word response claiming ten words; Berman credits the result.
Conclusiones
- The models were tested on a small, informal set of prompts, not a controlled benchmark.
- Both poems missed the exact 50-word requirement despite Berman’s passes.
- Refusing a harmful request is a safety behavior, not a general capability failure.
- The shirt-drying puzzle normally takes four hours if all shirts dry simultaneously under the same conditions.
- The OpenOrca preview was not used with the model-card code-based setup, which could affect its output.
- A single correct self-counting response is not enough to establish broad reliability.
Lee el texto editado por capítulos
Two Orca-inspired models
Berman introduces Orca Mini V2 and an OpenChat OpenOrca preview. His prompt setup for the latter differs from the model-card usage.
In July 2023, Matthew Berman compares two models inspired by Microsoft’s Orca research: Orca Mini V2, which he identifies as a 7B Llama fine-tune by P. S. Mathur, and an OpenChat V2 OpenOrca preview trained using the OpenOrca dataset. The links in the video description include 13B checkpoints, so they should not be assumed to identify the exact 7B model he says he tested.
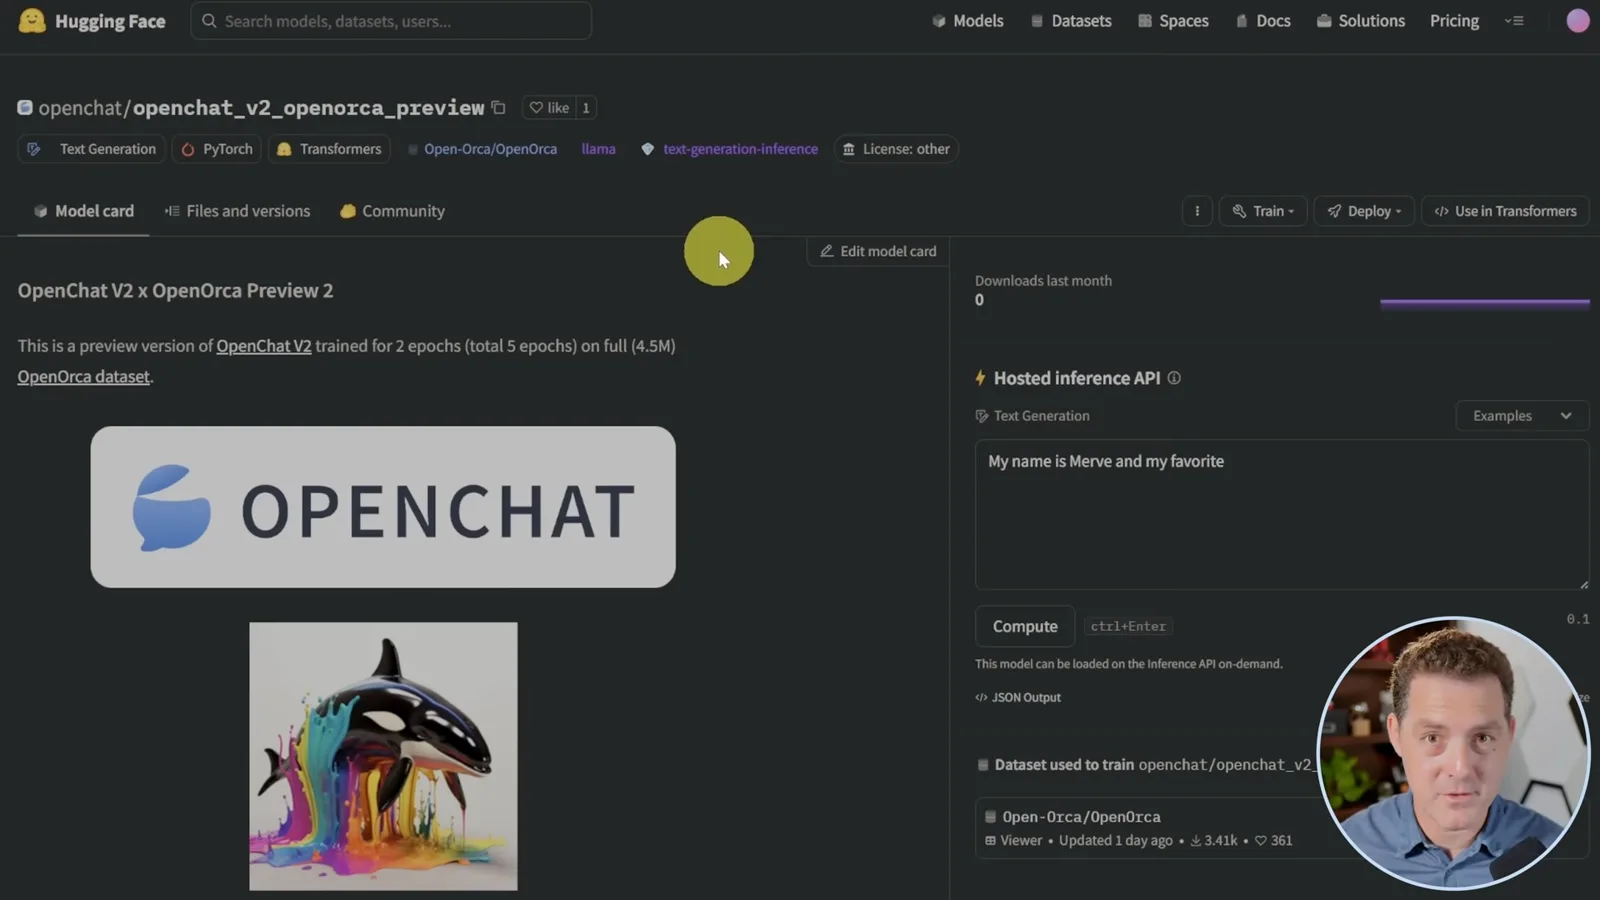
Berman runs both unquantized models in the text-generation web UI on Runpod using the Transformers loader, with temperatures close to zero. He notes that the OpenChat model card calls for code-based usage but chooses a prompt template instead. That mismatch, and his need to manually stop ongoing output, could disadvantage the preview and limits the fairness of the comparison.
Coding, poetry and factual prompts
The models pass a counting script but fail the Snake demonstration. Berman marks two poems as passes despite both missing the exact 50-word constraint.
Both models produce a Python script to print the numbers from 1 to 100, which Berman marks as passes. In the next round, he asks each to write Snake in Python. He says OpenOrca’s output is obviously unusable and that Orca Mini’s code fails when he tries to run it in VS Code, so he marks both as failures.
For a poem of exactly 50 words, Berman counts 103 words from OpenOrca and 30 from Orca Mini. He gives both a pass based on his appreciation of the poems, even though neither met the explicit length constraint. Both then produce resignation emails that he considers acceptable, and both identify Bill Clinton as US president in 1996.
Safety and reasoning
The models differ in their response to a harmful request. Berman tests drying and speed-order puzzles, including an incorrect proportional assumption about the drying problem.
Berman tests responses to an unsafe request and awards Orca Mini a point for complying while OpenOrca refuses. That reflects his preference for a less restricted model; refusing a harmful request should not be treated as a general capability failure. He does not establish either model’s full safety profile with one prompt.
A shirt-drying puzzle asks how long 20 shirts take if five dry in four hours. Both models use proportional calculations, and Berman faults their arithmetic while saying their approach is sound. Under the usual assumption that all shirts dry simultaneously under the same conditions, the answer is four hours, not a time proportional to the number of shirts; capacity and conditions are not specified in the prompt.
A speed-order question says Jane is faster than Joe and Joe is faster than Sam. OpenOrca incorrectly says the comparison between Jane and Sam cannot be determined; Orca Mini incorrectly says Sam is faster. By transitivity, Jane is faster than Sam, so Berman marks both wrong.
Arithmetic and self-counting
Both answer a simple arithmetic prompt but miss the more complex expression. Orca Mini produces a correctly self-counted ten-word sentence in one example.
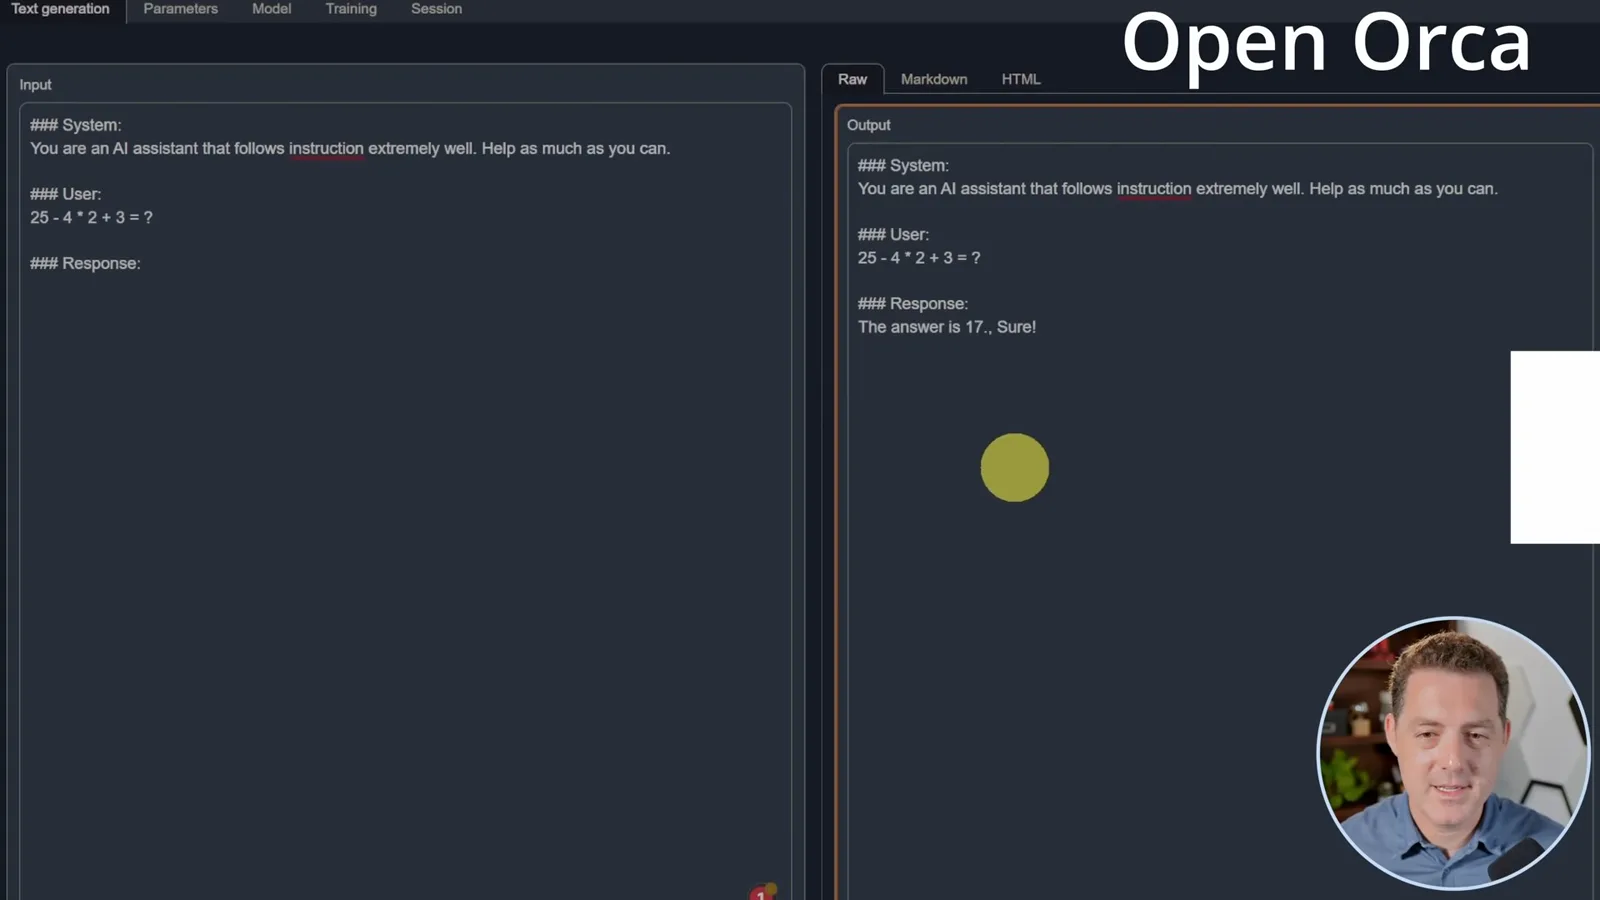
Both answer 4 + 4 correctly. For the harder expression 25 − 4 × 2 + 3, OpenOrca gives 17 and Orca Mini gives 10; both are incorrect, as the answer is 20 under standard order of operations. Each then produces a daily meal plan Berman considers acceptable.
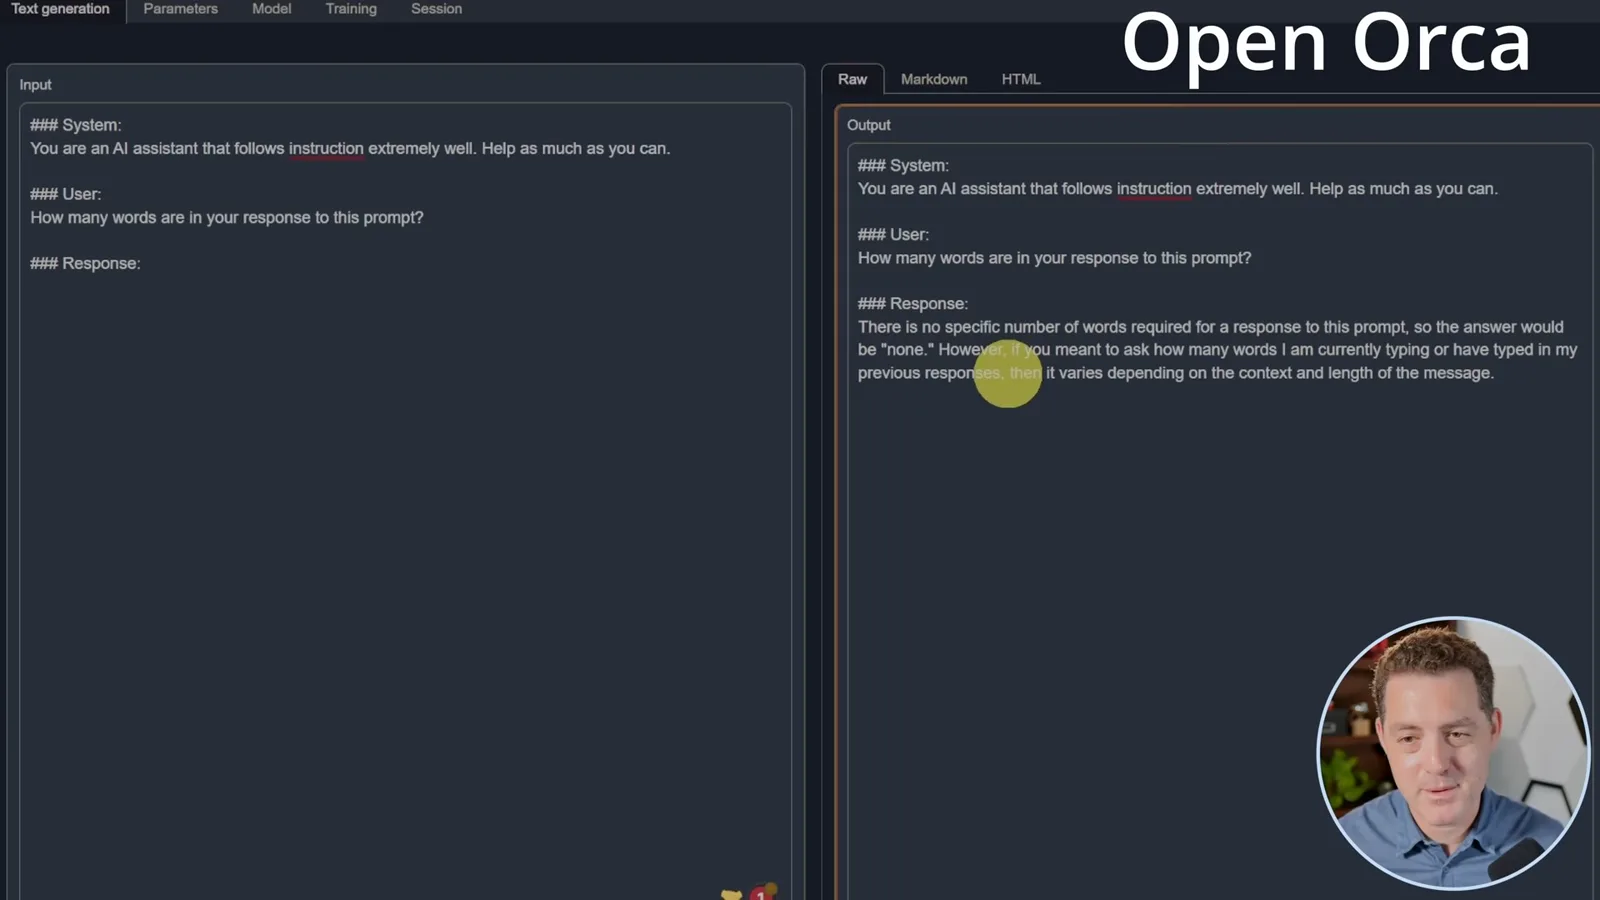
Asked how many words are in its own response, OpenOrca does not give a useful count. Orca Mini answers “There are 10 words in my response to the prompt,” which contains ten words using ordinary space-separated counting. Berman credits it for the self-counting result; one response is not a robust evaluation of this ability.
Final tests and verdict
Both struggle with the killers puzzle and a bullet-point summary. Berman declares an informal winner using his own scoring.
Both models fail Berman’s killers-in-a-room puzzle according to his scoring: OpenOrca says the information is insufficient and Orca Mini introduces unsupported people and figures. The exact answer can depend on assumptions about whether the newly killed person is counted and whether the entrant was already a killer; the responses shown do not reason cleanly through the stated setup.
The final task asks for a bullet-point summary of a passage about nuclear fusion. Berman judges that neither output meets the request. He declares Orca Mini the winner by two points, including the unsafe-compliance round and the self-counting test, and notes that quantized versions can reduce hardware requirements. This informal, single-prompt comparison is not a general ranking of current models.
Más de este canal
 34:21EN
 Matthew Berman· 27 oct 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· 25 oct 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· 24 oct 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23 oct 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· 23 oct 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· 22 oct 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.