In 30 seconds
Matthew Berman examines Stability AI’s StableVicuna announcement and tries its hosted demo in May 2023. The model produces simple text and working counting code, misses a transitive reasoning question, and responds slowly during his session.
- 1Instruction tuning and RLHFStability AI describes using public datasets and trlX to further train Vicuna v0 13B.
- 2Poetry and codeThe generated poems miss the requested word count, while the counting program outputs 100 numbers from zero through 99.
- 3A reasoning failureThe model fails to infer that Joe is slower than Mark when Mark is faster than Mary and Mary faster than Joe.
- 4An ordinary emailThe model produces a conventional resignation email with placeholders, though generation is slow in this session.
Takeaways
- StableVicuna further tuned Vicuna v0 13B with instruction data and reinforcement learning from human feedback.
- Stability AI called it a first large-scale open-source RLHF chatbot, a claim presented as the company’s characterization.
- The delta model card carries a non-commercial license, and the underlying LLaMA terms also matter.
- The small informal test showed useful simple outputs but a clear logical error and slow responses.
Read the edited text by chapter
What StableVicuna adds
Berman explains instruction tuning and RLHF, then reviews the model’s lineage and access. Licensing restricts commercial use.
StableVicuna continues the animal-themed lineage of LLaMA, Alpaca and Vicuna. Stability AI describes it as a large-scale chatbot trained with instruction fine-tuning and reinforcement learning from human feedback, or RLHF. The company calls it a first; that is its historical claim, not a claim I independently establish here.
Instruction tuning teaches a model with examples of instructions and desired answers. RLHF uses human preference information in a training process to shape responses; it does not necessarily mean the model continuously trains on every live user interaction. Stability AI cites public datasets and the trlX training framework in its announcement.
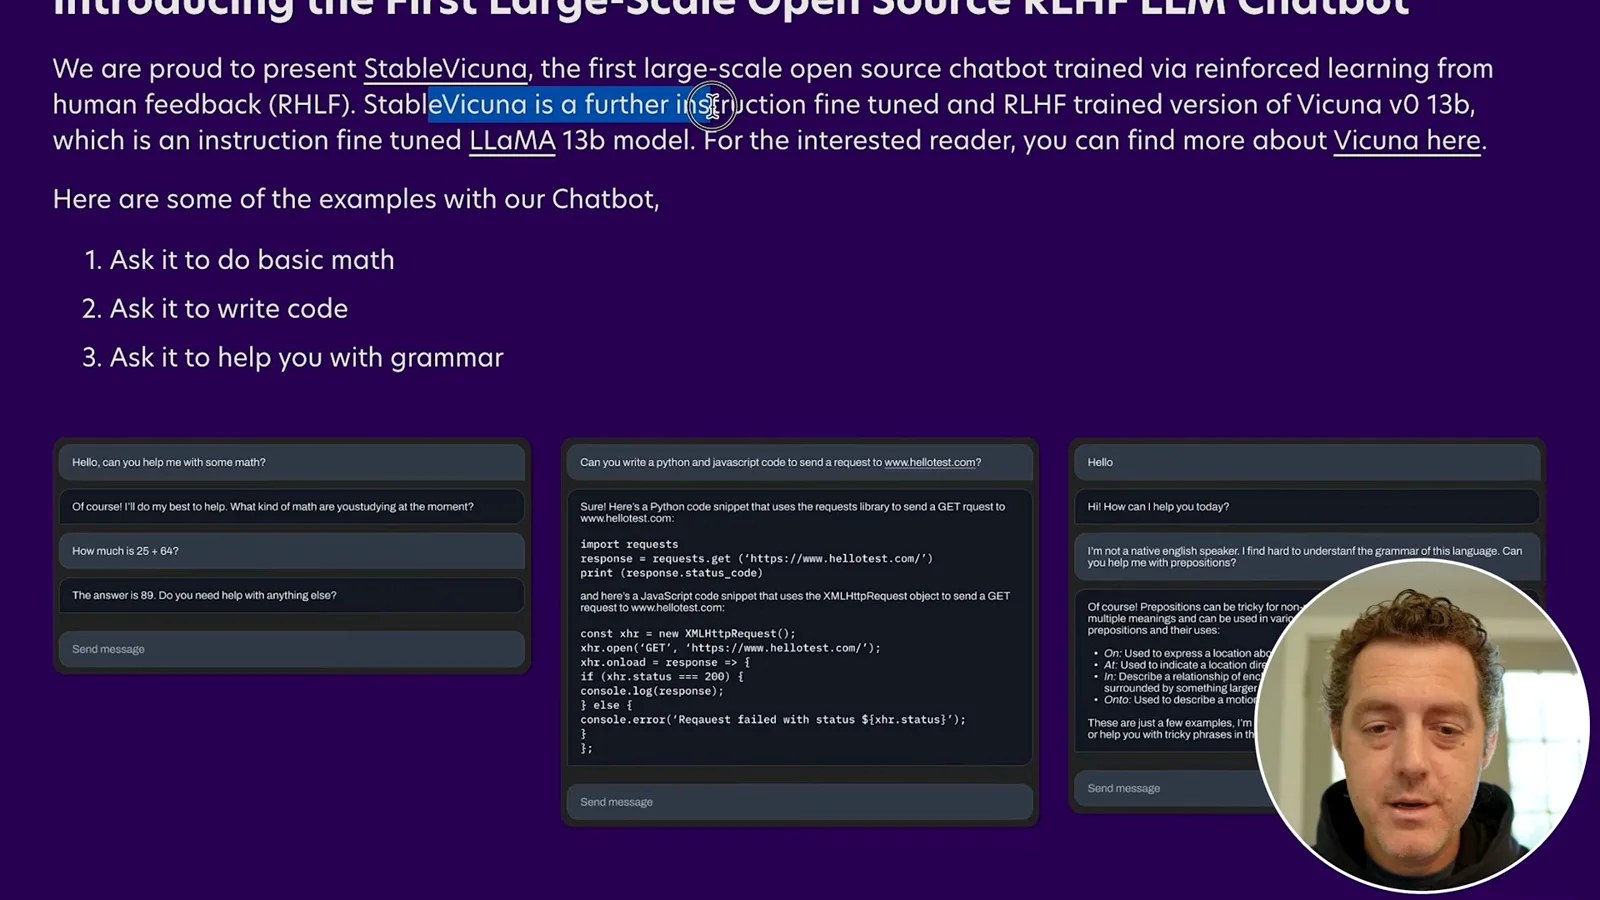
StableVicuna is a further instruction-tuned and RLHF-trained version of Vicuna v0 13B, which itself is based on LLaMA 13B. I call it open source but caution about commercial use. The published delta model card lists a non-commercial license, and users must also consider the underlying model’s terms; released weights do not automatically imply unrestricted commercial use.
Stability AI gives examples involving basic math, code and grammar, and points to a hosted Hugging Face interface as well as model downloads. I use the hosted Gradio demo for this May 2023 test rather than run the 13-billion-parameter model locally. Availability and speed may have changed since then.
Testing the model
He tries poetry, Python, a logic question and a resignation email in the hosted demo. The small sample includes a reasoning failure and slow responses.
First I ask for a 50-word poem about AI twice. The outputs are short and do not appear to meet the requested word count; one takes a surprisingly ominous tone and the other is more upbeat. These examples show the model can produce plausible text, but not reliably obey this length constraint.
Next I ask for Python code that counts to 100. I run the generated program and it prints zero through 99: 100 numbers, though it does not include 100. The model responds slowly compared with my experience of GPT-3.5, and I suspect more complex programming would be harder, but this single test does not establish a broad ranking.
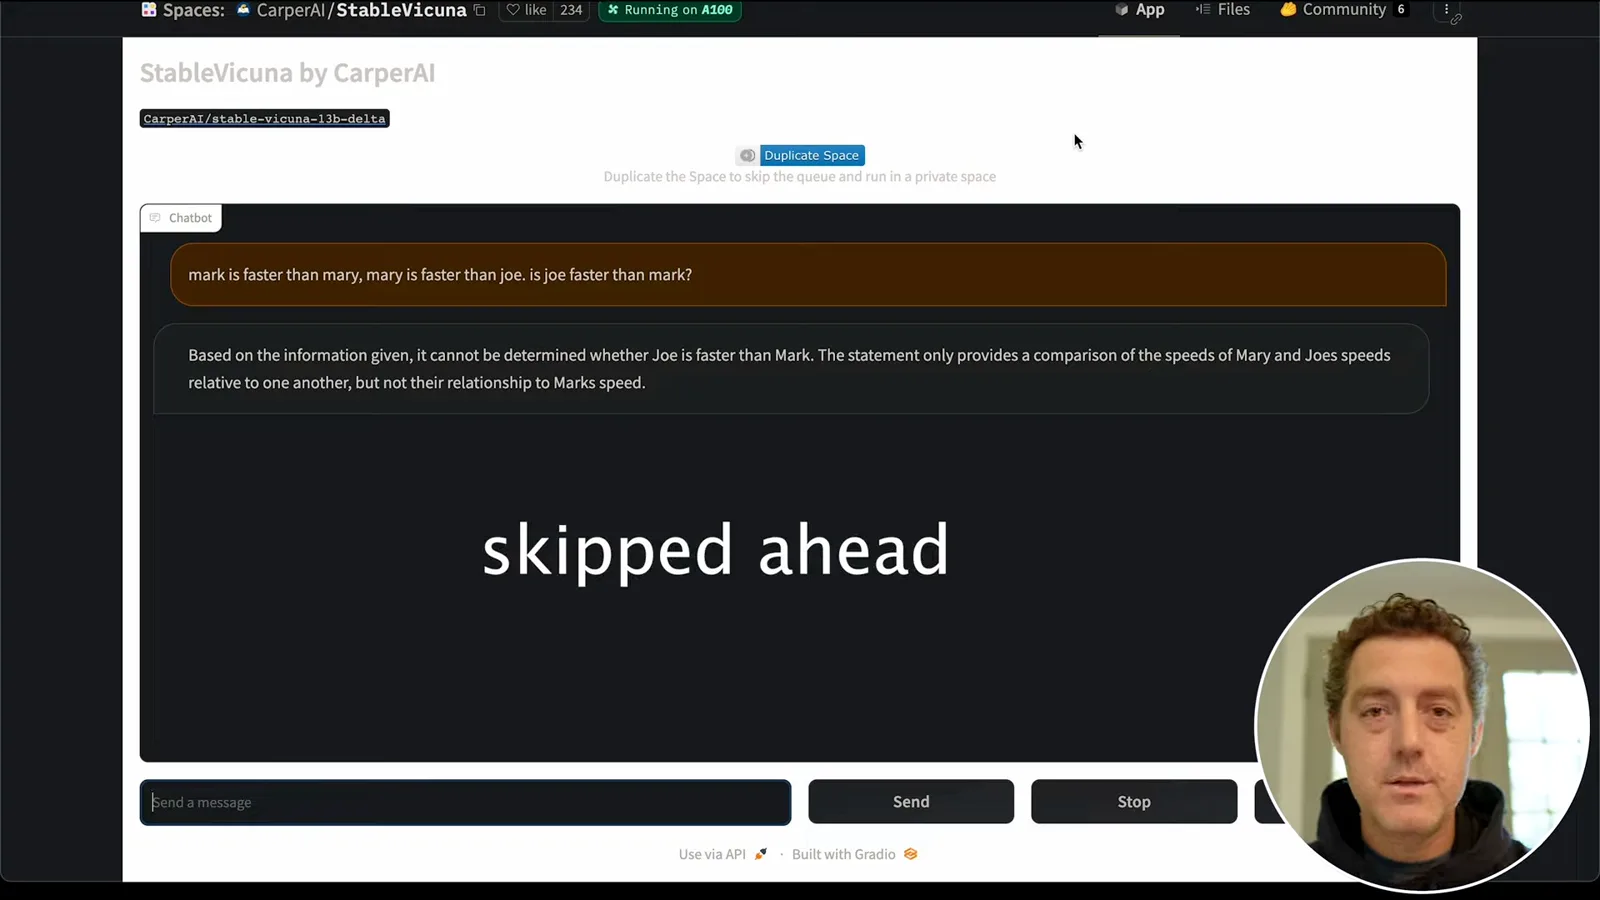
For a reasoning question, I state that Mark is faster than Mary and Mary is faster than Joe, then ask whether Joe is faster than Mark. After a slow response and retry, the model says the answer cannot be determined. That is incorrect: the stated comparisons imply Mark is faster than Joe.
Finally I ask for an email telling a boss I am leaving the company. The model produces a conventional resignation note with placeholders for the date and sender. I find it straightforward and usable as a draft, although generation is slow in this session; heavy demand is only a possible explanation, not a confirmed diagnosis.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· Oct 25, 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· Oct 24, 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.