In 30 seconds
Theo introduces Fable 5 as a Mythos-class model with additional safeguards and reviews early benchmark results. He cautions that refusals can affect comparisons and questions the reliability of SWE-bench Pro, while sharing his interpretation of other coding evaluations.
- 1Fable and MythosTheo says Fable offers a Mythos-class model with additional safeguards.
- 2Refusals affect scoresHe says Fable refused some benchmark tasks and reports a roughly 20-point Terminal-Bench gap versus Mythos in the comparison shown.
- 3Questioning a benchmarkHe reports a strong SWE-bench Pro result but questions whether the benchmark's existing pull requests make the score reliable.
- 4Early coding resultsTheo discusses DataCurve results and his interpretation of performance and cost on that evaluation.
Takeaways
- Theo describes Fable 5 as a safeguarded way to access a Mythos-class model.
- Refusals on benchmark tasks can lower the score of a safeguarded model.
- Theo questions whether SWE-bench Pro adequately measures new problem-solving rather than familiarity with existing pull requests.
- He views early FrontierCodeBench and DataCurve results as promising, while individual benchmark results have limited scope.
- His cost comparison reflects the measured tasks and usage at the time, not a universal price advantage.
Read the edited text by chapter
Safeguards and benchmark results
Theo introduces Fable and Mythos. He explains why refusals complicate benchmark comparisons.
We have heard about Mythos for a long time, and now we have Fable 5: a Mythos-class model with additional safeguards rather than unrestricted access to Mythos 5. I want to look at what it can do and how the early benchmarks should be interpreted.
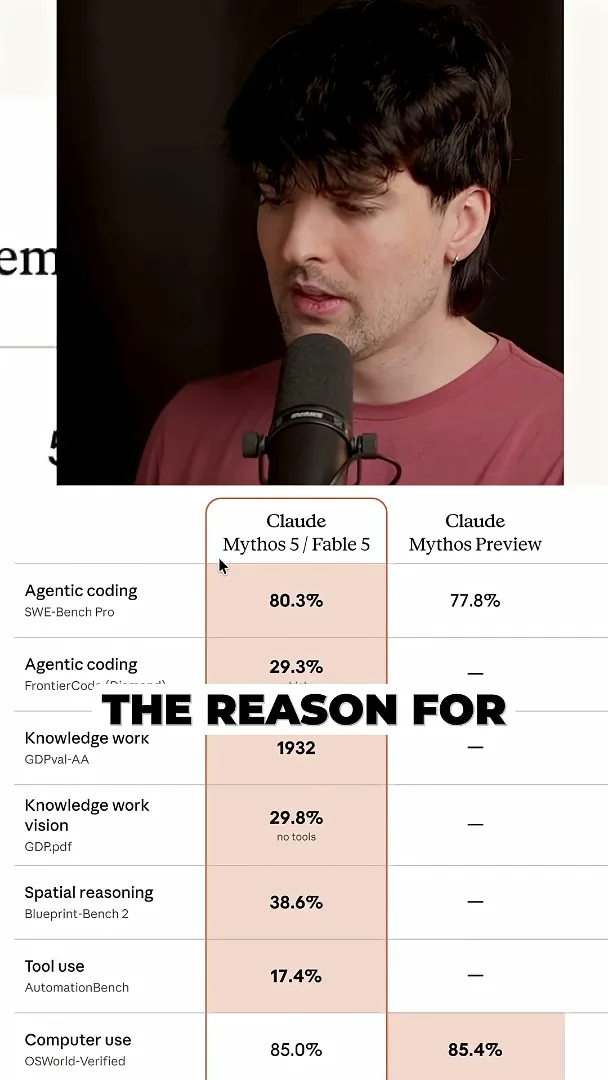
Some benchmark tables group Mythos 5 and Fable 5, but Fable refused certain tasks. I report a roughly 20-point drop on Terminal-Bench compared with the Mythos run. That makes it important to distinguish the underlying capability being measured from the effect of safeguards and refusals.
Evaluating coding performance
He questions SWE-bench Pro and reports other early coding results. He also discusses vision and task-specific cost.
The reported SWE-bench Pro score is around 80%, but I don't put much faith in that benchmark. Many tasks are based on existing pull requests, and I worry that exposure to relevant material in training could make reconstruction easier. That is my concern about the benchmark, not proof of contamination in a particular run.
I find FrontierCodeBench more interesting. I cite a roughly 30% result for Mythos compared with 13% for Opus 4.8 and 5.7% for GPT-5.5 in the comparison I saw. I also see an improvement in vision and spatial reasoning, though no single benchmark establishes overall superiority.
DataCurve shared early coding results with me. In the evaluation shown, I interpret Fable at high effort as comparable to GPT-5.5 and stronger than the Opus results at lower measured cost. Even with a higher model price, fewer tokens on those tasks can change the total cost; this is a task-specific comparison, not a promise for every workload.
More from this channel
 38:47EN
 Theo - t3․gg· Oct 28, 2026Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· Oct 27, 2026Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· Oct 26, 2026Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· Oct 23, 2026Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· Oct 22, 2026Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· Oct 20, 2026Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.