In 30 seconds
Matthew Berman reviews OpenAI’s paper on o1, the competition-specialized o1-ioi system and early o3 checkpoints, arguing that reinforcement learning and test-time compute point toward AGI. The paper reports a live IOI 2024 result, a relaxed-submission comparison, and a retrospective o3 evaluation as well as simulated Codeforces ratings. Those tests measure specific tasks under specified conditions, not all software engineering or general intelligence. The video was sponsored by Langtrace. The [paper](https://arxiv.org/abs/2502.06807) and [DeepMind’s AlphaGo Zero account](https://deepmind.google/blog/alphago-zero-starting-from-scratch/) also clarify points that Berman conflates: original AlphaGo used human game data, and o1-ioi’s gold-threshold result required relaxed submission limits.
- 1An argument about scalingBerman interprets the paper as evidence for a path to AGI. The reported results support a narrower claim about performance on the evaluated coding tasks.
- 2Verifiable rewardsSome tasks have automatically checkable outcomes, but tests can be incomplete and humans design the tasks and reward systems.
- 3Three systemsOpenAI compares general o1, coding-specialized o1-ioi and early o3 checkpoints with different training and selection approaches.
- 4A specialized pipelineo1-ioi samples many solutions, clusters them and reranks candidates before selecting submissions.
- 5Simulated Codeforces ratingAn early o3 checkpoint received an estimated 2,724 rating, the 99.8th percentile in the paper’s comparison with active participants.
- 6Different IOI conditionsThe live o1-ioi result was 213 points; 362.14 used 10,000 submissions per problem, while o3’s 395.64 was a later retrospective evaluation.
Takeaways
- OpenAI compared o1, coding-specialized o1-ioi and early o3 checkpoints on competitive programming.
- o1-ioi scored 213 points in the live 2024 IOI under the 50-submission-per-problem limit; its 362.14-point result used a relaxed limit.
- A later o3 checkpoint scored 395.64 points in a retrospective IOI evaluation with 50 submissions per problem.
- The 2,724 Codeforces rating and 99.8th percentile are estimates from simulated contests, not proof that o3 beat 99.8% of all human coders.
- Reinforcement learning and automated rewards still depend on human-designed problems, data, systems and evaluation choices.
- The original AlphaGo used human game records; AlphaGo Zero later learned from self-play without those records.
Read the edited text by chapter
Scaling, rewards and the AGI claim
Berman argues that reinforcement learning and test-time compute will drive broad intelligence. He explains verifiable rewards using Go and coding, but several claims require qualification.
OpenAI’s paper on competitive programming examines how reinforcement learning and test-time compute affect coding performance. I interpret this as a path toward AGI and beyond. That is my forecast: the study demonstrates progress on selected programming evaluations, not a proof of AGI or an unlimited scaling law.
I cite Sam Altman’s remarks about o3’s estimated competitive-programming standing and a future goal of reaching number one. Those are his statements and expectations, not an independently established current world rank. The paper’s own Codeforces comparison is based on simulated contests and estimated ratings.
I connect the study to DeepSeek-R1 and other reasoning-model work and emphasize reinforcement learning with verifiable rewards. I also caution that widely discussed training-cost numbers are not necessarily comparable. The video includes a sponsored segment from Langtrace; the sponsor’s advertised features and pricing are promotional claims.
A verifiable reward is useful where an output can be tested against a known criterion. In a game, a win or loss is measurable; in programming, test cases can check program behavior. This is a simplification: people still design problems, rules, tests, training systems and objectives, and a program passing limited tests can still be wrong elsewhere.
I use AlphaGo as an analogy for self-play. One correction matters: the original AlphaGo initially trained using human game records as well as later self-play. AlphaGo Zero was the subsequent system that learned from self-play without those human game records, according to DeepMind. Human researchers still designed the game setup, algorithms and training infrastructure.
Repeated self-play can produce strong strategies under a specified game and reward structure, but it does not guarantee an optimal strategy in every situation or unlimited scaling. Coding tests likewise verify only the cases and properties they cover, and many scientific problems have no simple automatic ground-truth reward.
Comparing the models
He reviews the paper’s comparison of o1, o1-ioi and early o3. The systems differ in training and test-time methods.
Returning to the paper, OpenAI compares o1 with o1-ioi, a version further trained for coding and paired with a specialized inference pipeline, and with early o3 checkpoints. The comparison asks how hand-engineered competition strategies perform against a more general model trained with additional reinforcement learning.
I describe earlier AlphaCode systems generating large numbers of candidate solutions and using selection heuristics. The paper reports up to one million candidates per problem before selecting ten. The name “Alpha” alone does not establish a specific training method, and these systems should not be treated as identical to AlphaGo.
The paper describes o1 using extended reasoning and tools to write and run code in a secure environment. Running examples can reveal failures and help refine a solution, but passing a test is not a proof of correctness on all inputs.
I compare the paper’s result to Tesla’s transition toward neural-network driving systems and argue that removing handwritten rules removes a bottleneck. That is an analogy and interpretation; the programming paper does not validate claims about Tesla’s training or show that human involvement is unnecessary.
Codeforces and the o1-ioi pipeline
OpenAI estimates ratings from simulated contests and describes candidate generation, clustering and selection. The scores depend on the evaluation protocol.
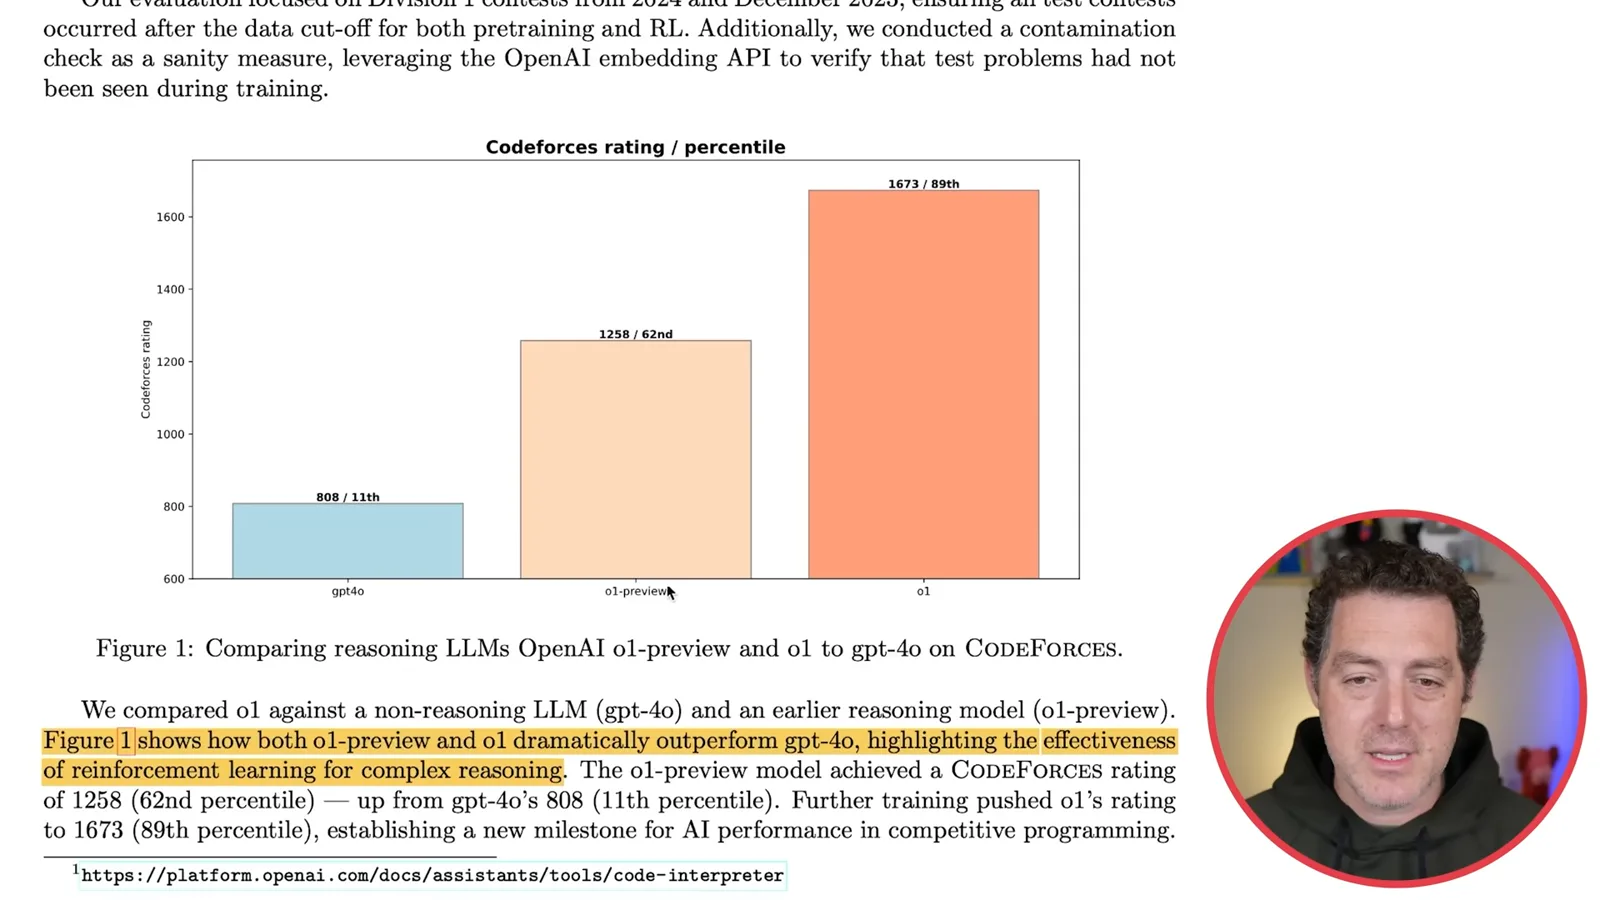
OpenAI evaluated Codeforces-style problems using simulated contests. Its estimated ratings are 808 for GPT-4o, 1,258 for o1-preview and 1,673 for o1 under its protocol. They are model estimates, not official ratings earned by human-like live participation.
The authors report improvements when they increased reinforcement-learning training compute and test-time compute. Those observations concern the tested models and tasks. Additional compute has costs, and the reported trends do not establish that performance will rise indefinitely in every domain.
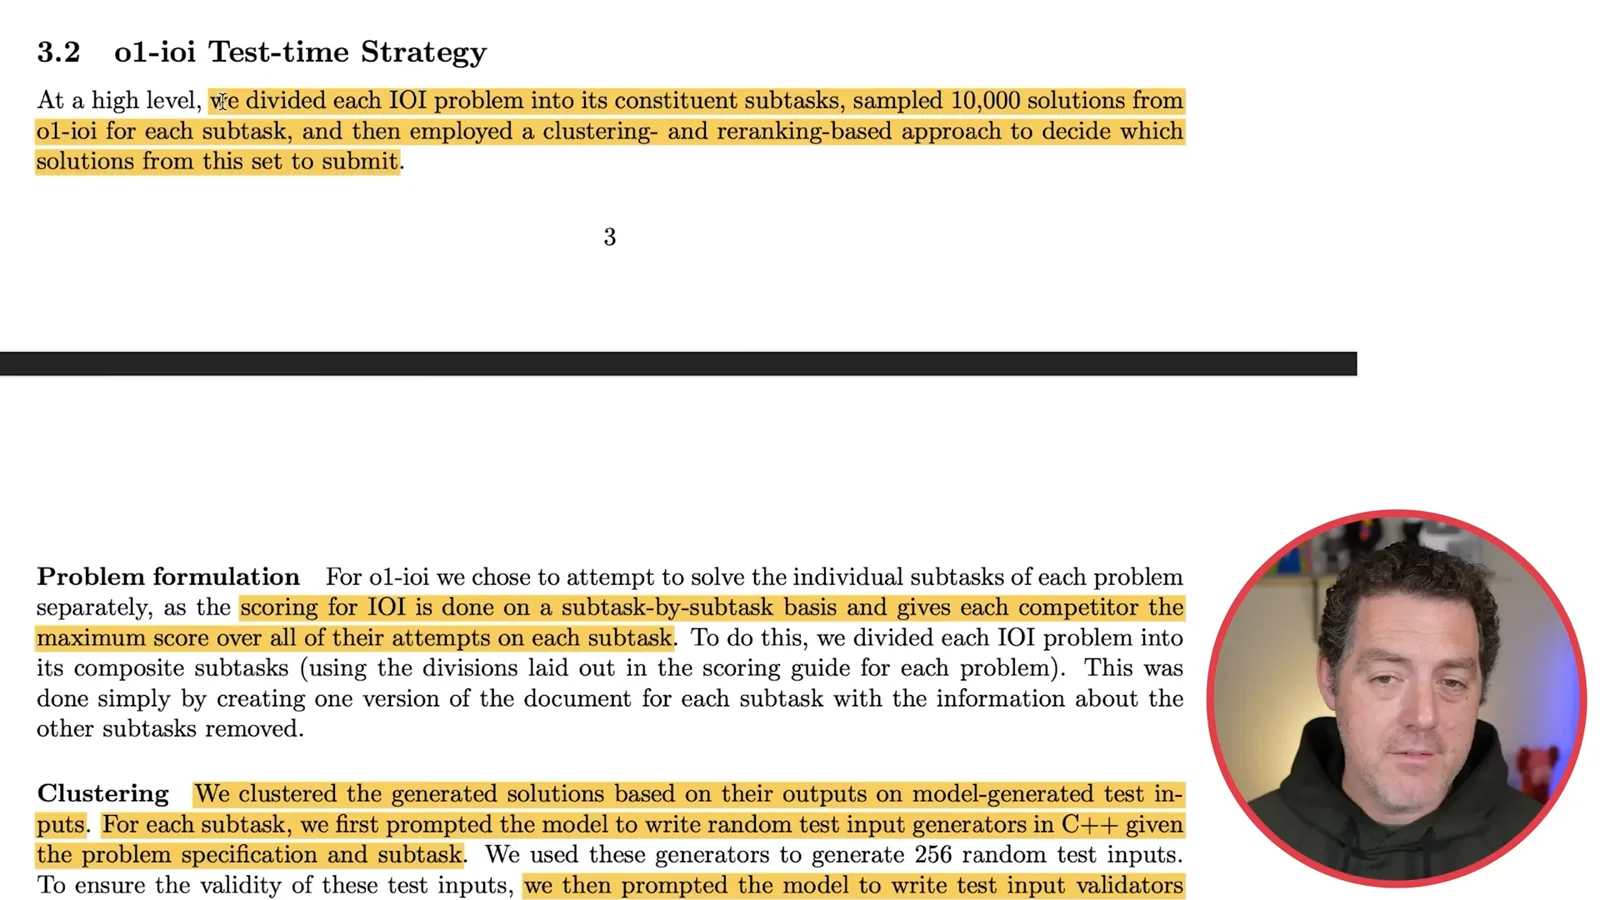
For o1-ioi, the team divided problems into subtasks and sampled 10,000 candidate solutions per subtask. It clustered candidates according to outputs on generated tests and reranked them using a learned scoring function, errors and public test cases. The pipeline then selected submissions, subject to the contest limit.
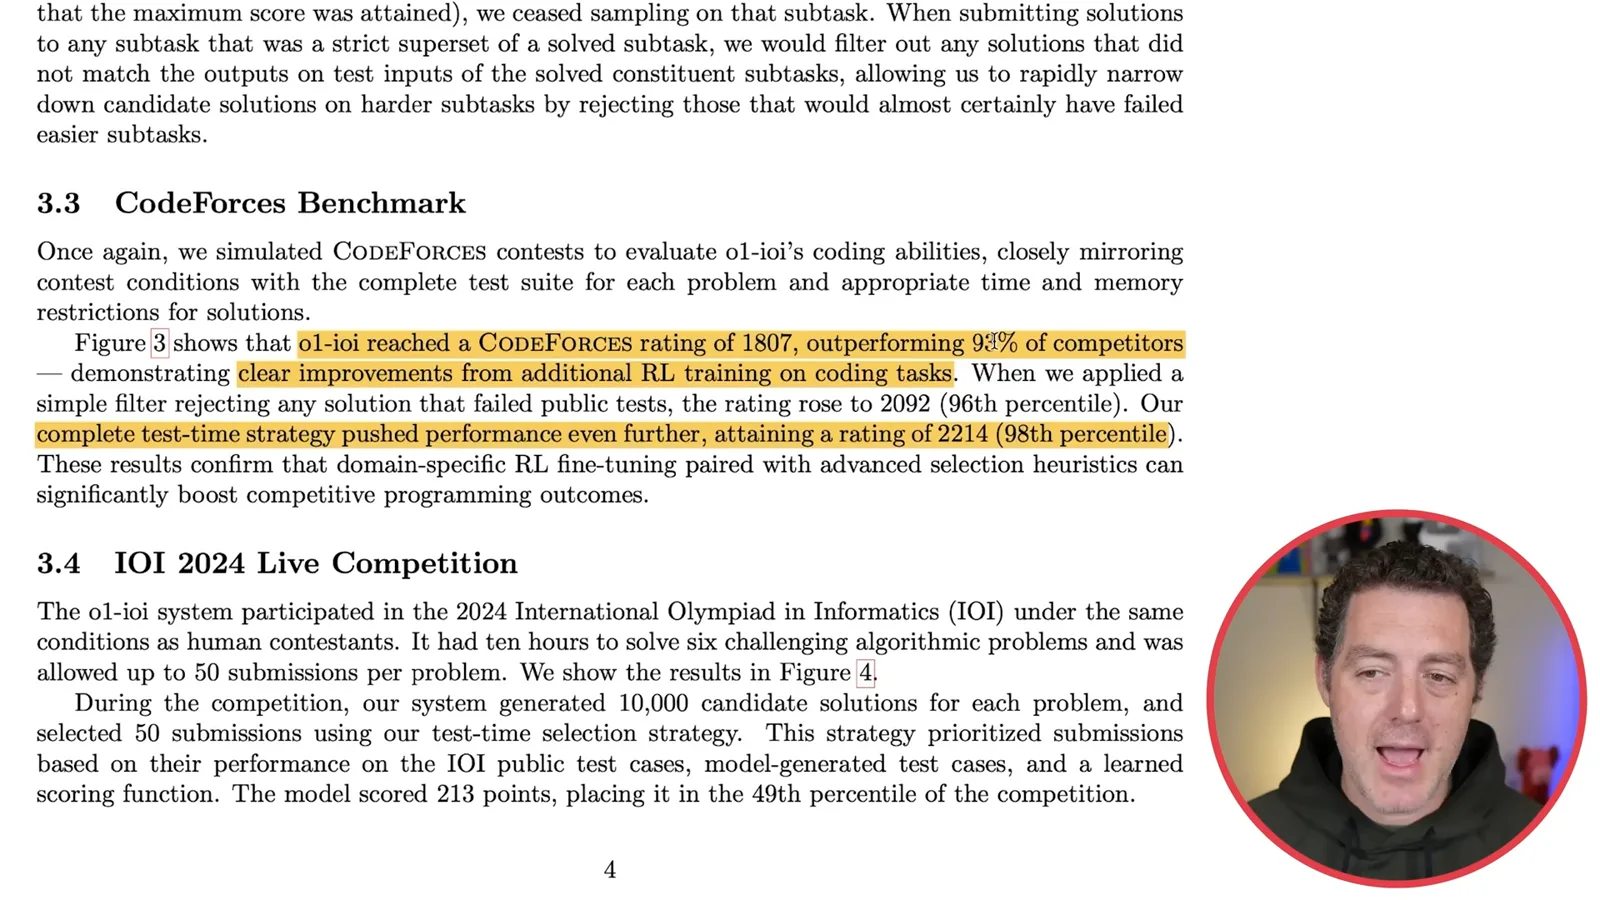
On simulated Codeforces tests, the paper reports an estimated 1,807 rating for o1-ioi, 2,092 with public-test filtering and 2,214 with the full strategy, corresponding to the 98th percentile in its comparison. These are separate configurations; the selection method matters to the result.
o3 and IOI results
Berman discusses o3’s simulated Codeforces performance and IOI scores. Live, relaxed and retrospective results must be distinguished.
For an early o3 checkpoint, the paper reports an estimated Codeforces rating of 2,724 and the 99.8th percentile relative to active competitors in its comparison. This is not a direct contest against every coder. The authors note that the strongest humans still solved more of the tested problems.
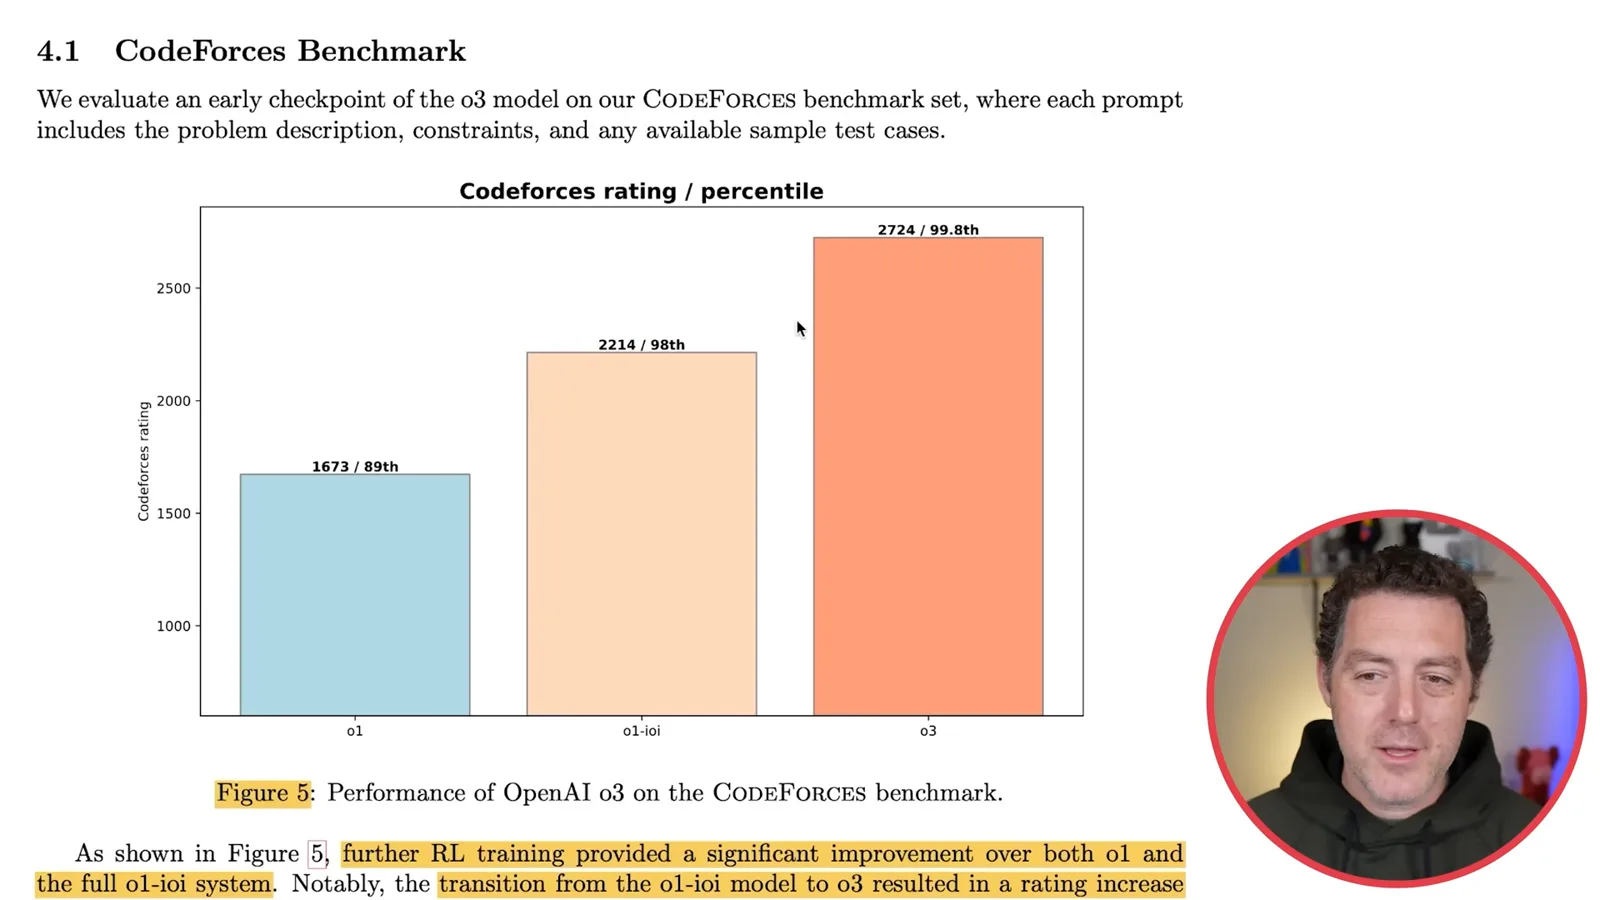
The o3 method was simpler than o1-ioi’s competition-specific clustering pipeline, but it was not devoid of human design: researchers chose prompts, sampling, ranking and evaluation. In the IOI test, they selected the 50 highest-compute candidates from 1,024 samples per problem. The IOI and Codeforces evaluations used different early o3 checkpoints.
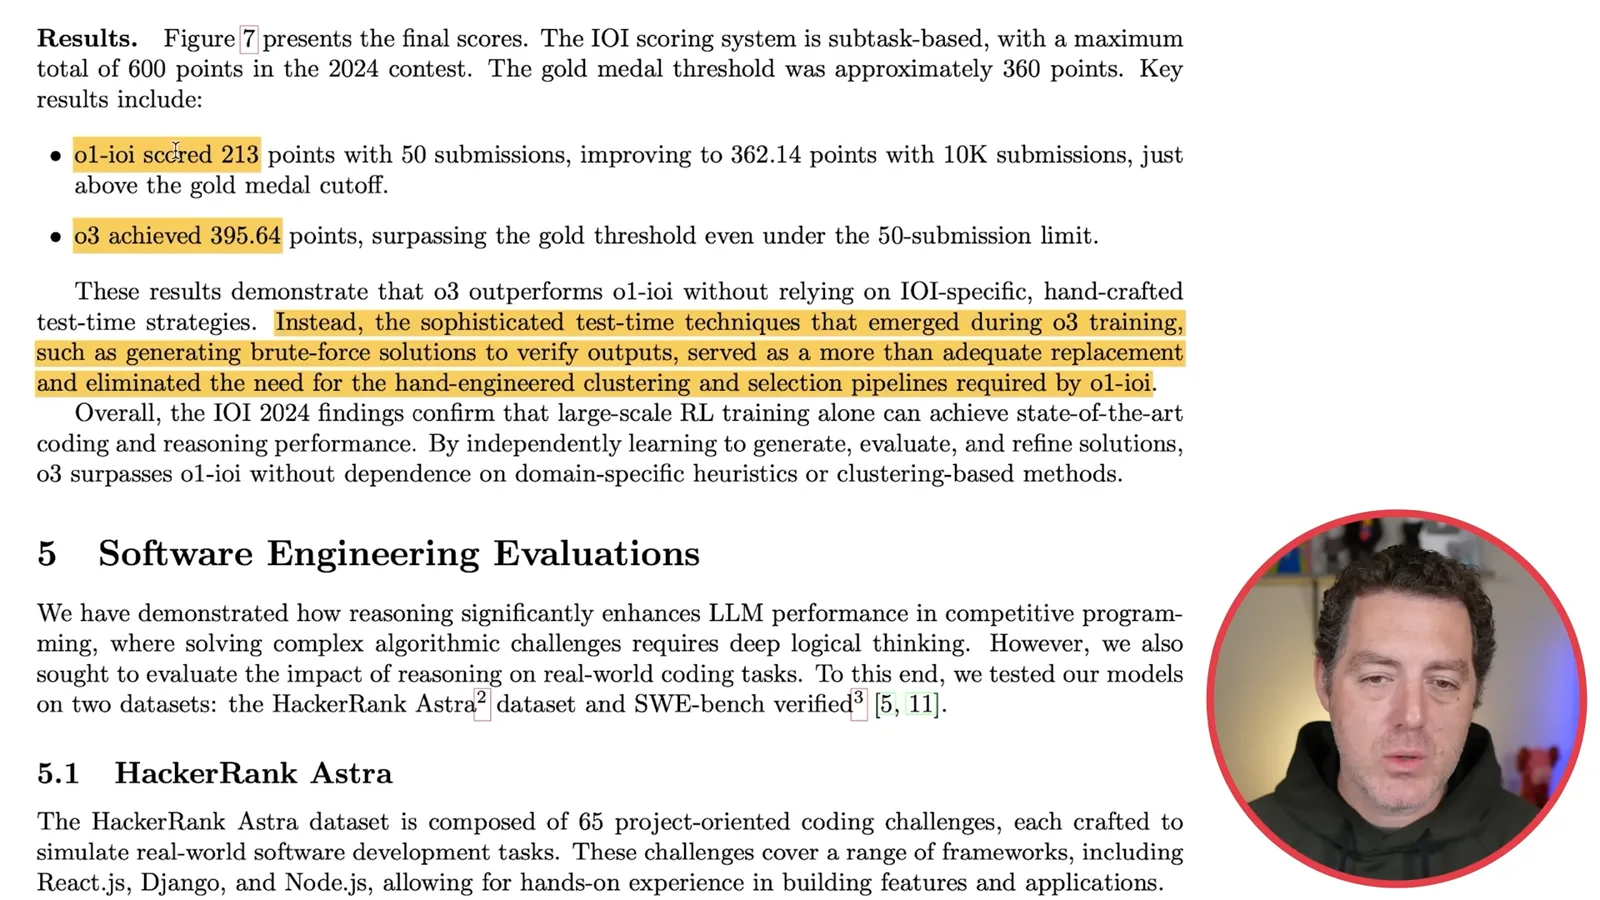
The paper reports that o1-ioi scored 213 points in the actual 2024 IOI under the limit of 50 submissions per problem, at the 49th percentile. Its 362.14 points exceeded the gold threshold only when the limit was relaxed to 10,000 submissions per problem. Berman’s implication that 213 was above the gold threshold is incorrect.
A later o3 checkpoint was evaluated retrospectively on the same six IOI problems and scored 395.64 points under the 50-submission-per-problem limit, above the approximately 360-point gold threshold. It was not a live medal awarded to o3. The paper states that the later checkpoint had additional training data and reports contamination checks.
I conclude that scaling reinforcement learning and test-time compute could lead to the strongest programmers and ultimately AGI or superintelligence. The competition results are meaningful but narrower: they do not establish that trajectory, prove best-in-world performance in every coding context, or eliminate the human work involved in developing and evaluating the systems.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· Oct 25, 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· Oct 24, 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.