In 30 seconds
Matthew Berman reviews Alexia Jolicoeur-Martineau’s 2025 Tiny Recursive Model paper, comparing its iterative network with the earlier HRM approach. The specialized puzzle scores are promising but depend on supervised training, heavy augmentation and test-time voting; they do not establish general superiority to language models or a path to AGI. The video includes a Mocha sponsorship.
- 1ARC resultsThe paper reports 44.6% and 7.8% for the seven-million-parameter attention model on the public ARC evaluation sets.
- 2Deep supervisionA cited ablation shows a gain from multiple supervision steps under the tested setup.
- 3Recursive updatesTRM uses a small network to repeatedly refine a latent state and predicted answer.
- 4Comparison limitationsSpecialized supervised models and pretrained language models are evaluated using different methods.
- 5Compute and augmentationARC experiments use extensive augmentation and voting, and the paper reports training on four H100 GPUs.
Takeaways
- The seven-million-parameter attention variant reports 44.6% on ARC-AGI-1 and 7.8% on ARC-AGI-2 public evaluation sets.
- A separate five-million-parameter variant produced the reported 87.4% Sudoku-Extreme result.
- The ARC setup uses heavy data augmentation and votes over 1,000 augmented versions at test time.
- The paper reports substantial GPU resources despite the small model size.
- Comparisons with general language models use different training and evaluation approaches and do not establish general superiority.
Read the edited text by chapter
Small models and puzzle scores
Berman introduces TRM and its reported ARC results. Comparisons use different model and evaluation setups.
A paper called 'Less is More: Recursive Reasoning with Tiny Networks' reports that a seven-million-parameter Tiny Recursive Model, or TRM, performs strongly on several puzzle benchmarks. Its ARC scores exceed some language-model results listed in the paper, but the systems use different training and evaluation setups. The result does not establish that this specialized model is generally more capable than frontier language models.
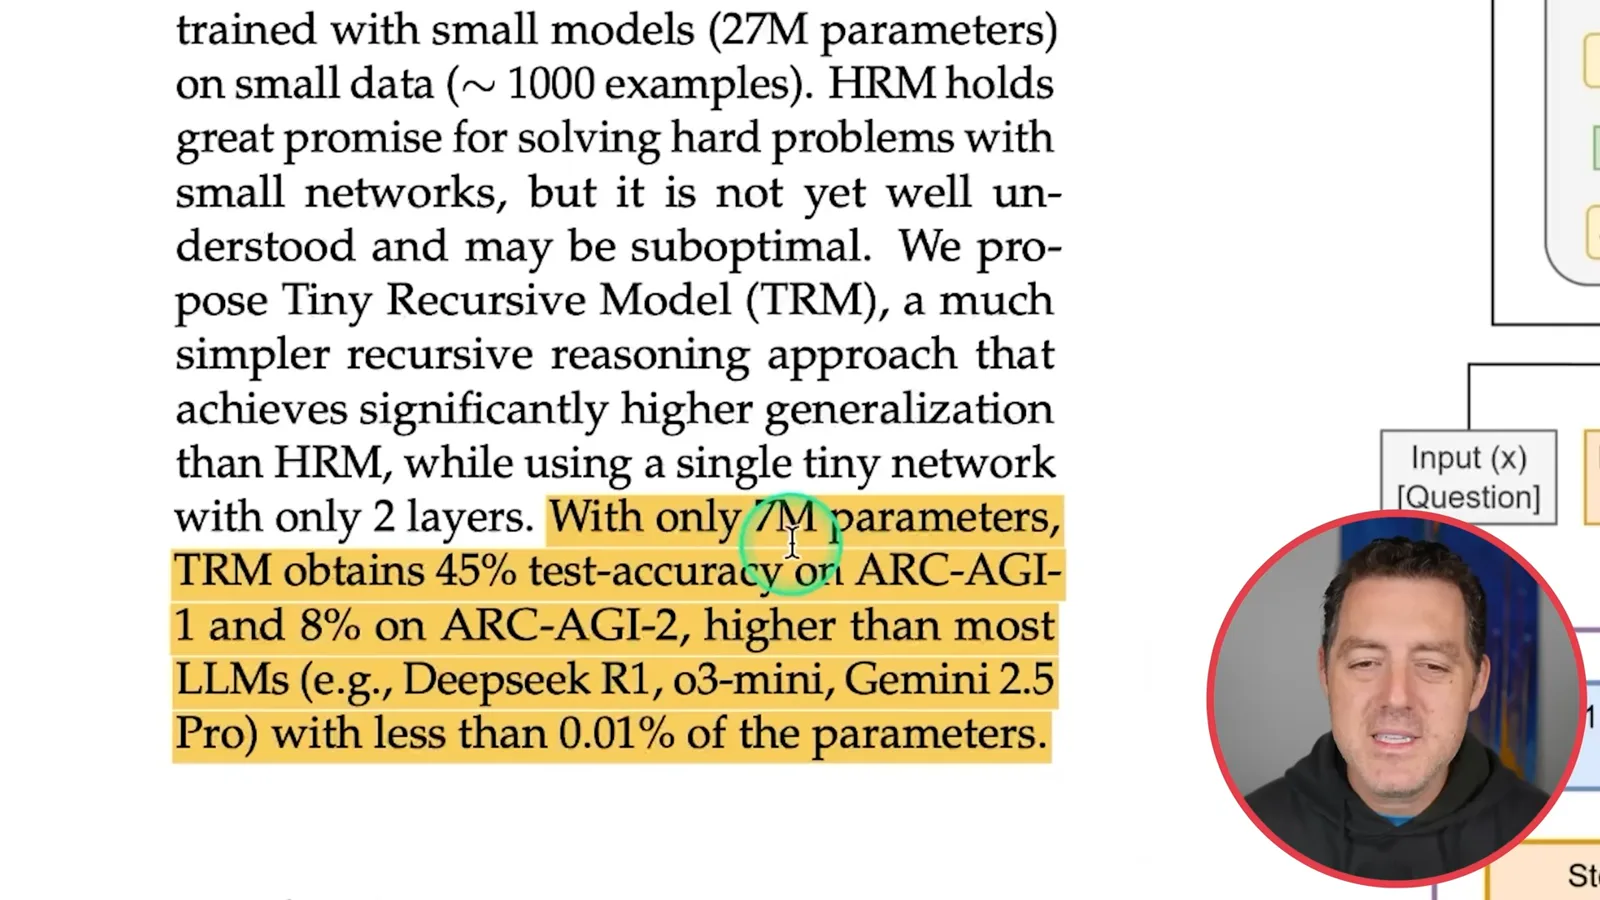
The paper by Alexia Jolicoeur-Martineau reports 44.6% on the ARC-AGI-1 public evaluation set and 7.8% on ARC-AGI-2 for its seven-million-parameter attention-based model, with two attempts. Those numbers round to 45% and 8%. The paper's comparisons are from its 2025 table, not a current universal ranking.
Language models generate answers autoregressively, and an incorrect step or token can undermine a solution. Chain-of-thought and additional test-time computation can help, but reasoning traces can be wrong and additional samples cost compute. My statement that next-token models therefore do not reason is an interpretation, not something established by this paper.
Sampling several answers and selecting one can improve results if a reliable selection method is available. Generating multiple answers does not automatically identify the best one. The paper explores a different way to refine a predicted answer through repeated computation in a small supervised network.
HRM and deep supervision
The prior model combines recursion and supervision. The video discusses an ablation and includes a Mocha sponsorship.
The paper builds on the Hierarchical Reasoning Model, or HRM, which uses two networks running at different frequencies and deep supervision. It was evaluated on tasks such as Sudoku, mazes and ARC puzzles. Its authors drew biological analogies, but the TRM paper questions how much those analogies explain the architecture's results.
The video includes a sponsored segment for Mocha, an AI app-building service. Its claims about building and monetizing an application are presented as sponsor claims, not a comprehensive independent test.
Deep supervision carries intermediate state through multiple supervised improvement steps. An earlier analysis cited in the paper found an increase from 19% to 39% under one comparison, while a hierarchical recursion comparison increased accuracy from 35.7% to 39%. These are specific ablations, not proof that recursion is generally useless.
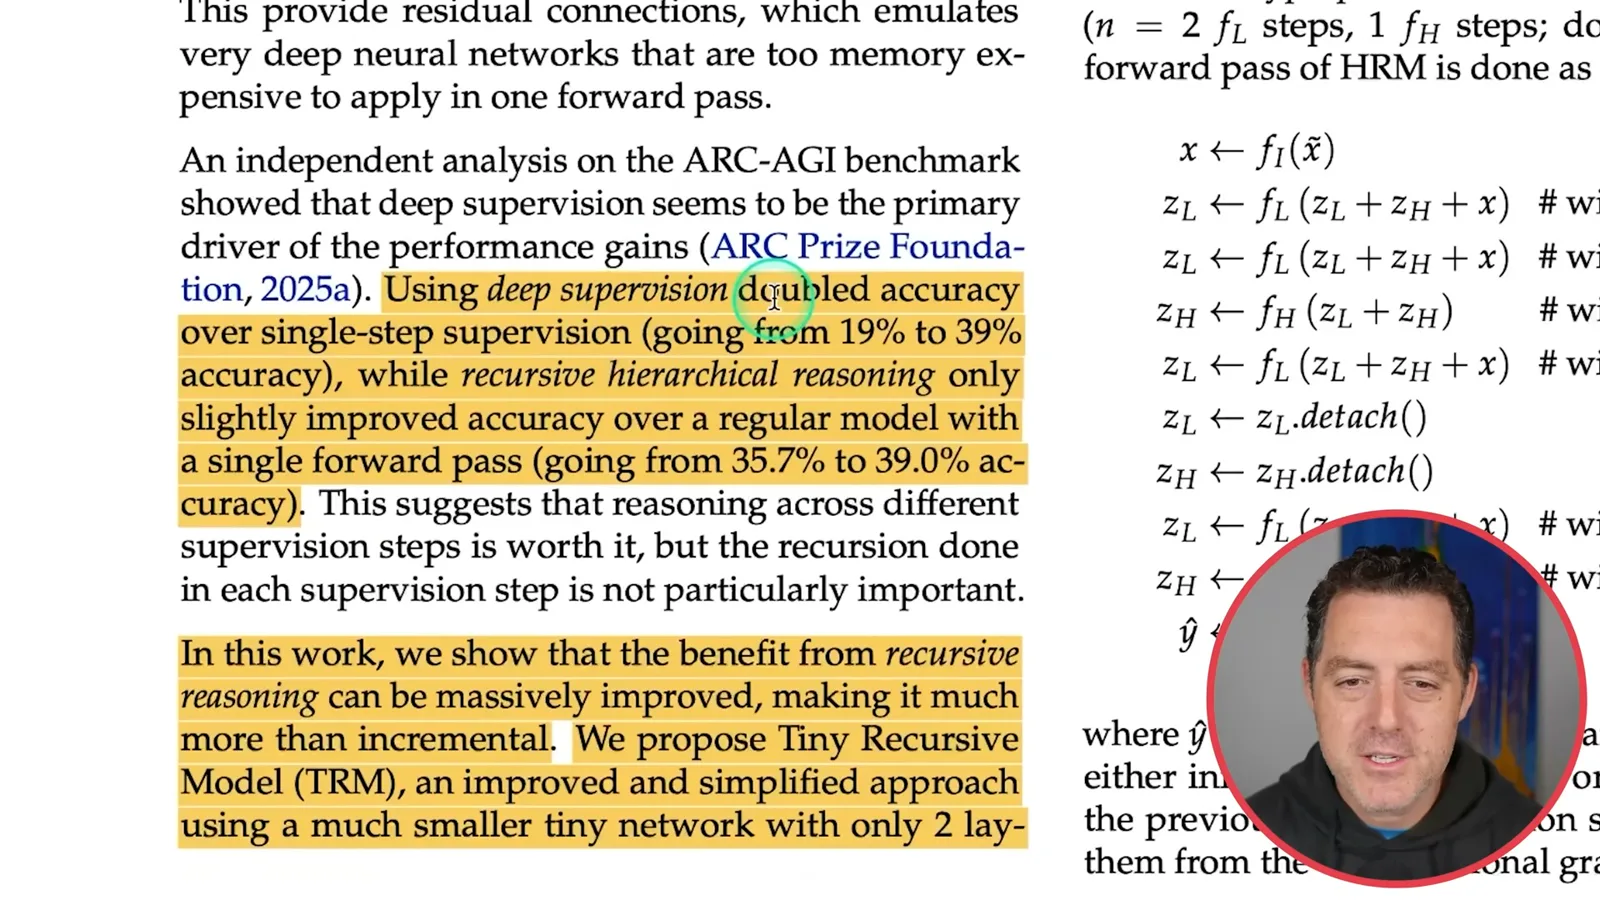
A smaller recursive network
The paper replaces the hierarchical pair of networks with a small recurrent network. Its variants and results differ across puzzle tasks.
The author proposes a smaller two-layer network that repeatedly updates a latent state and a candidate answer. The paper reports improvements over its HRM baselines on Sudoku-Extreme, Maze-Hard and both ARC benchmarks. Different tasks use different variants, so the headline results should not all be attributed to exactly the same seven-million-parameter model.
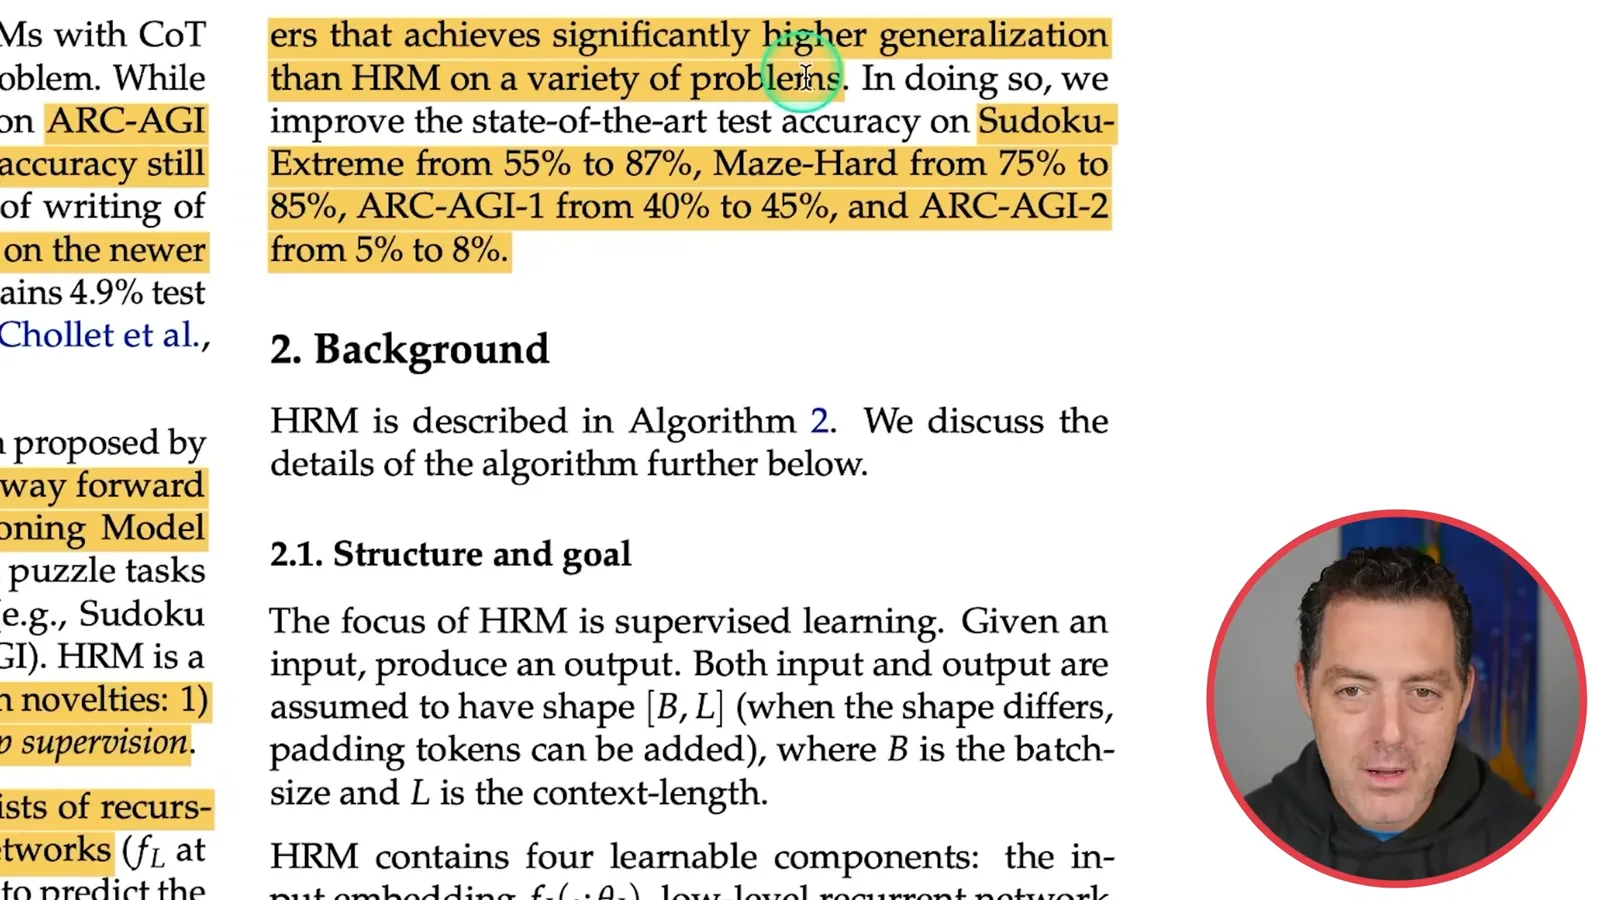
For example, the paper reports 87.4% on Sudoku-Extreme with a five-million-parameter MLP variant, versus 55.0% for the listed HRM baseline. Its seven-million-parameter attention variant reaches 85.3% on Maze-Hard and the two ARC figures. These are puzzle benchmarks, not a demonstration of broad language or real-world ability.
The paper challenges HRM's biological and fixed-point justifications and argues for a simpler interpretation. It treats one latent variable as an evolving answer and the other as a latent reasoning state. Describing these as two 'brains' or explicit written notes is an analogy; the system does not necessarily produce a human-readable reasoning trace.
The network repeatedly updates the latent state using the input and current answer, then updates the answer. That resembles trying a Sudoku move and revising it, but the operations are learned numerical transformations, not necessarily conscious reflection. Recursion creates additional effective depth without introducing a separate network for each step.
Results and limitations
The paper compares recursion depth and benchmark scores. Heavy augmentation, voting and computational requirements qualify claims about general ability and device deployment.
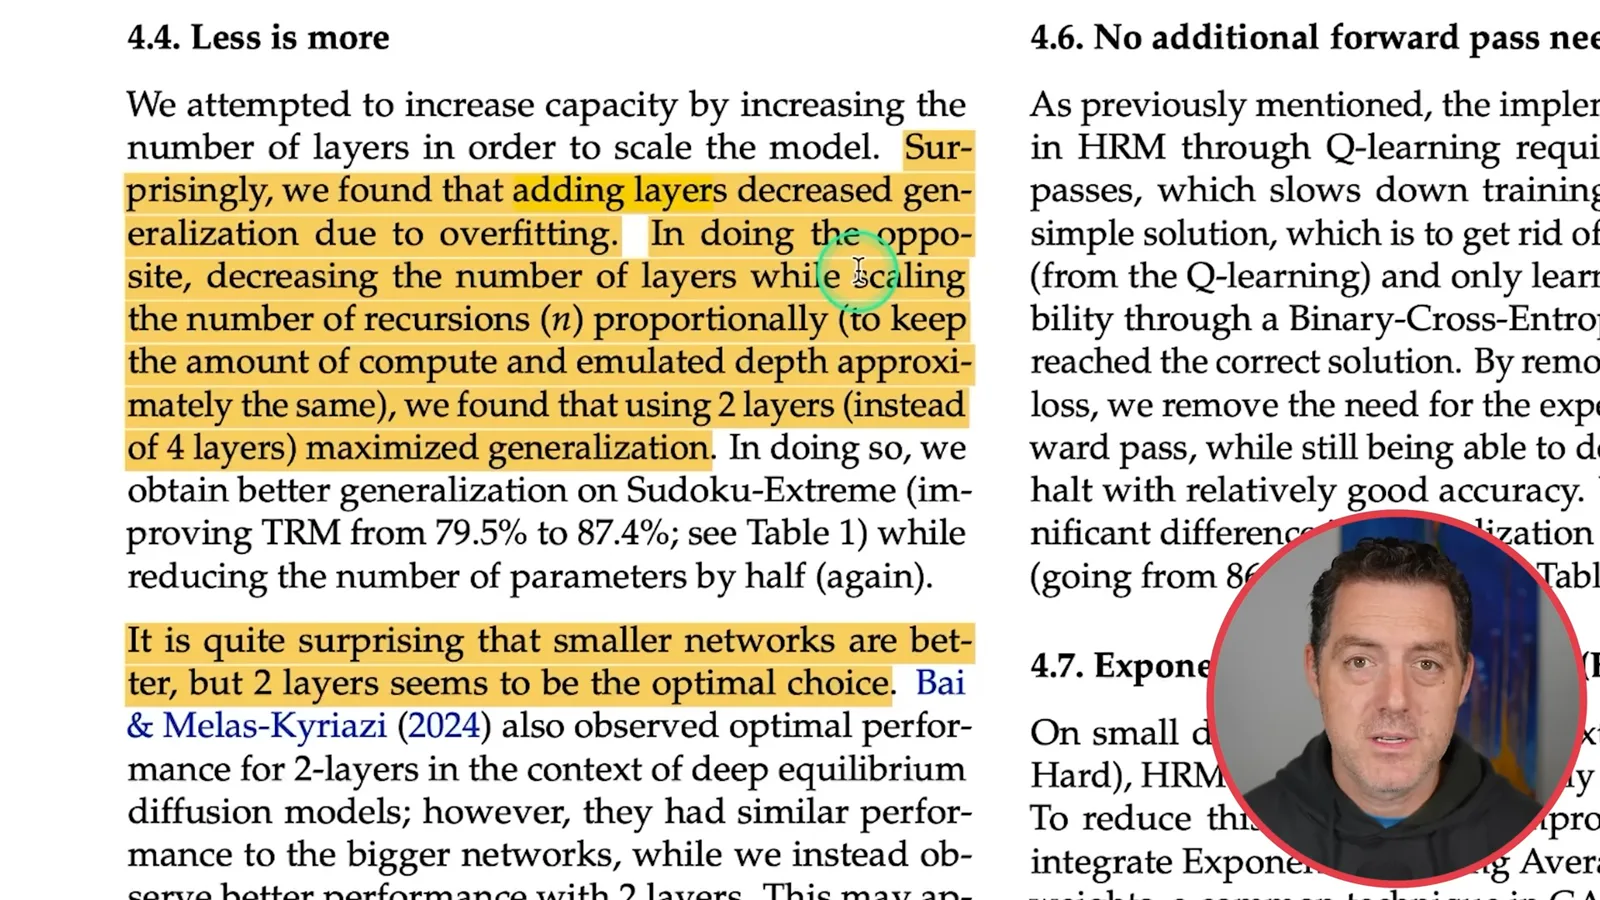
In the experiments, reducing the network from four to two layers while increasing recursion improved generalization under the tested setup. The author suspects overfitting may explain some of the benefit but says the mechanism is not fully understood. Two layers are not established as optimal for all tasks or datasets.
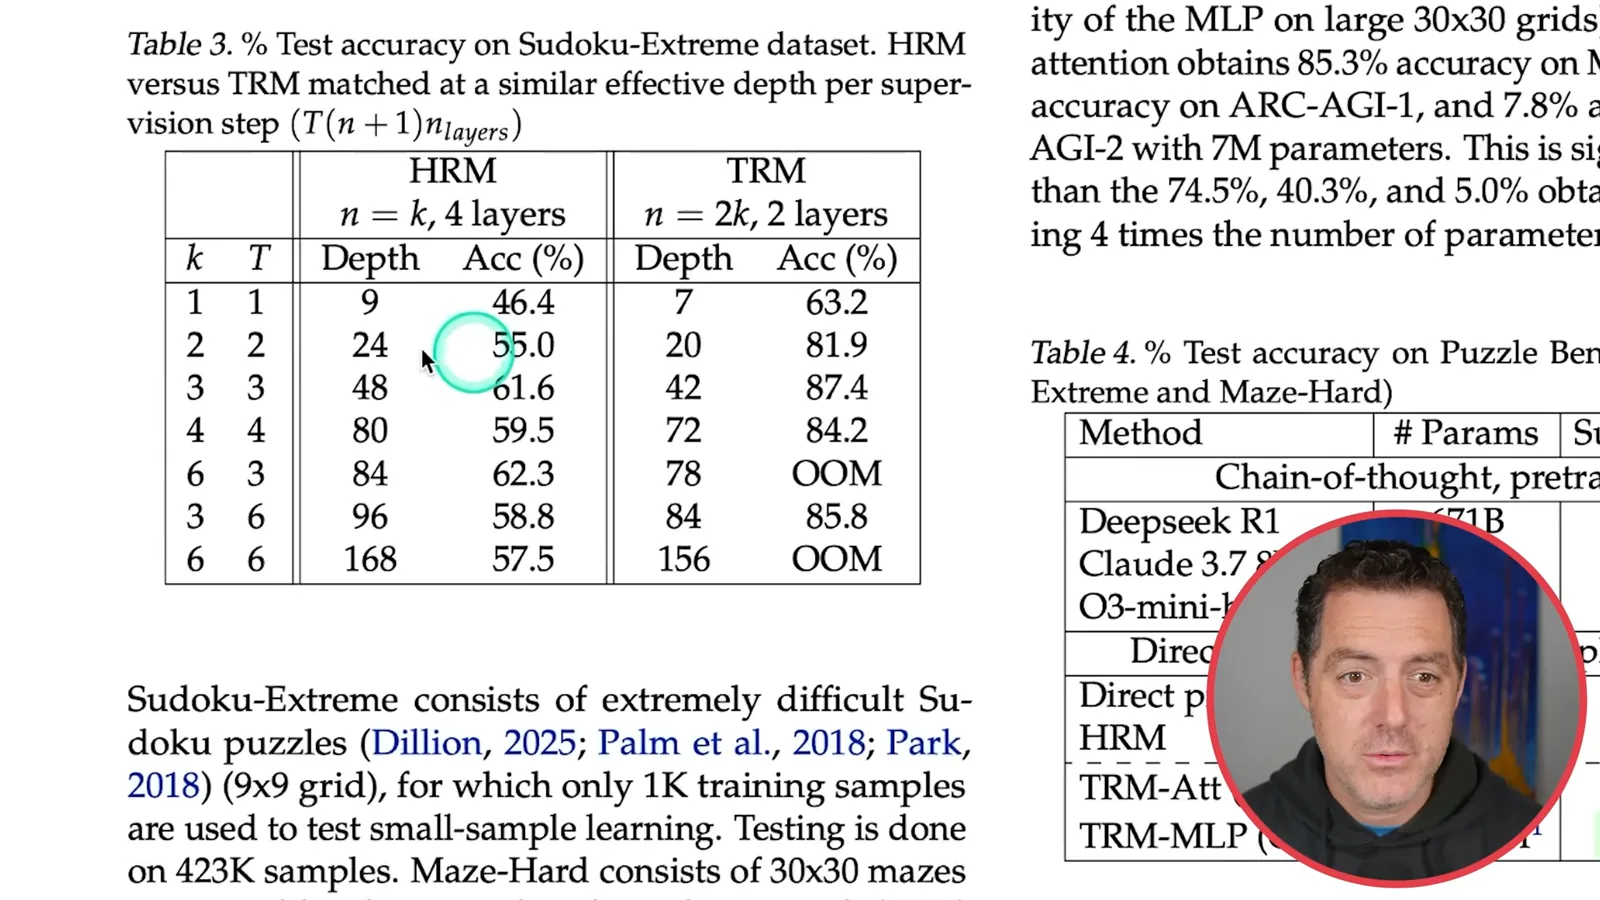
The paper compares recursion configurations at similar effective depths on Sudoku. Some deeper configurations run out of GPU memory, and performance is not monotonically better with more recursion. Small parameter count does not imply negligible training or inference cost.
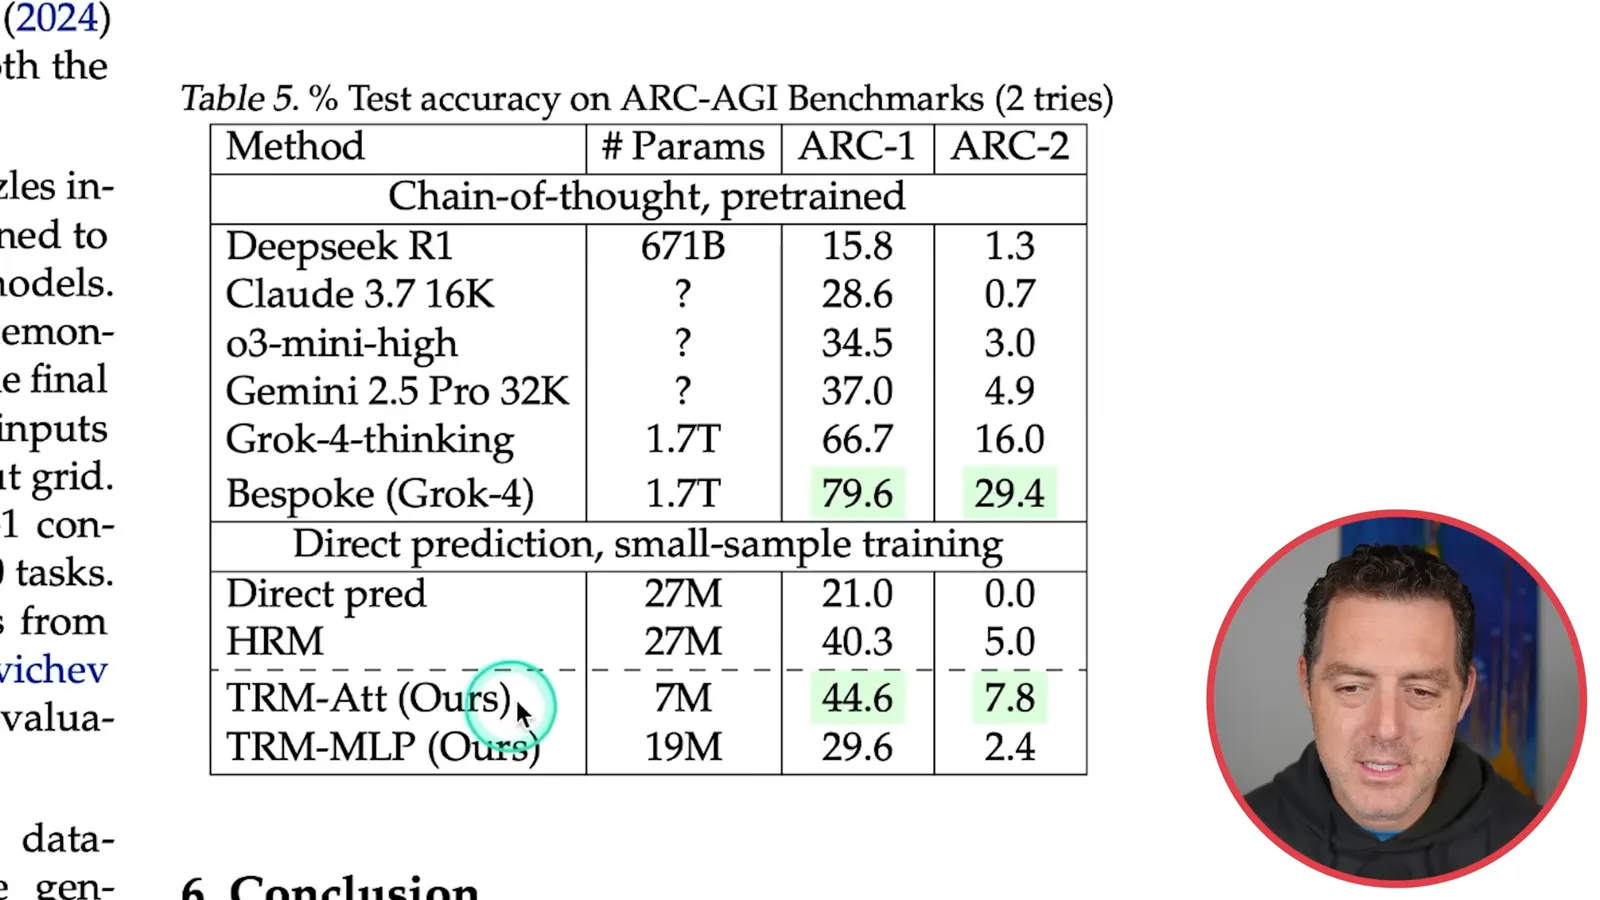
On the paper's ARC table, the attention-based TRM scores 44.6% and 7.8%, above several listed language models and below the listed Grok-4 configurations. The comparison mixes specialized small-sample supervised training with pretrained language-model approaches, so it is not an apples-to-apples measure of general reasoning or all model capabilities.
The experimental details matter: the paper uses heavy augmentation, adds ConceptARC examples to ARC training, and selects the most common output across 1,000 augmented versions at test time. It reports around three days on four H100 GPUs for ARC experiments. These conditions limit any conclusion that the complete benchmark procedure can run cheaply on a phone.
I describe the method as generating a guess and iteratively revising it, and speculate that recursion might point toward AGI or a new scaling law. That is a possibility to investigate, not a result established by the paper. The author notes that these supervised models produce a deterministic answer and that extending them to generative tasks remains future work.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.