In 30 seconds
In this October 2025 roundup, Matthew Berman discusses a GPT-6 rumor, NVIDIA hardware, Claude Skills, military decision-making, video tools and AI-assisted biology. He also considers speculative space infrastructure and a proposed, definition-dependent AGI metric. The video includes a Stack AI sponsorship.
- 1Claude SkillsReusable folders package instructions and resources that can be loaded when relevant.
- 2Human judgment in military decisionsBerman distinguishes exploring options from relying on unverified model outputs for command decisions.
- 3A reported sign-in proposalA reported OpenAI pitch suggests shifting some inference costs to user subscriptions, while creating potential platform dependence.
- 4An early biological resultResearchers report testing a generated hypothesis in human cell models; clinical applications remain unproven.
- 5Defining AGIA research proposal assigns scores across cognitive abilities, based on its own definition and measurement choices.
Takeaways
- The 2025 GPT-6 release suggestion was a rumor, and Berman expressed skepticism.
- Claude Skills package instructions and resources for selective loading; Berman had not yet tested them.
- Berman argues that humans must verify AI outputs and retain responsibility for consequential military decisions.
- A cancer-cell hypothesis was tested in cell models, not established as a treatment.
- AGI percentages reflect a particular research framework, not a universally agreed measure.
Read the edited text by chapter
A release rumor and NVIDIA hardware
Berman questions a reported GPT-6 timeline and reviews NVIDIA’s DGX Spark presentation. The performance comparison is a vendor claim with unspecified conditions.
A CNBC commentator relayed a suggestion that GPT-6 might arrive by the end of 2025. I was skeptical: GPT-5 had only recently launched, bringing a unified model and routing experience to ChatGPT, so replacing it after just a few months would be surprising. This was a rumor, not an announced release date.
NVIDIA had begun selling DGX Spark, a small desktop AI computer. In a clip, Jensen Huang delivers one to Elon Musk and recalls the original DGX-1 delivery in 2016. Huang claims the new machine has five times the computational power of DGX-1; the clip does not specify comparable precision or workloads, so that figure should not be read as a universal speedup.
I was eager to get a DGX Spark myself and said I was on a waiting list. NVIDIA also showed a delivery to the OpenAI team, including Greg Brockman and Sam Altman.
Claude Skills and military decisions
He explains reusable Skills and considers a viral claim about military use of ChatGPT. He argues that humans must verify information and make consequential decisions.
Anthropic introduced Claude Skills for Claude.ai, Claude Code and its API. The idea is to package specialized knowledge in a reusable capability that Claude can load when relevant. Some people suggested it could replace MCP, but the illustration I saw suggests it can also complement MCP; I had not tested Skills myself yet.
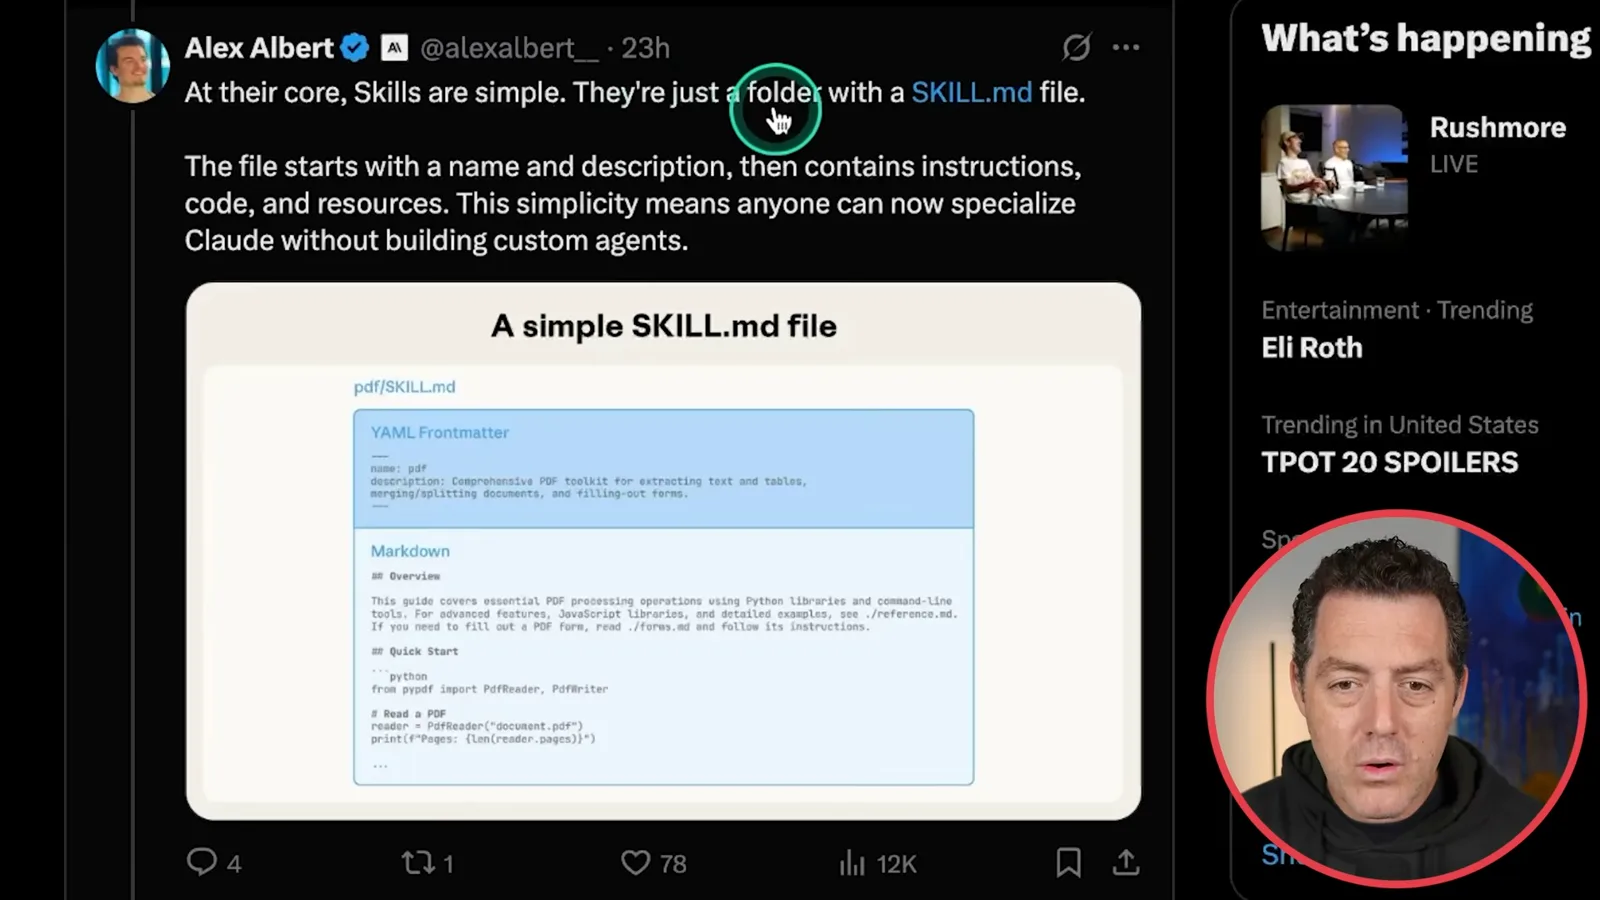
A skill is a folder containing a SKILL.md file with a name, description and instructions, along with optional code and resources. The idea is to load relevant material on demand rather than placing everything in every context window. That does not mean the model has unlimited active context.
For example, a company could bundle brand guidelines and assets into a skill. When someone asks Claude for a creative pitch deck, it can find the applicable skill and load the resources it needs. I thought the approach looked promising, although I had not yet tried it.
The video includes a sponsored segment for Stack AI, which describes its platform as a way for enterprises to build AI agents with integrations and security features. Those product and compliance claims are the sponsor's, not independently verified by this video.
A viral post said a US Army general had used ChatGPT in command decisions. The post alone does not establish exactly how it was used. If a general simply asks an AI whom to attack, I think that is a problem; using it to explore options, gather information and consider possible outcomes is a different proposition.
The Grok response shown in the video also warns about hallucinations, bias and security leaks when general-purpose AI is used for critical military decisions. My view is that people should verify the output and retain responsibility for the final decision. These cautions are not proof that any particular military use was safe.
Platform risk, robotaxis and video models
A reported ChatGPT sign-in pitch raises questions about costs and dependence on a platform. Berman also discusses Waymo congestion and then-current Veo and Sora updates.
According to reporting by The Information, OpenAI had pitched companies on a 'Sign in with ChatGPT' button, including the possibility that users' own subscriptions could cover some model costs. I thought this could be attractive to developers and might give subscribers access to a better model. The proposal was a report about a pitch, not an established product or a guarantee of those terms.
A developer relying on another company's login also takes on platform risk. If rules change or access is disabled, users may suddenly have trouble signing in. That trade-off matters even if the arrangement makes strategic sense for OpenAI.
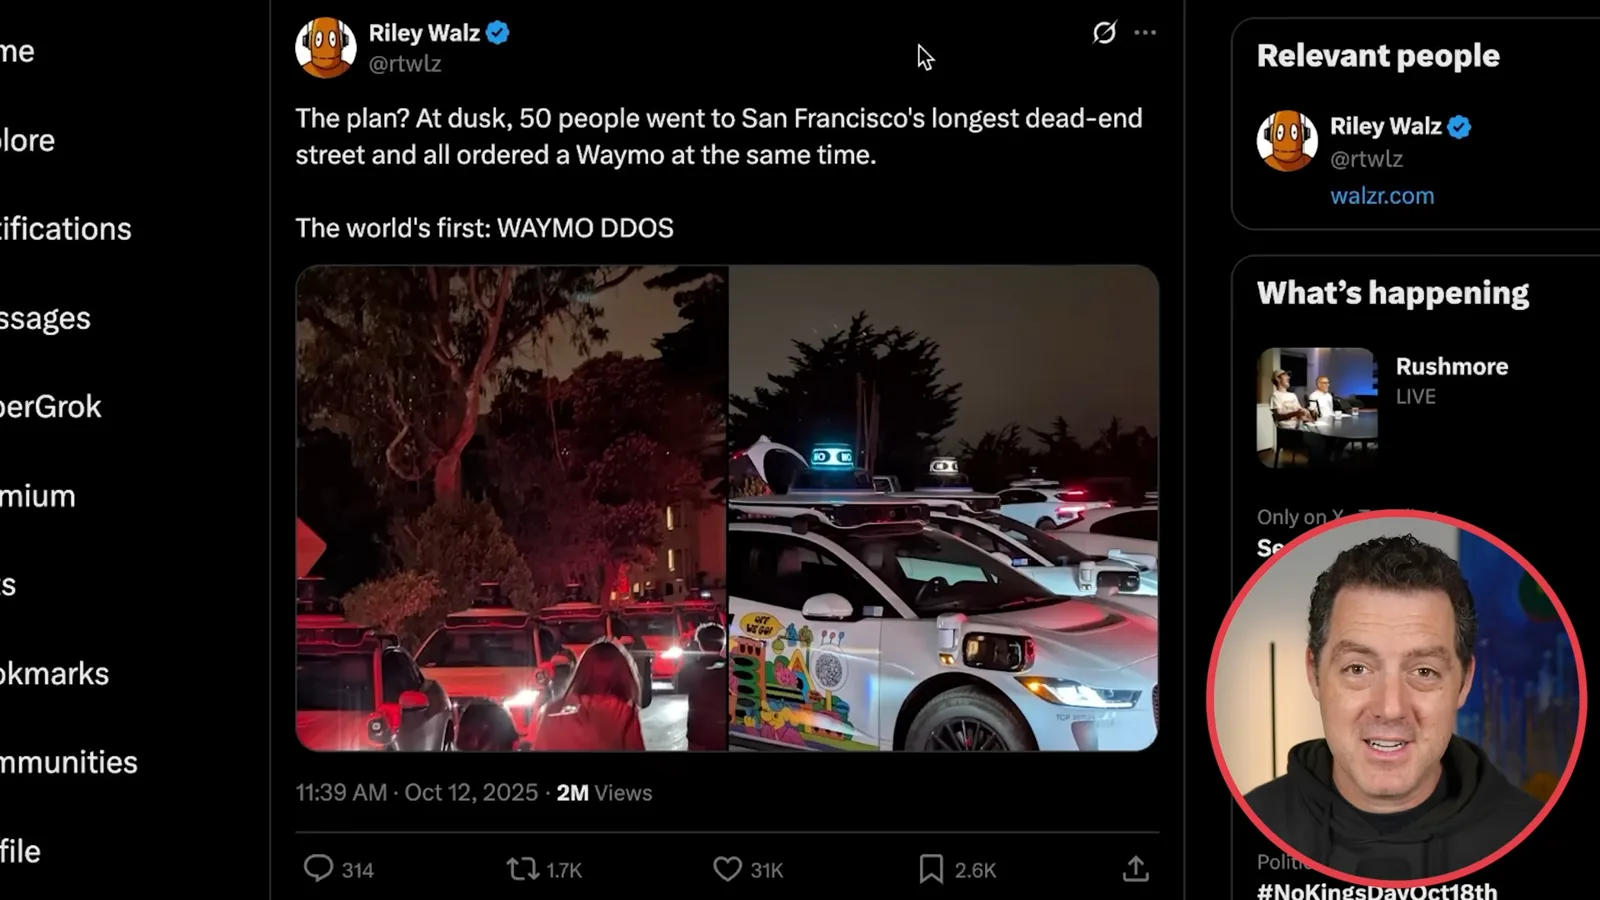
A social-media post described 50 people ordering Waymos to a San Francisco dead-end street at the same time, creating a traffic jam. Its author called it a Waymo 'DDoS' as a joke. In my own experience, a Waymo on a dead end sometimes needed time to work out how to turn around; the images show congestion, not a technical cyberattack.
Google announced Veo 3.1 updates to Flow, including sound with existing capabilities, multiple image references, start and end frames, and tools to insert or remove scene elements. Extending clips from the previous ending can create longer sequences. I had tested it only lightly, and people reported mixed impressions compared with Veo 3.
OpenAI also updated Sora: at the time, storyboards were available on the web for Pro users, with up to 15-second generations for all users and up to 25 seconds for Pro users. These are historical product details from October 2025, not a statement of present limits.
AI science and military displays
A cell-model experiment illustrates AI-assisted hypothesis generation, while an Anduril video shows augmented-reality concepts. Neither demonstration establishes a clinical treatment or operational performance.
Google CEO Sundar Pichai highlighted C2S-Scale 27B, a model built with Yale and based on Gemma. The researchers reported that a model-generated hypothesis about cancer-cell behavior was experimentally tested in human cell models. This is an early laboratory result, not a demonstrated cancer treatment; further preclinical and clinical work would be needed.
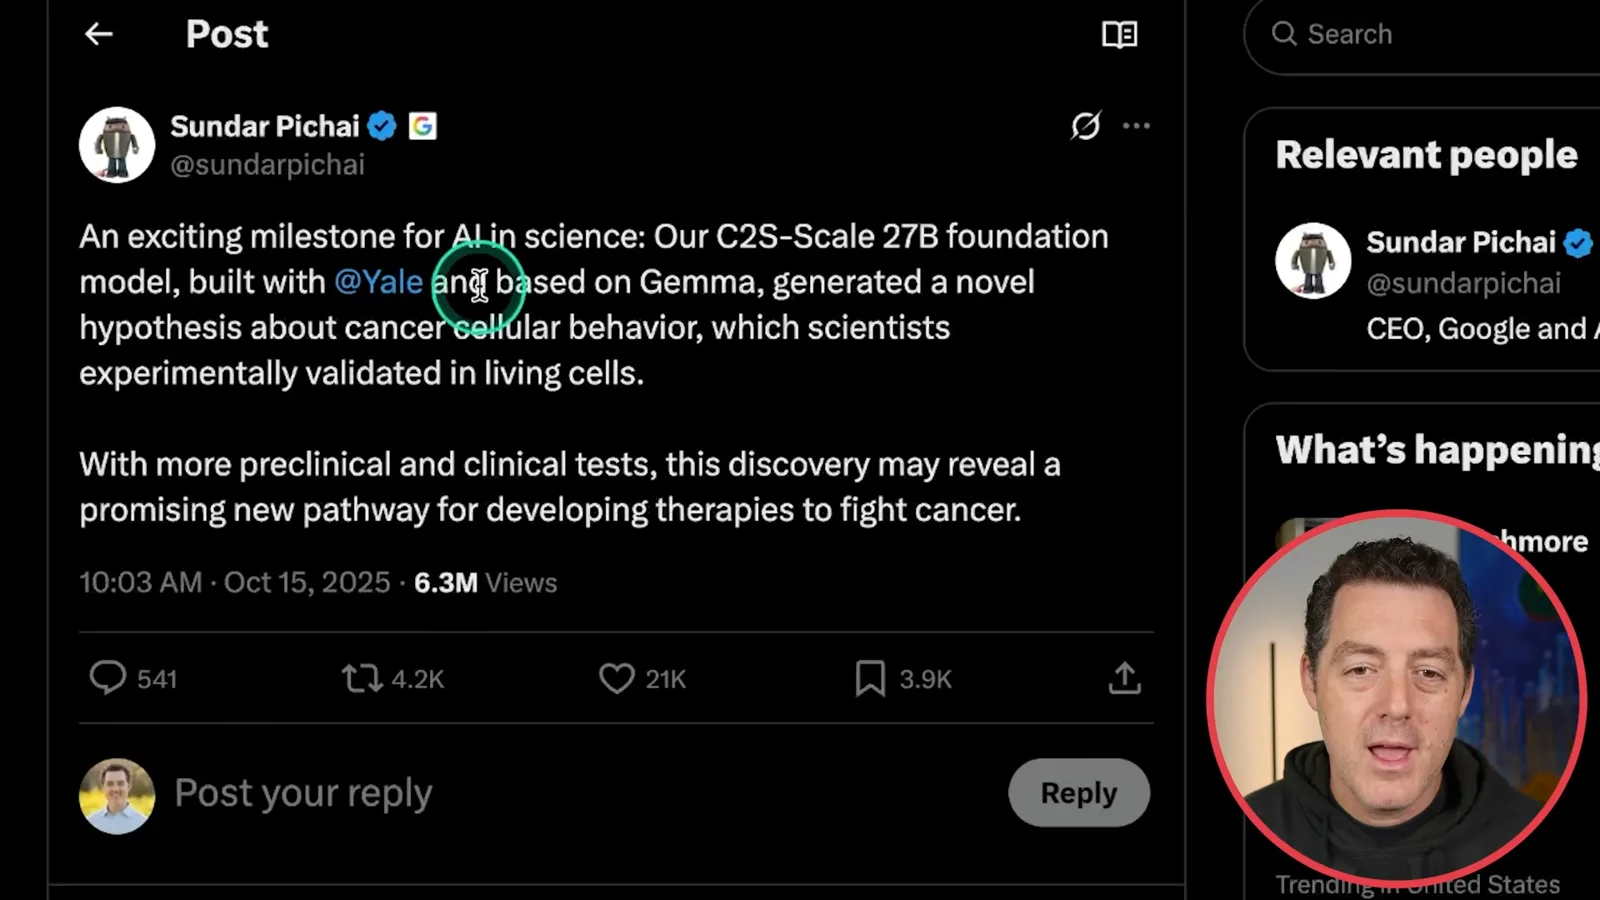
AI-assisted science is especially exciting to me, and I argued that more computing could help researchers make progress. That is an optimistic opinion, not evidence that compute alone can solve cancer or that scaling guarantees clinical success.
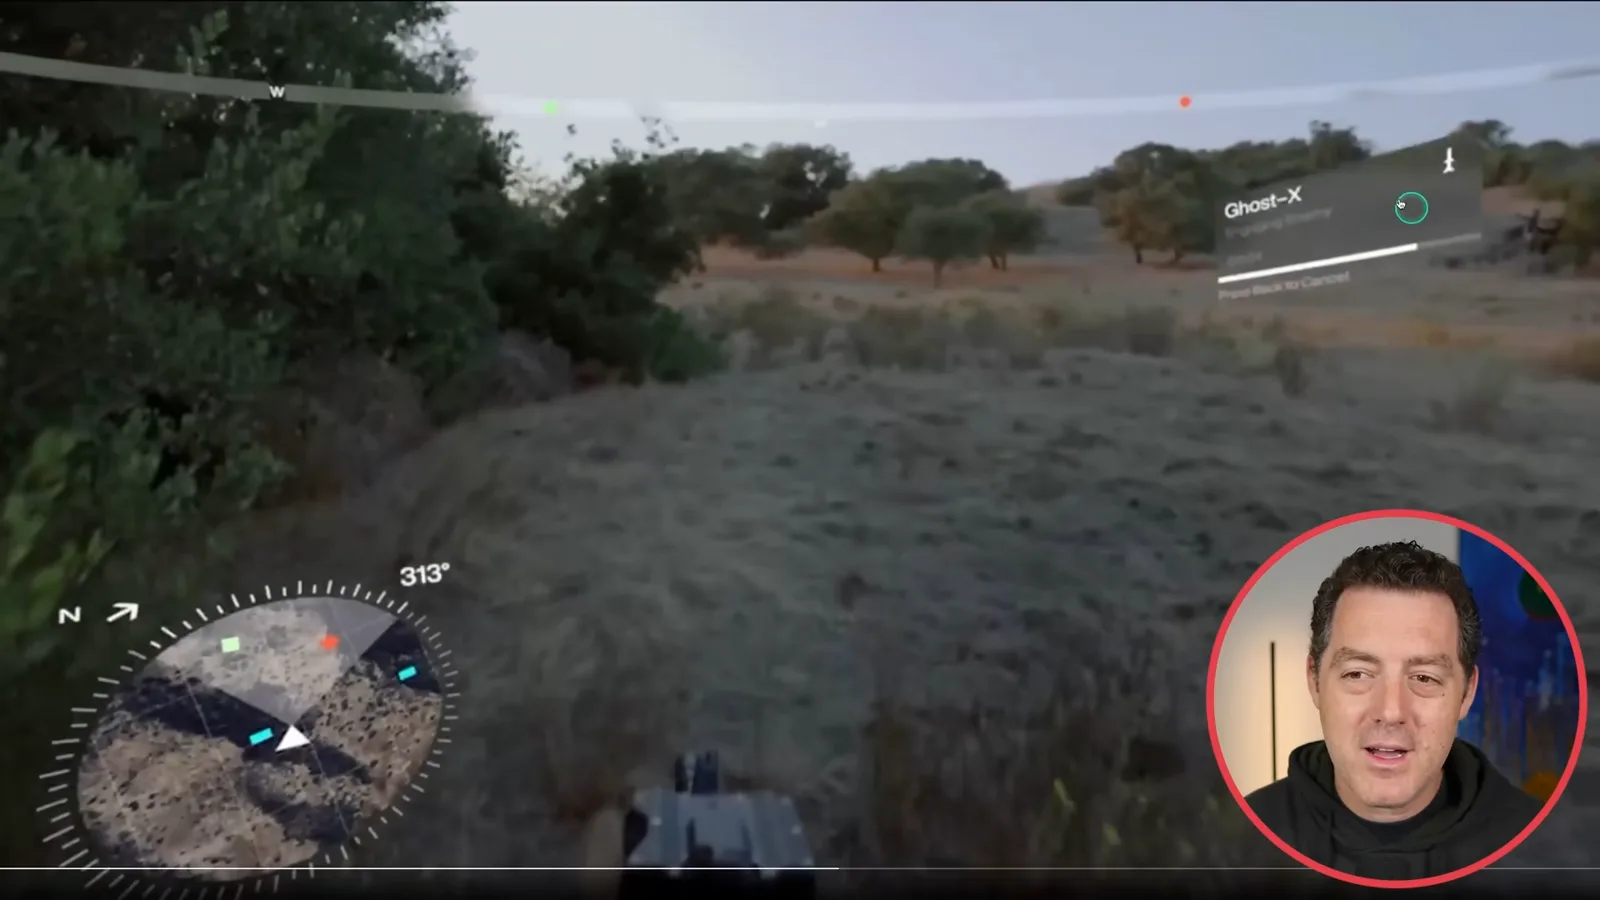
Anduril demonstrated EagleEye, an augmented-reality system for military use. The promotional footage showed a shared 3D view, mission rehearsal, location-aware video and overlays resembling a video game, including a map and tracked entities. I found the interface striking, but a promotional demonstration does not establish operational performance or deployment.
Space infrastructure and defining AGI
Bezos predicts future orbital data centers, and Berman shares a coding visualization. He closes with a proposed framework for measuring AGI, whose scores are definition-dependent.
Jeff Bezos predicted that large training data centers could eventually move to space, suggesting a horizon of roughly 10 to 20 years and arguing that solar power could make them economically competitive. I found the idea intriguing, but noted that launch and construction could be extremely expensive. His timetable and cost comparison are predictions; cooling in space also requires rejecting heat, not simply exposure to cold.
I also shared a visualization of Claude Code exploring a codebase, with a moving node representing navigation through files and directories. I enjoyed it as a way to picture the process; it is an illustrative visualization, not a measurement of how the model reasons.
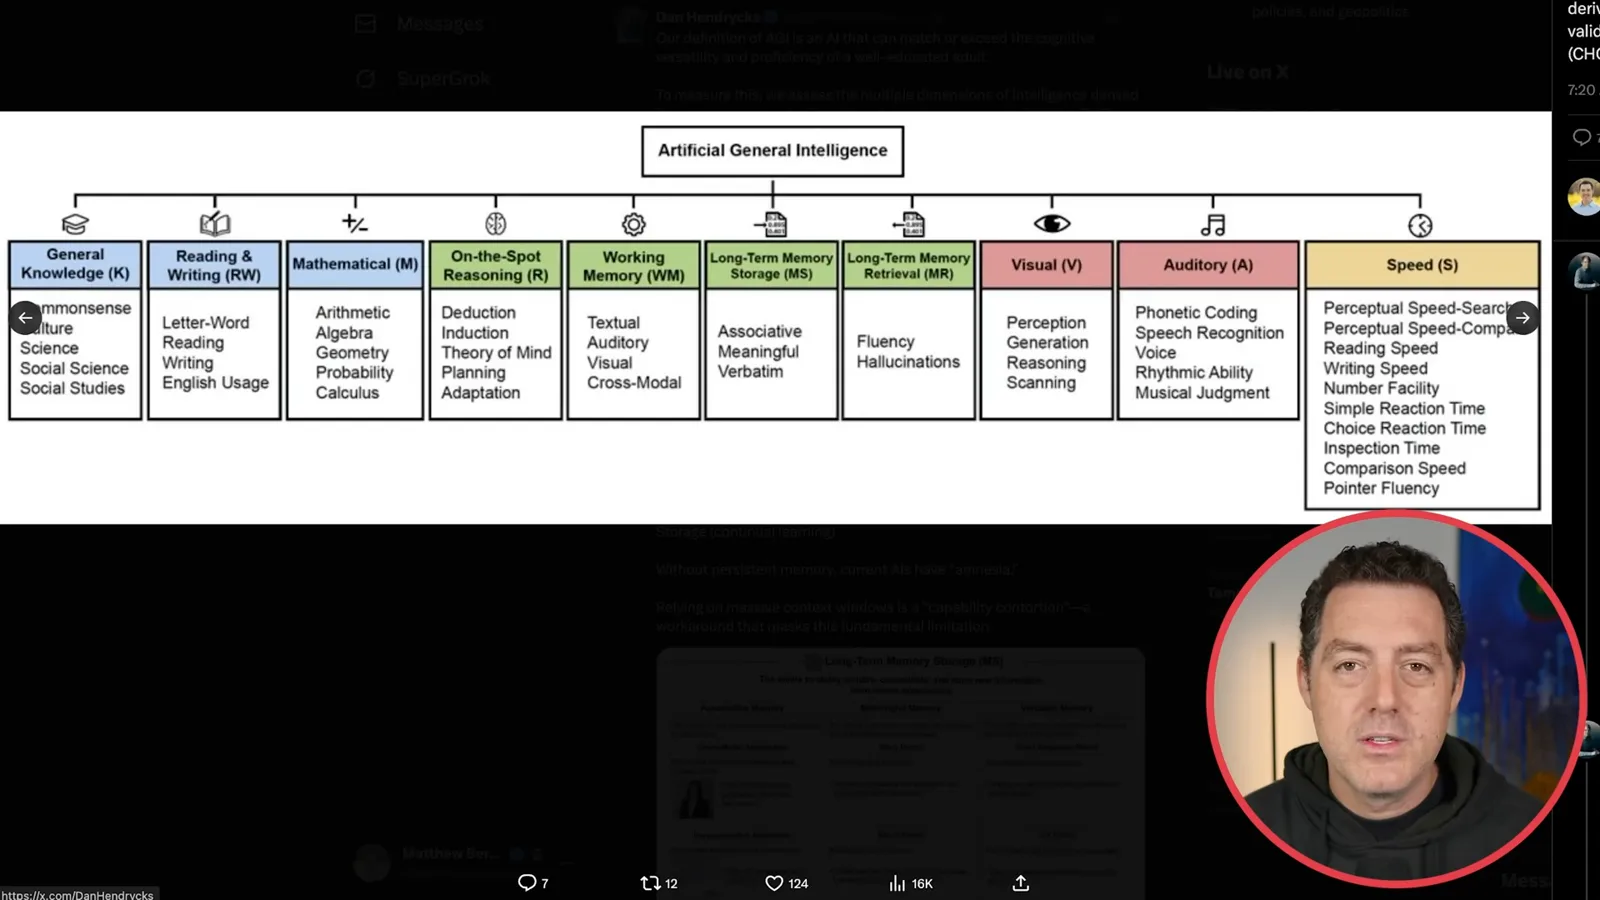
Finally, Dan Hendrycks and colleagues proposed defining AGI as matching or exceeding a well-educated adult's cognitive versatility and proficiency. Their framework divides ability into categories derived from CHC theory, including knowledge, reading and writing, mathematics, reasoning, memory, vision, hearing and speed.
The researchers' reported scores put GPT-4 at 27% and GPT-5 at 58% under their framework. I thought that suggested rapid progress, but the figures depend on the proposed definition and measurement choices, not a universally agreed percentage of the distance to AGI. The framework treats persistent long-term memory as a distinct ability; its authors argue that large context windows are not an equivalent substitute.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.