In 30 seconds
Matthew Berman walks through Veo 2 samples of people, vehicles, animals, food and cinematic settings. He finds many scenes visually impressive but identifies failures in complex body motion and missing prompt details. Google’s displayed human-preference chart and Berman’s selected examples are useful snapshots, not a universal ranking of every video model.
- 1Cinematic promptingBerman highlights a DJ close-up and the model’s ability to follow descriptions of camera angle, movement and lenses.
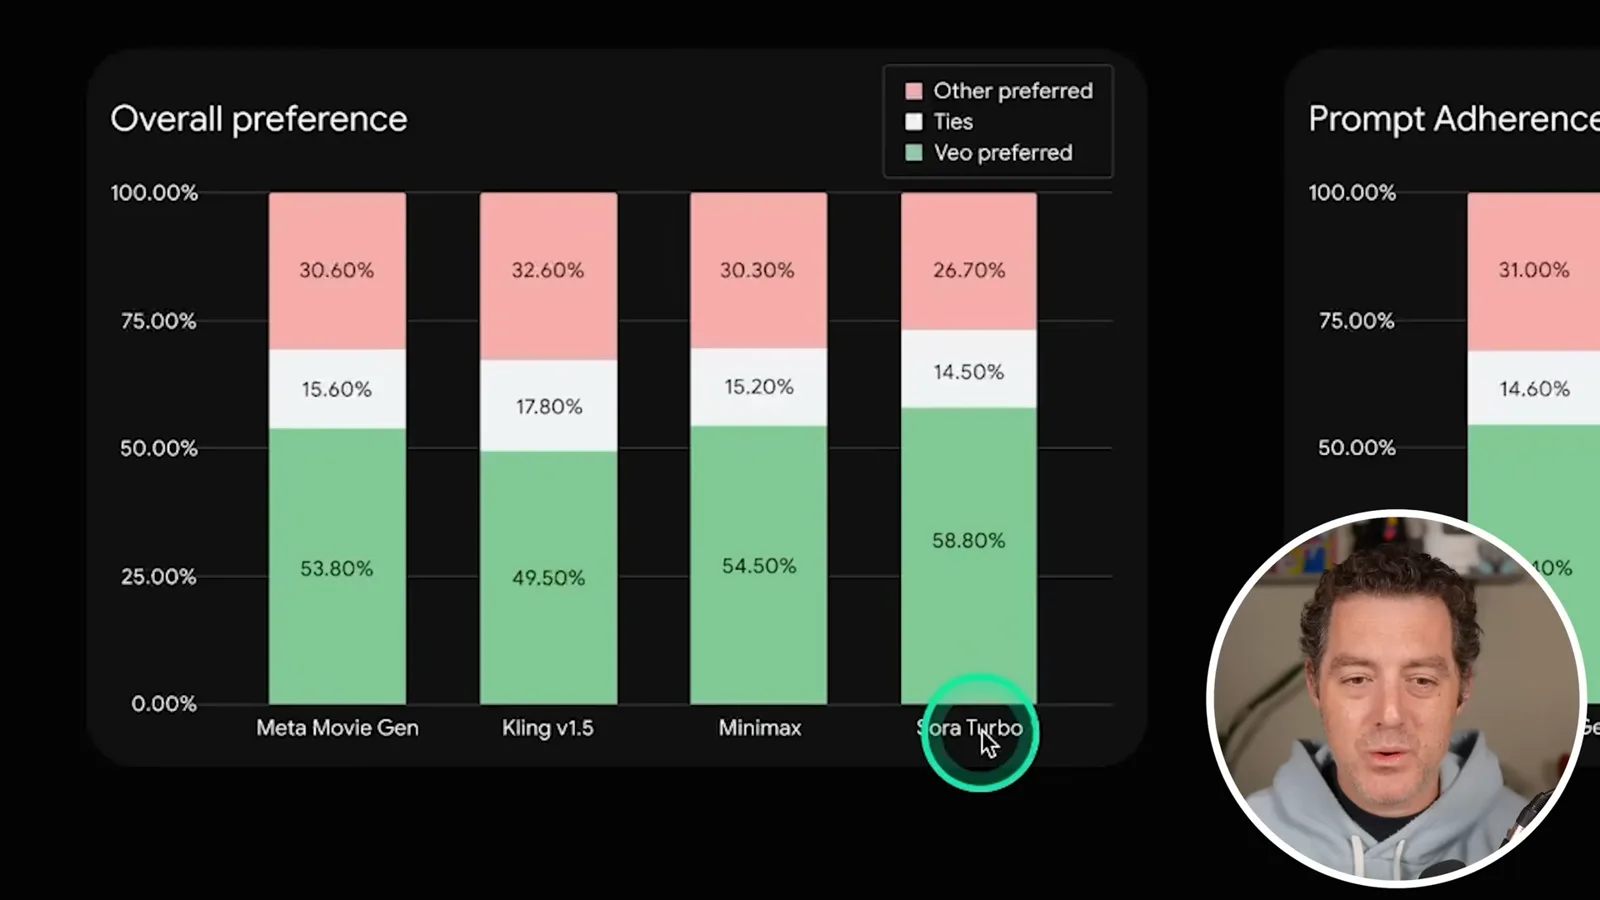
- 2A preference chartThe displayed Google chart compares human preferences against several 2024 competing models. Its result depends on the test and examples used.
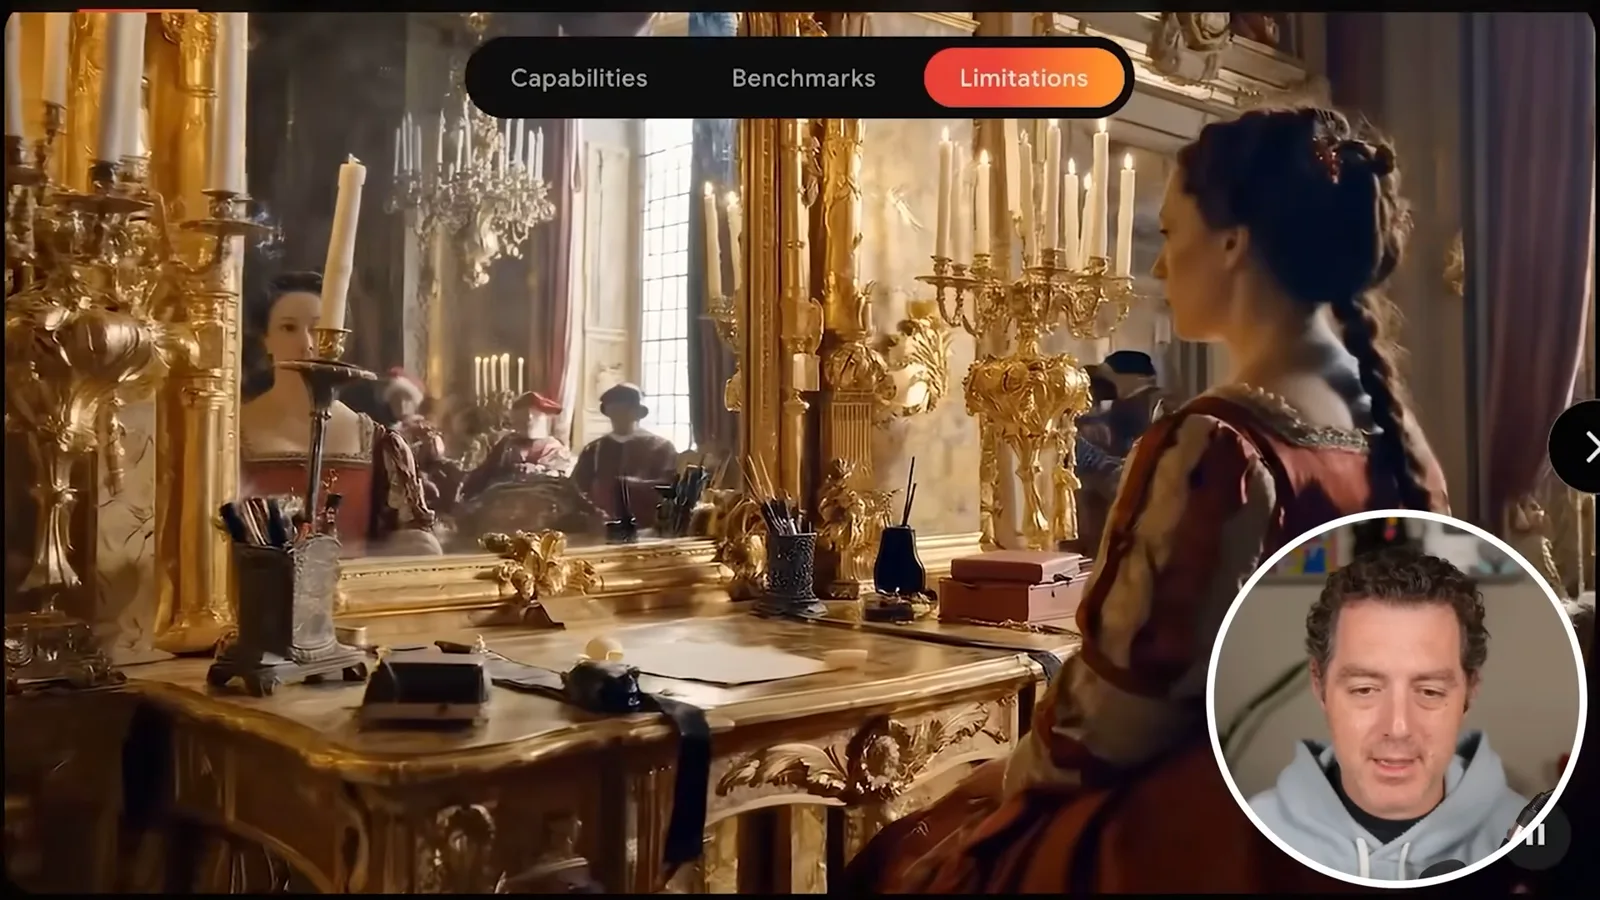
- 3Mirror and scene detailA palace example impresses Berman with a reflected face, though some details in the long prompt appear only partially.
- 4Difficult body motionAn ice-skating sample shows body-part distortions, and a skateboard example also breaks physical plausibility.
- 5Good visuals, missing detailsA breakfast sequence portrays liquids convincingly but omits some requested elements, including an orange close-up.
Takeaways
- Veo 2 accepts descriptive prompts about composition, camera movement, lenses and visual style.
- Berman finds several selected examples convincing, including reflections, liquid and animal footage, while acknowledging visible failures.
- Complex motion can cause limbs to distort or detach, and generated clips may omit requested details.
- Google’s displayed preference comparison is specific to its evaluation and competing model versions, not proof of universal superiority.
- The review reflects the 2024 release and its contemporary models, rather than current video-generation rankings.
Read the edited text by chapter
First examples and camera control
Berman reviews a DJ, a cartoon character and a drifting car. He explains how detailed cinematography prompts shape the scenes.
Google DeepMind has announced Veo 2, a text-to-video model, and the examples look impressive to me. I am particularly struck by the realistic appearance and the way some clips depict motion. This review is a snapshot of the December 2024 release; comparisons with Sora and other models refer to the versions and selected samples available then.
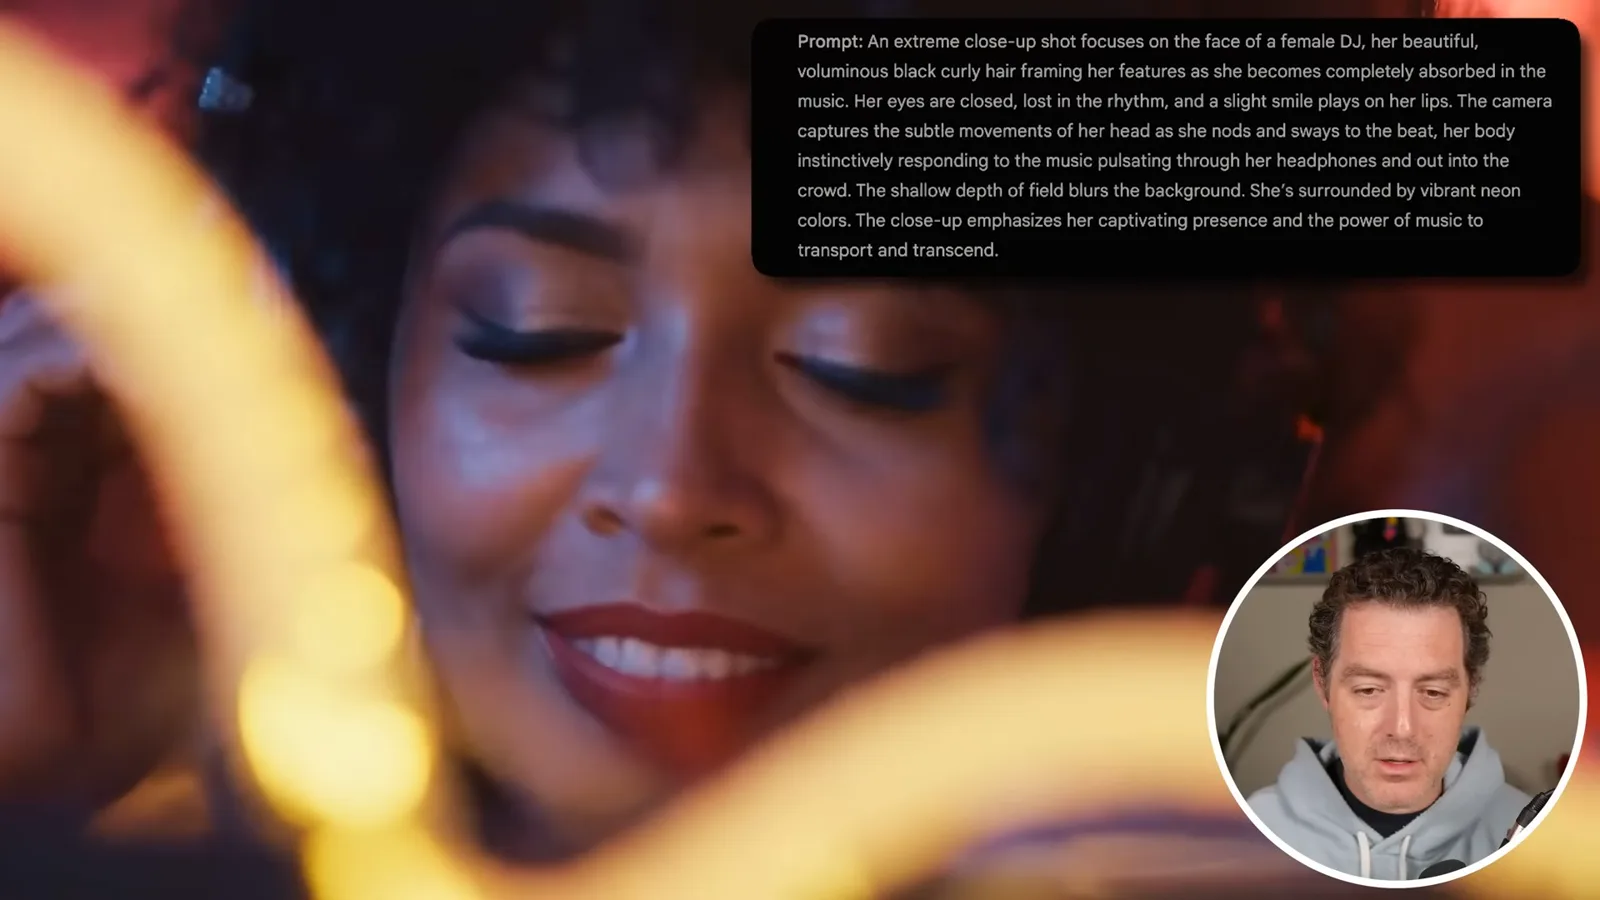
The first example is a close-up of a DJ with her eyes closed, moving to the music amid neon colors. The prompt describes her face and hair, a shallow depth of field and the camera’s close framing. I find the expression and image quality convincing. Prompts that specify shot type, lens and camera movement seem especially useful here.
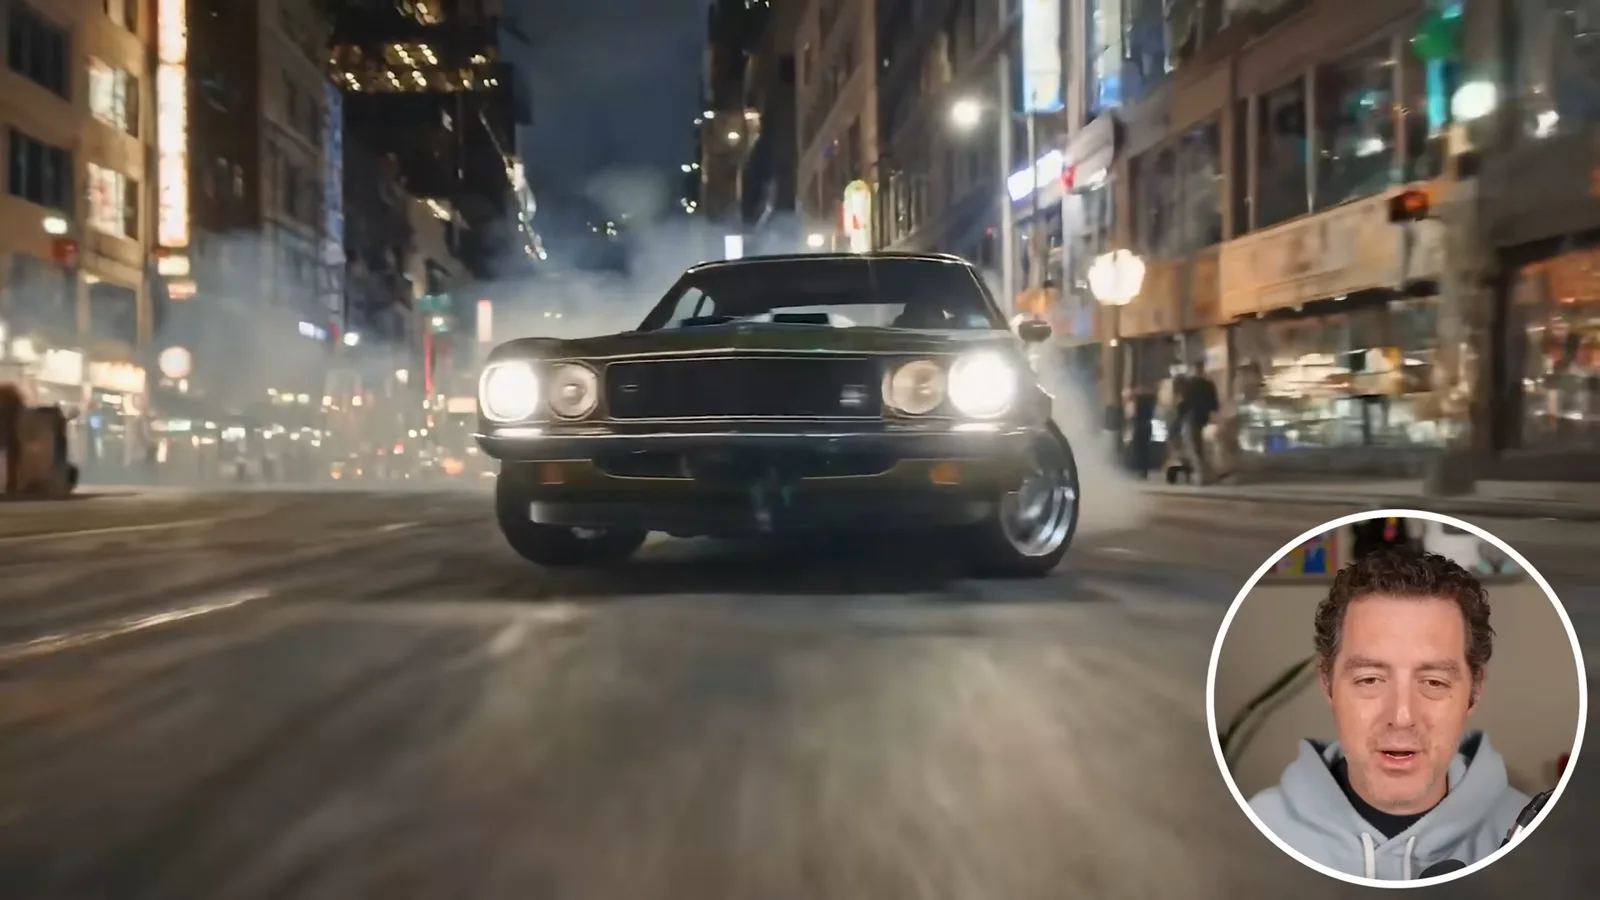
A second sample asks for a medium shot of an animated cartoon girl in a 1980s kitchen, again specifying shallow depth of field. Another uses a low tracking angle and an 18 mm lens to show a muscle car drifting through a street. I like the reflections and tire smoke, and the detailed cinematic instructions give a clear idea of the intended shot.
Preference comparisons and a palace scene
He discusses Google’s human-preference chart and a mirror reflection example. The clips and evaluation represent selected 2024 comparisons.
Google displays a human-preference comparison against Meta Movie Gen, Kling 1.5, Minimax and Sora Turbo. In the chart, raters preferred Veo in 58.8% of the Sora Turbo comparisons, preferred Sora in 26.7%, and tied 14.5%. Those numbers describe Google’s particular evaluation and model versions, not a guarantee that Veo wins on every prompt.
A palace scene shows a woman at a desk reflected in a mirror as the camera moves behind her. I find the reflection and rich interior convincing. The prompt also asks for a crimson gown, letter, background figures and dramatic lighting; some are only glimpsed or represented imperfectly. A polished sample is still one selected output, not a complete test of scene consistency.
Motion failures and prompt omissions
Ice skating and skateboarding show problems with complex movement. Food and beekeeper examples are visually strong but do not include every requested detail.
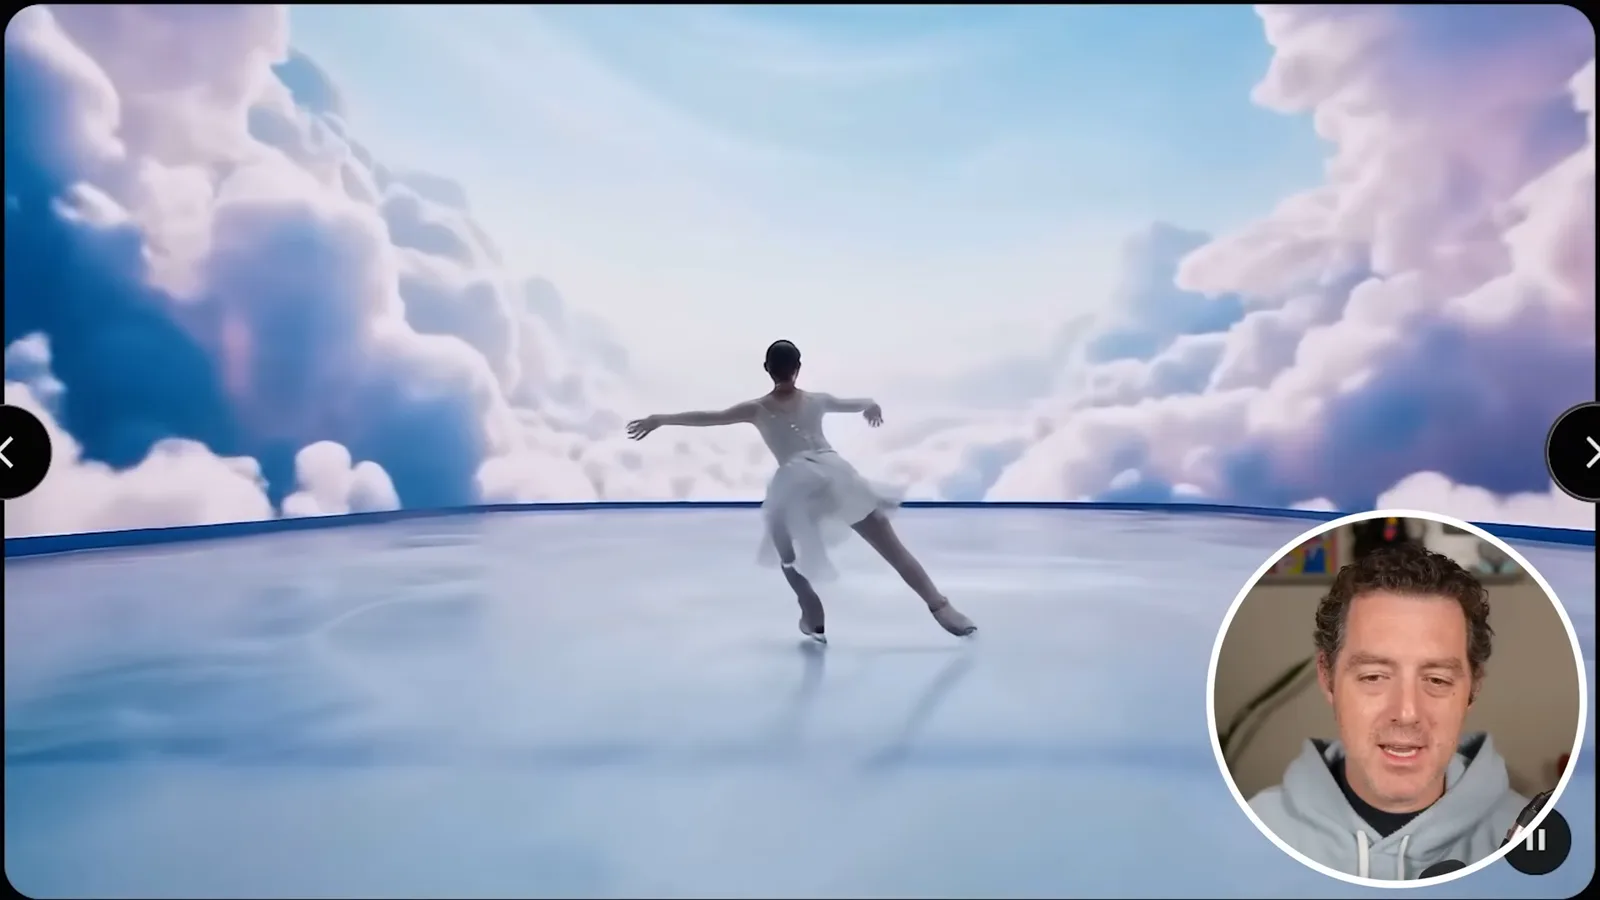
Complex physical movement remains difficult. I show a Sora gymnast whose body appears disconnected, followed by a Veo 2 ice skater whose legs and torso distort during a spin. A skateboarder also makes implausible movements after leaving the ground. These examples show that attractive frames do not guarantee consistent anatomy or physical motion throughout a clip.
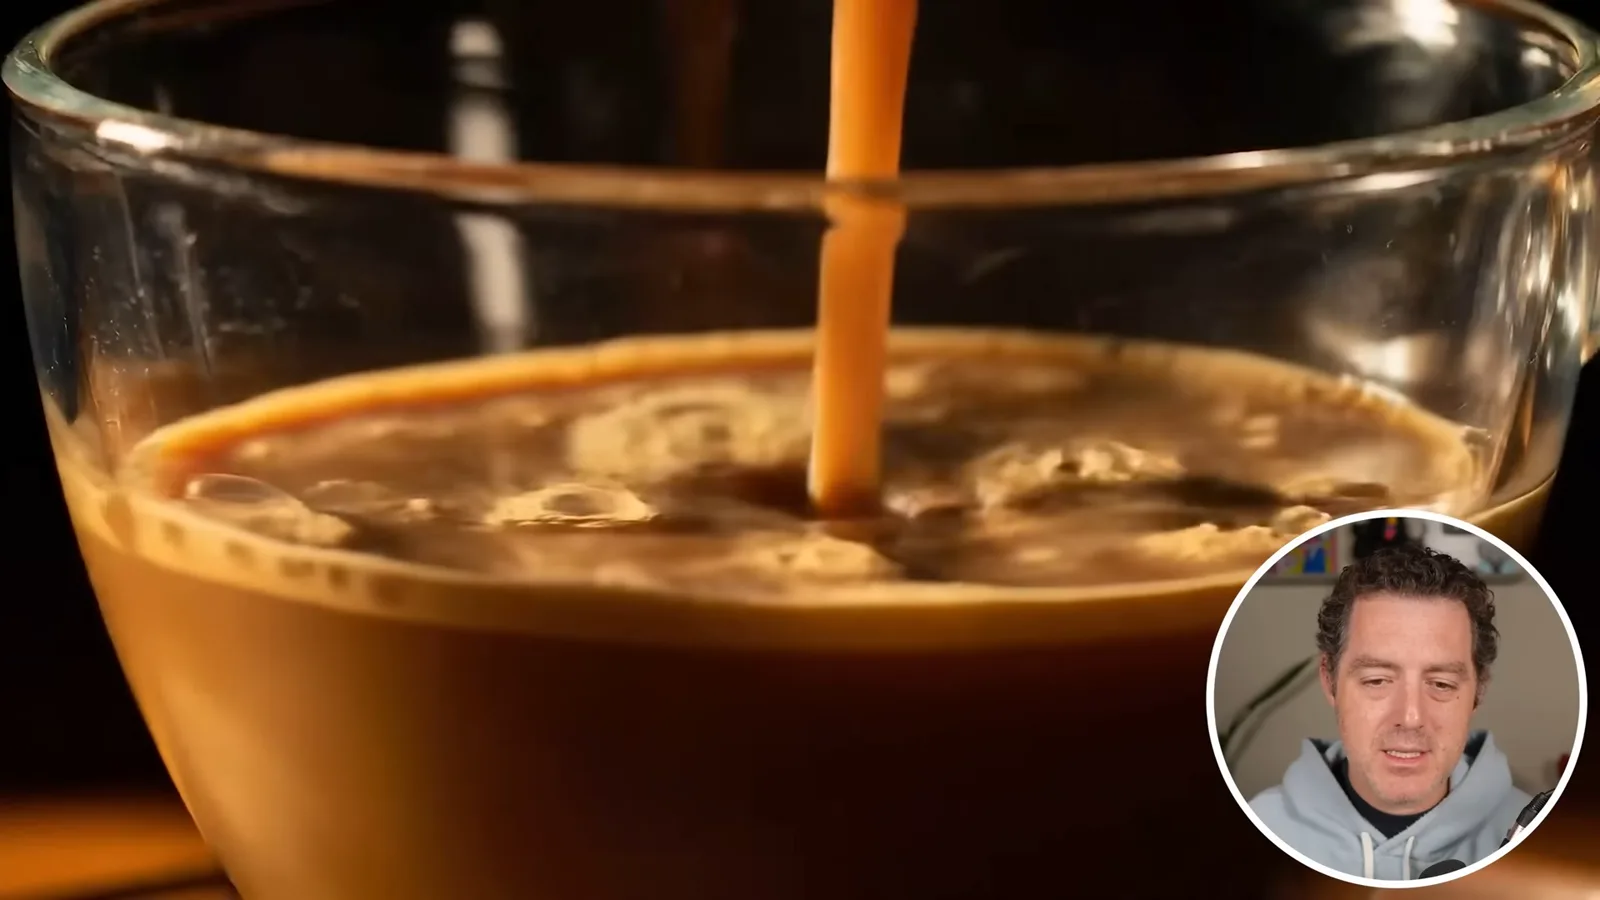
The breakfast example depicts syrup over pancakes and coffee pouring into a clear cup. I like the appearance of the liquids, but the requested close-up of a cut orange does not appear, and some other prompt details are missing. Visual quality and complete prompt adherence are separate questions.
Another sample follows a beekeeper among hives and sunflowers, with a detailed prompt mentioning camera movement, a 35 mm lens and film stock. I find the farmer and bees convincing, although the requested farmhouse and shutters do not appear. The ability to express camera language in a video prompt reminds me of techniques used in image generators.
Google describes improved realism, motion and camera control as Veo 2’s differentiating features. Its [December 2024 announcement](https://blog.google/innovation-and-ai/models-and-research/google-labs/video-image-generation-update-december-2024/) also notes that generated videos can still contain unwanted details. These are company claims and examples; a model’s apparent realism varies by task and output.
Comparisons and more generated clips
Berman compares selected animal clips from several models, then surveys imaginative scenes and everyday actions. His ratings are subjective impressions of individual outputs.
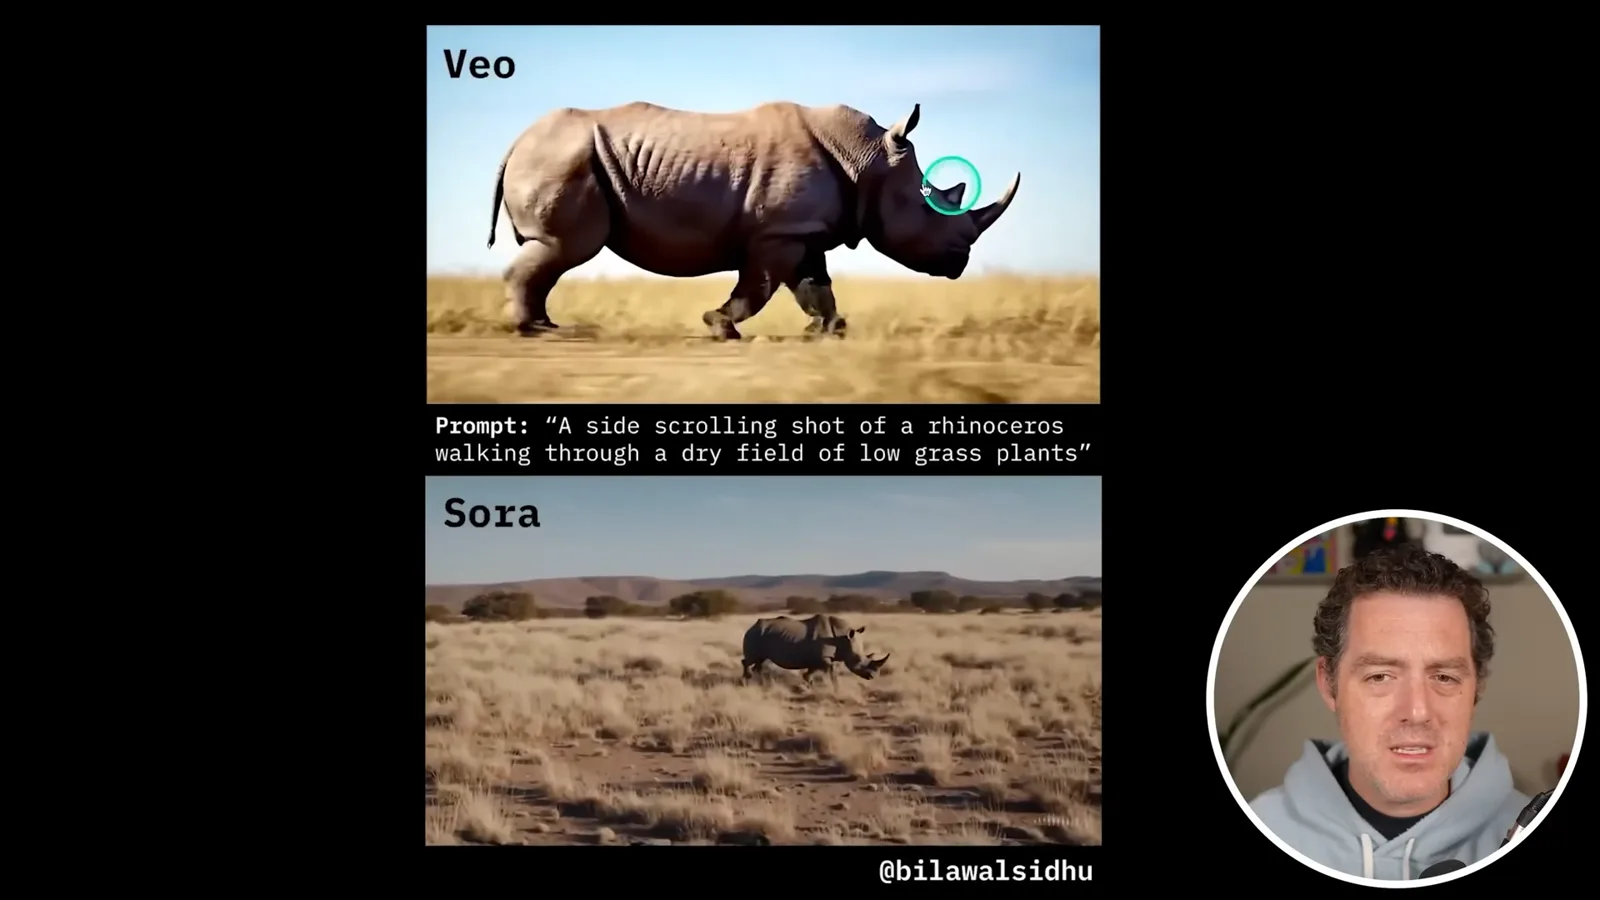
In a side-by-side rhinoceros prompt, the Veo output looks somewhat rigid, while the Sora sample begins with convincing movement but later appears to float. My preference for the Veo clip is a judgment about these particular generations, not a controlled comparison across all prompts. Another Veo rhinoceros sample looks to me like nature-documentary footage.
I look through several horse clips. One horse passes through a fence, even though the rest of the scene looks good; another shot hides the full body, and another has slightly unnatural movement. Some other examples appear more convincing. The comparison illustrates why examining the whole clip matters more than judging a single frame.
I compare additional clips from Hailuo and Sora Turbo. In the samples shown, some animals float, morph or move awkwardly. These are selected examples from different models and are not a comprehensive independent evaluation, but they make the remaining motion problems easy to see.
The later examples range from a pelican riding a bicycle to a car going over a waterfall, a market in the sky and animated potato chefs. These are fantastical rather than physically realistic subjects, yet I find their visual presentation compelling. A drifting car also retains a readable Veo license plate in the sample shown.
I also examine fabric falling onto marble, a woman and cat briefly hidden by a passerby, an octopus, shuffling cards and a jumping cat. The examples show different challenges—cloth movement, occlusion, morphing and hands. I find many impressive, while noting that the octopus and cards are not perfect.
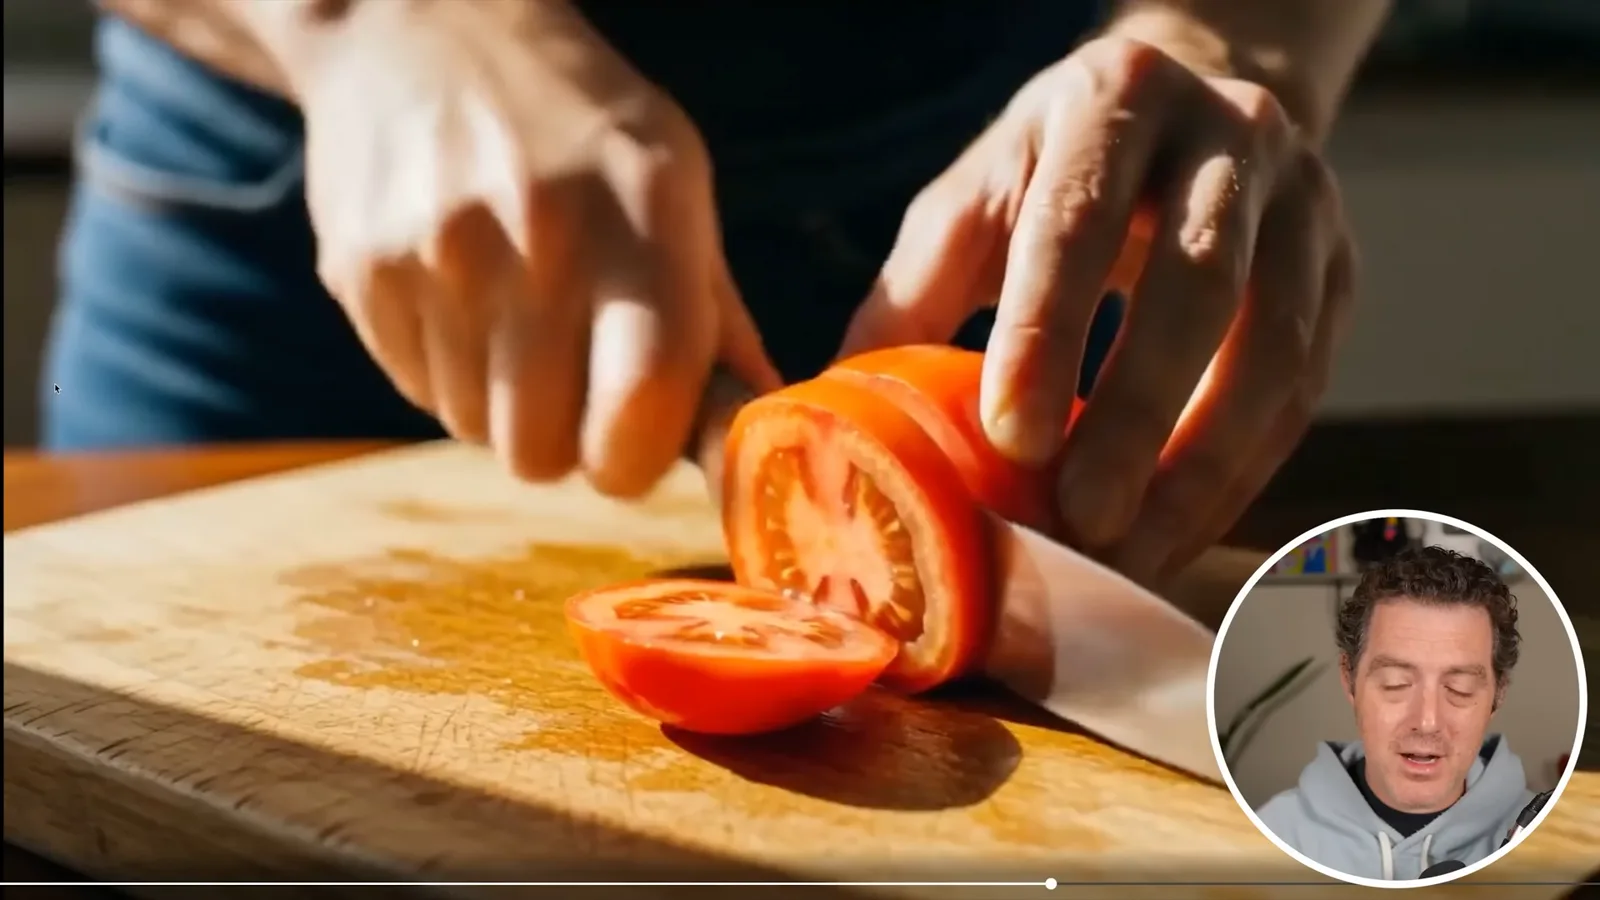
The final clips show running giraffes and a tomato being sliced. I am particularly impressed by the tomato’s reflections and apparent motion. These are my visual impressions of selected examples; they do not establish that the model consistently reproduces animal movement or real-world physics.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.