In 30 seconds
In this March 2025 roundup, Matthew Berman discusses updates to GPT-4o, Gemini 2.5 Pro and DeepSeek V3, alongside ARC-AGI-2, MCP integrations, image models and QVQ-Max. He cites benchmark claims and reporting on OpenAI’s finances, and offers his own assessments of speed and usefulness. Rankings, rollout details and projections are historical snapshots rather than current standings.
- 1GPT-4o updateArtificial Analysis reported higher scores on its selected indices; Berman also describes his own concerns about response speed.
- 2Gemini and DeepSeekBerman praises Gemini 2.5 Pro and reviews DeepSeek’s updated V3 checkpoint and its reported benchmarks.
- 3A harder ARC benchmarkARC-AGI-2’s early table compares a human panel and AI systems under specific task and cost settings.
- 4MCP integrationsZapier, OpenAI and Microsoft were adding support for a common protocol connecting models to external tools.
- 5QVQ-MaxQwen introduced a visual reasoning model; Berman’s claim that this specific model was open and downloadable is not substantiated by the cited announcement.
Takeaways
- Artificial Analysis reported that the March 2025 GPT-4o update improved its selected intelligence and coding scores among non-reasoning models.
- Berman praises Gemini 2.5 Pro for coding speed and notes the release of the open-weight DeepSeek-V3-0324 checkpoint.
- ARC-AGI-2 launched with low scores for the tested AI systems and a human-panel comparison, but one benchmark cannot establish general intelligence.
- Zapier, OpenAI and Microsoft announced or documented MCP integrations for connecting agents to tools.
- Berman discusses Reve Image 1.0, Ideogram 3.0 and QVQ-Max, but the QVQ-Max announcement does not establish his claim that its weights were downloadable.
- The OpenAI revenue figure he cites was a 2025 projection reported by CNBC, not realized revenue.
Read the edited text by chapter
GPT-4o and Gemini updates
Berman reviews an updated GPT-4o and its benchmark results, while noting latency and image-generation limits. He praises Gemini 2.5 Pro for coding and speed.
In late March 2025, I review a series of AI releases. Artificial Analysis reported that the updated GPT-4o improved on its selected intelligence and coding indices, leading the non-reasoning models it compared for coding. Those scores are specific to the evaluator’s benchmarks and the models available then, not a permanent ranking across all tasks.
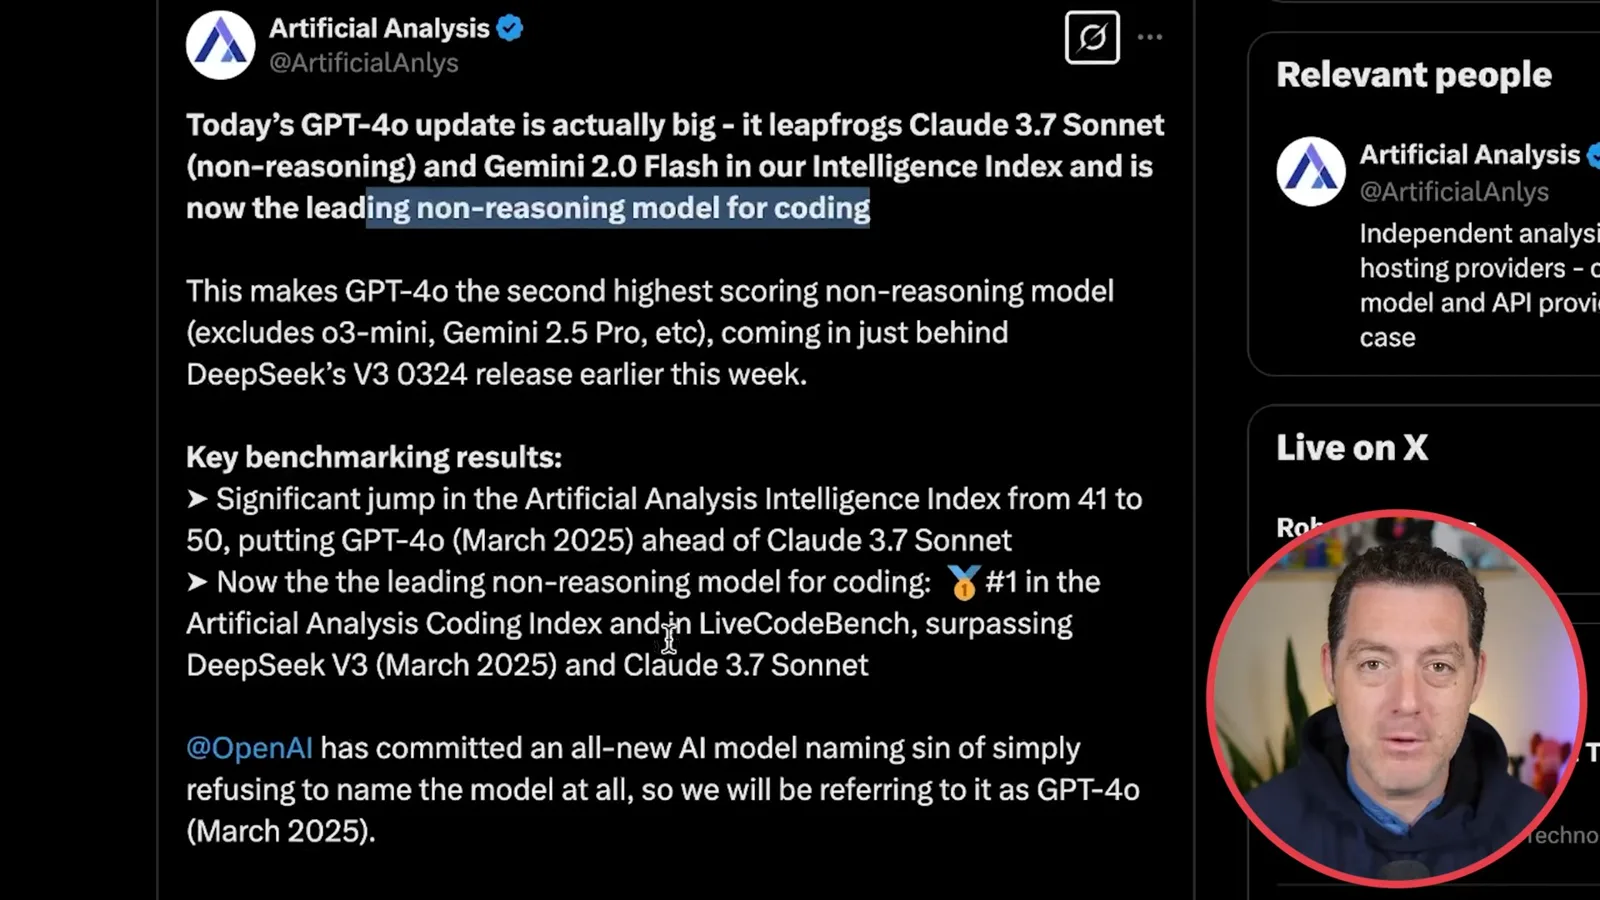
The displayed intelligence index rose from 41 for the November 2024 version to 50 for the March update, just behind the new DeepSeek V3 in that index. I also discuss high demand for compute and invoke Jevons’ paradox: cheaper or more efficient AI can encourage more use. That is a possible demand response, not proof that every efficiency improvement increases total spending.
OpenAI described improvements in detailed instruction following, technical and coding tasks, creativity and emoji use. I note that the updated model was being rolled out to users and that image-generation limits were introduced amid high demand. In my own experience, ordinary GPT-4o queries had also become slow; that anecdote is not a controlled latency comparison.
I am impressed by Gemini 2.5 Pro, particularly its coding performance and speed, and say it is the best coding model I have personally used at that point. The model was appearing in tools including Windsurf and Cursor. I want to test its one-million-token context window against my own codebases; a large context window alone does not prove that a model will use every part of it effectively.
DeepSeek and ARC-AGI-2
He discusses the updated V3 checkpoint and its reported performance. He then examines the new ARC benchmark and its early human and model comparisons.
DeepSeek also released the V3-0324 checkpoint. Its model card reports improvements over the earlier V3 and lists an MIT license; the weights are available, though the model’s size makes local use demanding. I highlight its reported coding and math results, including AIME 2024, while recognizing that developer-selected benchmarks and settings are not a complete measure of performance.
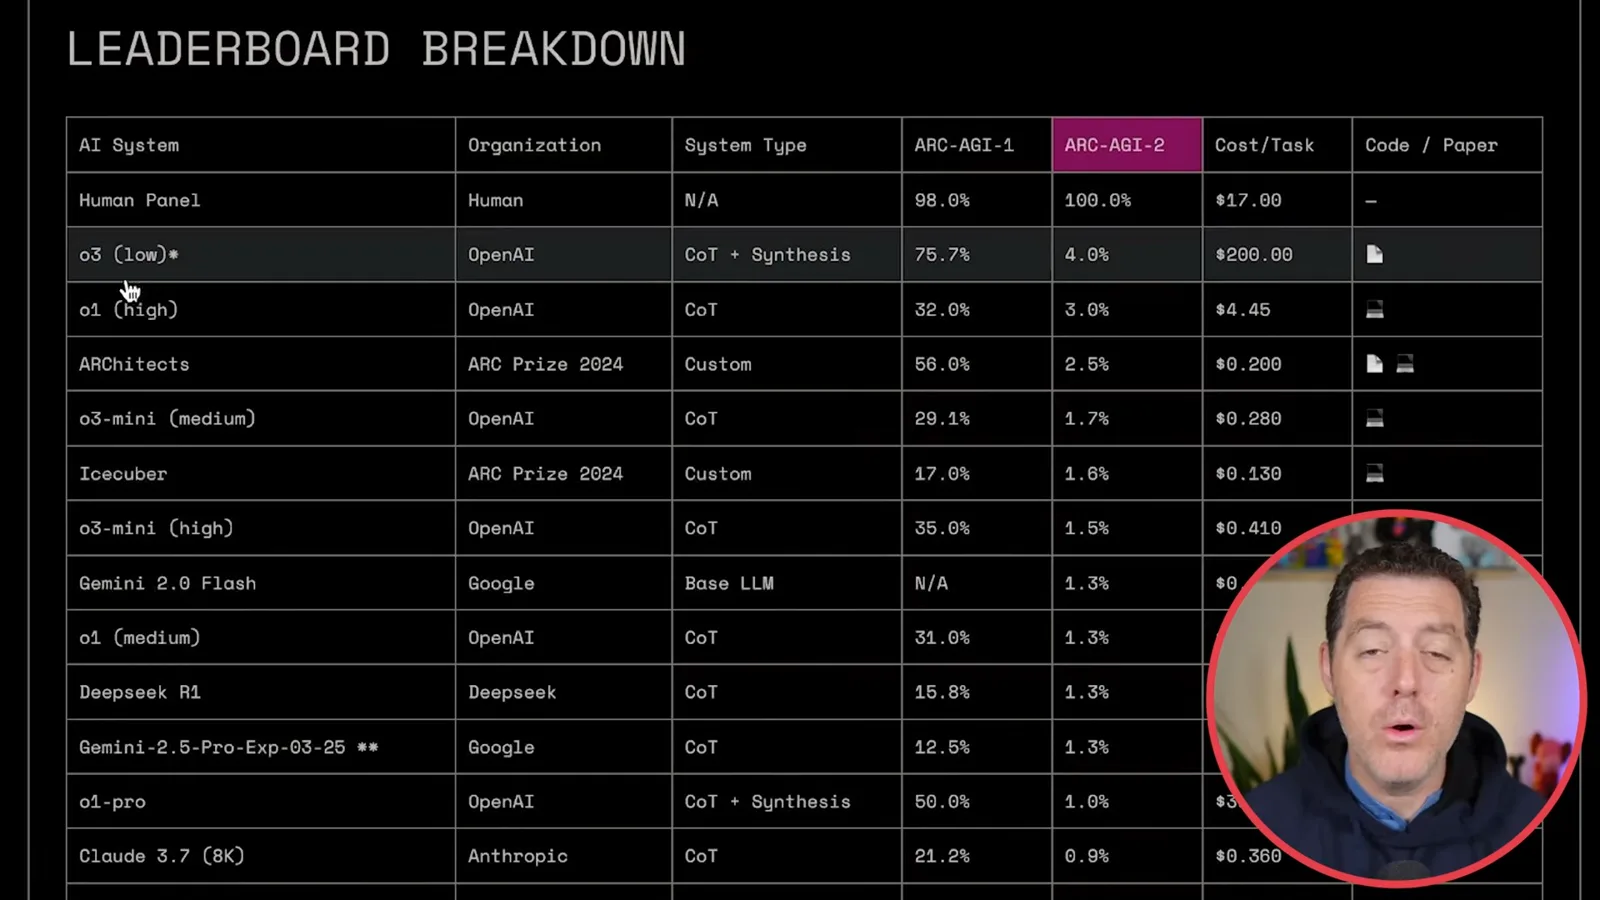
ARC Prize launched ARC-AGI-2 as a more difficult test of adapting to new visual patterns. The early table shown in the video lists o3 low at 4% on ARC-AGI-2 versus 75.7% on ARC-AGI-1, and a human panel at 100% and 98% respectively. These figures describe the specific early evaluation and panel, not every person or all future models.
The table shows an estimated $200 per task for o3 low and $17 for the human panel. I also misread the o1 high cost aloud as $445; the displayed table says $4.45. I like the benchmark because it asks systems to infer transformations from examples, but my description of it as a perfect AGI test is an opinion: no single benchmark establishes general intelligence.
An example uses colored grids: the solver examines input-output pairs, infers a pattern and applies it to a new input. ARC Prize reported that each ARC-AGI-2 task had been solved by at least two people within two attempts. That task-selection process is useful context for interpreting the human comparison, rather than a claim that every individual finds every task easy.
MCP and image models
Berman describes early MCP integrations and reviews image-generation releases from Reve and Ideogram. The visual examples and rankings are time-specific.
Zapier announced an MCP integration that could expose its connected apps to AI agents. OpenAI’s Agents SDK and Microsoft’s Copilot Studio also documented MCP support. I see a common protocol for connecting models to tools and context as a major development; the specific integrations, permissions and available tools depend on the service and configuration.
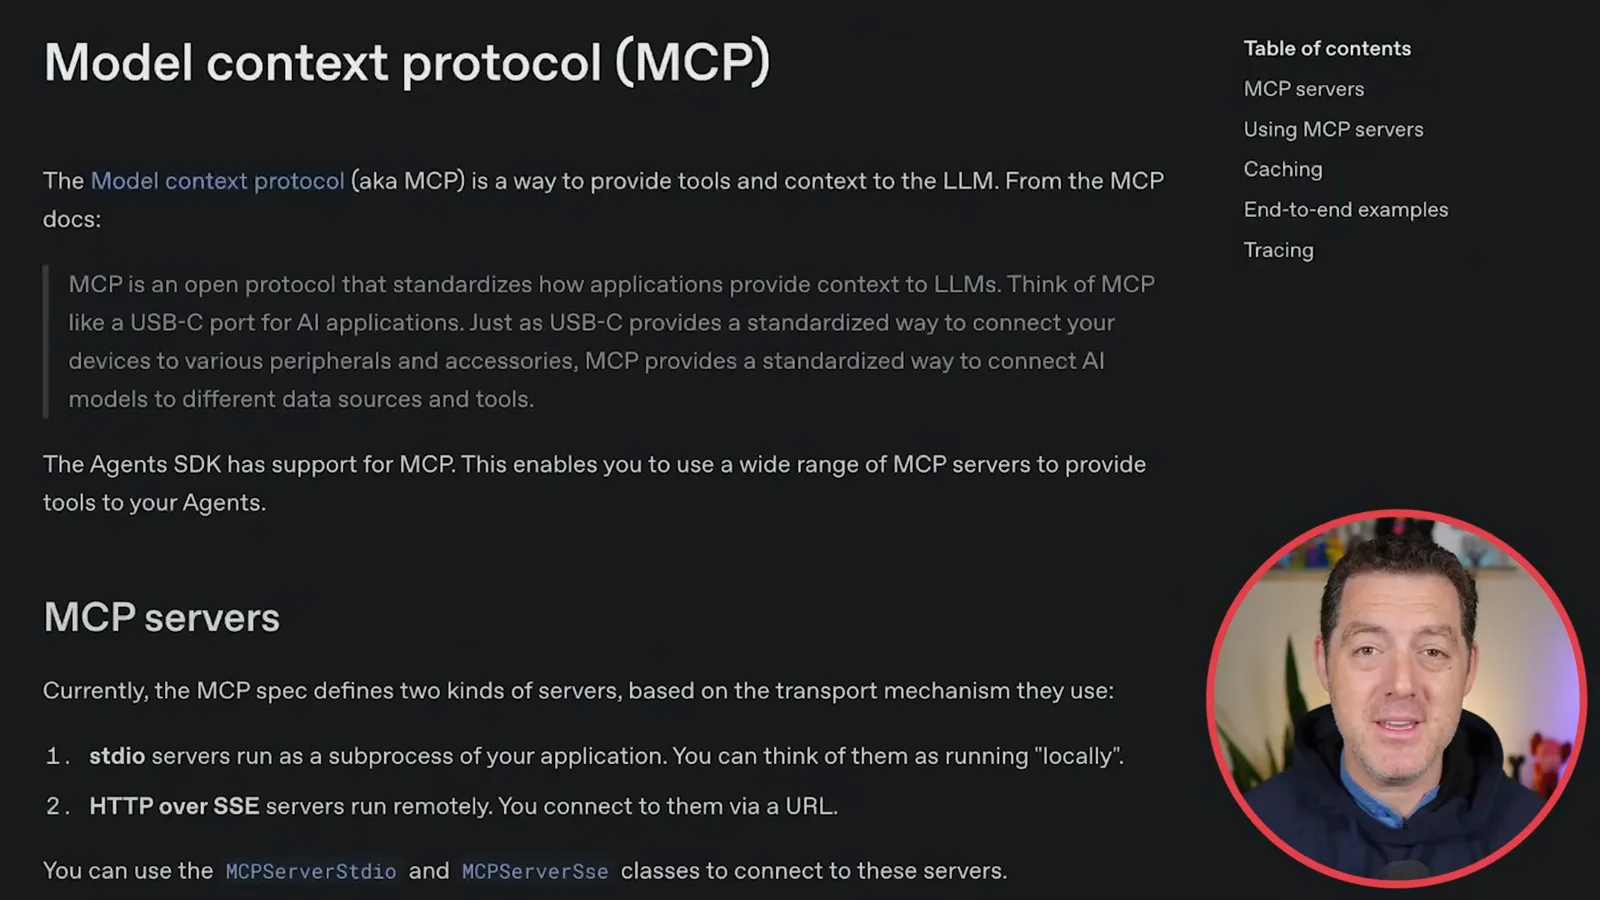
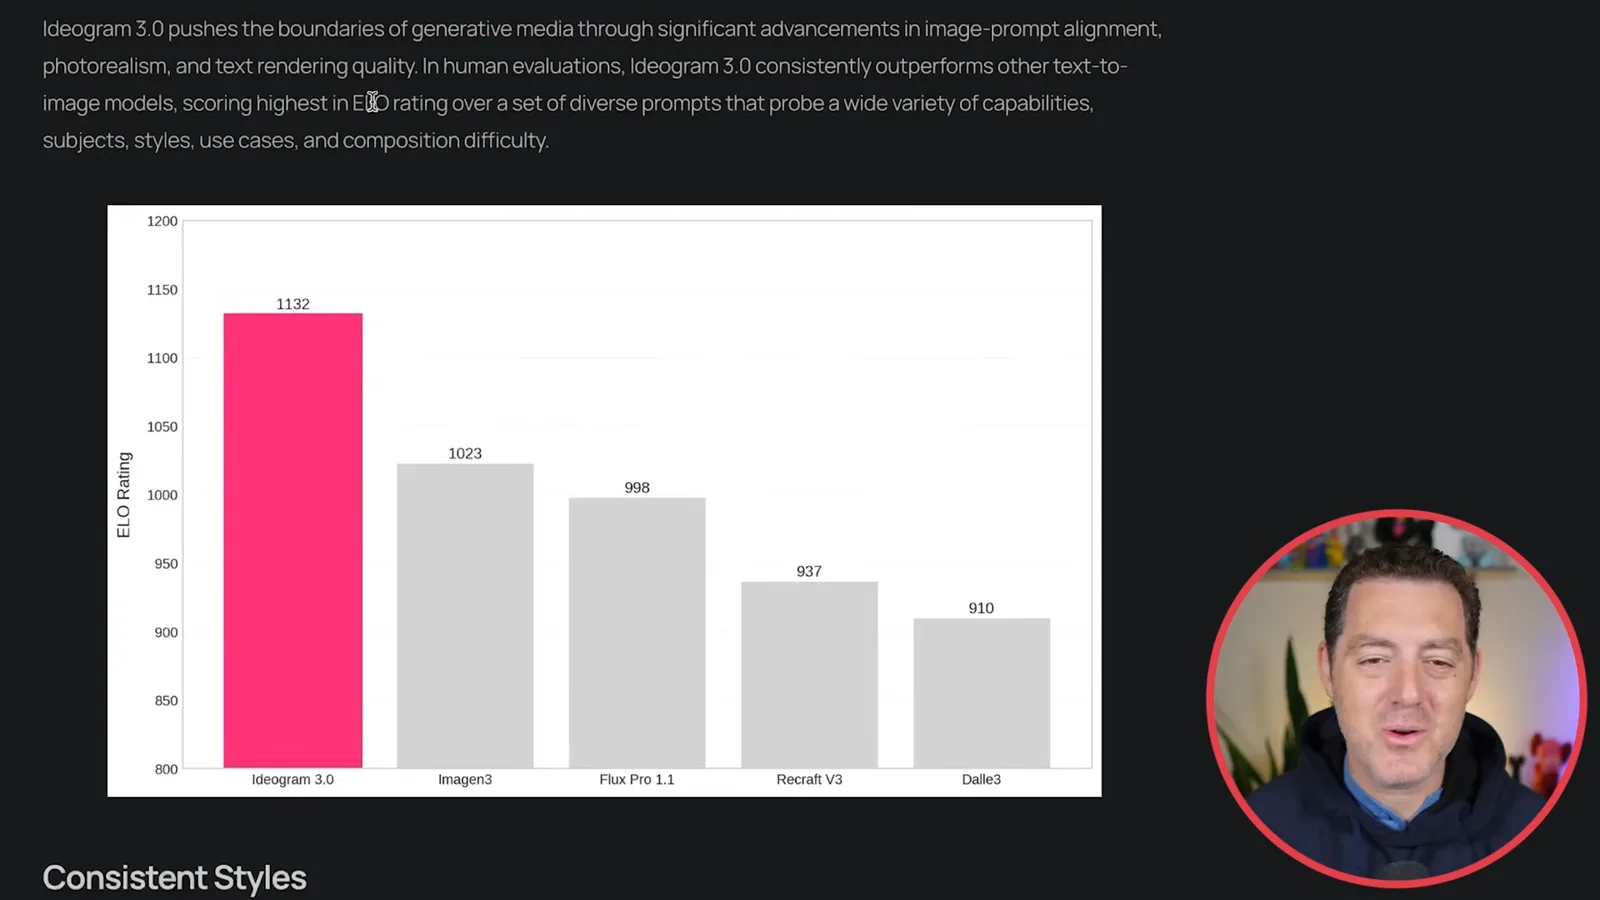
Image generation was another major topic that week. I show examples from Reve Image 1.0 and mention its position in an Artificial Analysis user-vote ranking. I also discuss Ideogram 3.0, whose company reported a strong Elo rating and offered features such as remixing, upscaling and styles. These are selected examples and dated evaluations, not proof that every generated image or text rendering is accurate.
OpenAI finances and QVQ-Max
He discusses a reported OpenAI revenue forecast and leadership changes. The roundup closes with Qwen’s visual reasoning announcement and access limitations he encountered.
CNBC reported that OpenAI expected revenue to reach $12.7 billion in 2025, roughly triple the previous year, according to sources. That was a forecast, not realized revenue. I am personally optimistic about the value of AI tools and acknowledge my own stake in the subject; my team and family’s experience is anecdotal, and I think education about practical uses matters.
I also discuss reported leadership changes in which Sam Altman would focus more on research and product while Brad Lightcap took a larger operational role. I mention the reported SoftBank investment plans and valuation as they stood at the time; a proposed deal or valuation should not be confused with a completed financing or a measure of profitability.
Qwen announced QVQ-Max as a visual reasoning model able to analyze images and video. Its team presented examples and benchmark claims, including a demonstration comparing two scenes. I describe it as open and downloadable, but the cited QVQ-Max announcement does not establish release of that specific model’s weights; the earlier QVQ-72B-Preview is a separate model.
I note access constraints I encountered with Qwen’s service and hope that additional providers will make models easier to use. Availability, regional requirements and whether weights can be downloaded depend on the particular product and date. The demonstration offers an example of visual reasoning, not a systematic assessment of all its capabilities.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.