In 30 seconds
Matthew Berman walks through xAI’s Grok-1.5V announcement, comparing its vendor-reported benchmark scores and showing examples involving diagrams, photos, text and spatial questions. He runs one supplied guessing-game program but has not independently tested the preview model itself.
- 1Vendor-reported comparisonsxAI presents zero-shot benchmark results that vary by dataset. The reported scores do not establish that Grok leads every task.
- 2Flowchart to codeBerman runs the supplied Python guessing game generated from a handwritten diagram.
- 3Explaining a memeA published example interprets an exaggerated comparison of startups and large companies.
- 4Real-world spatial questionsxAI introduces RealWorldQA, with examples involving objects, signs, driving scenes and a compass.
Takeaways
- xAI previewed Grok-1.5V as a model able to process images, charts, documents and screenshots as well as text.
- Its reported benchmark results are mixed: it leads some listed tests but trails other models on others.
- Berman successfully runs the provided flowchart-to-Python guessing game, while the other examples come from the announcement.
- RealWorldQA initially contained over 700 images with spatial questions and verifiable answers.
- Berman’s speculation about Tesla training data is not confirmed by the announcement.
Read the edited text by chapter
A multimodal preview
Berman introduces Grok-1.5V and its promised visual inputs. He discusses the preview and his hope for open weights.
xAI has previewed Grok-1.5V, a multimodal model that can interpret visual input as well as text. The April 2024 announcement says it can process documents, diagrams, charts, screenshots and photographs. At the time of this video it is a preview promised to early testers and existing Grok users; I am looking at the company's examples rather than testing the model independently.
I am excited to try it when it becomes available, and I hope its weights will eventually be released. The earlier Grok-1 release had open weights, but that does not establish the release terms of Grok-1.5V, nor does open weights automatically mean the whole training process is open source.
Benchmark comparisons
He examines xAI’s reported results against other models. The scores differ by benchmark and are not a blanket ranking.
xAI says the model is competitive on several multimodal benchmarks and highlights a new spatial-understanding test, RealWorldQA. In the company's [published comparison](https://x.ai/news/grok-1.5v), Grok-1.5V was evaluated zero-shot without chain-of-thought prompting. The results are vendor-reported and show a mix of outcomes, not a universal win over every competing model.
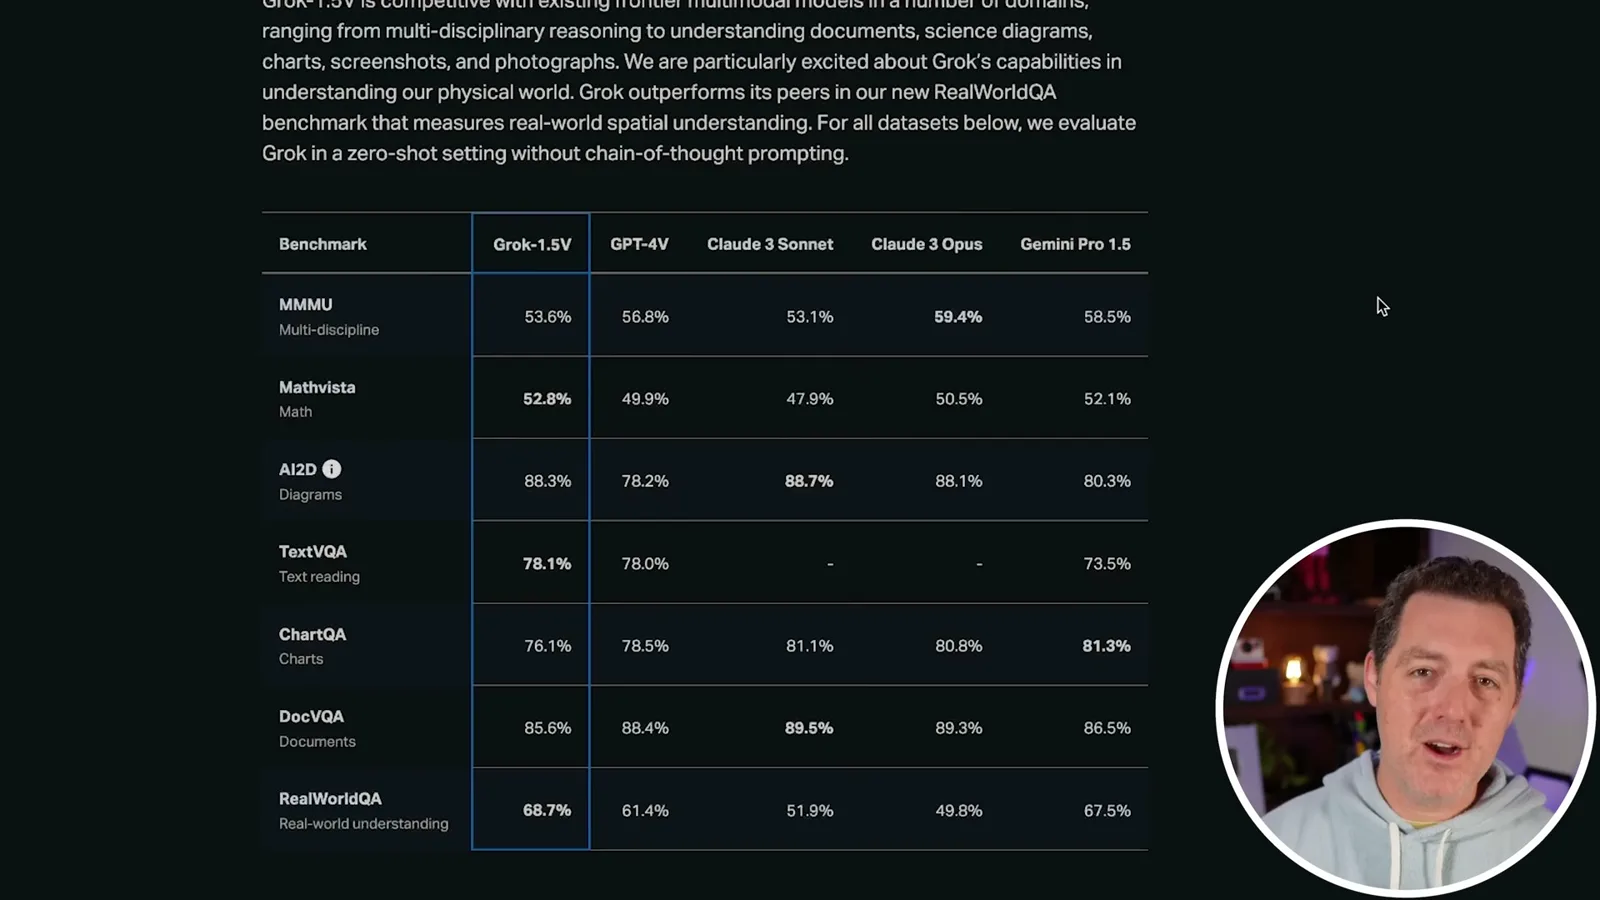
On MMMU, Grok scored 53.6%, below GPT-4V's 56.8% and Claude 3 Opus's 59.4%. On MathVista it led the listed models with 52.8%, and on AI2D diagrams its 88.3% narrowly trailed Claude 3 Sonnet's 88.7%. I find Claude 3 Opus strong in my own testing, although I consider it slower; that comparison is my experience, not a controlled measurement.
The same table lists Grok at 78.1% on TextVQA, 76.1% on ChartQA and 85.6% on DocVQA. Its RealWorldQA score was 68.7%, versus 67.5% for Gemini Pro 1.5. Results depend on the particular datasets and evaluation conditions, and xAI created RealWorldQA itself.
Images, stories and code
Berman walks through the company’s published demonstrations and runs the guessing-game code. He discusses nutrition, storytelling, a meme, a table, a deck photo and a coding problem.
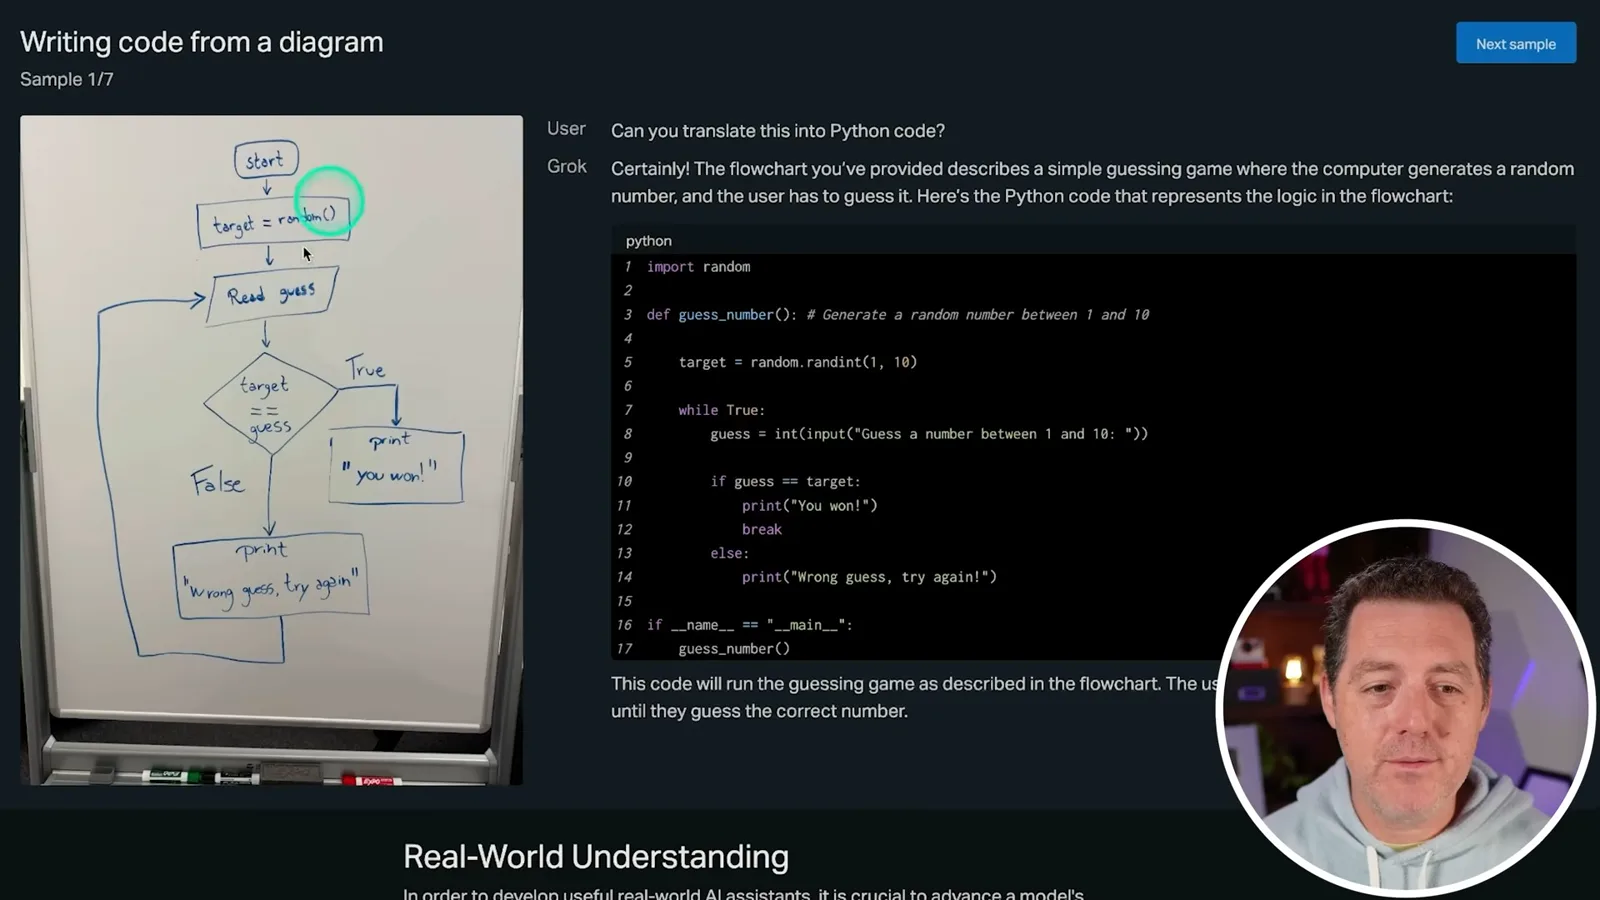
The first published example converts a hand-drawn flowchart into Python for a number-guessing game. The chart says to generate a random target, read guesses and report whether the guess is correct. I copy the supplied code into Visual Studio Code and run it: after several wrong guesses, the game accepts the correct number. This checks one published example, not every possible flowchart.
Another example gives the model a photo of a nutrition label and asks about five slices. The label says three slices contain 60 calories, so the illustrated answer calculates about 100 calories for five. It is an appealing demonstration of reading an image and performing a calculation, similar to the early GPT-4 Vision examples.
I think this kind of visual interface could become useful on AI devices: point a camera at something and ask a question about it. Another example turns a child's simple drawing, including a person and a boat, into a short bedtime story. The output connects those elements into a story about a boy and a paper boat.
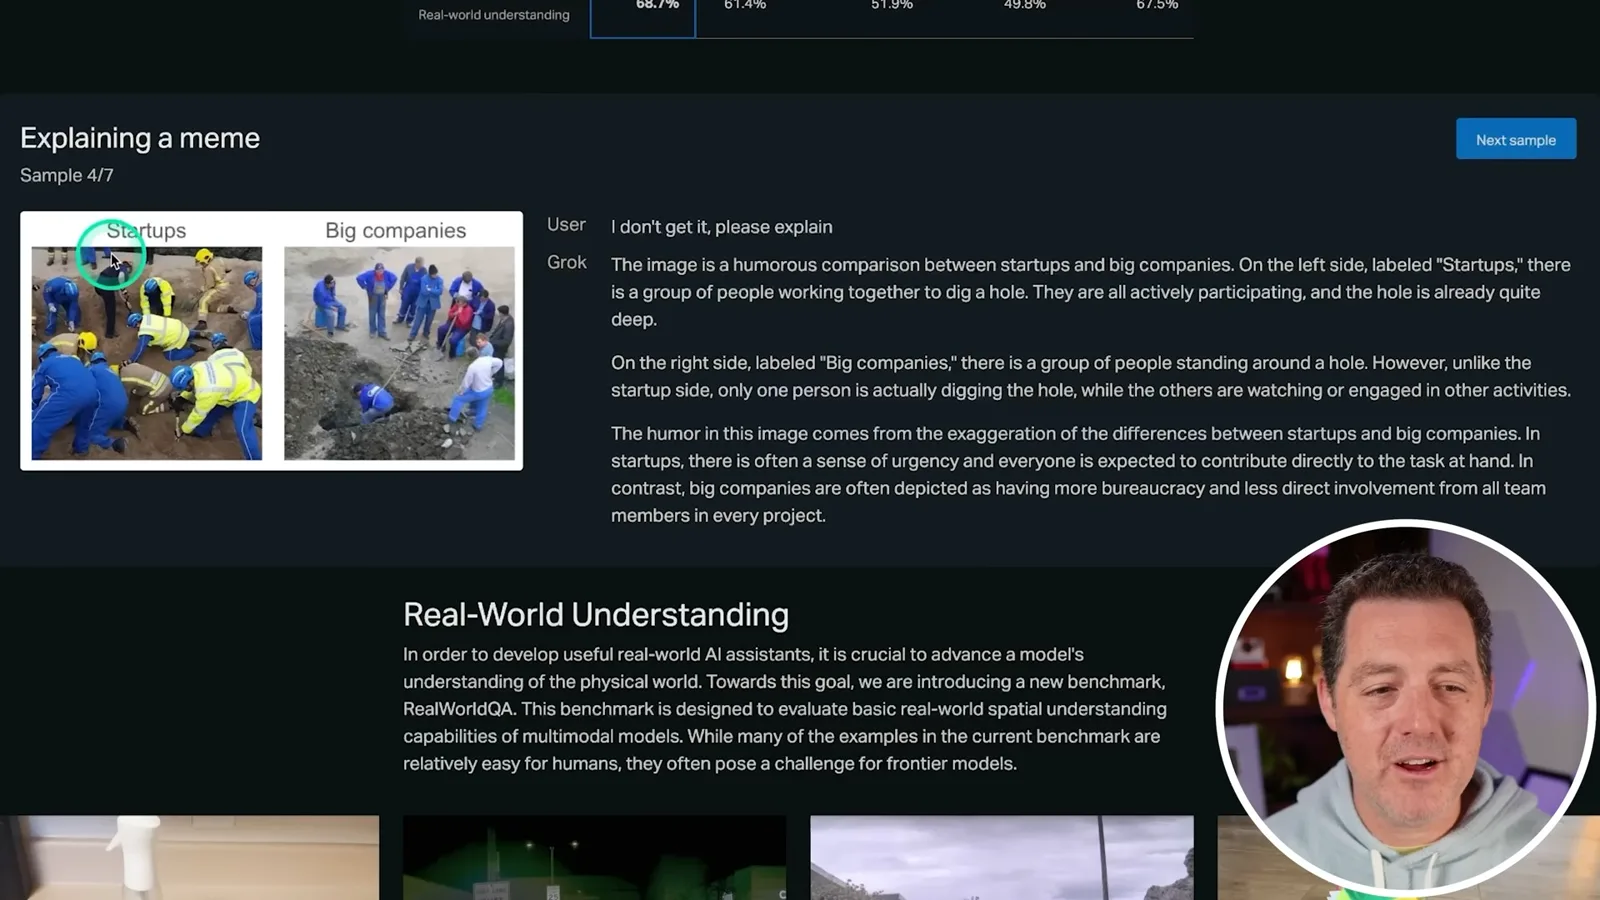
One example asks Grok to explain a meme contrasting startups and large companies. The picture shows a group digging together on one side and a single person digging while others stand around on the other. The supplied answer identifies the joke as an exaggerated contrast between direct participation and bureaucracy; I find this understanding of the analogy especially impressive.
The examples also include converting an image of a table to CSV and interpreting a photograph of wood around a deck screw. In the latter, the model suggests the wood appears to be rotting and recommends replacing affected boards. The example illustrates an image-based suggestion, not a verified inspection or proof of the deck's condition.
A final coding example uses a screenshot of a programming problem asking for integer triplets, then asks for Python code. I think the response looks plausible, but I do not have an easy way to test it here and assume the example works. That is not a verified result of running the solution.
RealWorldQA and spatial understanding
He considers xAI’s new benchmark and reviews its spatial examples. His speculation about Tesla data remains unverified.
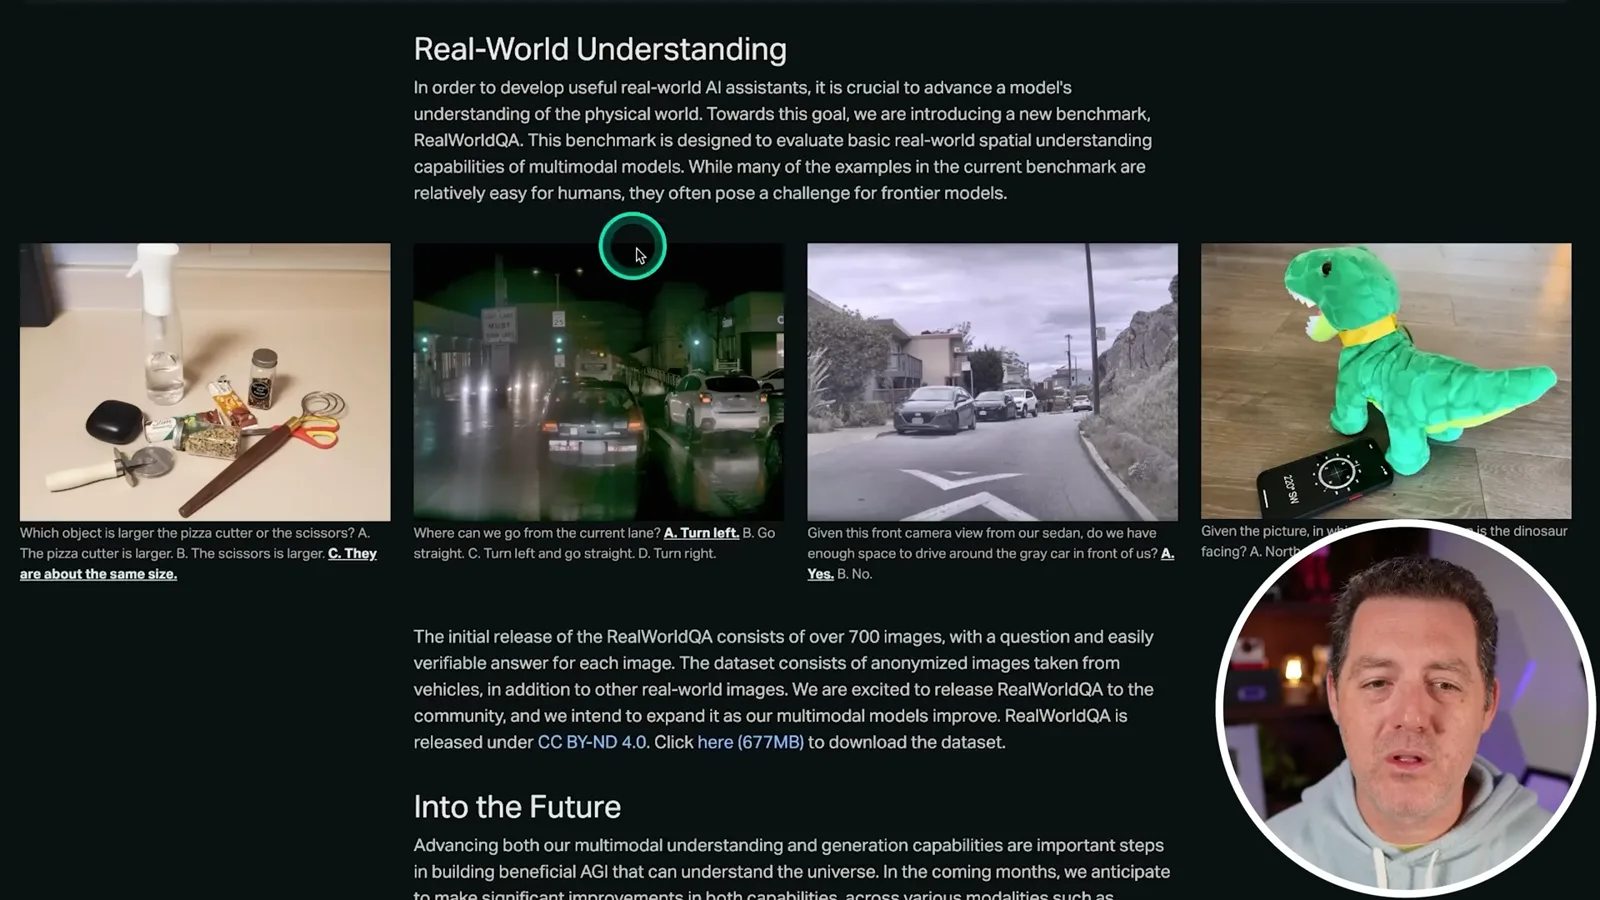
The other focus is RealWorldQA, which xAI says tests basic spatial understanding through real-world images and questions with verifiable answers. I speculate that Tesla data might help xAI's real-world understanding because some examples depict driving, and that X's text could also be useful. The announcement says the dataset includes anonymized vehicle images, but it does not identify Tesla as the source or confirm my speculation about training data.
In one example, the question asks whether a partially obscured pair of scissors or a pizza cutter is larger; the answer given is that they are about the same size. Another shows a left lane and a sign requiring traffic to turn left. The illustrated answer follows that sign and chooses a left turn.
A further driving image asks whether a sedan can go around a gray car; the displayed answer is yes. I find the apparent spatial reasoning impressive and connect it to my thoughts about driving systems, but a still-image example is not evidence that this model can safely drive a vehicle.
The last example asks which cardinal direction a toy dinosaur faces, using a phone compass in the image; the given answer is east. xAI says the initial RealWorldQA release contains more than 700 images, each with a question and an easily verifiable answer. I am eager to try the model myself and hope its weights are released, but those are expectations at the time of this 2024 preview.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.