In 30 seconds
Matthew Berman recounts his first CES in 2025, where NVIDIA invited him, paid for his hotel and gave him an RTX 5090 as part of its partnership on the video. He shows autonomous vehicles, robotics and NVIDIA demonstrations, then tests two DeepSeek R1 distills on a coding prompt. The 8B run displays about 79 tokens per second; his 40–50 token-per-second figure for the 32B model is an estimate. The short demonstration does not establish code correctness or guarantee privacy and security.
- 1CES and NVIDIA partnershipNVIDIA invited Berman, paid for his hotel and gave him an RTX 5090; he identifies NVIDIA as a partner on the video.
- 2Autonomous machinesHe visits John Deere farming equipment, a Waymo vehicle and Unitree robots.
- 33D-guided image generationA demonstrator uses a Blender scene and a text prompt to guide a generated image.
- 4Two local modelsBerman loads Q4-quantized 8B Llama and 32B Qwen DeepSeek R1 distills with full GPU offloading.
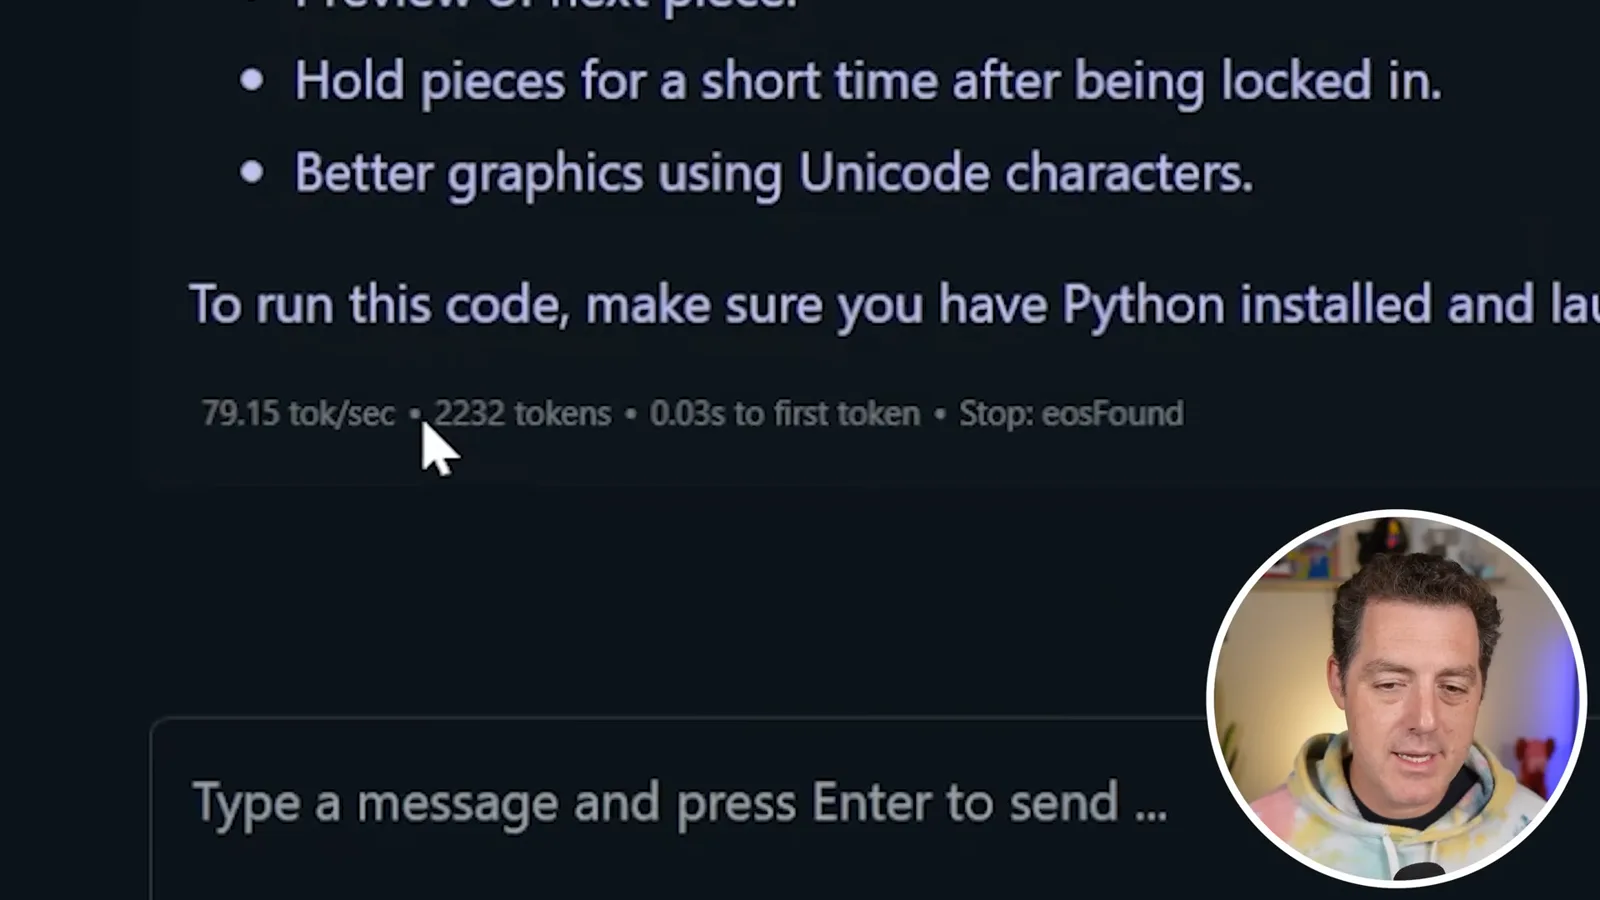
- 5Tetris promptThe 8B run displays 79.15 tokens per second. Berman estimates 40–50 tokens per second for the larger model.
Takeaways
- Berman saw autonomous farming equipment, self-driving vehicles and robots at CES 2025.
- NVIDIA showed a desktop assistant, 3D-guided image generation and an AI-character game demo.
- He ran Q4-quantized DeepSeek R1 distills based on Llama 8B and Qwen 32B on an RTX 5090 with 32 GB of VRAM.
- The displayed 8B response ran at 79.15 tokens per second on one prompt; the 32B speed was an estimate, not a measured result.
- Local inference can keep processing on the device, but privacy and security depend on the complete setup.
Read the edited text by chapter
CES 2025: vehicles and robots
Berman describes his NVIDIA invitation and tours autonomous farming machines, a Waymo car and Unitree robots.
This was my first CES, and I loved seeing so much technology centered on AI. NVIDIA invited me, paid for my hotel and gave me an RTX 5090, which I put in the machine beside me. NVIDIA partnered with me on this video. After a tour of the show, I will use the card to run DeepSeek R1 distilled reasoning models locally.
The giant farming equipment brought out the kid in me: the wheels on one dump truck were taller than I am. John Deere showed autonomous machines with arrays of cameras and sensors. I was excited to see AI being applied to farming, with NVIDIA technology powering the equipment.
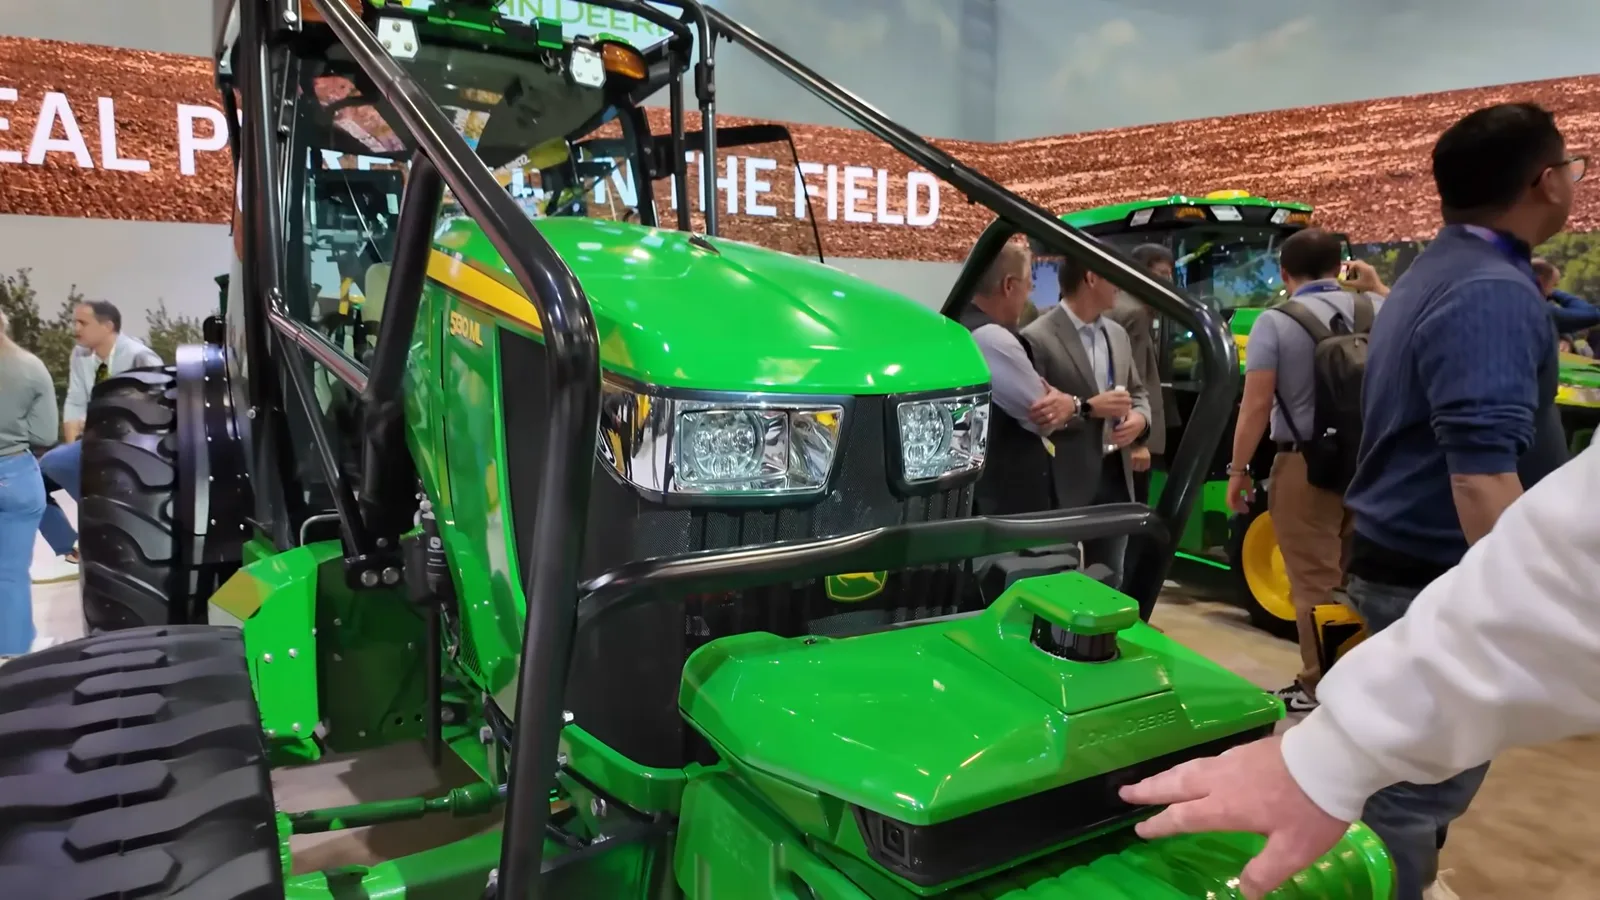
Autonomous vehicles had a large section of CES, including Waymo. I am from the Los Angeles suburbs, so I rarely see its cars at home, although I recently saw them everywhere in San Francisco. Unitree also showed quadruped and humanoid robots, and there were many other robots at the show.
At an NVIDIA editor day, around 100 to 200 invitees got a preview of new technology, including the RTX 5090. NVIDIA also showed Blueprints on build.nvidia.com: application frameworks developers can extend. I saw examples involving CrewAI and a NotebookLM-like application, with options for local execution and services such as ElevenLabs voice.
NVIDIA software and demonstrations
He discusses NVIDIA Blueprints and shows a desktop assistant, Blender image-generation workflow and AI-character game demo.
One demonstration showed a Windows assistant that can answer questions about the screen and perform computer actions. Asked what app was open, it identified Adobe Photoshop and an image called night market.PSD.
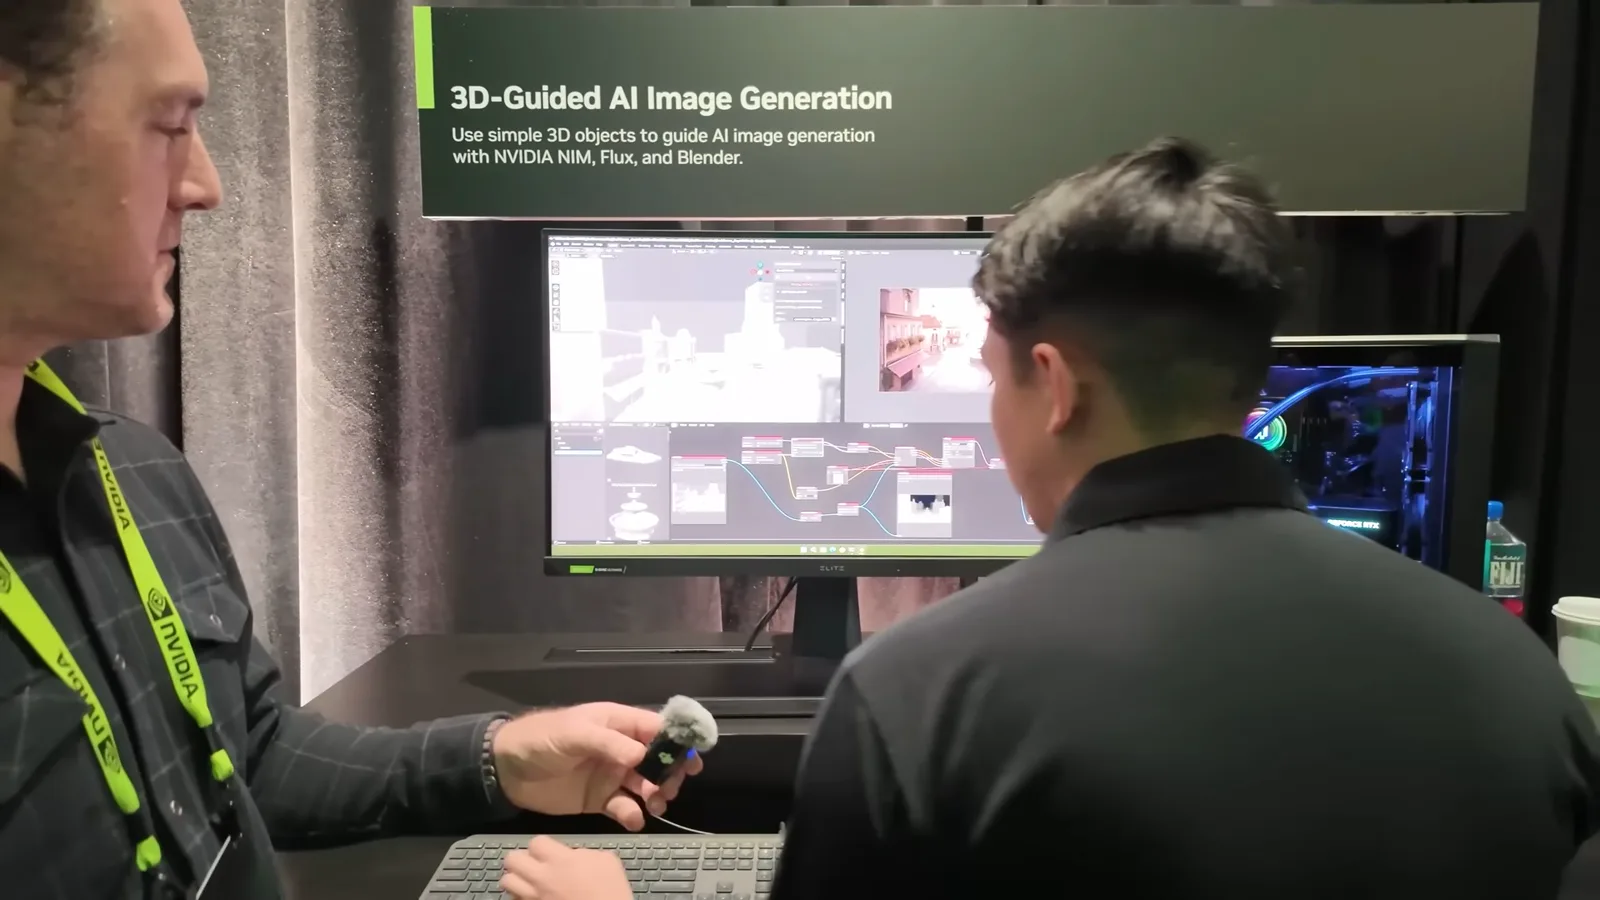
Another demonstration combined Blender and ComfyUI for 3D-guided image generation. A demonstrator explained that a simple scene could guide composition while a changed text prompt produced a different setting, such as the canals of Venice. That could let an artist explore a change in creative direction without rebuilding the composition.
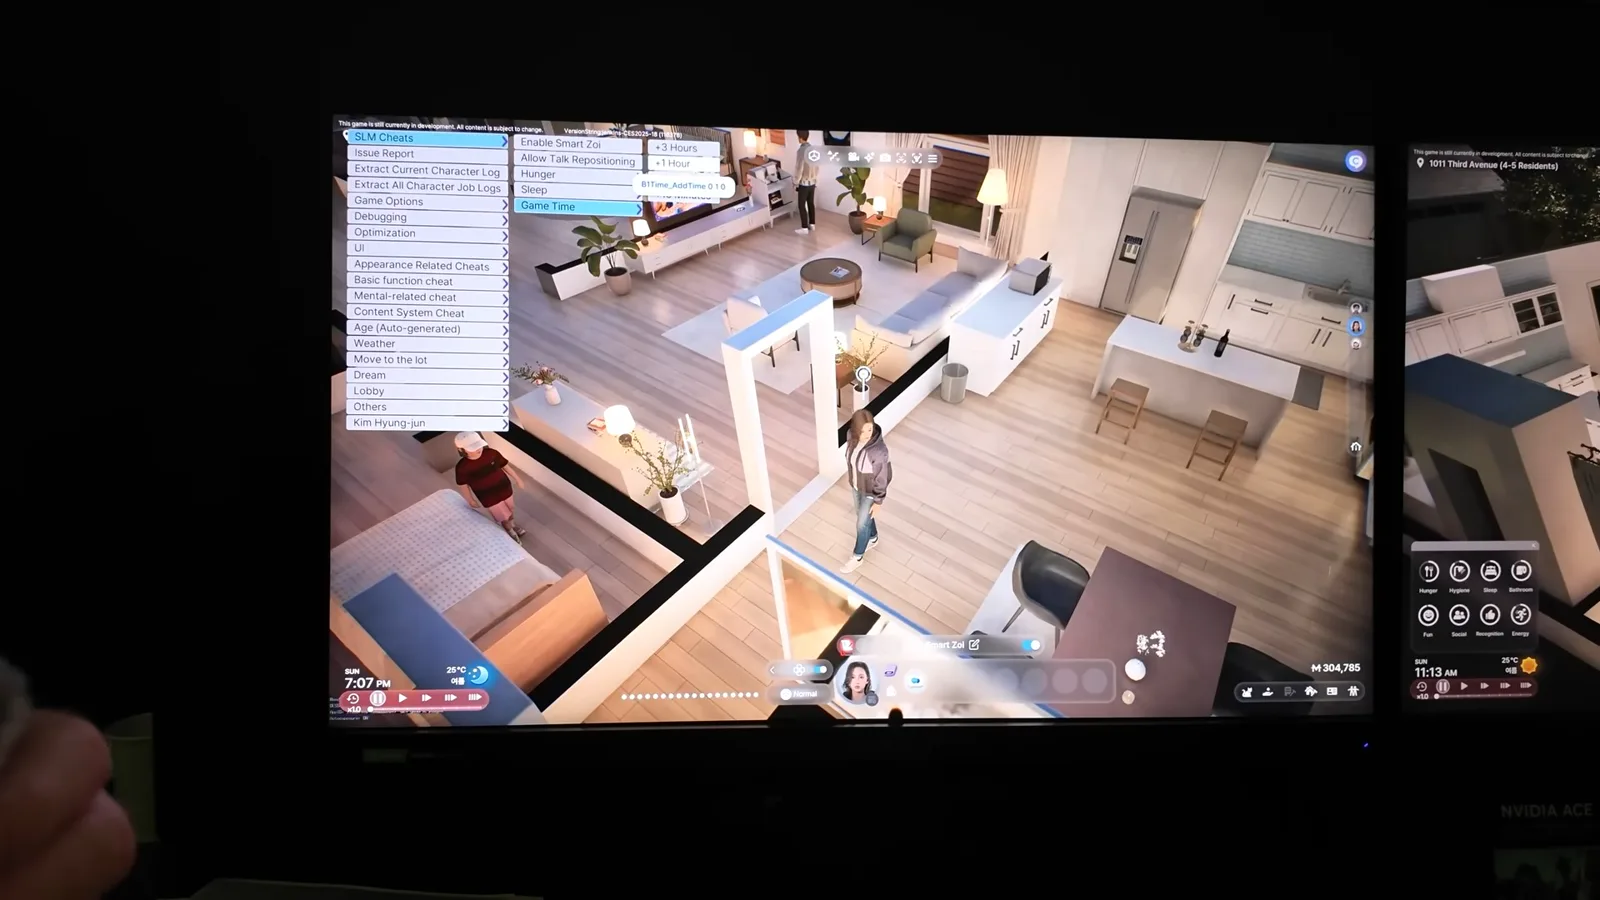
Another project reminded me of The Sims, with AI-driven characters living in a 3D world. It brought to mind an earlier research project about simulated humans. I was told the project could be downloaded and run locally.
Frame generation and the future of games
Berman shares his understanding of generated frames and predicts a more generative future for games. His prediction is speculative.
I also discuss my understanding that generative AI can produce additional frames between conventionally rendered frames on the RTX 5090. I am uncertain about the technical details. NVIDIA describes DLSS Multi Frame Generation as generating additional frames using AI; it is a frame-generation technique, not evidence that ray tracing itself is replaced.
I believe games and software could eventually become more predictive, with AI operating over a CRUD database rather than a conventional game engine. That is my prediction about a possible future, not a demonstration of that architecture at CES.
DeepSeek R1 distills on the RTX 5090
Berman runs two quantized models locally on the same Tetris prompt and discusses speed and local inference.
For the local test, the RTX 5090 has 32 GB of VRAM. I downloaded two GGUF models: DeepSeek-R1-Distill-Llama-8B at about 4.92 GB and DeepSeek-R1-Distill-Qwen-32B at about 18.71 GB. Both use Q4 quantization and, in my setup, are fully offloaded to the GPU.
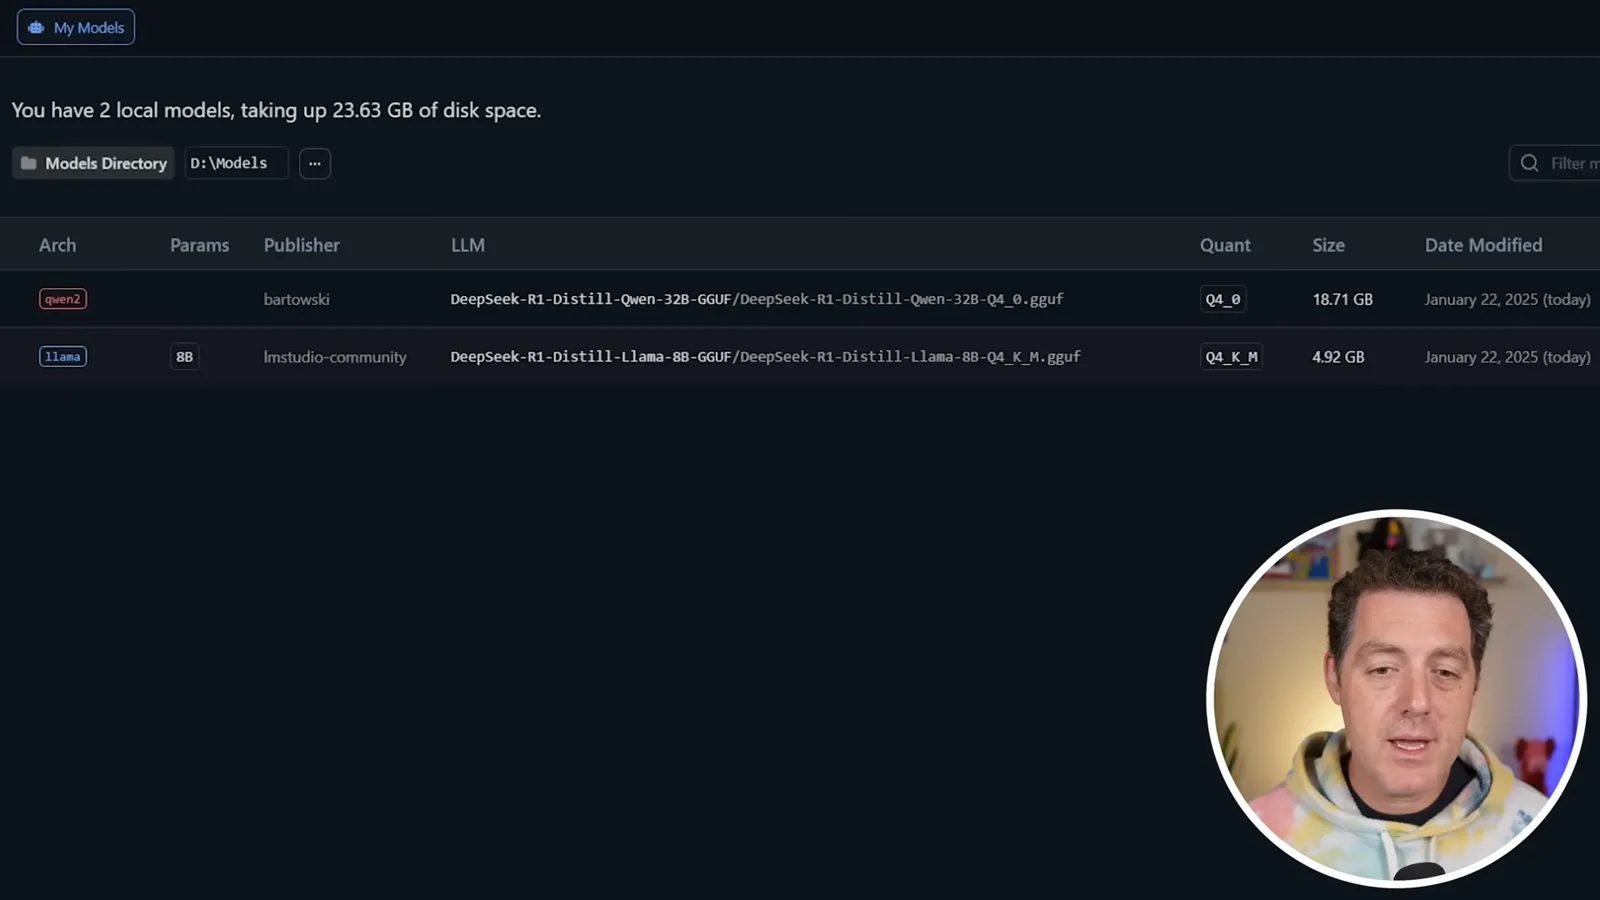
I ask the 8B model to write Tetris in Python. It reasons through the task before producing code. The displayed run reports 79.15 tokens per second, 2,232 tokens and 0.03 seconds to first token; I say I have seen as much as 90 tokens per second. I show the generated response, but do not run or validate the game in this demonstration.
I load the 32B Qwen distill and give it the same prompt. It is slower, and I estimate 40–50 tokens per second while watching it generate; that is not a displayed completed benchmark. I like being able to download and run models locally. Local processing can reduce reliance on a remote service, though privacy and security depend on the software, connections and configuration.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· Oct 21, 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.