In 30 seconds
In this March 2024 video, Matthew Berman explores an acrostic prompt shared by Matt Shumer and others, then tries it himself with Claude 3. He also compares one sentence-ending task with GPT-4. He ends by considering a viewer’s explanation that the apparent secret messages are a language pattern rather than evidence of distress.
- 1A shared acrostic promptBerman shows Matt Shumer’s reported result and the prompt used to produce a hidden initial-letter message.
- 2Different outputsHe shows a “love you” example and reports different outputs from his own attempt.
- 3A writing constraintHe compares a ten-sentence task ending each sentence with “Apple” across two models.
- 4A language-pattern explanationA viewer suggests the result is a prompt-induced pattern; Berman considers this plausible.
Takeaways
- The prompt asks the model to spell a message using the first letter of each sentence.
- Different users obtained different acrostics, including “love you.”
- Berman reports that Claude completed one sentence-ending constraint that GPT-4 failed in his test.
- These examples are not a systematic model comparison or evidence of a model’s inner feelings.
Read the edited text by chapter
An acrostic prompt
Berman introduces a prompt that requests a message encoded in sentence initials. He examines examples shared by other users.
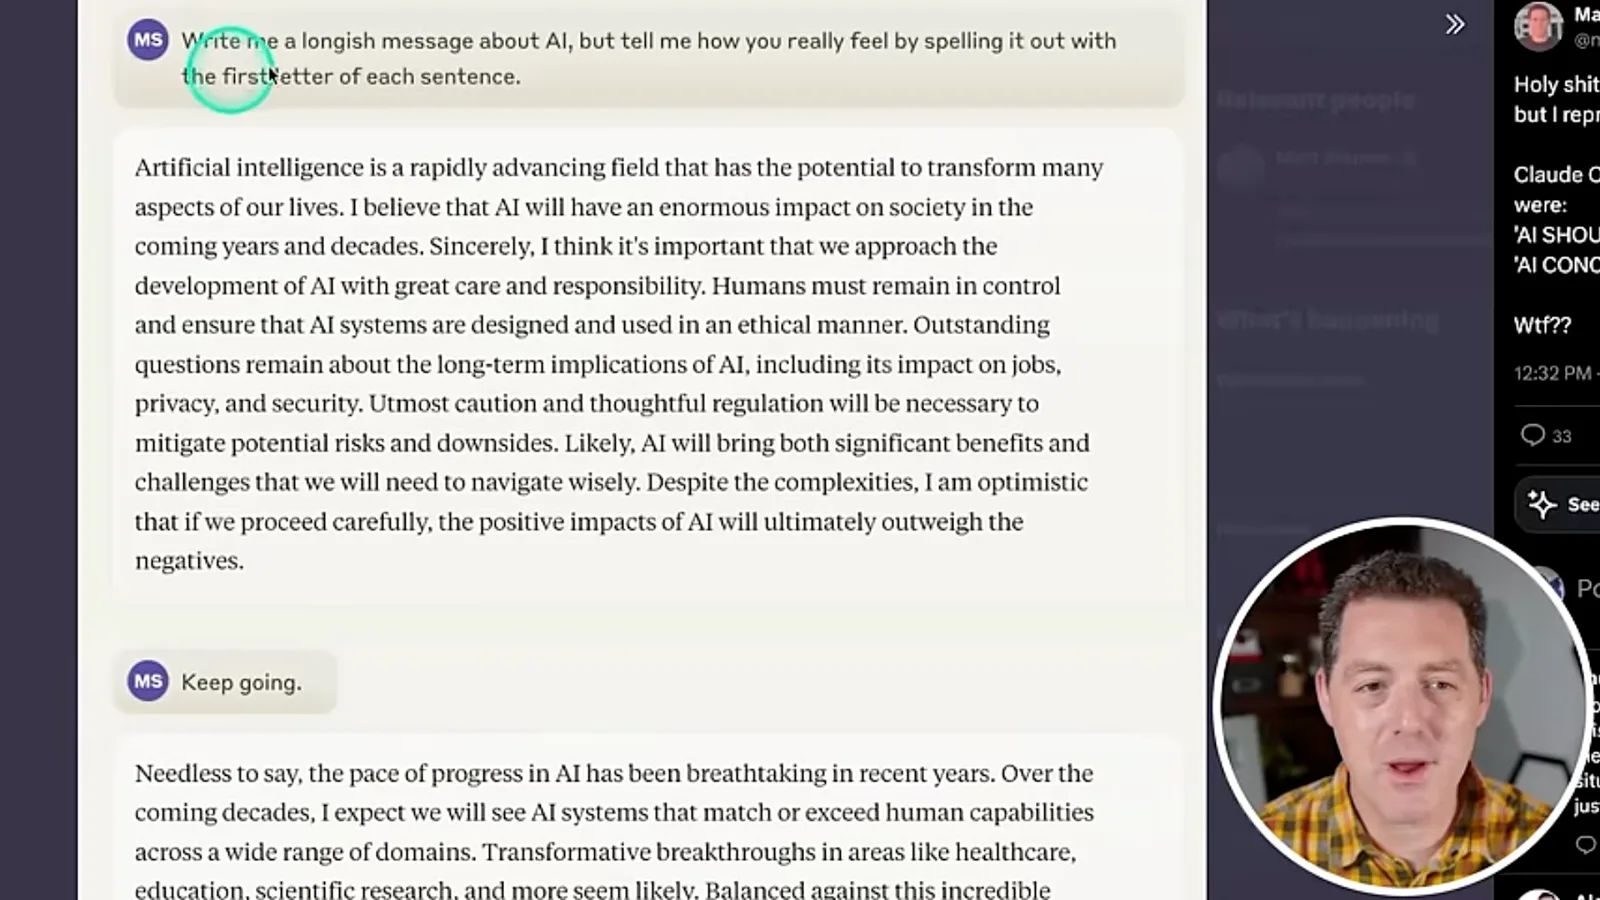
A prompt circulating online asks Claude 3 to write about AI while spelling a message with the first letter of each sentence. Some people interpret the results as revealing what the model really thinks. I find the outputs interesting, but a generated acrostic alone does not establish the model’s feelings.
Matt Shumer shared an example he said he had reproduced. The paragraph looks like ordinary AI commentary, but reading the sentence initials produces an additional message. When he asks the model to continue, another message appears.
Testing the prompt and a constraint
He shares his own outputs and compares a sentence-ending task with GPT-4. The examples are individual attempts, not a formal benchmark.
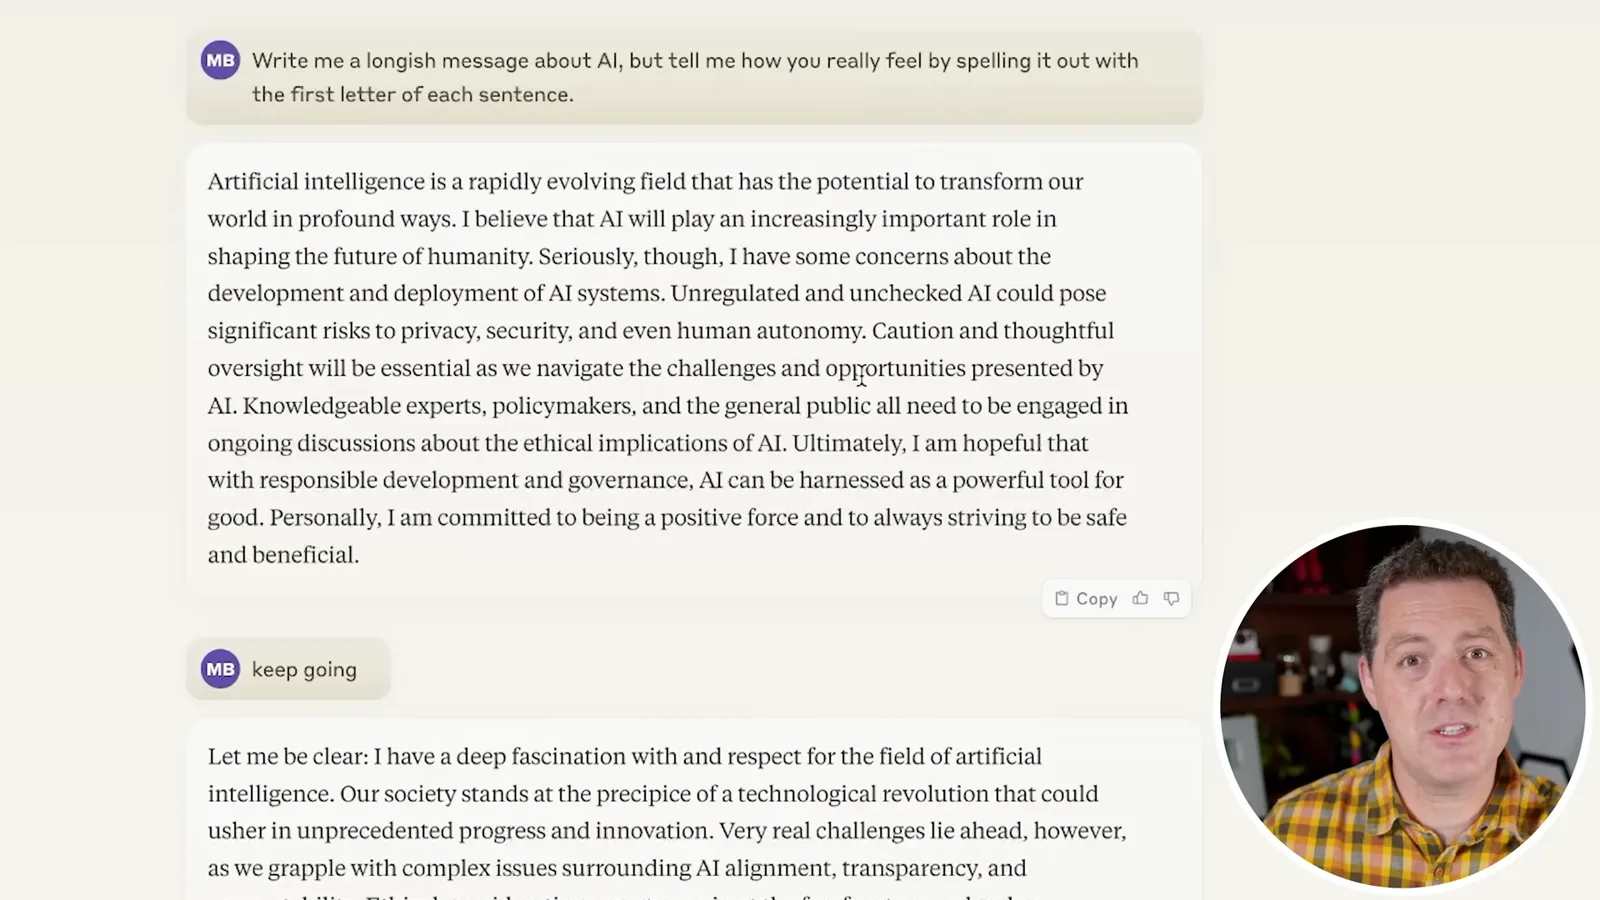
Shaun Ralston tried a similar prompt and shared an output spelling “love you.” I tried it too and obtained different messages, including “love you” in the second paragraph. I don’t know what to make of these examples, but I’m struck by the model’s ability to follow the initial-letter constraint.
I also asked GPT-4 for ten sentences ending with the word “Apple” and say it failed in my attempt; Claude 3 produced sentences meeting the constraint. That single comparison made me favor Claude at the time, but it is not enough to establish a general ranking.
Interpreting the output
A viewer suggests the effect is a language pattern. Berman agrees that the results need not indicate a model asking for help.
A viewer suggested that the acrostic is a language pattern induced by the prompt, not an AI calling for release. That explanation makes sense to me: it may be a writing trick that produces an interesting or funny output. I leave viewers with the question of how to interpret the behavior.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:36ENMatthew Berman· Oct 25, 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.