








Results
57 articlesSort
 1:05EN
 Matthew Berman· Sep 18, 2026NVIDIA PAIR Routes Local AI Requests Across ComputersMatthew Berman · Forward FutureMatthew Berman demonstrates NVIDIA's local-network router for distributing AI inference work among compatible machines.
 0:48ENMatthew Berman· Aug 25, 2026Matthew Berman on Earning From Idle Mac Compute With DarkbloomMatthew Berman · Forward FutureA proposed network of Apple Silicon Macs could serve AI inference, but the earnings shown are projections that depend on hardware, availability and demand.
 9:15ENMatthew Berman· Aug 17, 2026Six Open-Source Projects for Local AI, Agents, and 3D DesignMatthew Berman · Forward FutureMatthew Berman tours tools for running and training models, giving agents new skills, coordinating work, browsing, and generating 3D meshes.
 2:22ENMatthew Berman· May 29, 2026Pioneer Agent and Automated Fine-Tuning of Small ModelsMatthew Berman · Forward FutureIn a Fastino-sponsored video, Matthew Berman describes a system that automates parts of model adaptation and discusses its reported benchmark results.
 9:47ENMatthew Berman· Apr 3, 2026Gemma 4: Smaller Open-Weight Models for Local AIMatthew Berman · Forward FutureMatthew Berman reviews Google’s model sizes, multimodal features and reported benchmarks, with an eye toward local agents.
 1:09ENMatthew Berman· Mar 18, 2026The Benefits and Tradeoffs of Running AI Models LocallyMatthew Berman · Forward FutureMatthew Berman weighs the privacy, control and costs of local models against technical complexity and performance tradeoffs.
 1:02ENMatthew Berman· Mar 16, 2026Matthew Berman’s Plans for a GB300 AI Workstation at HomeMatthew Berman · Forward FutureAfter NVIDIA visits with a Dell Pro Max GB300 system, Berman describes his plans for local models, fine-tuning and future AI agents.
 0:45ENMatthew Berman· Mar 13, 2026A DGX Spark Giveaway Connected to NVIDIA GTCMatthew Berman · Forward FutureMatthew Berman announces a 2026 giveaway for a DGX Spark and highlights GTC sessions on robotics and AI.
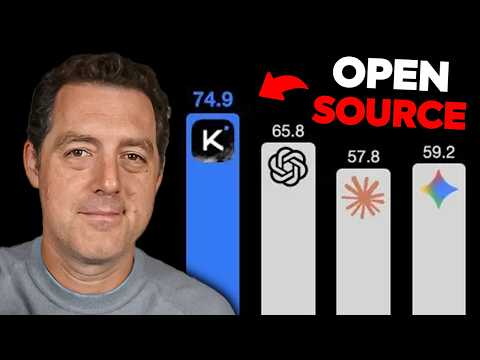 14:44ENMatthew Berman· Jan 27, 2026Kimi K2.5: Visual Coding, Agent Swarms, Benchmarks and Local DeploymentMatthew Berman · Forward FutureMatthew Berman examines Moonshot AI’s multimodal open-weight model, its parallel-agent demonstrations and the practical costs of running it.
 9:10ENMatthew Berman· May 15, 2025Guiding AI Image Generation with Blender and ComfyUIMatthew Berman · Forward FutureMatthew Berman walks through NVIDIA’s RTX blueprint for turning a simple Blender scene and a text prompt into a generated image, from installation to editing the result.
 1:14ENMatthew Berman· Mar 27, 2025NVIDIA NIM Microservices Bring Packaged AI Models to RTX PCsMatthew Berman · Forward FutureIn an NVIDIA-sponsored short, Matthew Berman introduces local AI microservices, compatible applications and the planned PDF-to-podcast workflow.
 12:30ENMatthew Berman· Mar 7, 2025QwQ-32B: A Smaller Reasoning Model and Its TradeoffsMatthew Berman · Forward FutureMatthew Berman examines Qwen’s reinforcement-learning recipe, tests a coding task, and compares benchmark scores and hardware requirements with DeepSeek-R1.
 6:50ENMatthew Berman· Feb 12, 2025DeepScaleR: A Small Reasoning Model Tested on Competition MathMatthew Berman · Forward FutureMatthew Berman reviews a 1.5B model’s reported benchmark results and runs a quantized version locally on one AIME problem.
 7:41ENMatthew Berman· Jan 30, 2025CES 2025 and Running DeepSeek R1 Distills on an RTX 5090Matthew Berman · Forward FutureMatthew Berman tours AI demonstrations at CES and runs two quantized DeepSeek R1 distilled models locally on an NVIDIA GPU.
 5:27ENMatthew Berman· Jan 29, 2025Ways to Try DeepSeek R1: Hosted and Local Distilled ModelsMatthew Berman · Forward FutureMatthew Berman demonstrates DeepSeek chat, Groq’s hosted distill and a local model in LM Studio.
 0:55ENMatthew Berman· Jan 23, 2025A Quick RTX 5090 Local AI TestMatthew Berman · Forward FutureMatthew Berman runs an 8B DeepSeek R1 distillation locally and reports the speed of one generation.
 8:52ENMatthew Berman· Jan 21, 2025Industry Reactions to DeepSeek R1’s 2025 ReleaseMatthew Berman · Forward FutureMatthew Berman reviews early reactions to DeepSeek R1, from open-weight reasoning models and local hardware to benchmark results and API pricing.
 1:03ENMatthew Berman· Nov 29, 2024AnythingLLM’s Community Hub and Local AI Agents on NVIDIA RTXMatthew Berman · Forward FutureIn a sponsored short, Matthew Berman introduces local agent workflows, shared prompts and integrations, with important limits on privacy and performance claims.
 1:00ENMatthew Berman· Nov 7, 2024Connect Obsidian to a Local AI Model with LM StudioMatthew Berman · Forward FutureMatthew Berman outlines a way to connect an Obsidian note-taking plugin to a model running on your own computer.
 0:28ENMatthew Berman· Nov 6, 2024Comparing Three Local Coding ModelsMatthew Berman · Forward FutureMatthew Berman introduces a sponsored comparison of DeepSeek Coder V2, Yi-Coder and Qwen Coder running on a workstation.
 12:50ENMatthew Berman· Nov 2, 2024Comparing Three Local Coding Models on Games and Programming ChallengesMatthew Berman · Forward FutureMatthew Berman runs DeepSeek-Coder-V2 Lite, Yi-Coder 9B, and Qwen2.5-Coder 7B on a sponsored workstation. Their results vary by task and include manual corrections.
 9:15ENMatthew Berman· Sep 25, 2024Llama 3.2 Adds Vision and Smaller On-Device ModelsMatthew Berman · Forward FutureIn a Meta-partnered 2024 video, Matthew Berman reviews the model family, its tooling and a brief hosted 1B demonstration.
 1:00ENMatthew Berman· Sep 5, 2024An ASUS ProArt Laptop with RTX 4070 for AI WorkloadsMatthew Berman · Forward FutureMatthew Berman describes a laptop sent by NVIDIA, a local Llama demonstration and RTX software features.
 0:58ENMatthew Berman· Aug 22, 2024NVIDIA ACE Brings AI Conversations to Game CharactersMatthew Berman · Forward FutureMatthew Berman explains how NVIDIA ACE combines speech, language models and facial animation, with Mecha BREAK as an early showcase.
Load moreShowing 24 of 57