 Matthew Bermanyesterday +1
 20VC with Harry Stebbingsyesterday +4
 No Priors: AI, Machine Learning, Tech, & Startupsyesterday +1
 Sequoia Capitalyesterday +6
 AI Engineeryesterday +1
 The Buildersyesterday +4
 Everyyesterday +1
 Uncapped with Jack Altmanyesterday +1
 Chris Williamsonyesterday +2
 Cheeky Pintyesterday +1
Results
146 articlesSort
 11:16EN
 AI Explained· Mar 25, 2025A 2025 Comparison of AI Image Generation and EditingSelected prompts test object counts, idioms, readable text, edits and visual puzzles.
 1:43:54EN
 Cognitive Revolution "How AI Changes Everything"· Mar 23, 2025PodcastA Year to Grow a Brain Organoid, an Hour to Simulate ItHost Nathan LabenzStanford postdoc Siyu He tells Nathan Labenz how Squidiff and CORAL move single-cell and spatial experiments into the computer — and where the models still cannot go.
 35:14ENNo Priors: AI, Machine Learning, Tech, & Startups· Mar 20, 2025Podcast · 2 speakersRobots Have No Wikipedia. Chelsea Finn Is Starting With Three Buildings.Host Sarah Guo, Elad GilPhysical Intelligence’s cofounder tells No Priors why a generalist robot model has to be trained across embodiments, why open-sourcing hardware is a bet against the problem going unsolved, and why humanoids are a little overrated.
 14:53ENMatthew Berman· Mar 20, 2025OpenAI’s 2025 Audio Models and Voice Agent ToolsMatthew Berman · Forward FutureMatthew Berman reviews a launch demonstration of transcription, controllable speech synthesis and agent tracing.
 0:48EN
 Google DeepMind· Mar 12, 2025Gemini Robotics Demonstration: A Whiteboard-Erasing RequestA short Google DeepMind clip shows a person asking an ALOHA 2 robot to erase a whiteboard.
 6:44ENMatthew Berman· Feb 1, 2025Testing DeepSeek Janus-Pro for Image Understanding and GenerationMatthew Berman · Forward FutureMatthew Berman tries the 7B multimodal model on diagrams, memes and image prompts using a sponsored cloud GPU demonstration.
 3:53:49ENCognitive Revolution "How AI Changes Everything"· Jan 3, 2025PodcastWith One-Twelfth the Data, an Open-Source Vision Model Beat GPT-4oHost Nathan LabenzWill Hardman of Veratai walks Nathan Labenz through two years of vision-language models, from ViT and CLIP to InternVL, BLINK, and Transfusion.
 27:07ENNo Priors: AI, Machine Learning, Tech, & Startups· Dec 26, 2024Podcast · 2 speakersAfter adding $100 billion a month, Jensen Huang says NVIDIA is selling the data centerHost Sarah Guo, Elad GilSarah Guo and Elad Gil clip their favorite 2024 No Priors conversations into a year-end reel of NVIDIA, Karpathy, Sierra, Sora, Waymo, Figma, and Scale.
 9:00ENMatthew Berman· Dec 20, 2024Best-of-N Jailbreaking: What Repeated Prompt Variations Revealed in 2024Matthew Berman · Forward FutureMatthew Berman reviews research on how repeated input variations can expose safety failures in text, vision and audio models.
 13:31ENMatthew Berman· Dec 19, 2024Google Veo 2: Cinematic Controls, Realistic Scenes and Motion LimitsMatthew Berman · Forward FutureMatthew Berman reviews Google’s 2024 video-generation examples, compares selected outputs with Sora and points out where movement or prompt adherence breaks down.
 1:07:32EN
 Unsupervised Learning: With Jacob Effron· Dec 18, 2024Podcasto1 Is a New Generation — and the Day AGI Arrives Will Feel BoringHost Jacob EffronOpenAI’s former chief research officer Bob McGrew on why o1 is a 100x leap, why agents stall on reliability, and why AGI may land as office tedium rather than a single dramatic moment.
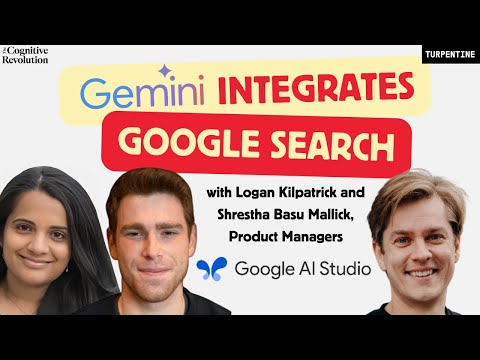 55:16ENCognitive Revolution "How AI Changes Everything"· Oct 31, 2024PodcastGemini’s API Grew 14× in Six Months. Google’s PMs Explain the Catch-Up.Host Nathan LabenzLogan Kilpatrick and Shrestha Basu Mallick walk through search grounding, Gemini Flash’s price-latency quadrant, and why a near-tied leaderboard still leaves Google third in most developers’ queues.
 12:29ENMatthew Berman· Oct 25, 2024Testing the Updated Claude 3.5 Sonnet: Coding, Reasoning and VisionMatthew Berman · Forward FutureMatthew Berman tries the October 2024 model on Python games, logic puzzles and images, with mixed results and some ambiguous grading.
 15:20ENMatthew Berman· Oct 24, 2024AI News: Copilot Agents, Claude Computer Use and New Generative MediaMatthew Berman · Forward FutureMatthew Berman surveys a crowded week of AI announcements in October 2024, from enterprise agents and open models to image, video and voice tools.
 54:45ENCognitive Revolution "How AI Changes Everything"· Oct 9, 2024PodcastA Few Megabytes of Doom and a Few Gigabytes of Model: Why Runway Bets on GeneralizationHost Nathan LabenzCTO Anastasis Germanidis tells The Cognitive Revolution why video is a fuller record of the world than text, why physics shows up without being programmed in, and how a small lab competes with unlimited compute.
 19:25ENMatthew Berman· Sep 26, 2024AI News in September 2024: Advanced Voice, Llama 3.2 and OrionMatthew Berman · Forward FutureMatthew Berman tests ChatGPT voice and reviews Meta’s models and AR prototype alongside a week of AI industry announcements.
 16:56ENAI Explained· Sep 25, 2024A 2024 AI Snapshot: Voice, Compute, Gemini and NotebookLMAI Explained examines proposed data-center capacity, model comparisons and generated audio in September 2024.
 9:15ENMatthew Berman· Sep 25, 2024Llama 3.2 Adds Vision and Smaller On-Device ModelsMatthew Berman · Forward FutureIn a Meta-partnered 2024 video, Matthew Berman reviews the model family, its tooling and a brief hosted 1B demonstration.
 11:14ENMatthew Berman· Sep 18, 2024Pixtral 12B: Testing a 2024 Vision-Language ModelMatthew Berman · Forward FutureMatthew Berman runs informal image, text and interface-generation tests of Mistral’s Pixtral on a sponsor-provided cloud GPU.
 0:58ENMatthew Berman· Aug 22, 2024NVIDIA ACE Brings AI Conversations to Game CharactersMatthew Berman · Forward FutureMatthew Berman explains how NVIDIA ACE combines speech, language models and facial animation, with Mecha BREAK as an early showcase.
 1:20:00ZH → English
 Zhang Xiaojun Podcast· Aug 17, 2024Podcast · 2 speakersYang Zhilin on Moonshot AI’s First Year, Long Context, and SoraGuest 杨植麟 · Host 张小珺In two early-2024 interviews, Yang Zhilin reviews Kimi’s technical choices and discusses AI organizations, user feedback, and multimodal research.
 24:18ENMatthew Berman· Aug 14, 2024Gemini Live and Pixel AI: Matthew Berman Reviews Google’s 2024 EventMatthew Berman · Matthew BermanA walkthrough of Google’s voice assistant and on-device AI demonstrations, including a live demo that needed several attempts.
 2:04:15ENCognitive Revolution "How AI Changes Everything"· Aug 14, 2024PodcastA parrot cannot paraphrase — and Claude cannot be talked into harmHost Nathan LabenzRobert Wright of the Nonzero podcast interviews Nathan Labenz on whether large language models understand anything, what Anthropic’s 10 million features actually show, and why open weights collide with U.S.–China policy.
 12:17ENMatthew Berman· Aug 7, 2024Testing Gemini 1.5 Pro on Code, Reasoning, Images and VideoMatthew Berman · Forward FutureMatthew Berman compares standard and experimental Gemini versions in an informal 2024 review, finding mixed results and repeated output errors.
Load moreShowing 24 of 146