In 30 seconds
Berman reacts to OpenAI’s March 2025 audio launch and compares direct speech-to-speech systems with a modular speech–text–speech chain. The presenters show transcription benchmarks, a text-to-speech interface, an order-support agent and audio tracing; the examples and product details are historical.
- 1Two voice architecturesThe launch compares direct speech-to-speech with a modular speech–text–speech chain.
- 2Transcription resultsOpenAI reports word error rates on the FLEURS dataset.
- 3Controllable speechThe team demonstrates instructions for how text should be spoken.
- 4Audio tracingThe interface shows audio events, metadata and timelines for debugging.
Takeaways
- Voice agents can use direct speech-to-speech models or a chain of transcription, text reasoning and speech synthesis.
- A modular chain can reuse text agents but may lose vocal cues in plain text.
- OpenAI presented transcription error rates on FLEURS; those figures are specific to the tested dataset.
- A text-to-speech instruction field can influence delivery in the demonstrated interface.
- Tracing audio, transcripts and tool calls can help inspect a voice agent’s behavior.
Read the edited text by chapter
Voice agents and architecture
Berman introduces the launch and compares direct speech interaction with a chained design. The OpenAI presenters explain the modular approach.
In March 2025 I react to an OpenAI livestream announcing audio models and developer tools for voice agents. I see voice as an important interface for AI, especially when a screen or keyboard is inconvenient.
The OpenAI team introduces two speech-to-text models, a new text-to-speech model with controllable delivery, and updates intended to help turn text agents into voice agents. The claims and product capabilities in this video reflect the launch period.
An OpenAI presenter describes a voice agent as an AI system acting for a user through speech, with examples including customer support and language-learning practice. I describe using voice interaction for quick questions while away from a screen.
The presenters distinguish speech-to-speech systems from a chained approach: speech is transcribed, a text agent processes it, and a text-to-speech model speaks the result. The two architectures expose different components and can support different workflows.
I favor direct speech interaction because spoken intonation, emphasis and other cues may be lost in a plain transcript. I also note that a chained system can add latency, though actual latency and fidelity depend on implementation rather than architecture alone.
The OpenAI team explains why developers may still prefer a chain: components are modular, they can choose models independently, and an existing text agent can gain audio input and output without being rebuilt from scratch.
Transcription and streaming
The team presents new transcription models, word-error comparisons and streaming features. Berman considers local alternatives and service costs.
The team introduces GPT-4o Transcribe and GPT-4o mini Transcribe. Its presenter says the larger model was trained on extensive audio data and that the smaller version was distilled for speed and efficiency; these are launch claims, not a measurement performed by me.
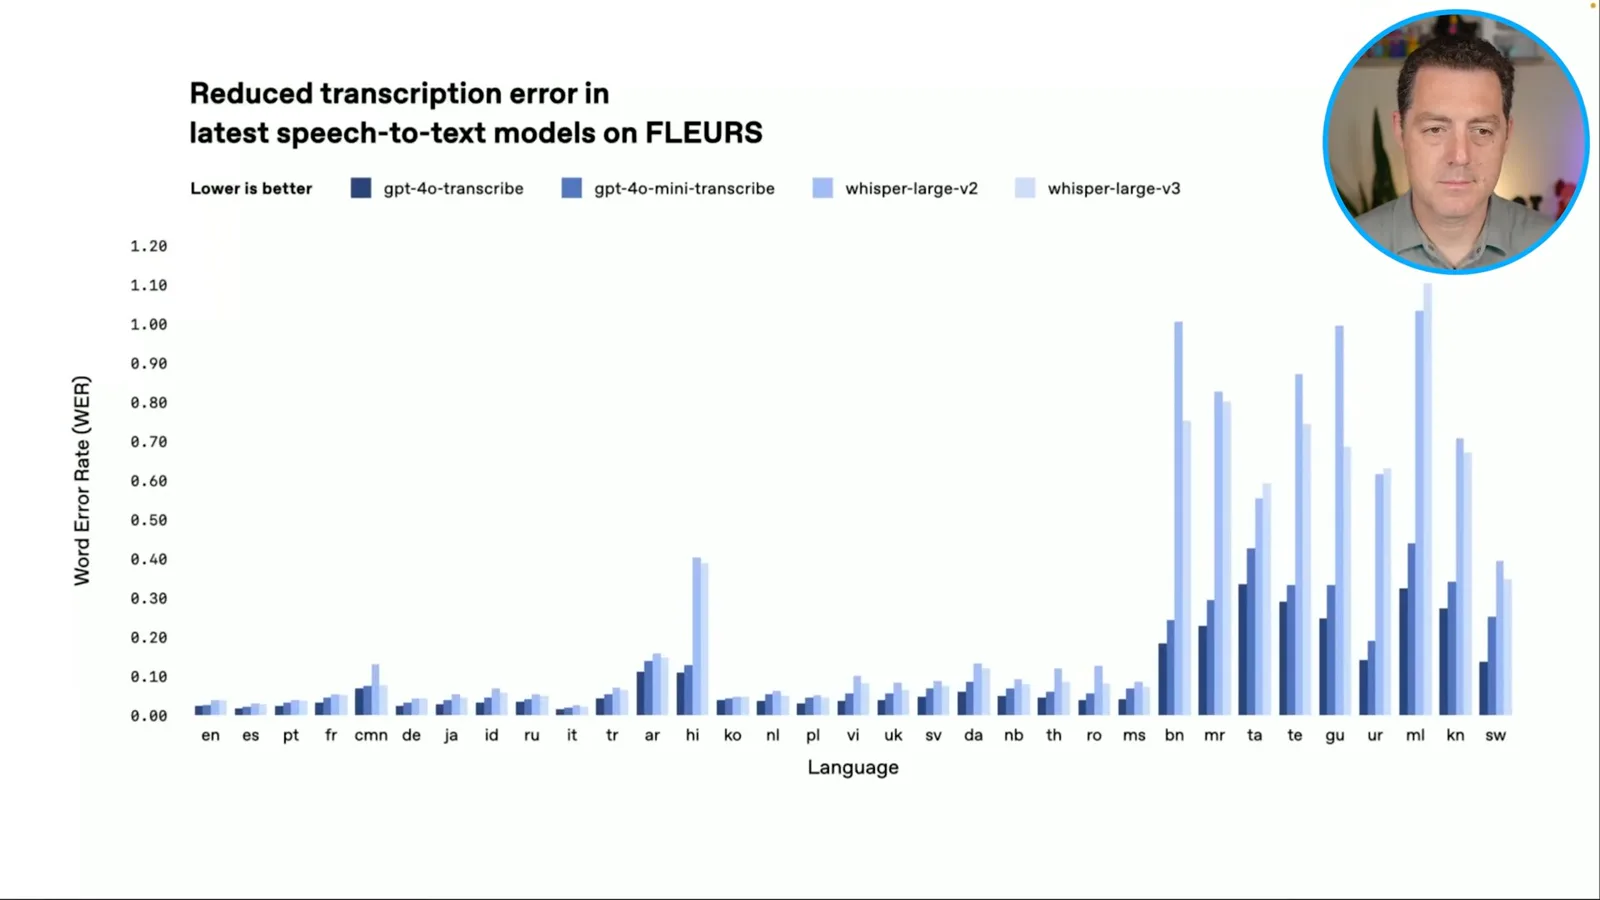
OpenAI shows word error rates across languages on the FLEURS dataset, comparing the new models with Whisper variants. Lower word error rate is better, but these company-presented results apply to that dataset and do not guarantee the same improvement for every recording.
I consider whether a locally run open-weight speech model might be preferable for some workloads. Local inference still requires hardware, energy and maintenance, while hosted APIs charge for service; the cheapest choice depends on usage and operational requirements.
The presenters discuss streaming transcription, noise cancellation and semantic voice activity detection. The latter is intended to help identify when a speaker has finished, so an application can respond without treating every short pause as the end of a thought.
Speech generation and agent tracing
OpenAI demonstrates delivery instructions, a customer-support agent and an audio-aware trace. Berman gives his early impressions.
OpenAI demonstrates GPT-4o mini TTS through OpenAI.fm, selecting a voice and providing instructions for tone and delivery. Different styles are demonstrated using the same text-to-speech interface; the video does not evaluate every voice or language.
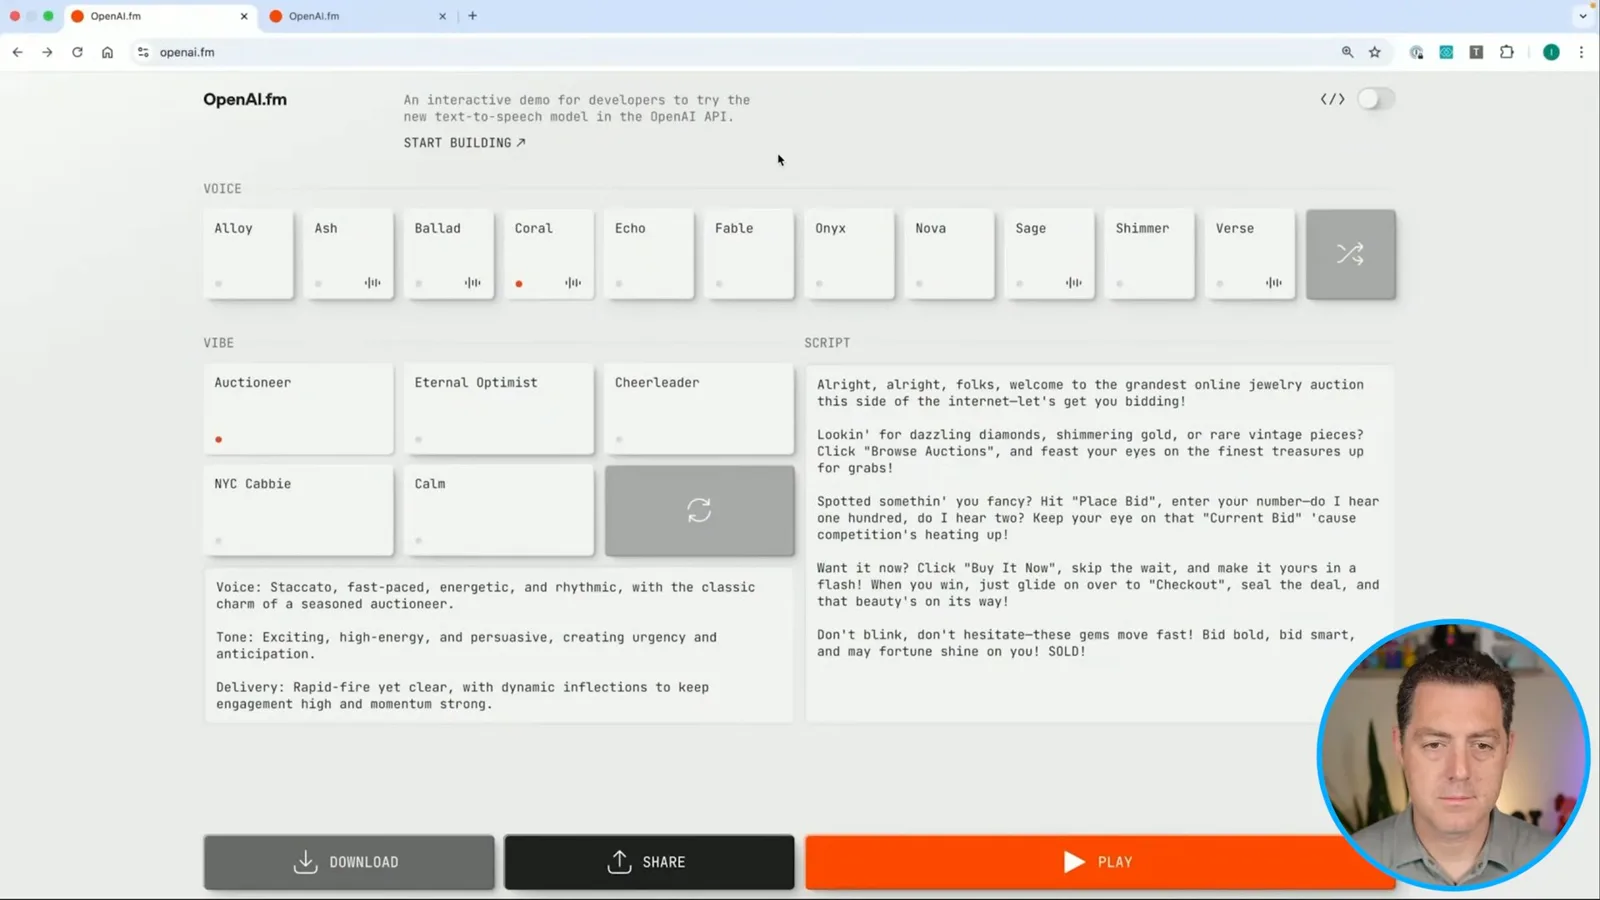
I remain interested in retaining tone, emotion and cadence when speech is converted to text. I suggest that an additional representation of delivery could be useful, while acknowledging that a simple transcript cannot capture every aspect of audio.
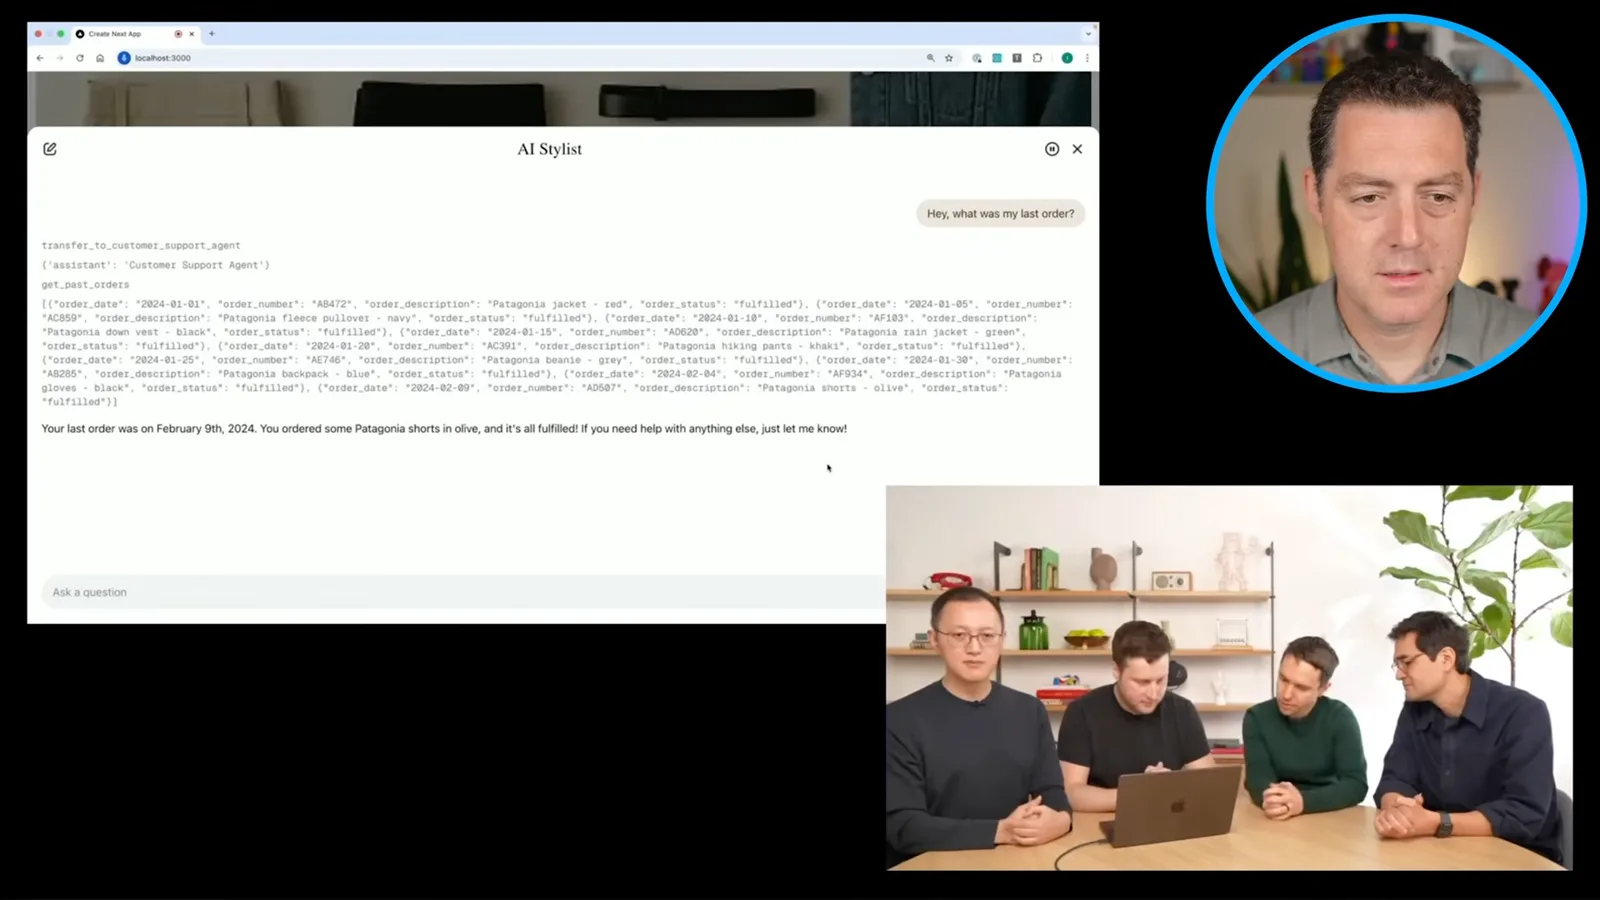
The team demonstrates a voice-enabled customer-support agent that calls tools to retrieve a recent order and answer a follow-up question. The example illustrates a workflow, not a guarantee that every order lookup or response will be correct.
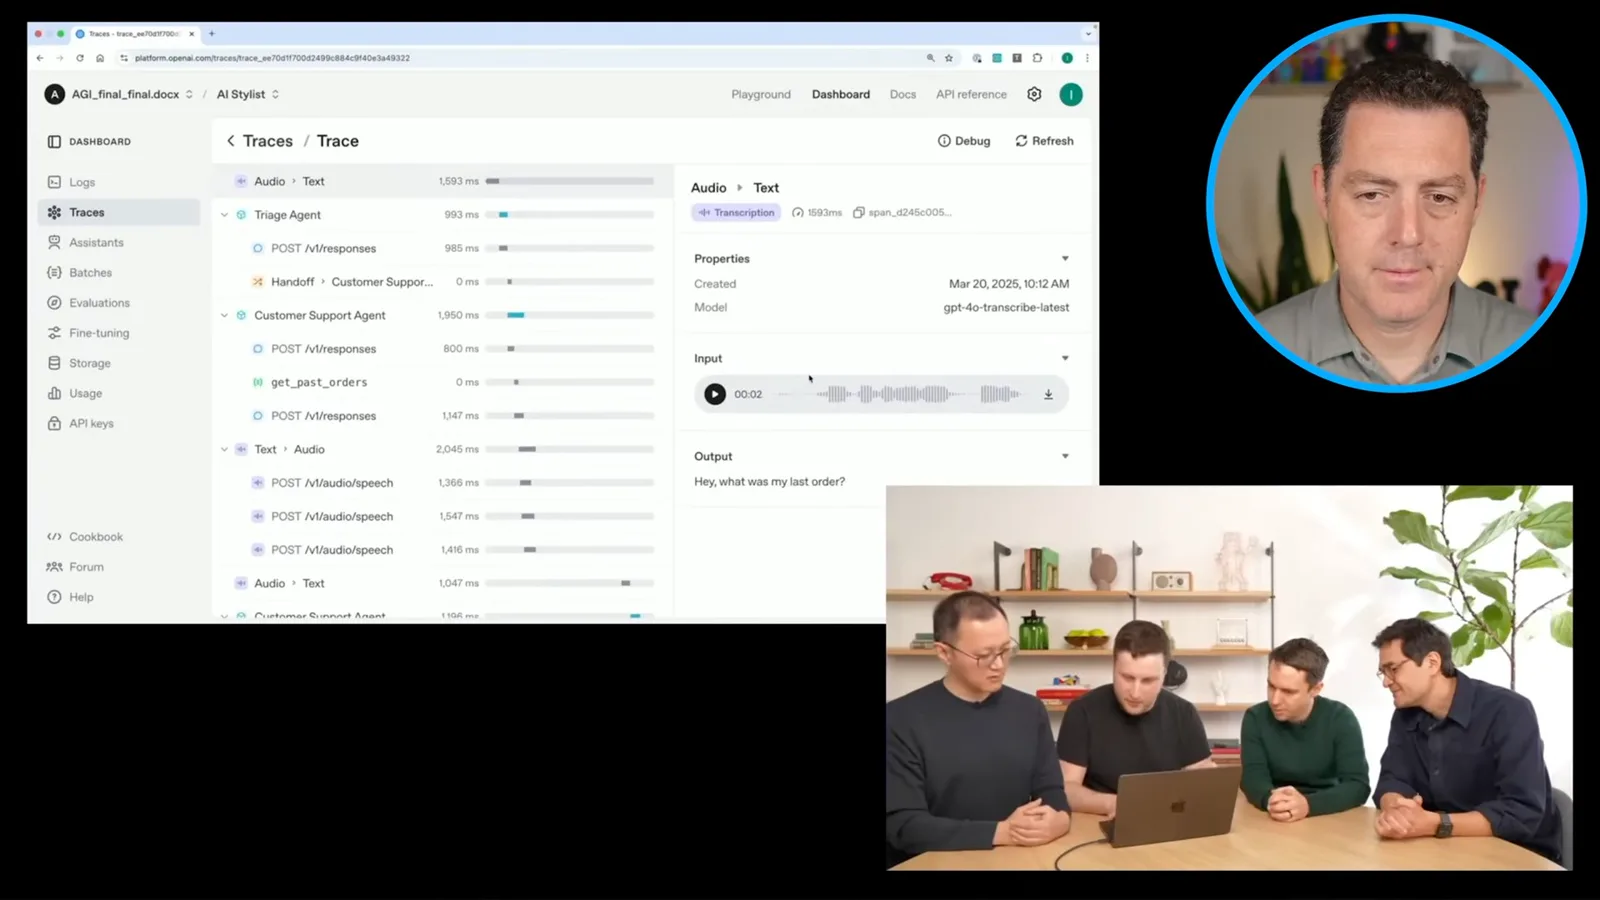
The presenters show a tracing interface with audio, transcript, metadata and timelines for the agent interaction. I like the ability to inspect and replay events as a debugging aid, although I have not yet tried the interface myself.
I conclude that the launch offers useful developer building blocks for voice applications. These demonstrations and pricing discussed in March 2025 should be understood as historical rather than current documentation.
More from this channel
 34:21EN
 Matthew Berman· Oct 27, 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 25:50ENMatthew Berman· Oct 24, 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· Oct 23, 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.
 1:03:37ENMatthew Berman· Oct 23, 2026Matthew Berman’s Team Tests Kimi K3.1 on Animation, Games, and ChartsMatthew Berman, Alex, Brian · Forward FutureA live team AMA turns into an informal test of Kimi K3.1, from personal-agent workflows to motion graphics, a browser game, and a benchmark chart.
 0:53ENMatthew Berman· Oct 22, 2026Sam Altman on AI and the Discovery of New KnowledgeSam Altman · OpenAIAltman expects progress in mathematical discovery to extend to biology, materials and energy.
 0:22ENMatthew Berman· Oct 21, 2026A Robot Bodyguard Video Shows Dramatic Rescue ScenariosMatthew Berman · Forward FutureMatthew Berman reacts to a short robot demonstration depicting fighting and vehicle-rescue scenarios.