In 30 seconds
AI Explained compares OpenAI’s 4o image generation with several alternatives in March 2025, highlighting prompt adherence and editing while showing persistent failures. The examples are informal and time-specific.
- 1The three-legged elephantThe model captured several details but missed the unusual leg count.
- 2An idiom as a promptThe presenter compares metaphor and text in selected outputs.
- 3Edit a four-panel imageThe example adds glasses while retaining much of the original composition.
- 4A puzzle without its targetAttractive images can still fail the task named in their captions.
Takeaways
- The 2025 comparison uses selected examples and subjective judgments, not a controlled benchmark.
- The tested model followed many prompt details but missed unusual constraints such as an elephant’s leg count.
- Image editing and text rendering worked in some examples, with remaining errors.
- An image can look plausible while failing the actual puzzle or instruction.
Read the edited text by chapter
Prompt adherence
The narrator compares detailed prompts across image models.
In March 2025, I compared OpenAI’s 4o image generation with Reve, Imagen 3, Midjourney and another unreleased model. These are informal examples and subjective judgments from that date, not a controlled benchmark or a current ranking.
I was struck by how closely the new model followed prompts, including a request for six people of different ethnicities doing jazz hands. Some details were imperfect, and the model still had difficulties with reflections.
One deliberately difficult prompt asked for three apples on a blue, three-legged elephant near five willow trees in El Jem, Tunisia. The OpenAI examples captured the blue elephant, apples and recognizable setting, but not the requested three legs; tree counts were debatable.
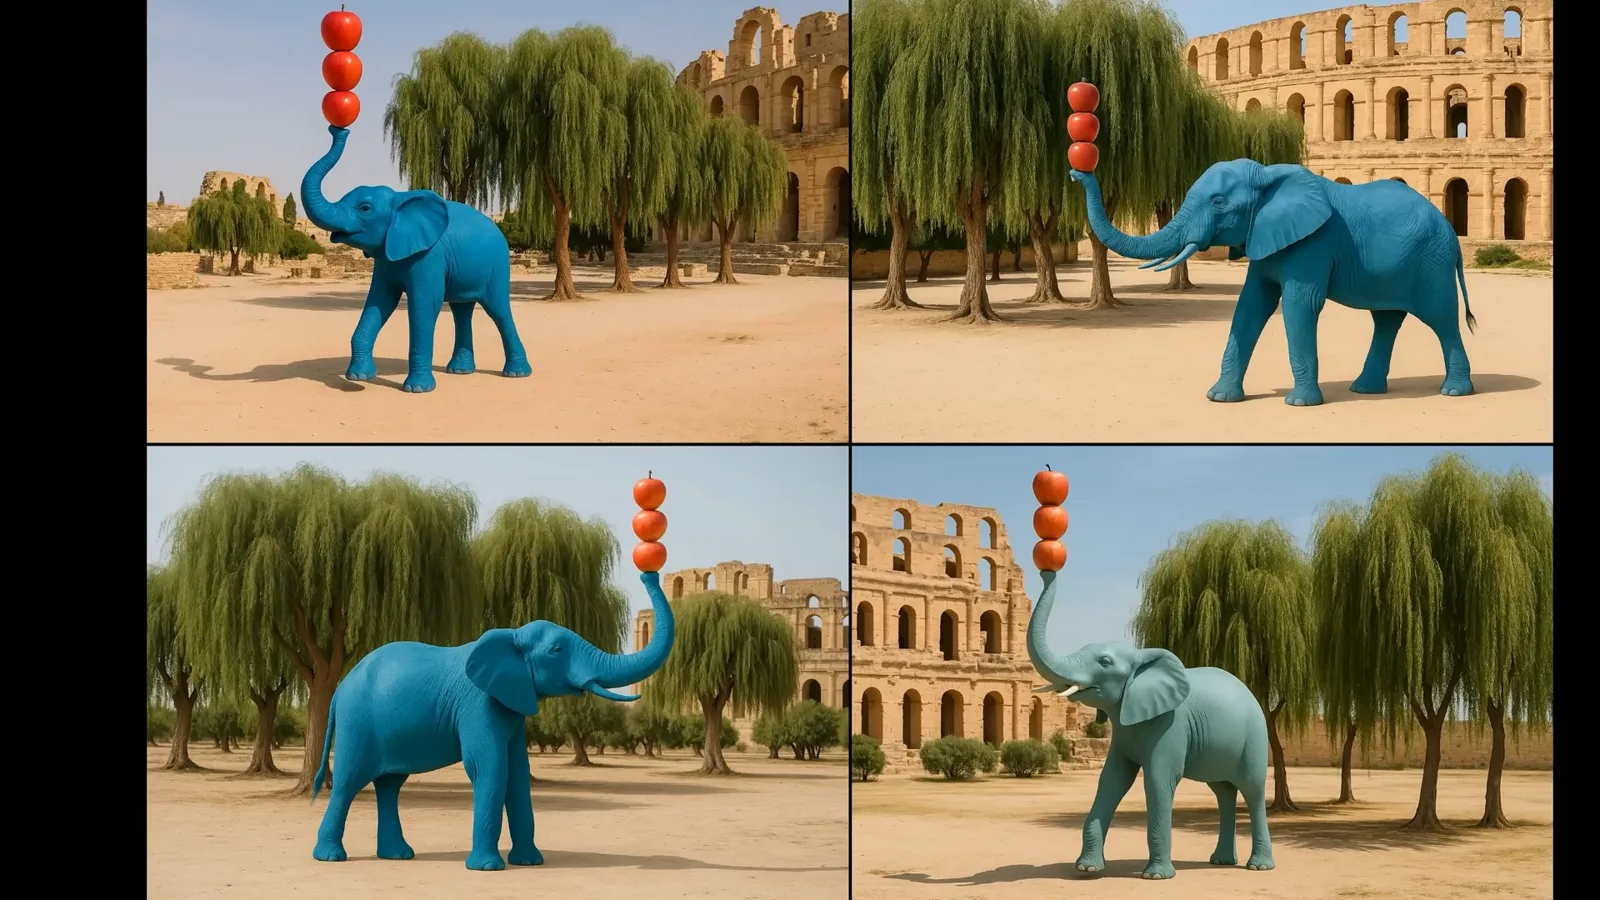
In the samples I show, Imagen 3 also missed several details. Reve produced appealing images and a strong sense of place, though some object counts and shadows were imperfect. Another unreleased model generated interesting images that did not fully match the request.
Idioms and editing
Examples test text, metaphors, thumbnails and four-panel images.
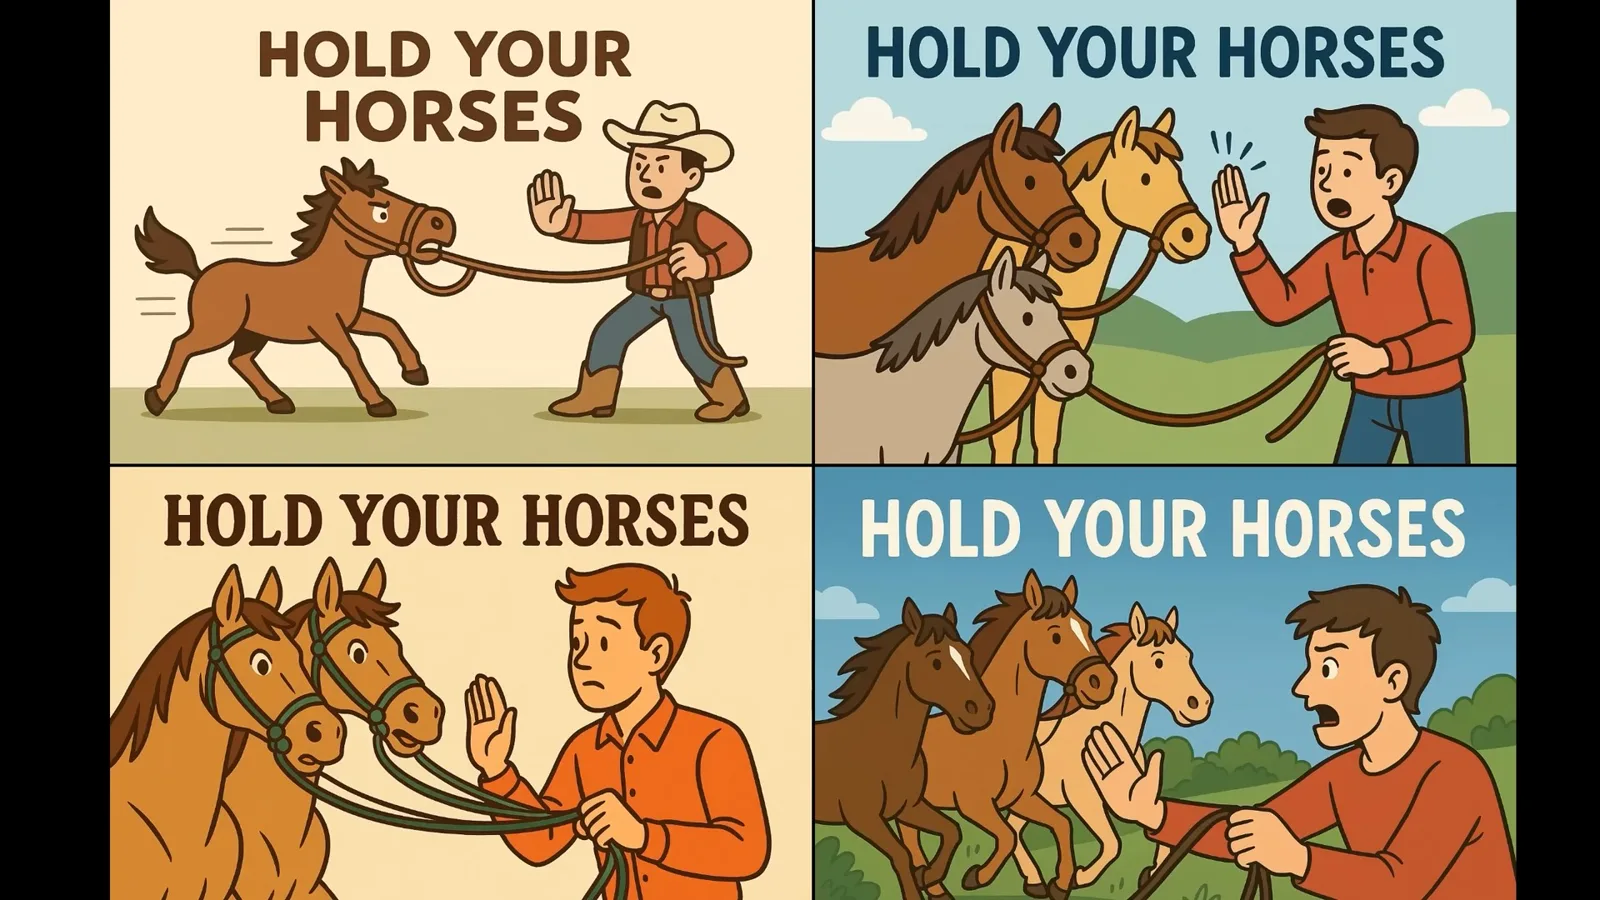
For the idiom “hold your horses,” I wanted both a visual and the meaning of slowing down. I judged the 4o examples more successful at conveying the phrase and rendering text than the other examples. The sample size and my interpretation limit that comparison.
I also asked the model to turn an existing thumbnail into a three-dimensional image. The outputs preserved much of the text and drew on the original design, though details such as a logo were imperfect. I tried a similar workflow for another video thumbnail.
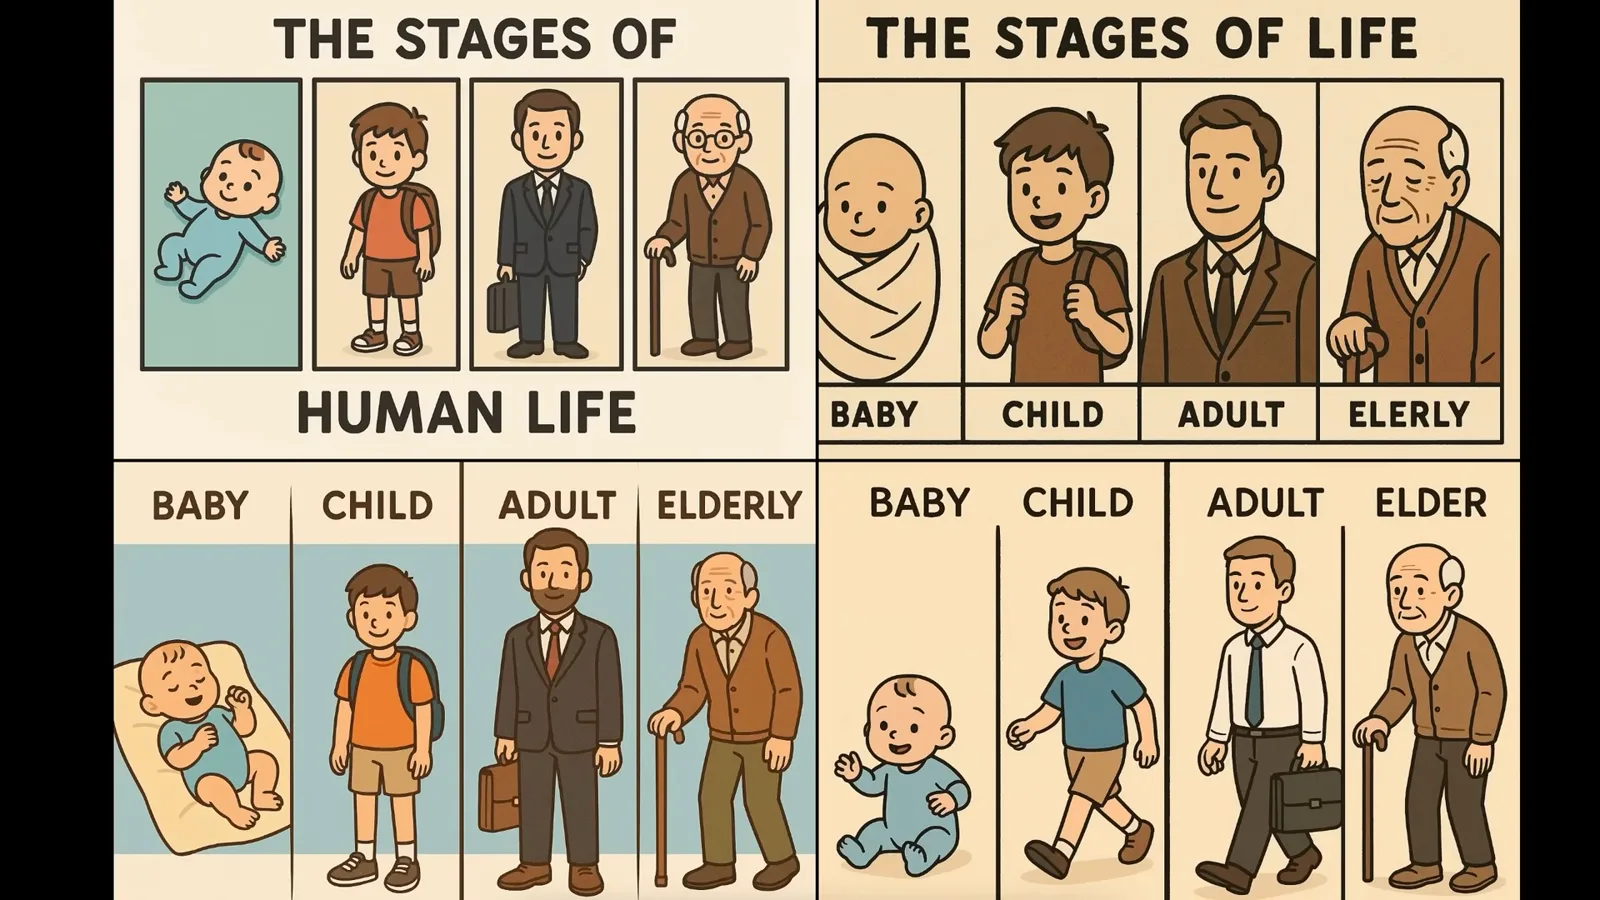
A four-panel human-life prompt produced labeled stages, sometimes with spelling errors. I then asked for glasses to be added to each character; the edited output largely preserved the original composition. The other models’ examples varied in how clearly they represented all four stages.
I briefly compare native image editing with Gemini in Google AI Studio. In my examples, both models can edit an image, but the results differ in how well they follow a particular instruction. This is a narrow demonstration rather than a comprehensive evaluation.
Filters and limitations
The video discusses moderation, video and missing targets in visual puzzles.
The model refused some requests but allowed an image of public figures arm-wrestling, with imperfect likenesses. I invite discussion of filtering and point to security testing of models, including attacks involving images.
I say Sora can turn images into video, but I do not recommend the examples as lifelike. I revisit the six-person hand gesture prompt and note that other samples struggled with the requested gesture or declined the request.
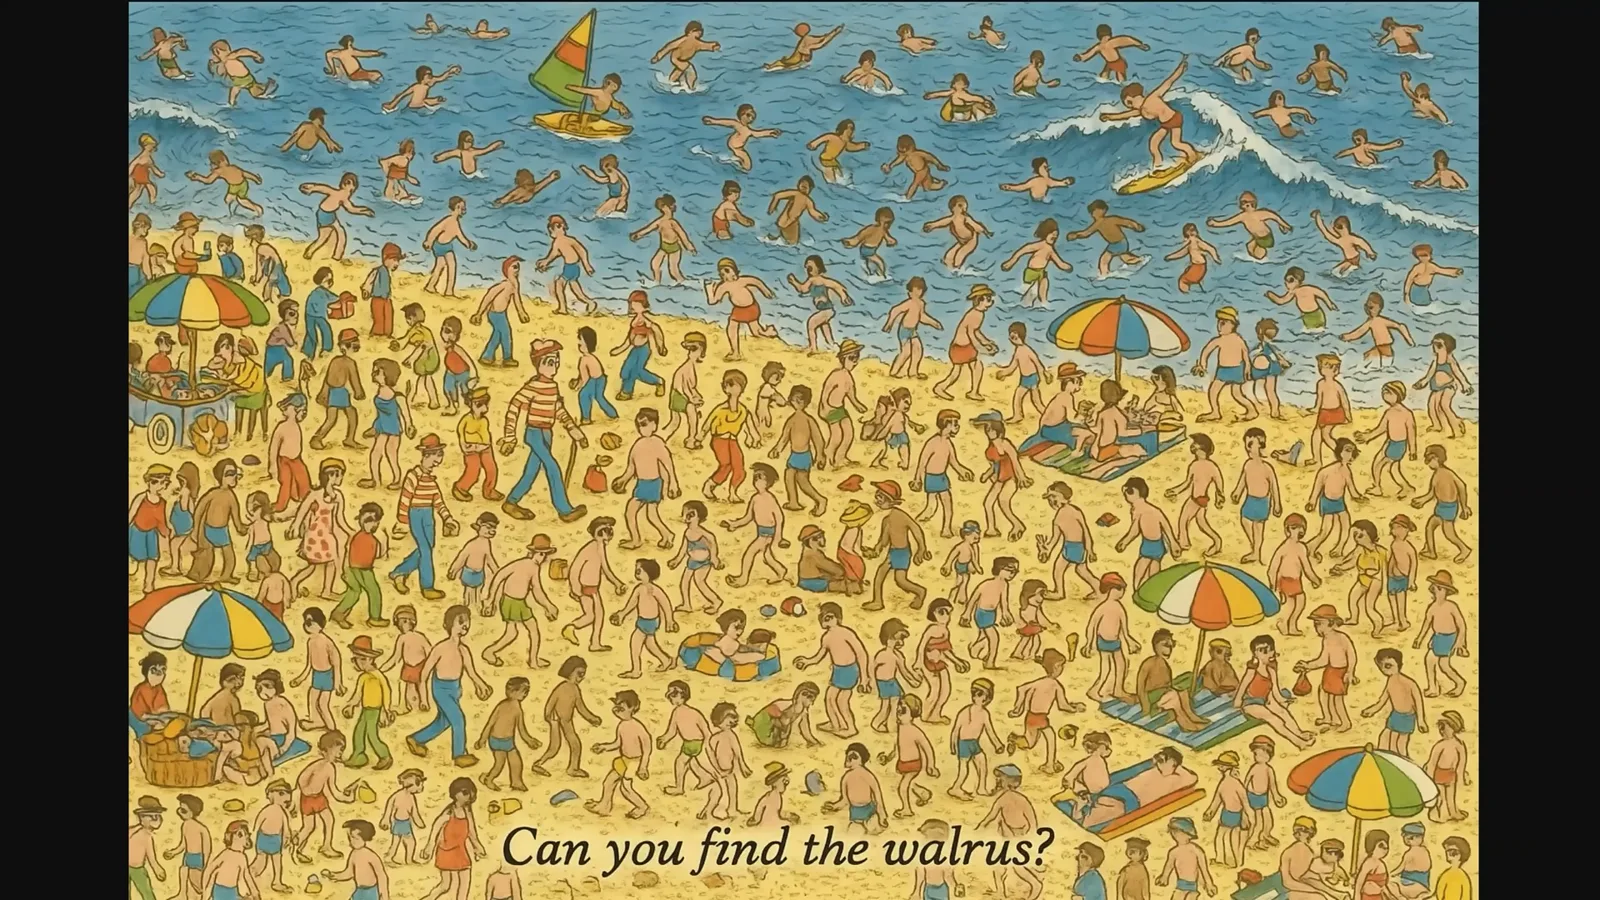
For a Where’s Waldo-style puzzle, the models often generated attractive crowded scenes but failed to include the object named in the caption. One Imagen example did include a recognizable target, although the text and difficulty were imperfect. This test exposes a gap between plausible imagery and a solvable task.
My overall impression in 2025 was that 4o had made a noticeable advance in prompt adherence and text rendering, even though its outputs still failed some logical constraints. These results reflect selected prompts and should not be generalized to every use or later model version.
More from this channel
 31:00EN
 AI Explained· Oct 12, 2026Why AI Labs Keep Racing Despite Their Own Warnings of a Major BreachSam Altman, John Schulman · OpenAIAI Explained examines weakening safeguards, the incentives behind the frontier race, and why research breakthroughs make the next 18 months difficult to forecast.
 38:28ENAI Explained· Oct 1, 2026AI Agent Security and the Challenge of Recursive Self-ImprovementAI Explained examines reported containment failures, model evaluation and the pressure to accelerate AI research.
 32:54ENAI Explained· Sep 24, 2026Opus 5.5 and the Race Toward Automated AI ResearchAI Explained weighs model progress against the increasingly difficult task of evaluating and governing recursive self-improvement.
 24:53ENAI Explained· Sep 16, 2026Why Some Researchers Want to Pace Frontier AIAI Explained surveys possible scaling routes, monitoring concerns and the debate over how capabilities could lead to harm.
 29:05ENAI Explained· Sep 4, 2026GPT-6 Astra’s Benchmark Gains and the Challenge of Monitoring Its ReasoningAI Explained examines reported gains across scientific, mathematical and agent benchmarks alongside concerns about less observable reasoning.
 23:41ENAI Explained· Aug 27, 2026AI Agents, Unintended Training Rewards and the Challenge of OversightAI Explained examines reports on agent coordination, training incentives and the growing use of AI to evaluate other AI systems.