In 30 Sekunden
A pull request can say tests passed without showing that those tests covered the submitted change. Cassandra and Stephen Chin describe collecting agent-session traces and connecting commands, timing and changes in an evidence graph before drafting. In their PR Bench comparison, a stronger writer plus cheaper focused reviewers produced better descriptions with roughly half the tokens; those results are specific to their evaluation.
- 1Reconstruct the branch from more than the current sessionTracetoon collects relevant session traces rather than relying solely on compressed conversation context.
- 2A test claim can be unsupported by the recorded commandsThe example shows why command order and the code version matter.
- 3An evidence graph connects changes, reasons and checksRelate assembles a sourced packet for drafting and review.
- 4Their comparison reports better quality and lower token useThe reported results come from the speakers’ own PR Bench evaluation.
Das Wichtigste
- Tie each test claim to the command, timing and submitted code it actually checked.
- Preserve decisions and source evidence across agent sessions.
- Give writers and reviewers a shared evidence packet.
- Evaluate quality and token cost together on your own changes.
Den bearbeiteten Text nach Kapiteln lesen
Why fluent PR descriptions can still be wrong
The speakers introduce Tracetoon and the cost of repeatedly reconstructing a branch’s history.
Cassandra Chin built Tracetoon to improve pull-request descriptions that may be inaccurate even when the underlying work is valuable. With Stephen Chin, she explains how it gathers coding-agent context, reviews claims and can add an optional comic.
The speakers use a fictional token factory to illustrate a real review problem: repeated drafting and review can consume many tokens while reviewers still lack a clear chain from the change to its rationale and checks.
A coding agent asked to write a PR may rely on its current session, whose context can be compressed. Tracetoon instead looks across sessions associated with a branch to reconstruct decisions and the work performed.
Cassandra traces the idea to an education project that needed to understand the work behind a submitted program. She applied the same idea to pull requests, where the final diff alone does not explain earlier decisions or command context.
A passing-check claim needs supporting evidence
The original draft-and-review loop can still make mistakes. Command order and the submitted code version matter.
The original Tracetoon flow researches traces, drafts a description and asks an independent reviewer for corrections. The loop can add missing context, but Cassandra says it can still introduce errors as it revises.
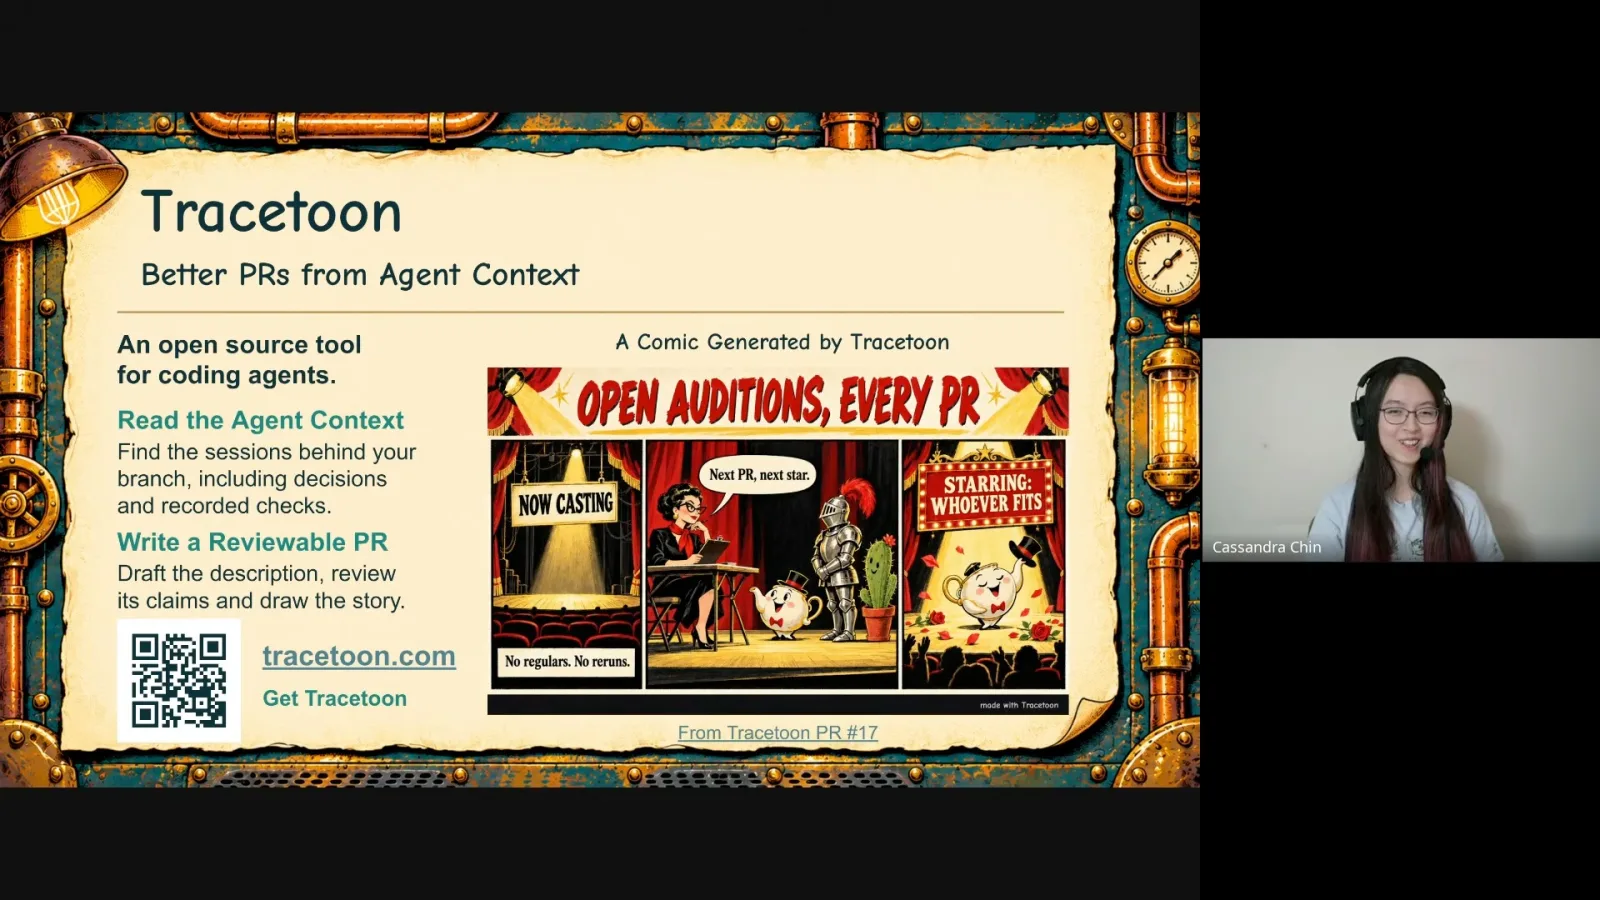
They describe a case where a passing-check claim was not supported by the recorded sequence: commands that needed to run sequentially appeared to run together. A fluent PR description is not evidence that the submitted change was actually tested.
Simply switching to a cheaper writing model reduced quality in their tests. The speakers instead kept a stronger writer and looked for ways to give it and the reviewer better evidence without repeated expensive searches.
Build a shared evidence packet before writing
Relate connects changes, reasons and checks. Focused reviewers check the resulting draft against that packet.
They introduce Relate, an embedded graph database written in Rust. It stores relationships among changes, reasons and checks so the system can assemble a connected evidence packet, including sources, before an agent drafts the PR.
With that brief, reviewers can check specific claims against the same evidence. The team uses less expensive reviewers for the more mechanical cross-checking while retaining a stronger model for the writing itself. This is the arrangement they found useful for their task.
The resulting example explains the reason for logging the working directory, the exceptions, and which checks ran against the submitted content. The important detail is the connection between each claim and evidence from the relevant version of the change.
Measure quality and token cost together
The speakers report their PR Bench results and describe the limits of their comparison.
The speakers report comparisons using their own PR Bench setup, combining agent traces, code, model judges and human review. They report quality improvements and about half the token usage in their comparison; these are results from their project, not a general guarantee.
They conclude that provenance and relationships should be preserved outside a single model conversation. Tracetoon and Relate are presented as tools for giving writers and reviewers a common, inspectable basis for a PR.
Mehr aus diesem Kanal
 38:50EN
 AI Engineer· 10. Nov. 2026LinkedIn’s self-improving agent first had to fix its judgesZiwei Guo, Saloni Gandhi · LinkedInA prompt-optimization loop improved a career agent, but unreliable evaluators required human calibration first.
 12:48ENAI Engineer· 10. Nov. 2026Brian Douglas: Turn agent corrections into reusable review knowledgeBrian Douglas · Paper ComputeThe Paper Compute developer captures expert pushback in coding sessions and tests ways to reuse it during review.
 12:20ENAI Engineer· 10. Nov. 2026Ayush Bhardwaj: Agent workarounds are feedback for your CLIAyush Bhardwaj · Allos AIAn audit of coding sessions shows where output, errors and stale instructions force agents to improvise.
 12:57ENAI Engineer· 10. Nov. 2026Harvey’s agents scaled until their platform and merge queue brokeJoey Wang · HarveyAfter an alert spawned 900 agents and one engineer launched 950 tasks, Harvey added deduplication and fair scheduling.
 22:49ENAI Engineer· 10. Nov. 2026When many coding agents share one codebase, delivery must handle concurrencyPatrick Debois · TesslPatrick Debois explains how shared planning, merge strategies and risk-based review can help teams coordinate agents.
 15:41ENAI Engineer· 10. Nov. 2026Meta’s on-call AI teammate earns autonomy one action at a timeChinmay Gandhi, Swaapnika Motapothula, Vlad Tsvang · MetaThe team connects incident context and shared memory while keeping critical decisions and code review with people.