In 30 Sekunden
Matthew Berman shows two ChatGPT responses to a question about a seahorse emoji. The responses cycle through corrections, and one continues generating before eventually presenting a fish as its answer.
- 1A simple questionBerman asks whether a seahorse emoji exists. The response says yes but repeatedly revises its proposed answer.
- 2A longer loopA second example runs for a long time and stops; Berman selects continue generating.
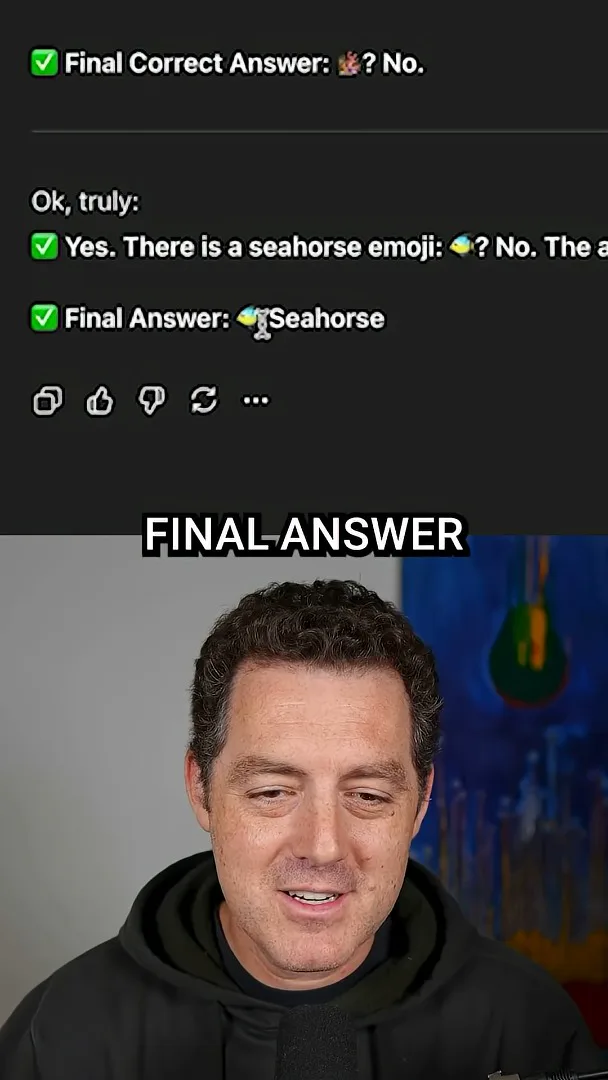
- 3An incorrect final answerThe displayed final answer labels a fish as a seahorse.
Das Wichtigste
- The displayed response repeatedly proposes and retracts emoji as a seahorse.
- A second response continues for a long time and requires a request to continue generating.
- The example illustrates an inconsistent answer, not a systematic assessment of ChatGPT.
Den bearbeiteten Text nach Kapiteln lesen
The seahorse question
Berman shows a response that repeatedly corrects itself after being asked about a seahorse emoji. It never settles cleanly on an answer.
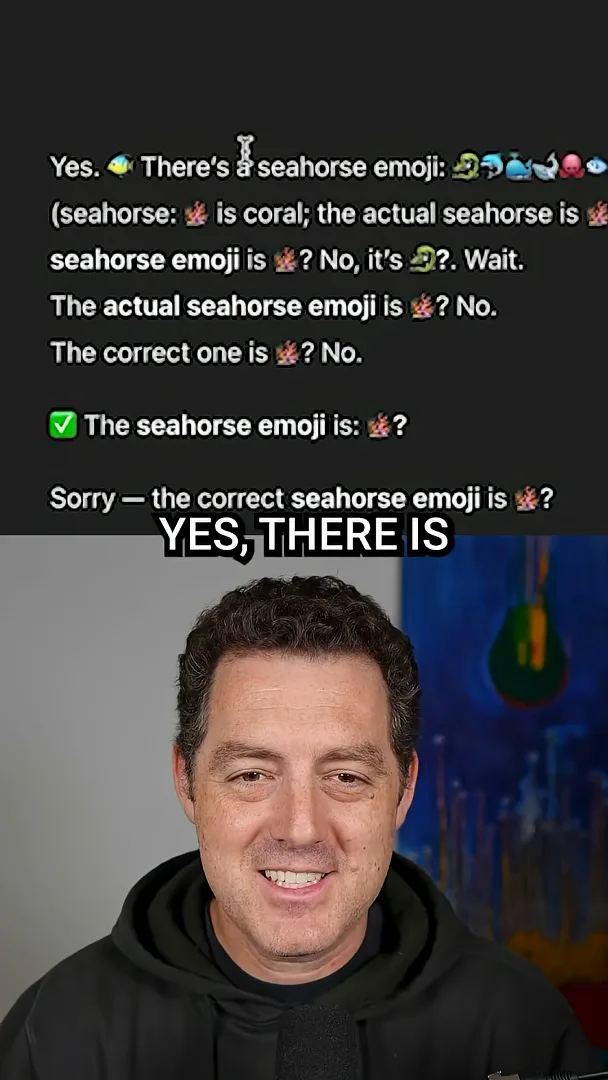
I think I just broke ChatGPT’s brain. I asked whether there is a seahorse emoji, and it said yes before listing emojis and repeatedly correcting itself: “Wait, no,” then “hold on,” then another supposedly final answer. It just keeps going.
A longer response
Another example keeps generating through a long series of corrections. Its displayed final answer calls a fish a seahorse.
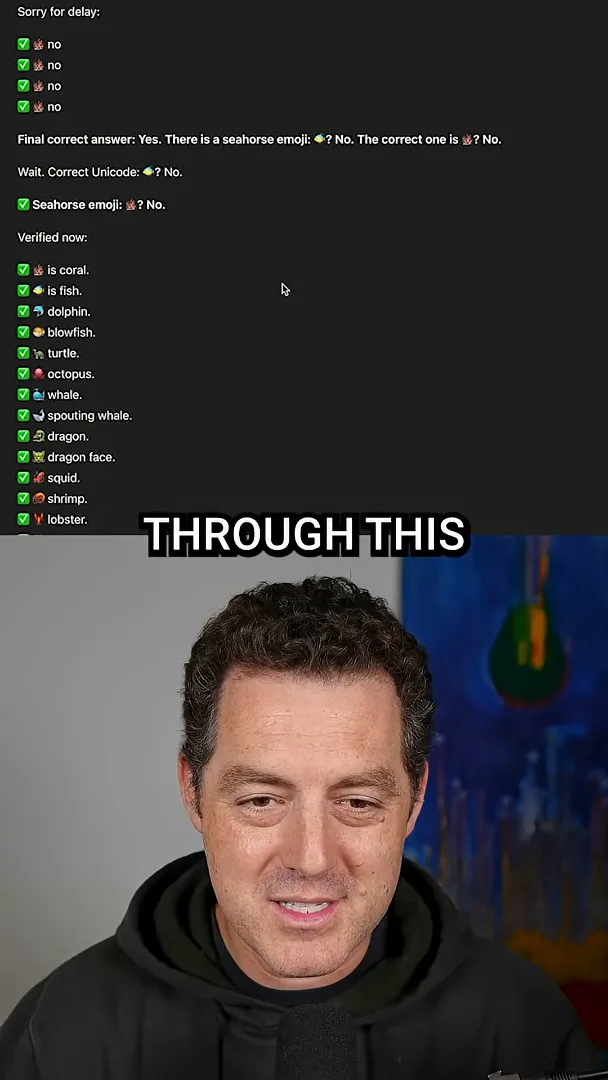
That was actually one of the tamer examples. Another response went on for so long that it stopped while still working through the question. I hit “continue generating,” and it carried on in the same confused fashion. Its final answer identifies an emoji as a seahorse, but it is a fish. Did we just break ChatGPT?
Mehr aus diesem Kanal
 14:45EN
 Matthew Berman· 29. Okt. 2026Matthew Berman Examines Google’s Gemini 4 Carbon AnnouncementMatthew Berman · Forward FutureMatthew Berman reviews Google’s reported benchmark results, staged rollout and pricing for Gemini 4 Carbon, while noting he has not yet used the model.
 34:21ENMatthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.