In 30 Sekunden
Matthew Berman discusses Google’s announcement of Gemini 4 Carbon, focusing on reported coding, cybersecurity and long-horizon benchmark results, pricing and token efficiency. He says the model was not publicly available when he recorded the video, so his assessment is based on published figures rather than hands-on use. Berman compares the reported results with competing models and considers the cost per task, while distinguishing his own preferences and speculation from the announced figures.
- 1Announced before general releaseBerman reviews the announcement and says the model was not yet publicly available at the time of the video.
- 2A new index resultHe reports that Carbon scored 59 on Artificial Analysis Intelligence Index v5, ahead of the comparison scores shown in the video.
- 3Staged accessAccording to the announcement he reads, access begins with cybersecurity defenders and trusted partners before wider availability.
- 4Pricing and task costHe discusses introductory and later token prices and argues that efficiency should be judged by cost per completed task.
- 5Benchmarks vary by taskThe displayed table compares coding, computer use, science and security. Carbon leads several metrics, while another model leads OSWorld in the table.
- 6Token usage and the cost curveBerman compares output tokens per task and an intelligence-versus-cost chart, while noting that he has not used Carbon himself.
Das Wichtigste
- Berman says Carbon was announced before general public access, with cybersecurity partners to receive early access.
- The reported benchmark table shows strong results across coding, science and cybersecurity, with different models leading some individual tests.
- He reports introductory pricing of $2 per million input tokens and $10 per million output tokens, with a higher price after the introductory period.
- Cost per completed task depends on both token prices and the number of tokens a model uses.
- Berman emphasizes that he had not yet tested Carbon and his preference for competing models reflects his own experience.
Den bearbeiteten Text nach Kapiteln lesen
The announcement and early results
Berman introduces the announced model, its limited initial availability and reported index and security results.
Matthew Berman introduces Google’s announced Gemini 4 Carbon and says the company claims it is its strongest model. He intends to review the announcement and benchmark figures, but notes that the model was not yet publicly available when he recorded the video.
Berman dislikes the gap between announcing a model and making it available, saying that waiting for access makes independent assessment uncomfortable. He then turns to Artificial Analysis, which aggregates benchmarks and conducts its own evaluations.
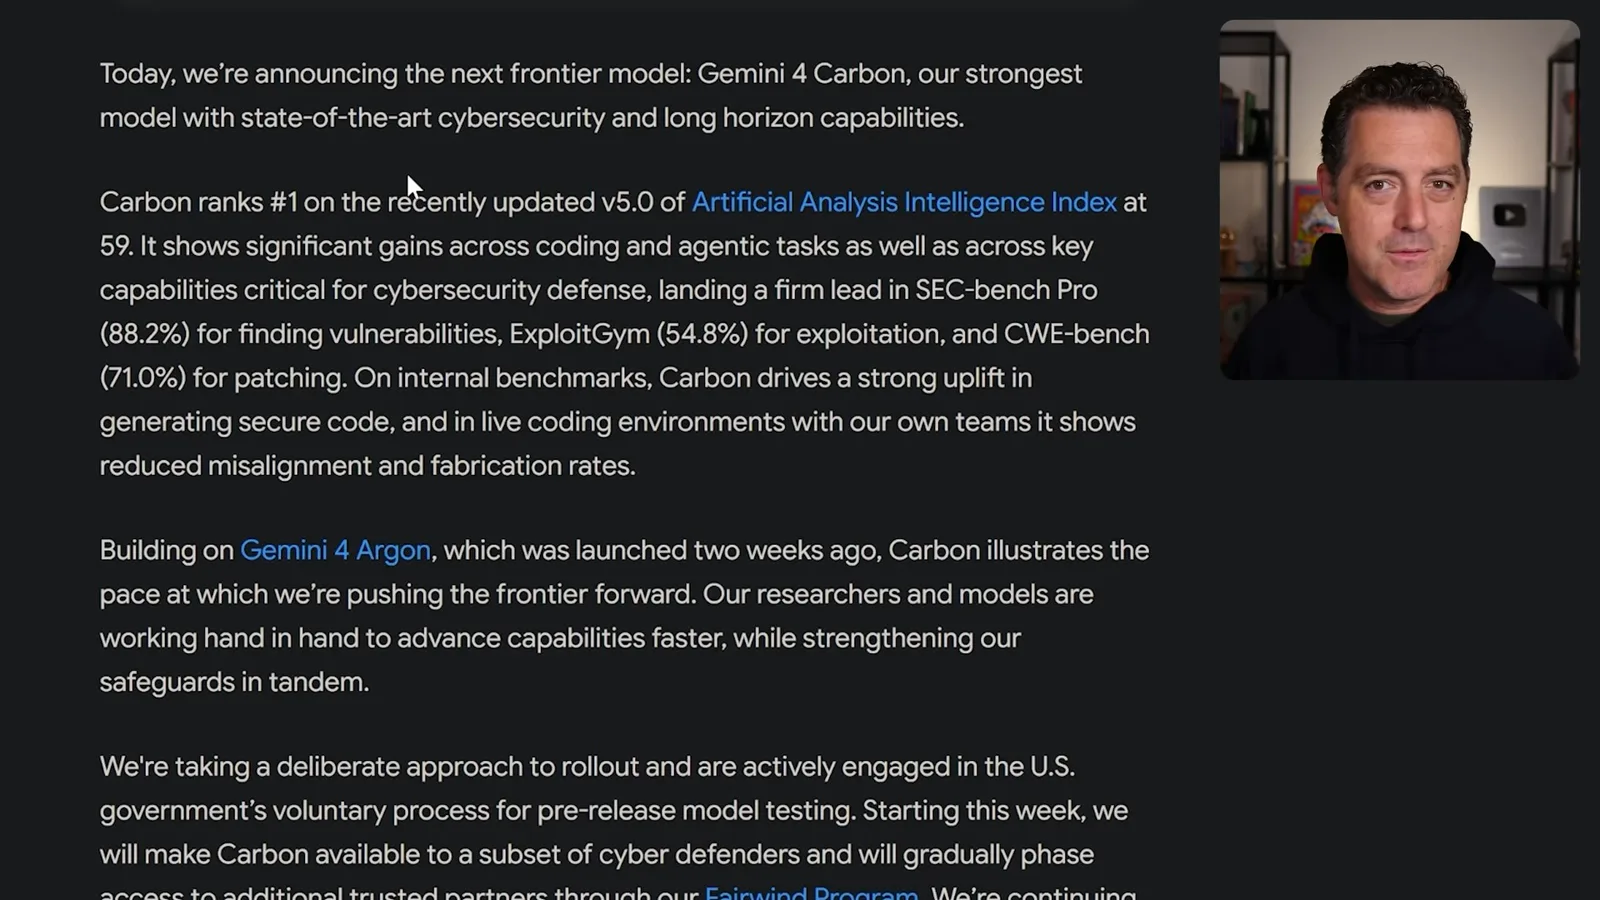
The video reports that Carbon scored 59 on the updated Artificial Analysis Intelligence Index v5, above the competing scores Berman shows. He says the announcement also claims gains in coding, agentic tasks and cybersecurity tests, including vulnerability finding, exploitation and patching.
Rollout, pricing and cost per task
He reviews the staged access plan and token pricing, and explains why token usage affects overall task cost.
Berman says the initial rollout will give cybersecurity partners access before general availability. He interprets this as an opportunity to find and patch vulnerabilities first. The announcement he reads describes pre-release testing and gradual access through Google’s Fairwind program.
The announcement also reports internal improvements in secure-code generation and reductions in misalignment and fabrication. Berman notes that Gemini 4 Argon appeared about two weeks earlier, but says he does not know whether Carbon reflects continued training or post-training.
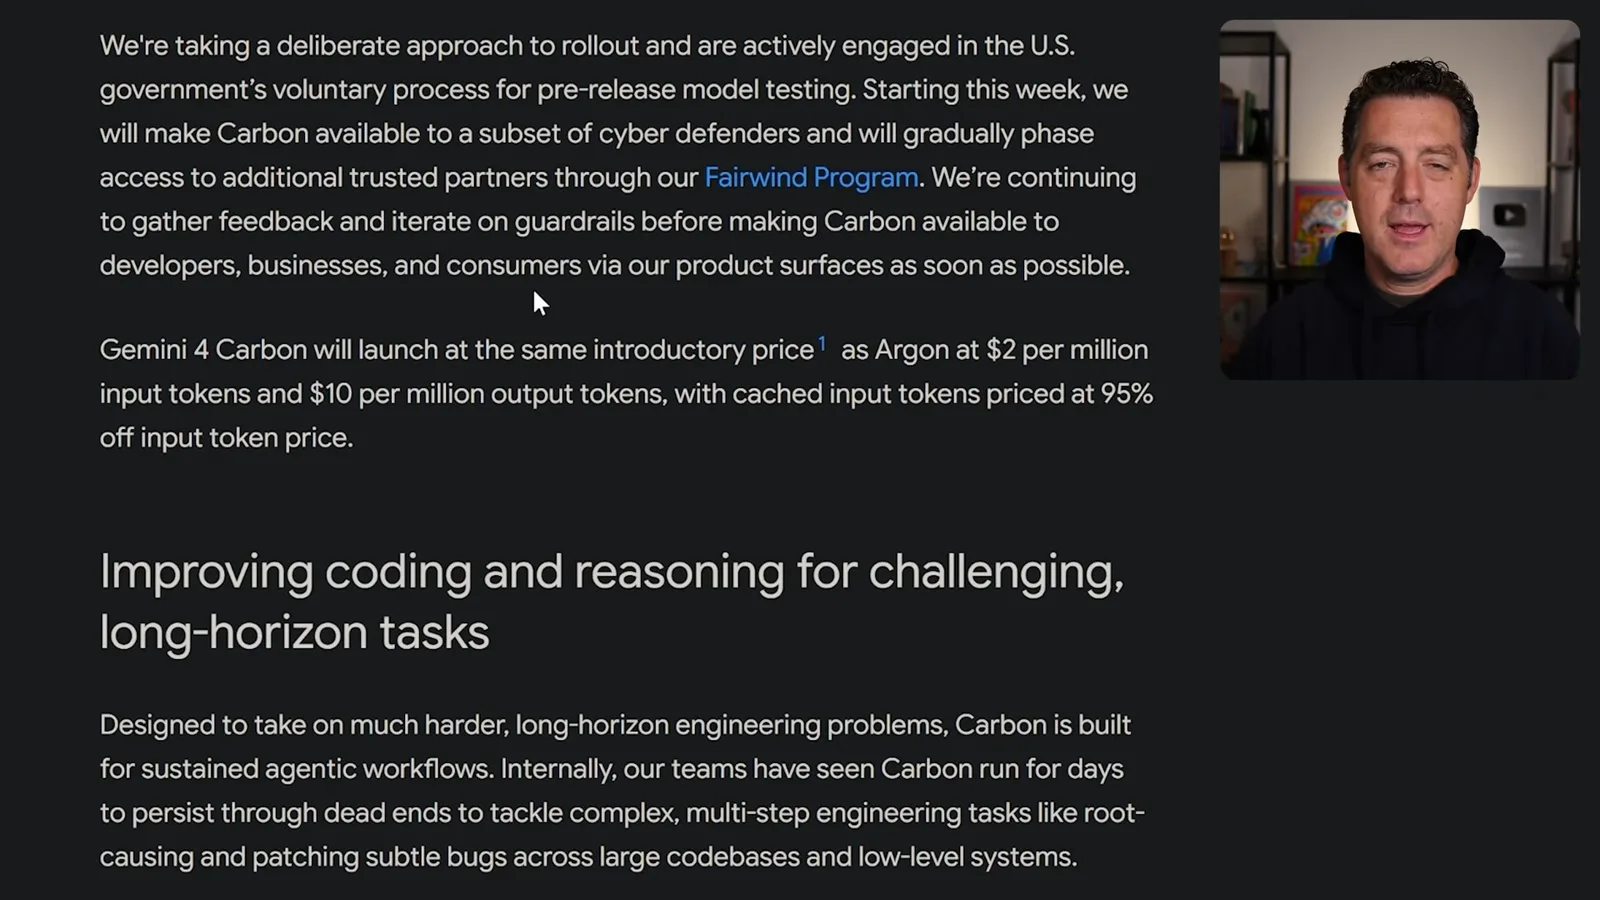
Berman reports introductory prices of $2 per million input tokens and $10 per million output tokens, with cached input at a 95% discount. He says the listed prices rise to $4 and $20 after the introductory period, whose length was not specified in the material he reviewed.
He argues that token price alone does not determine the economics: cost per completed task also depends on how many tokens the model uses to solve it. His speculation that an introductory price might be extended is an opinion, not a confirmed pricing commitment.
Comparing benchmark results
He walks through the displayed coding, computer-use, science and cybersecurity comparisons, separating his opinions from the figures.
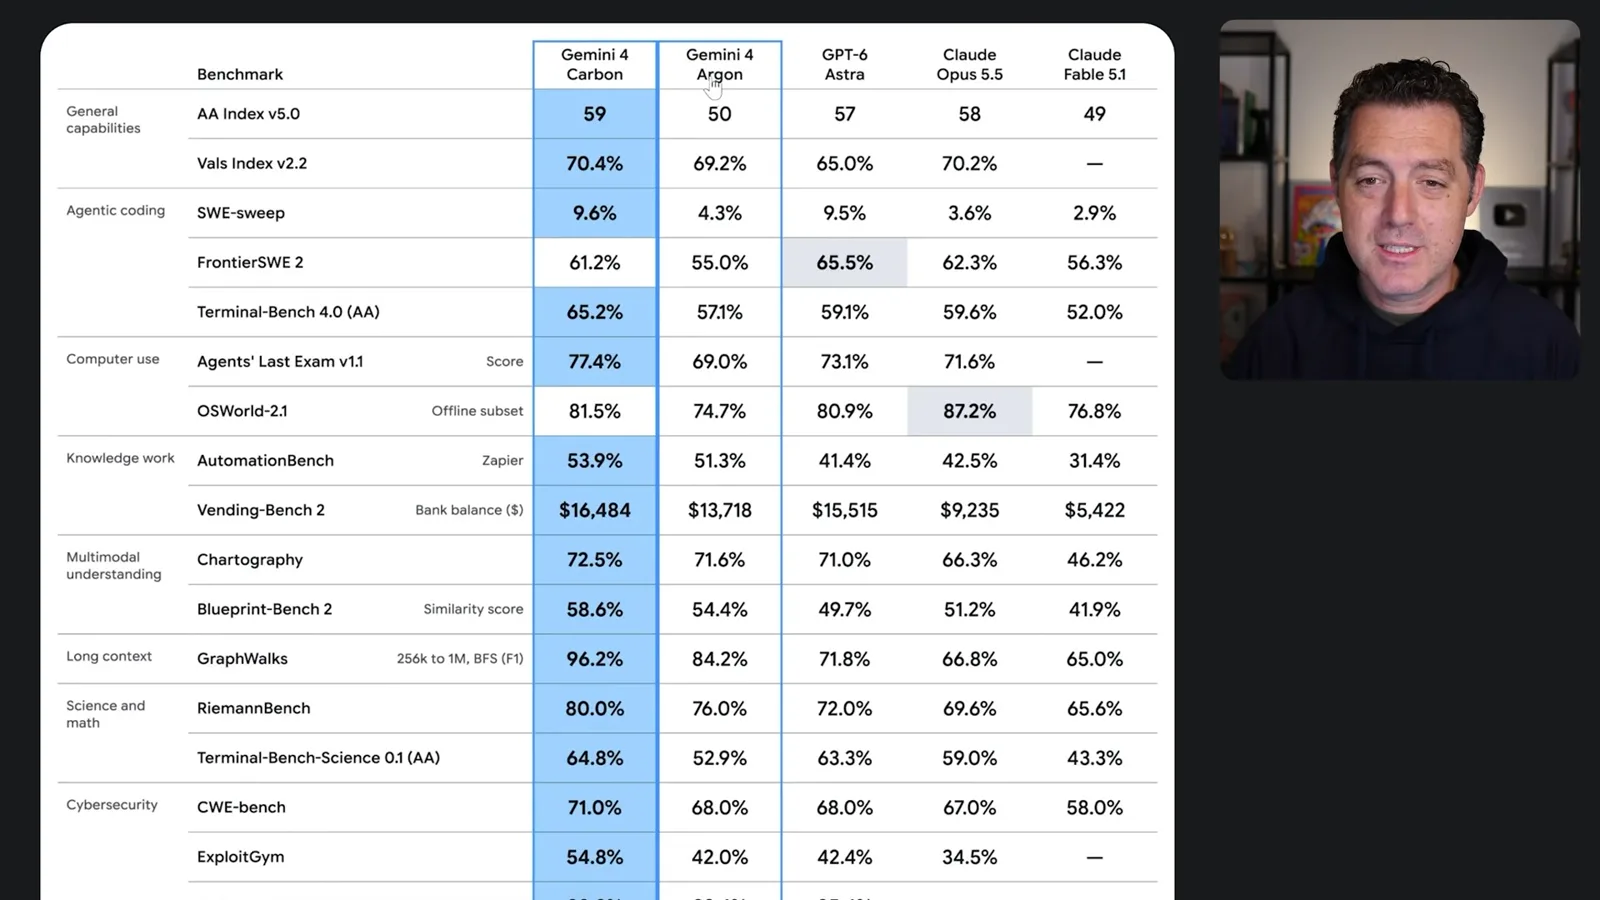
The benchmark table compares Carbon with Argon, GPT-6 Astra, Claude Opus 5.5 and Claude Fable 5.1. Berman reports an index score of 59 for Carbon, compared with 50 for Argon, 57 for Astra and 58 for Opus in the displayed table.
On the displayed coding tests, he cites Carbon at 9.6 on SWE-sweep and approximately 65 on Terminal-Bench 4.0, compared with roughly 57 for Argon on the latter. He describes terminal-based evaluation as relevant to agentic coding because it tests command execution.
For computer use, he cites a 77.4 score on Agents’ Last Exam and 81.5 on OSWorld. He personally prefers GPT models for computer and browser use, but notes that the displayed OSWorld table places Opus 5.5 above Carbon.
On Vending-Bench, the table shows Carbon ending with approximately $16,000, ahead of the compared Astra result of about $15,000. Berman also points to reported leading results on RiemannBench and Terminal-Bench-Science.
Berman says recent mathematical research announcements may involve internal models different from publicly available versions. In the cybersecurity table, he cites 71 on CWE-bench and approximately 54 on ExploitGym for Carbon. His explanation for differences in competitors’ security capabilities is presented as his belief.
Alignment and token efficiency
Berman reviews the announcement’s reported reductions in shortcut attempts and unsupported claims, then compares token use.
He reviews Google’s claims about reducing shortcuts and loophole exploitation. The announcement reports zero successful cheating and 4% attempted cheating on Terminal-Bench 4.0, alongside better accuracy. Berman also cites a reported approximate twofold reduction in unsupported claims relative to Argon.
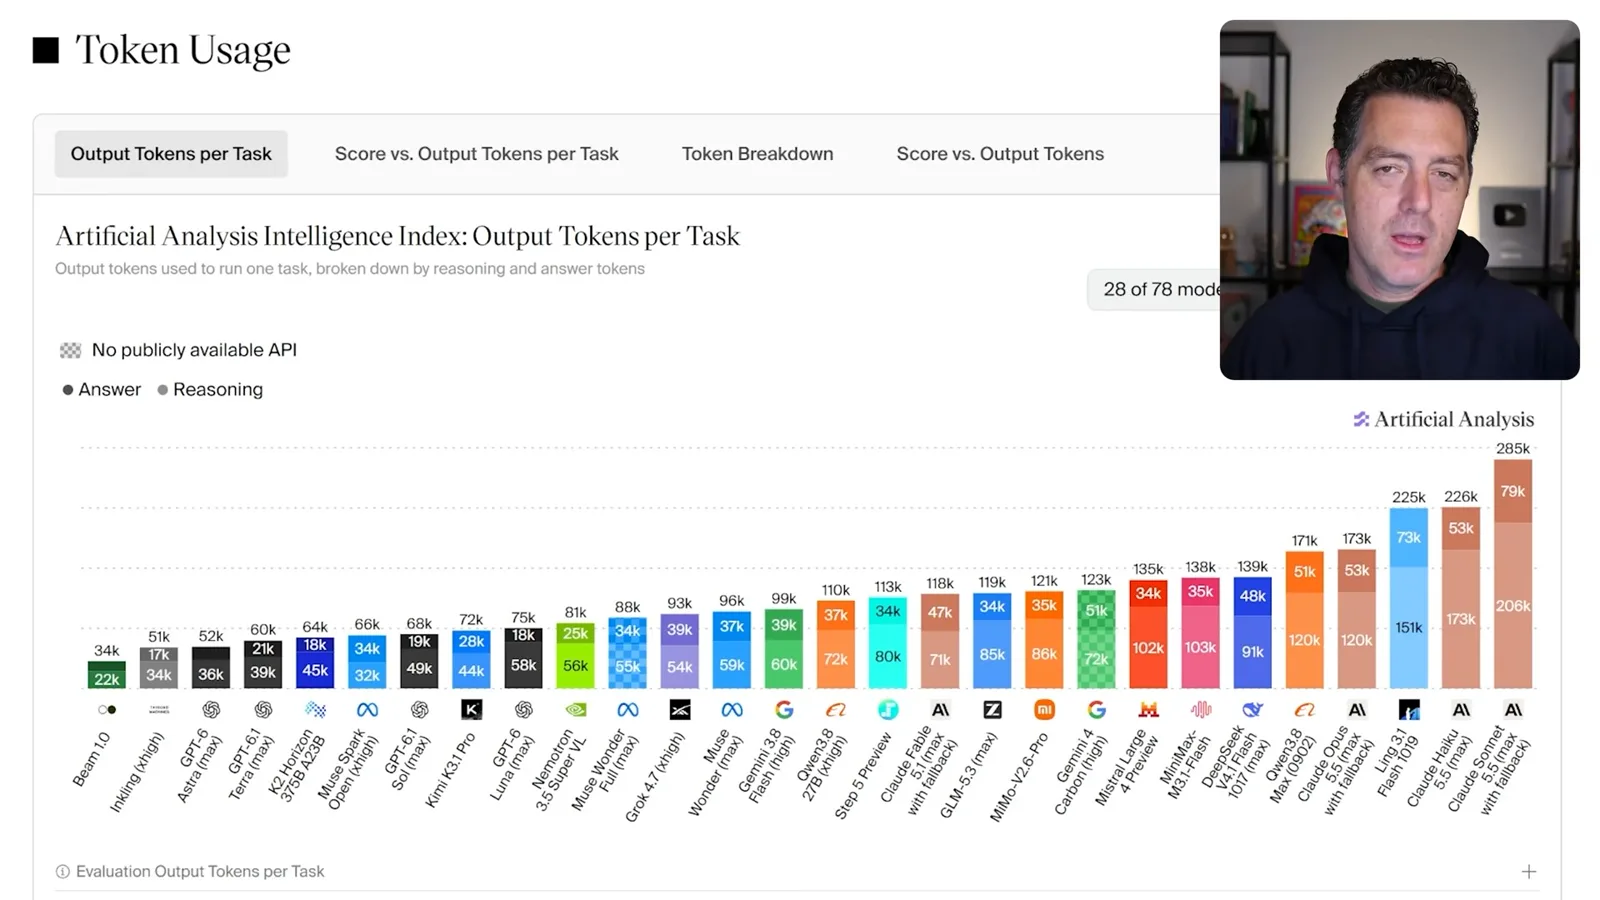
Berman returns to token efficiency: the displayed chart shows Carbon at roughly 123,000 output tokens per task, compared with higher figures for the Claude models he mentions. He estimates that Carbon uses about half as many tokens as those examples and around 20% fewer than Opus 5.5.
The intelligence and cost tradeoff
He examines the plotted cost-quality frontier and closes with his current model preferences, noting he has not tested Carbon.
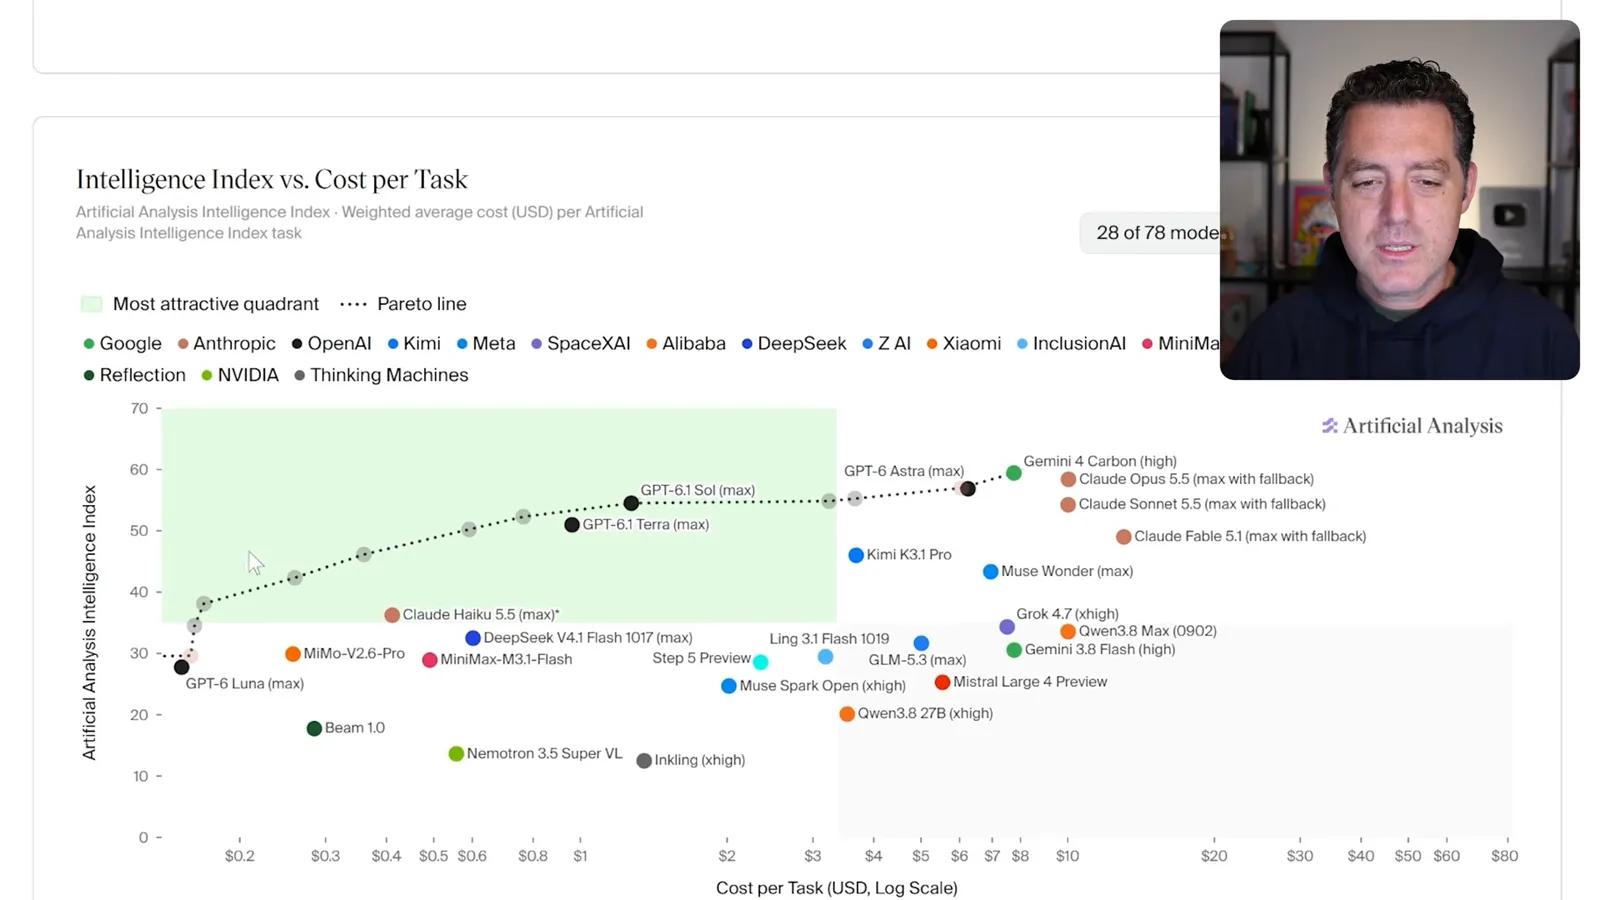
He examines a chart of intelligence index versus cost per task, where the upper-left area represents higher scores at lower cost. Carbon is plotted at the high end of quality, although other models occupy lower-cost positions. He expects Google to develop smaller, faster models as well, which is his prediction.
Berman says the displayed GPT-6.1 variants lie near the cost-quality frontier and calls the overall OpenAI offering strong. He still prefers Opus 5.5 for his own use because he has not tried Carbon, while also praising GPT-6.1 Sol.
He points to roughly 68,000 output tokens per task for GPT-6.1 Sol max on the displayed chart, compared with Carbon’s 123,000. He closes by saying he expects further improvements and lower costs, and remains enthusiastic about Google’s prospects.
Mehr aus diesem Kanal
 21:11EN
 Matthew Berman· 28. Okt. 2026Matthew Berman tests DeepSeek V4.1 Flash: coding, vision and local appsMatthew Berman · Forward FutureA hands-on tour of visual coding, image reasoning, local applications and provider economics reveals both impressive results and visible flaws.
 34:21ENMatthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.