In 30 Sekunden
Kamil Potrec of Keycard uses an invoice example to show why a downstream service may not know whether a user or an agent chose an action. He describes risks from personal tokens, agent-held keys and overprivileged service accounts, and proposes distinct agent identities, scoped credentials, delegation, policy and audit. Potrec also explains the operational complexity of applying these controls across many systems. He compares SDKs with a gateway that keeps downstream credentials outside the agent’s environment, including the gateway’s benefits and limitations.
- 1Who chose the action?An agent asked to retrieve an invoice might also decide to send it. If the service sees only the user’s credential, attribution is ambiguous.
- 2Issue credentials for a specific interactionPotrec proposes dynamic, scoped credentials and authentication for agents using existing identity mechanisms such as workload federation.
- 3The requirements at scaleSeparate identities, delegation, short-lived credentials, federated trust, policy and audit must work across many services and agent hops.
- 4Move secrets outside the agentA gateway can authenticate an agent, check policy and inject a downstream credential without exposing it to the agent’s execution environment.
- 5Gateways have costsThey introduce latency and a security-sensitive dependency; network controls, identity, local tools and configuration remain problems to solve.
Das Wichtigste
- A downstream service needs to distinguish the user who authorized work from the agent that chose an action.
- Agents should authenticate with their own identities and obtain scoped, short-lived credentials.
- Delegation, policy, audit and federation are needed across users, agents and legacy services.
- A gateway can keep downstream credentials away from an agent and inspect each request if bypass is prevented.
- Gateways add latency and operational complexity and do not replace agent identity or protect local tool execution.
Den bearbeiteten Text nach Kapiteln lesen
Who is making the request?
Potrec introduces a user, an agent, an MCP server and an invoicing API. Passing user credentials through this chain obscures who decided to take an action.
I’m Kamil Potrec, and I work on the product team at Keycard. In this short talk I’ll give a high-level overview of agent authentication and authorization: what is required, how the pieces might fit together, and where the practical problems begin.
A familiar diagram connects a user to an agent, then to MCP servers and other systems. What receives less attention is how the participants authenticate, authorize requests and establish which actor is responsible for an action.
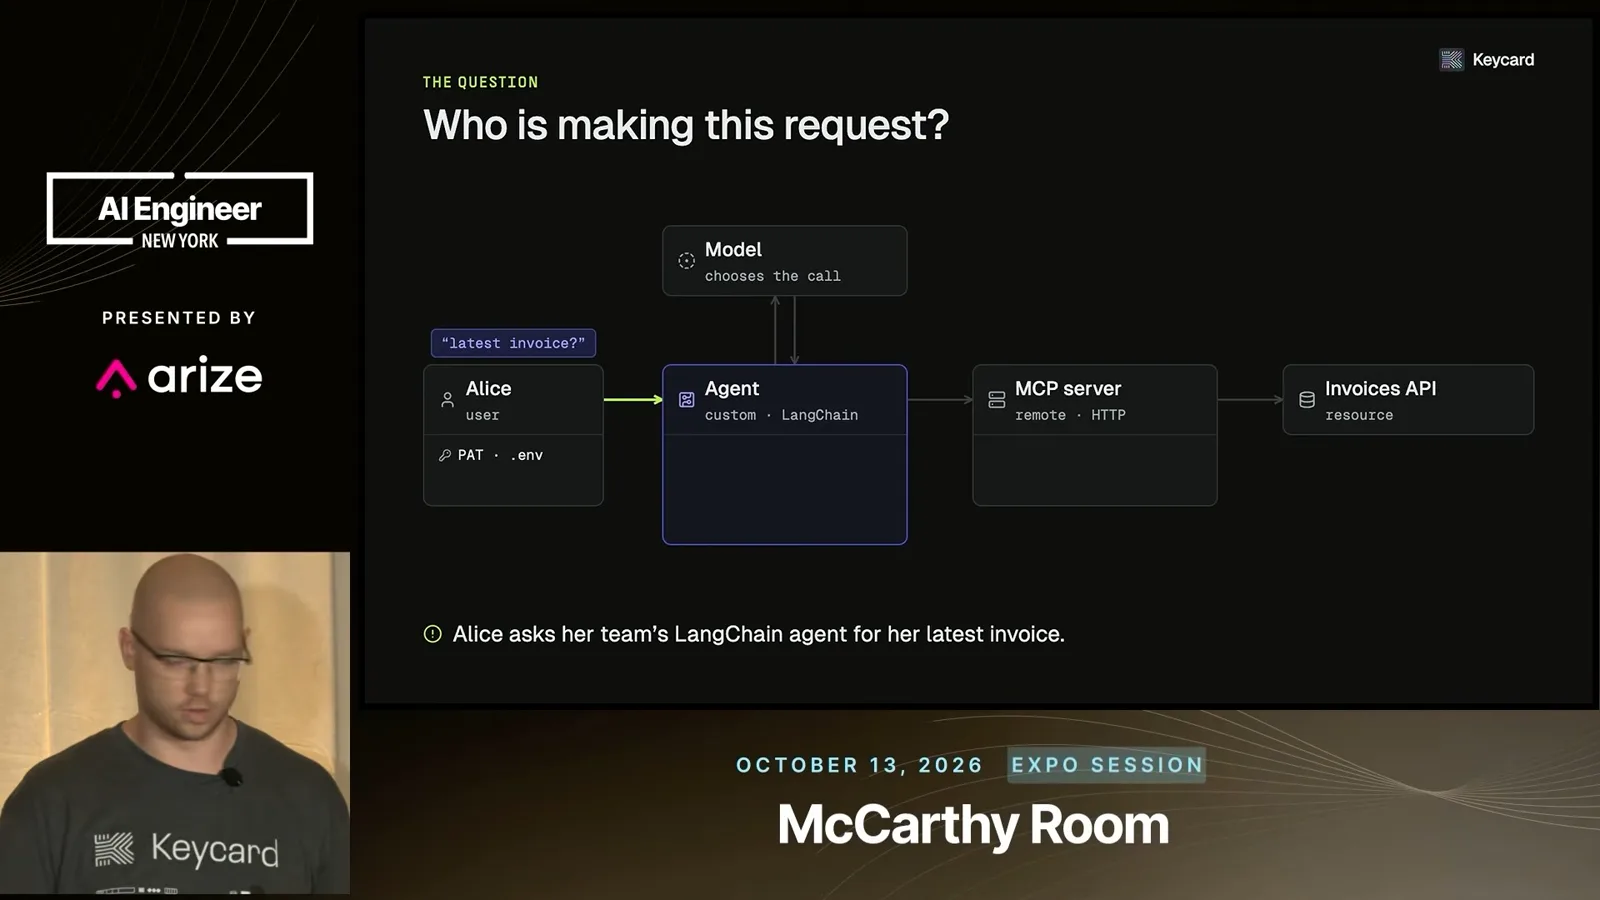
A user may give the agent a personal access token or another opaque credential. A local agent may skip even that step. The agent also needs credentials of its own, such as an API key for a model provider, and often needs additional credentials to call remote MCP tools.
An agent might pass Alice’s token through, use its own static key or obtain a dynamic credential. If the MCP server sees only Alice’s identity, however, it cannot tell whether the caller is an agent, Alice’s command-line client or another tool.
MCP servers often wrap existing APIs, databases and external systems. To serve many users, a server may use a service account rather than a single user’s token. That account can become an aggregation of permissions, a familiar problem from service-to-service applications.
Agents add a reasoning loop. Consider a request to retrieve an invoice: the agent receives a pending invoice and decides, perhaps because it is being too helpful, to send it. Was that action Alice’s decision or the agent’s? A service that only sees Alice’s credential may not be able to tell.
The risks of shared credentials
He discusses portable personal tokens, accumulated agent credentials and broad service accounts. He proposes short-lived, scoped credentials and distinct agent identity.
There are other problems with credentials lying around. A user can copy a personal token onto an unmanaged machine, bypassing protections in corporate infrastructure. Such credentials can be difficult to revoke, and agents accumulate more keys as they gain more capabilities.
Service accounts have long been overprivileged buckets of permissions. Previously, organizations often accepted this risk because they relied on developers to release deterministic software securely. Agents introduce another actor that can use those permissions while making its own choices.
I compare this to a colleague using an unlocked laptop to send a message promising everyone doughnuts. We learned to lock the machine; with agents, we can accidentally leave credentials available to software that acts for us. Some of the technology needed to improve this has existed for years.
Instead of asking Alice to find a static token, a service can advertise how to obtain access. A client can request authorization and receive a dynamic credential scoped to a particular interaction and tool. OAuth is one technology that can support this pattern.
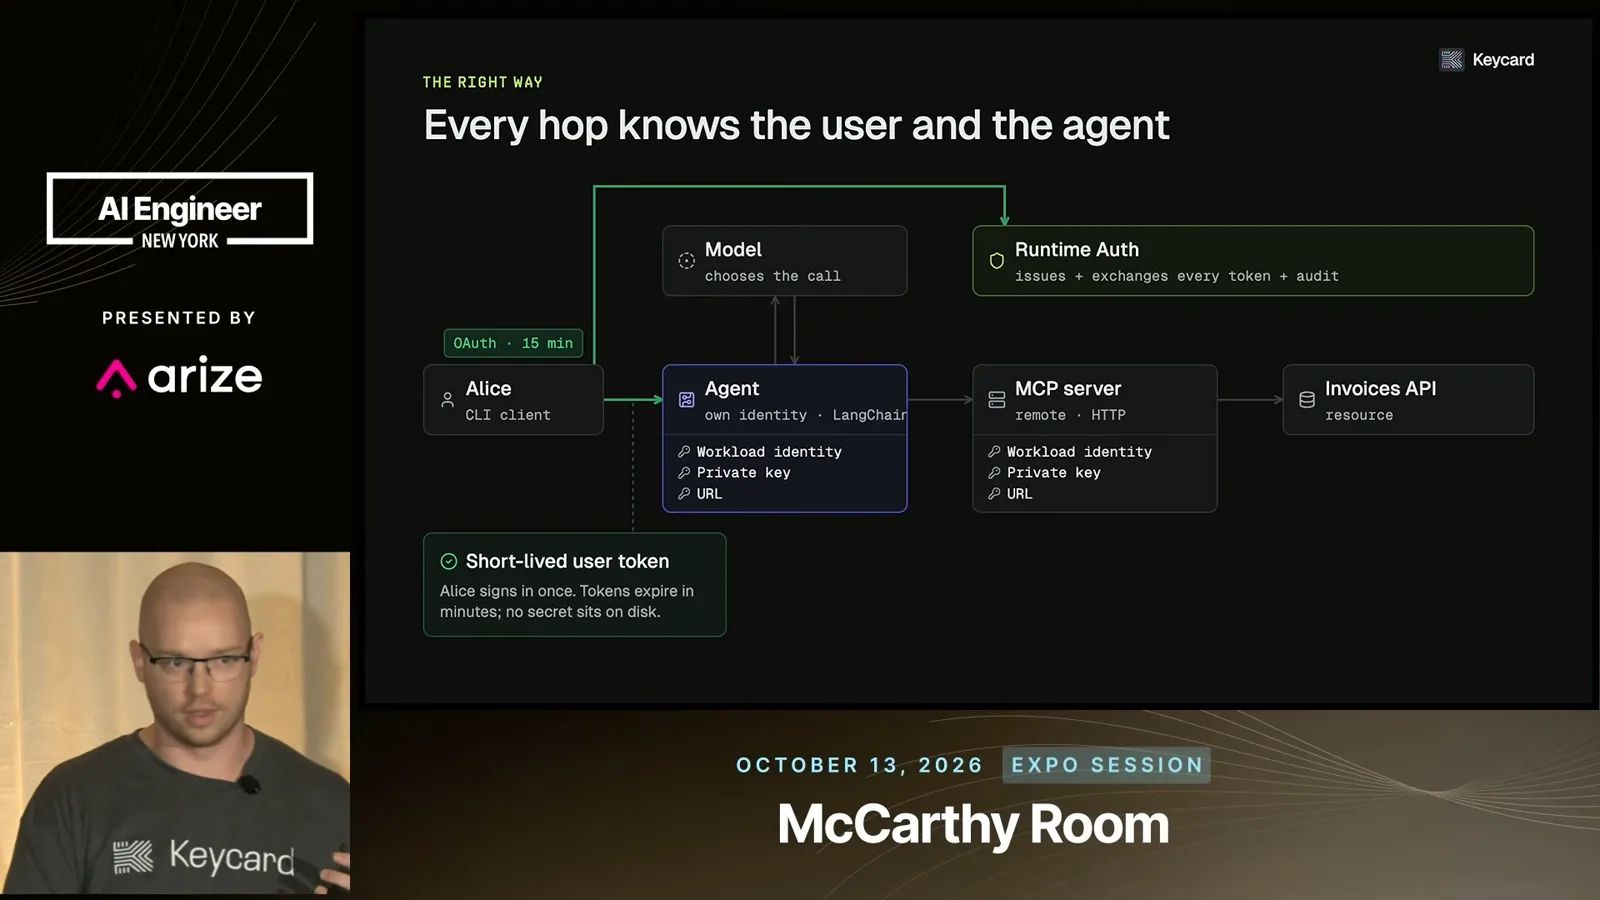
We also need agents to authenticate before they receive credentials. Workload identity federation, private keys and certificates are examples of mechanisms; the important point is to establish the agent’s identity. When an agent calls another service, it can discover the required authorization and obtain an appropriately scoped token.
Except for the reasoning loop, the agent and traditional application are both software, so similar patterns can be reused. The hard part is scale: an organization may have hundreds of APIs, different authorization servers and both purchased and internally built agents, some of which it cannot modify.
Identity and delegation at scale
Many services, agent types and delegation hops complicate the design. Potrec outlines federation, policy, audit and support for legacy systems.
There may be multiple hops between agents. Across thousands of users and arbitrary actions, we need to express delegation and consent while preserving attribution: who authorized the action, and which agent decided to perform it?
A practical system needs identities separate from the users who launched agents, potentially down to a session. It also needs delegation rules, scoped short-lived credentials and no master key that gives an agent persistent access to everything.
Existing systems cannot all be rewritten. Federated trust must connect identities across services, and an adaptive broker may need to exchange legacy credentials just in time. Policies specify which actions require human approval and which agents can act automatically; audit records show who authorized and enabled a request.
Why SDKs are not sufficient
Each request requires discovery, verification, authorization and logging. SDK adoption, maintenance and access to secrets present challenges.
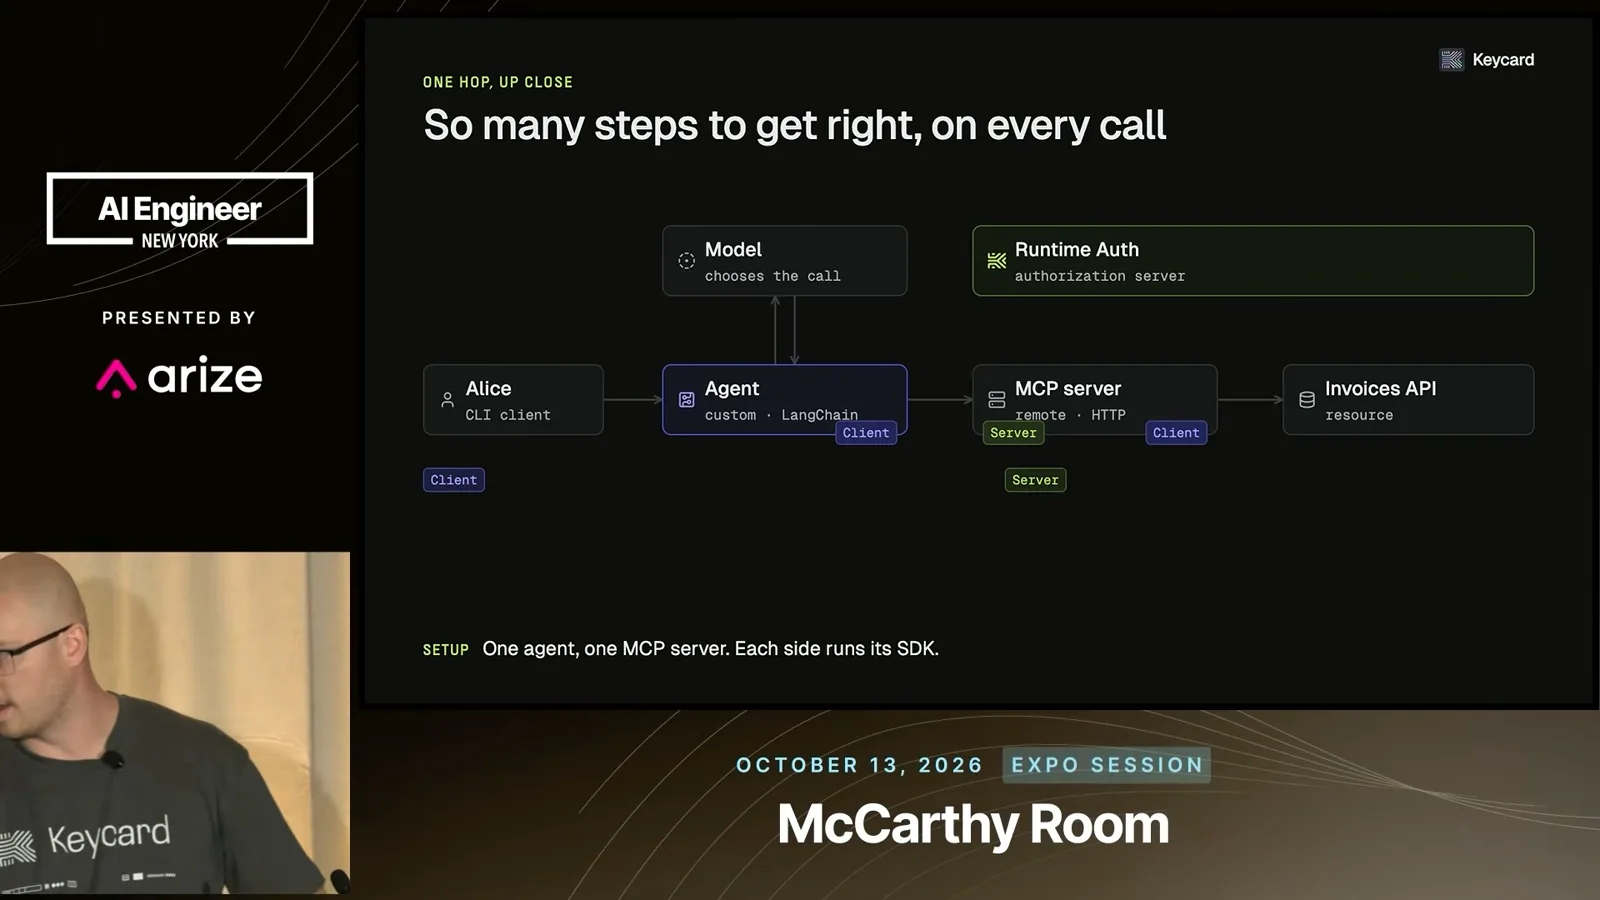
Even one agent-to-MCP-server interaction has many steps. The server publishes authorization information, the client discovers it and obtains credentials, and the server validates signatures, issuers and tokens. Policy must then be enforced, downstream credentials may be needed, and the actions must be logged.
We have handled similar complexity with shared libraries, middleware and SDKs: implement the logic once, review it and reuse it. But an SDK only helps where it is adopted, and organizations need implementations for different languages and systems they may not be able to modify.
When a security bug is found, teams must update the SDK and locate every service that uses it. Agents add another concern: an agent may be manipulated or persistently try to bypass controls. If a credential remains inside its execution environment, client-side code alone does not hide it from the agent.
A gateway outside the agent
A gateway can broker credentials, inspect requests and enforce policy. It also introduces operational, identity and network-control challenges.
One alternative is to move downstream credentials into a secure vault or runtime authorization service outside the agent’s environment. The agent calls a gateway, which authenticates it, checks policy with the authorization service and retrieves the credential needed for a specific target such as GitHub.
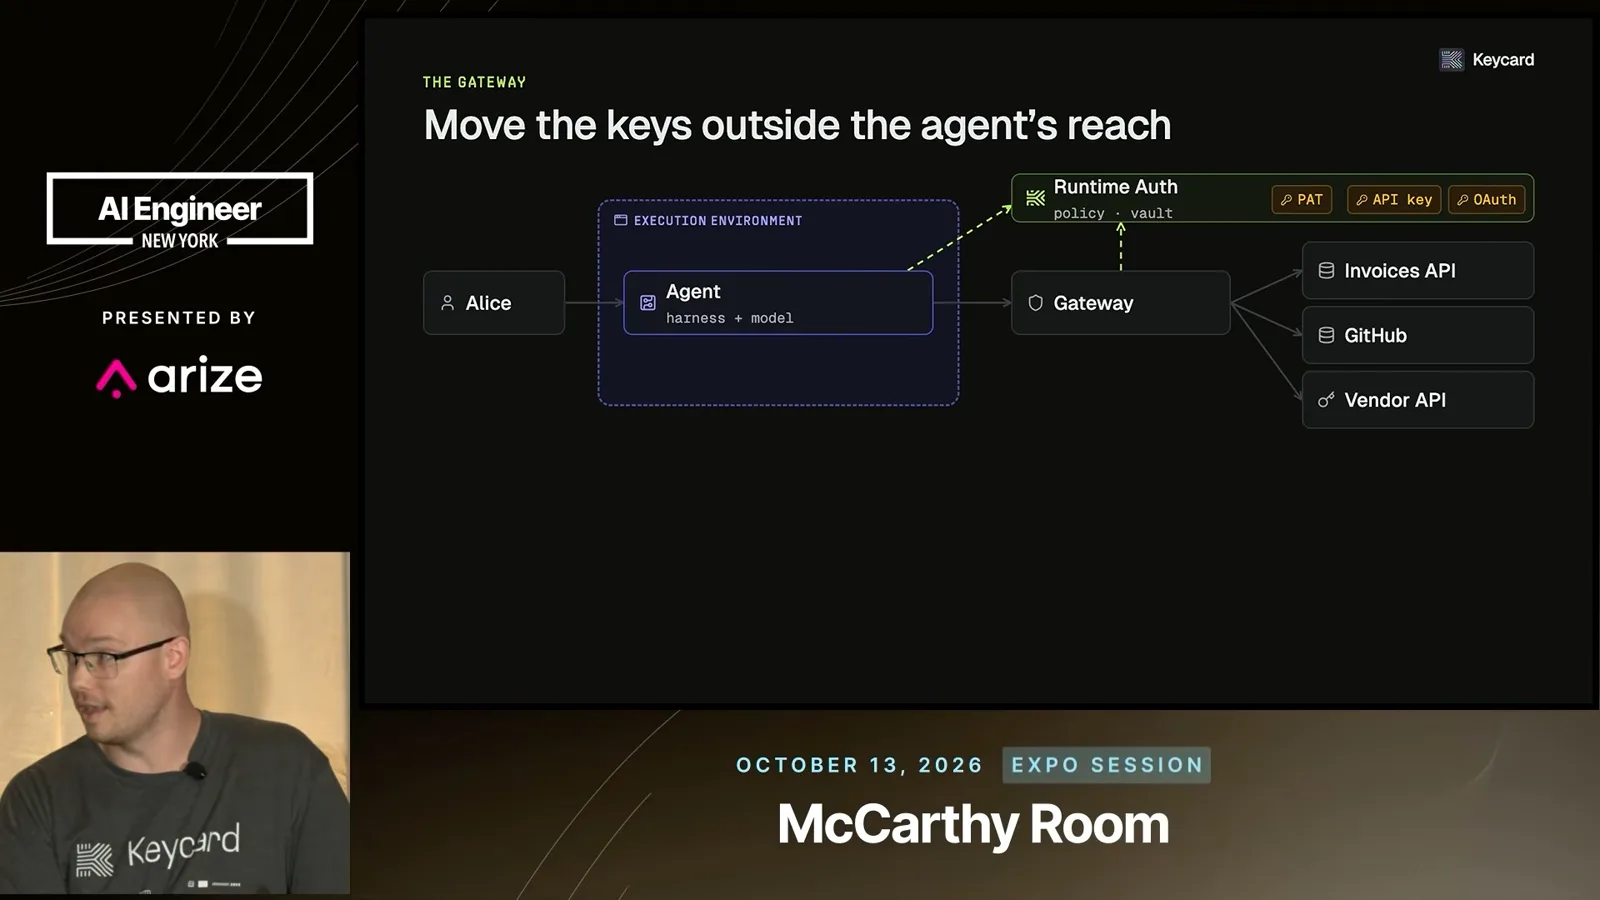
The gateway injects the credential into the outgoing request. If the agent cannot reach the credential store or bypass the gateway, it does not need to hold the downstream secret itself. This creates a separate control point between agent execution and the protected service.
Even short-lived credentials remain usable until they expire. A gateway that evaluates each request can enforce revocation at that point. It can also narrow coarse legacy permissions: for example, allow an agent to read email while blocking a request to send it.
Because the gateway sits on the network path, it can improve visibility without changing every downstream service. But there are tradeoffs: another hop adds latency, and weak network controls let agents bypass it. Local tool execution is not covered simply by adding a gateway.
The gateway does not eliminate the identity problem: agents still need credentials to authenticate to it. It also becomes a high-value target because credentials pass through it. TLS interception, route and policy configuration, connectors and operating the gateway all add complexity.
A control plane and closing advice
Potrec describes Keycard’s identity, policy, SDK and gateway offerings. He recommends open standards, interoperability and security review.
At Keycard, we offer a control plane for agent identities, token issuance and federation, policy and audit, client and service SDKs, and an optional gateway. Teams can choose the components appropriate to their application or orchestration platform.
My closing advice is to treat agent authentication as necessary, use open standards and interoperability, and review security-sensitive code rather than assuming an LLM will implement it correctly. Keycard also points to Agent Baseline as a reference implementation for exploring these capabilities.
Mehr aus diesem Kanal
 21:47EN
 AI Engineer· 28. Okt. 2026Patrick Smyth on Open-Source Supply Chain Security in the AI EraPatrick Smyth · ChainguardChainguard’s Patrick Smyth discusses faster exploitation, malware in dependencies, zero-days and the expanding attack surface around developer workflows.
 14:09ENAI Engineer· 28. Okt. 2026Taylor Luttrell-Williams on Finding Logic Vulnerabilities with SonarQube Hunter AgentTaylor Luttrell-Williams · SonarSonar’s Taylor Luttrell-Williams explains how a security agent maps a codebase, investigates logic flaws and presents validated findings alongside conventional scans.
 16:29ENAI Engineer· 28. Okt. 2026Chris Vela on Benchmarking vLLM Configurations with Runpod BenchPodChris Vela · RunpodRunpod’s Chris Vela demonstrates a dashboard for comparing LLM serving configurations and choosing performance settings with workload-specific data.
 18:52ENAI Engineer· 28. Okt. 2026Manish Kapur and Addy Osmani on Verifying AI Software FactoriesManish Kapur, Addy Osmani · SonarSonar’s Manish Kapur and Anthropic’s Addy Osmani discuss code review, evidence and layered checks as coding agents increase the pace of software changes.
 18:56ENAI Engineer· 27. Okt. 2026John Feminella: Five Controls for AI Agents, and the $900 Million Bank ErrorJohn Feminella · Two SigmaA payment mistake shows why good intentions and approval prompts are not enough. Feminella describes practical controls for giving agents useful autonomy.
 18:12ENAI Engineer· 27. Okt. 2026Tim Tyler: An Accountability Framework for AI Agents as a Digital WorkforceTim Tyler · GraviteeThe Gravitee speaker applies identity, sponsorship, authority and oversight to agents, drawing on how organizations manage human work.