








Ergebnisse
27 ArtikelSortieren
 12:14EN
 Matthew Berman· 14. Okt. 2026Gemini 4 Argon Tested: 3D Demos, a Spreadsheet Prototype and Benchmark ResultsMatthew Berman · Forward FutureMatthew Berman tests Google’s model on games and visual projects, then compares reported coding and agent benchmarks.
 10:36ENMatthew Berman· 13. Okt. 2026Meta Muse Wonder Tested: Strong Benchmarks, Mixed Demos and Quota FrictionMatthew Berman · Forward FutureMatthew Berman tests Meta’s models on browser demos and reviews their published benchmark scores, availability and cost.
 13:09ENMatthew Berman· 14. Aug. 2026AI News: Ultrafast Inference, Claude Watermarks and New ModelsMatthew Berman · Forward FutureMatthew Berman reviews an ultrafast coding preview, text watermarking, Grok Bot, open-weight models and Computer History.
 9:47ENMatthew Berman· 3. Apr. 2026Gemma 4: Smaller Open-Weight Models for Local AIMatthew Berman · Forward FutureMatthew Berman reviews Google’s model sizes, multimodal features and reported benchmarks, with an eye toward local agents.
 0:37ENMatthew Berman· 20. Feb. 2026Gemini 3.1 Pro: A Look at the Reported Benchmark ScoresMatthew Berman · Forward FutureMatthew Berman reacts to a Gemini 3.1 Pro comparison and highlights results on Humanity’s Last Exam.
 11:49ENMatthew Berman· 17. Feb. 2026Matthew Berman Reviews Claude Sonnet 4.6: Benchmarks, Computer Use and SafetyMatthew Berman · Forward FutureA launch-day overview examines Anthropic’s reported knowledge-work and agent results, along with prompt-injection and capability evaluations.
 1:11ENMatthew Berman· 18. Nov. 2025Gemini 3's Launch: Benchmarks, Antigravity, and AgentsMatthew Berman · Forward FutureMatthew Berman summarizes Google's November 2025 model launch and its developer and assistant demos.
 8:47ENMatthew Berman· 16. Sept. 2025Why Identical LLM Prompts Can Produce Different Answers at Temperature ZeroMatthew Berman · Forward FutureMatthew Berman explains Thinking Machines Lab’s work on batch-invariant inference and what its reproducibility experiment actually showed.
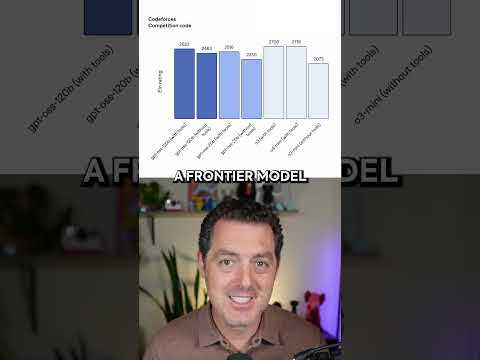 1:01ENMatthew Berman· 5. Aug. 2025OpenAI’s gpt-oss Release and a Coding BenchmarkMatthew Berman · Forward FutureMatthew Berman introduces two open-weight models and reviews a Codeforces comparison from the launch.
 7:33ENMatthew Berman· 4. Apr. 2025Ace Computer-Use Agent: Fast Desktop and Browser DemonstrationsMatthew Berman · Forward FutureMatthew Berman reviews General Agents’ examples and reported click accuracy and latency, while noting he has not yet tested Ace himself.
 9:35ENMatthew Berman· 25. Feb. 2025Claude 3.7 Sonnet and Claude Code: An Early Coding TestMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s 2025 launch benchmarks and builds an AI-controlled Snake game, then tests math and recent information.
 13:24ENMatthew Berman· 18. Feb. 2025Grok 3’s 2025 Launch: Benchmarks, Reasoning and DeepSearchMatthew Berman, Elon Musk · Forward FutureMatthew Berman reviews xAI’s launch charts, a historical user-preference leaderboard and an early product demonstration.
 9:58ENMatthew Berman· 31. Jan. 2025OpenAI o3-mini Launch: Reasoning Effort, Benchmarks and a Snake TestMatthew Berman · Forward FutureIn January 2025, Matthew Berman reviews OpenAI’s reported results and tries two coding examples with different reasoning settings.
 8:52ENMatthew Berman· 21. Jan. 2025Industry Reactions to DeepSeek R1’s 2025 ReleaseMatthew Berman · Forward FutureMatthew Berman reviews early reactions to DeepSeek R1, from open-weight reasoning models and local hardware to benchmark results and API pricing.
 11:14ENMatthew Berman· 18. Sept. 2024Pixtral 12B: Testing a 2024 Vision-Language ModelMatthew Berman · Forward FutureMatthew Berman runs informal image, text and interface-generation tests of Mistral’s Pixtral on a sponsor-provided cloud GPU.
 10:57ENMatthew Berman· 24. Juni 2024Testing Claude 3.5 Sonnet: Coding, Reasoning, and VisionMatthew Berman · Forward FutureMatthew Berman puts Anthropic’s June 2024 model through informal coding, math, puzzle, and image-understanding prompts.
 9:53ENMatthew Berman· 28. Mai 2024Testing Microsoft Phi-3 Medium Locally: Mixed Coding and Reasoning ResultsMatthew Berman · Forward FutureMatthew Berman runs a quantized Phi-3 Medium on a MacBook and explores coding, arithmetic and reasoning prompts.
 13:37ENMatthew Berman· 16. Mai 2024Testing Gemini 1.5 Pro’s Long Context and Video UnderstandingMatthew Berman · Forward FutureMatthew Berman’s 2024 tests show useful image and video summaries alongside blocked code and missed details.
 9:25ENMatthew Berman· 31. Jan. 2024Matthew Berman Tests Meta’s Code Llama 70B on a Snake GameMatthew Berman · Forward FutureA 2024 look at Meta’s coding-model release, a SQL-focused fine-tune and a hands-on test that did not work on the first attempt.
 0:42ENMatthew Berman· 31. Jan. 2024LLaVA 1.6 Adds Higher-Resolution Image UnderstandingMatthew Berman · Forward FutureMatthew Berman reviews the January 2024 release of LLaVA 1.6 and its local availability through Ollama.
 12:49ENMatthew Berman· 14. Sept. 2023Falcon 180B: A 2023 Review of TII’s Open-Weight ModelMatthew Berman · Forward FutureMatthew Berman tests coding, reasoning and writing prompts while examining the model’s training scale and license.
 2:25ENMatthew Berman· 1. Aug. 2023Gorilla: Generating API Calls with Language ModelsMatthew Berman · Forward FutureMatthew Berman introduces a 2023 research project on using retrieved documentation to help language models generate tool calls.
 4:36ENMatthew Berman· 20. Juni 2023Testing WizardCoder 15B as a Local Coding AssistantMatthew Berman · Forward FutureMatthew Berman runs the 2023 WizardCoder model locally, testing small Python exercises and a longer Snake game.
 10:40ENMatthew Berman· 7. Juni 2023Testing Nous Hermes 13B Locally: Mixed Reasoning and Unsafe ResponsesMatthew Berman · Forward FutureMatthew Berman compares a 2023 quantized model on hosted and local hardware, with uneven results across coding, logic and safety.
Mehr laden24 von 27 angezeigt