In 30 Sekunden
In January 2025 Matthew Berman surveys reactions to DeepSeek R1 from researchers, developers and investors. He discusses its released weights, smaller distillations, reported benchmark scores, API prices and possible implications for access to reasoning models. The comparisons reflect particular 2025 model versions, tests and prices. Local inference requires hardware, and the paper’s R1 training process includes supervised data; a reinforcement-learning result does not mean that all human input was removed.
- 1Open research reactionNVIDIA researcher Jim Fan welcomed the release of weights and training research and highlighted reinforcement learning.
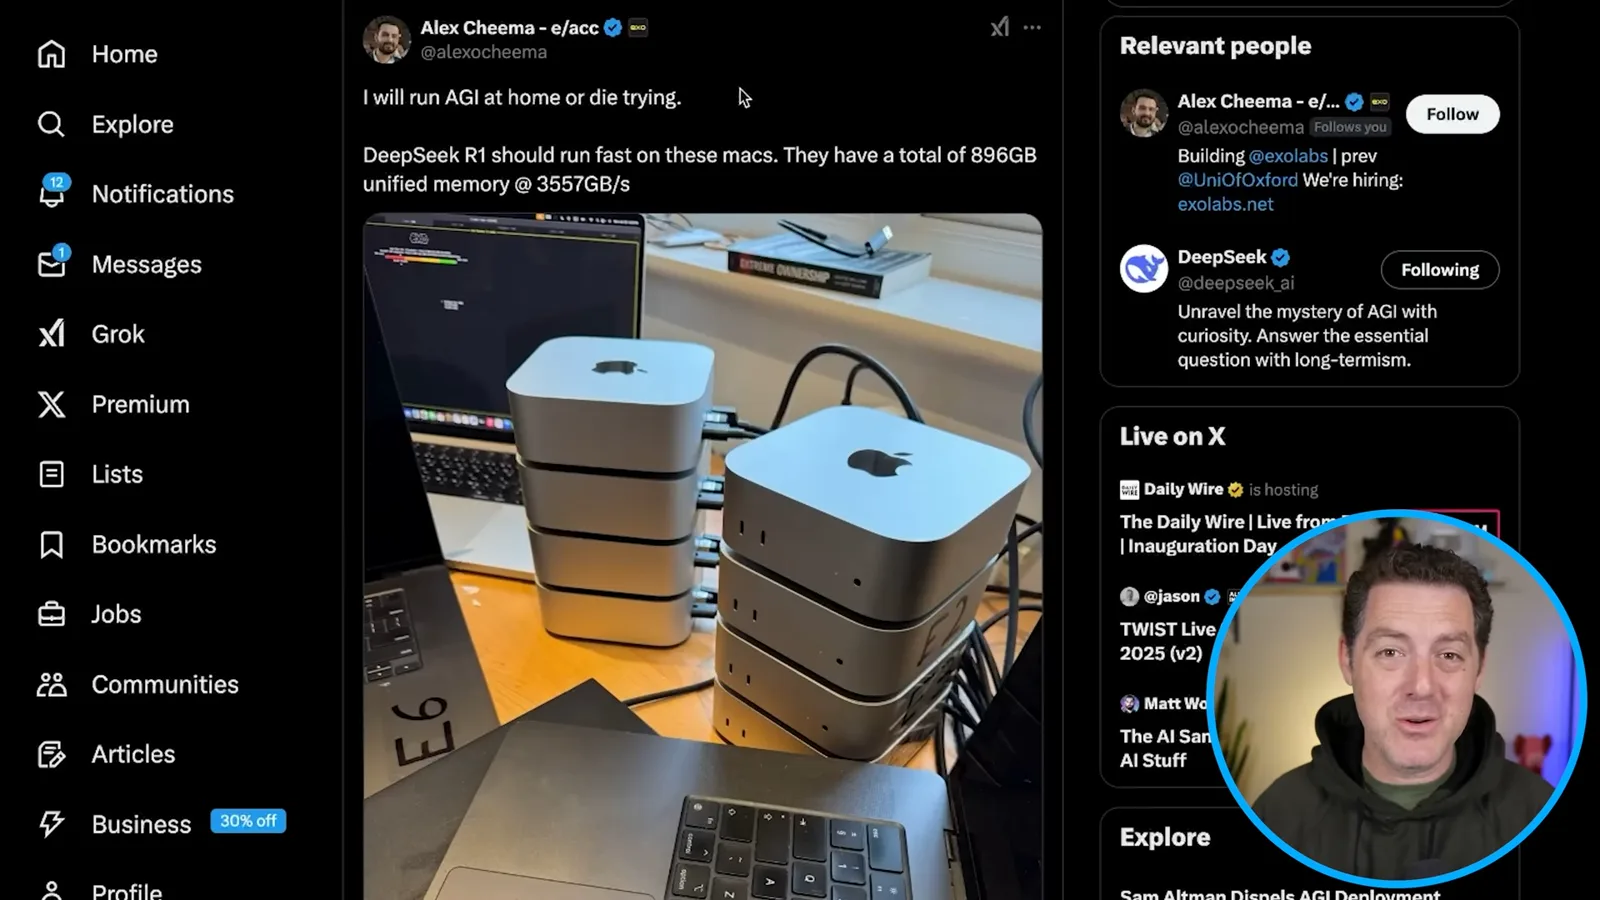
- 2A local hardware experimentAlex Cheema showed a multi-Mac setup and anticipated running the large model on it.
- 3Smaller model resultsThe paper reports 28.9% on AIME 2024 and 83.9% on MATH-500 for the Qwen 1.5B distill under specified evaluation settings.
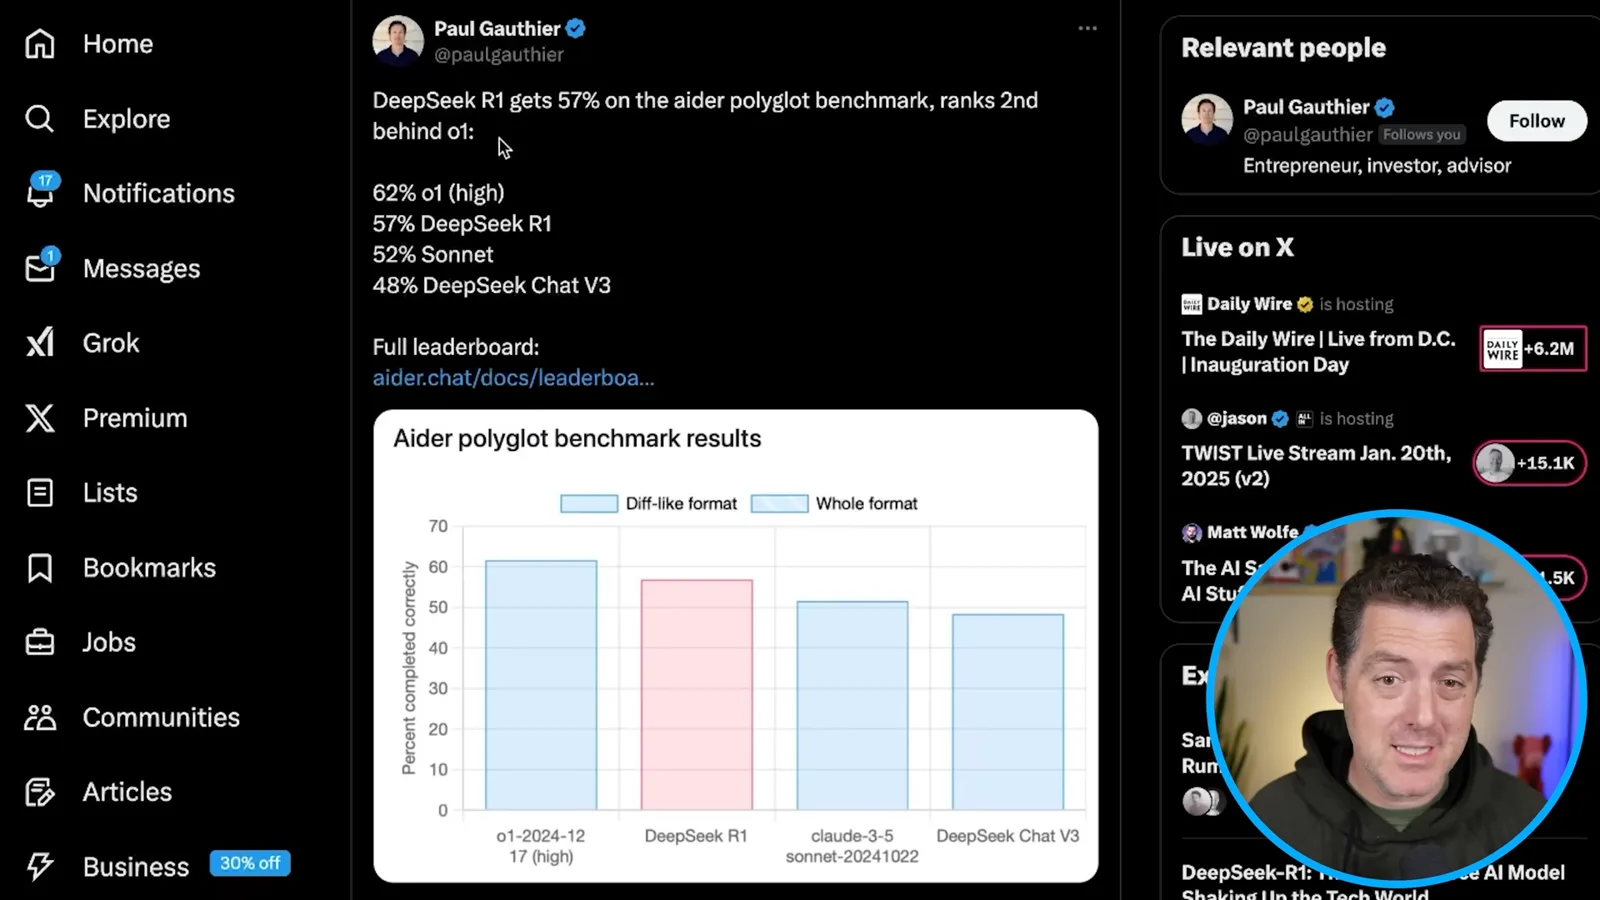
- 4A coding benchmarkAider’s founder reported 57% for R1 and 62% for o1 high on its polyglot benchmark at the time.
- 5Historical API pricesA posted January 2025 price comparison lists different rates for cached input, uncached input and output.
- 6Model behavior and modificationBerman discusses political-topic refusals and the possibility of changing model behavior through fine-tuning.
Das Wichtigste
- DeepSeek released R1 weights and a research report alongside smaller distilled models, widening options for local deployment.
- R1-Zero and R1 had different training pipelines; the latter used supervised cold-start data as well as reinforcement learning.
- Reported benchmark scores apply to specific datasets, versions and test conditions rather than universal model rankings.
- The 2025 API price comparisons and local-compute costs depend on provider, token mix and hardware.
- Open weights make modification possible but do not guarantee removal of refusals or safety constraints.
Den bearbeiteten Text nach Kapiteln lesen
Open weights and reinforcement learning
Berman introduces R1 and discusses Jim Fan’s reaction and the paper’s training approach.
DeepSeek’s R1 release has prompted strong reactions across the industry. The team released model weights and a research report describing its approach to reasoning. I am excited about the possibility of more openly available reasoning models, but access to weights is not the same as publishing every training dataset or detail.
NVIDIA researcher Jim Fan praises the release and highlights a reinforcement-learning flywheel. I interpret that as removing the human-feedback bottleneck. The paper draws an important distinction: R1-Zero is an RL-focused experiment without an initial supervised fine-tuning stage, whereas R1 uses supervised cold-start data and additional training stages. Neither claim establishes that humans played no role throughout development.
Fan contrasts publicity about future AI with publishing algorithms and learning curves. I appreciate seeing concrete technical material that others can study, even though releasing a paper and weights does not necessarily disclose every ingredient needed to reproduce the model.
Local models and early evaluations
He reviews a multi-Mac setup, smaller distillations and early benchmark comparisons.
Alex Cheema shows a multi-Mac setup and says its machines have 896 GB of combined unified memory and 3,557 GB/s of aggregate bandwidth. He anticipates running the large R1 model on it. Those figures describe his setup and expectation; they are not a measured speed for every local installation.
The availability of weights means users can explore local inference instead of relying only on a hosted service. I compare it with subscription and API prices for proprietary models, and emphasize cheaper access. Downloading weights does not make hardware, electricity or hosted inference free, and model licenses and the resources needed vary by version.
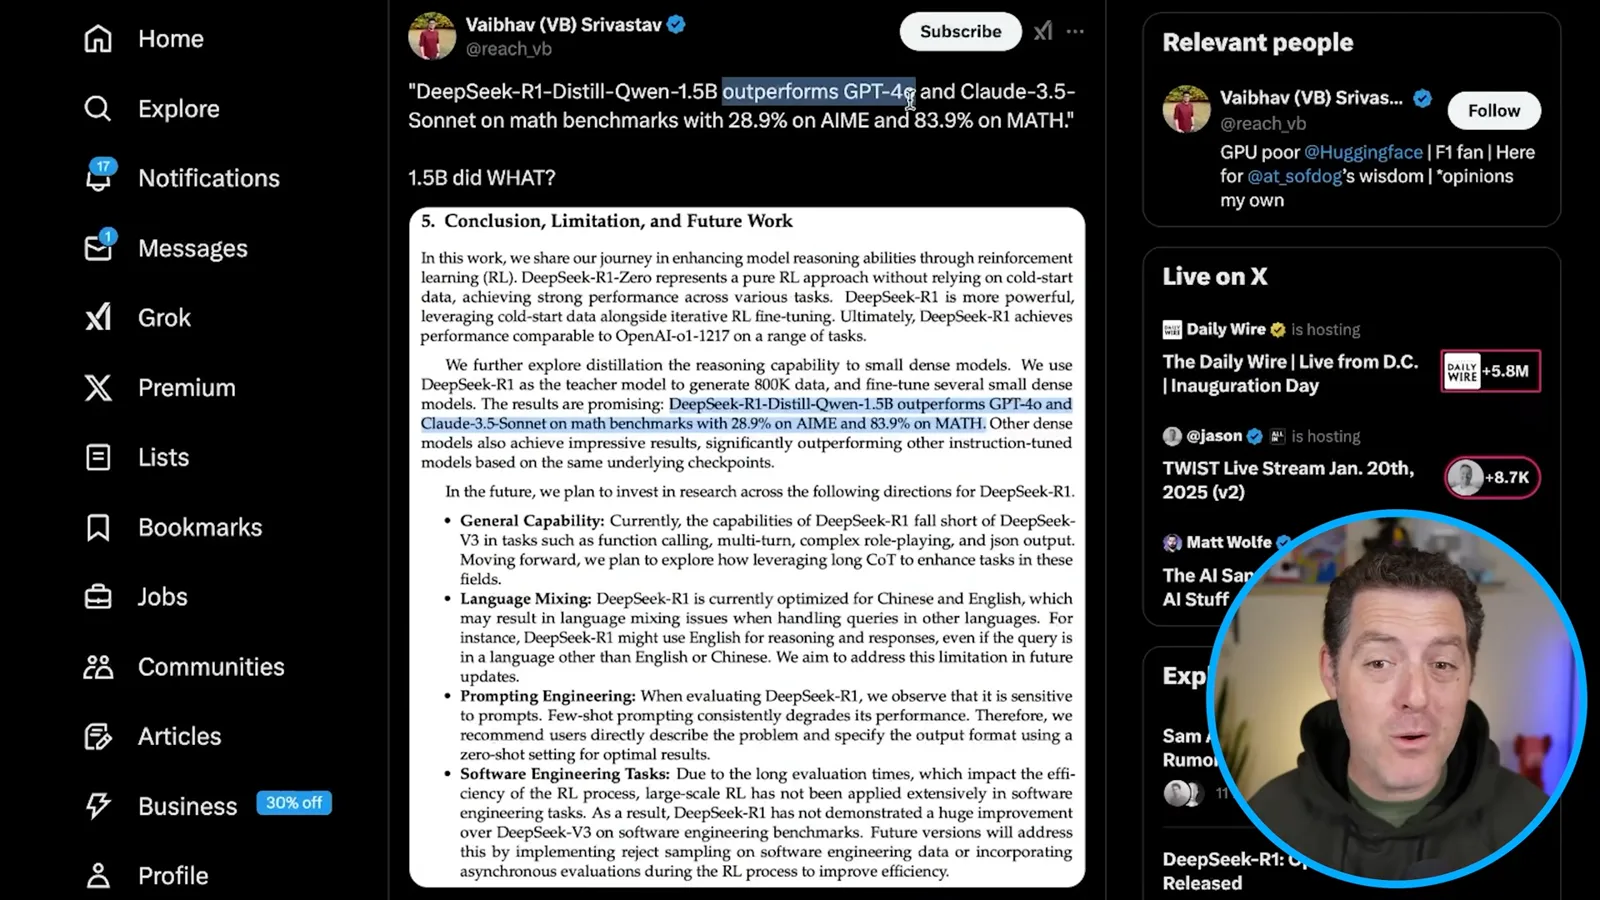
A Hugging Face team member highlights the smaller DeepSeek-R1-Distill-Qwen-1.5B. The DeepSeek paper reports 28.9% on AIME 2024 and 83.9% on MATH-500 for this model, higher than the paper’s GPT-4o and Claude 3.5 Sonnet baselines on those math tests. Those scores do not imply it is better at every task; local speed and memory needs depend on hardware and quantization.
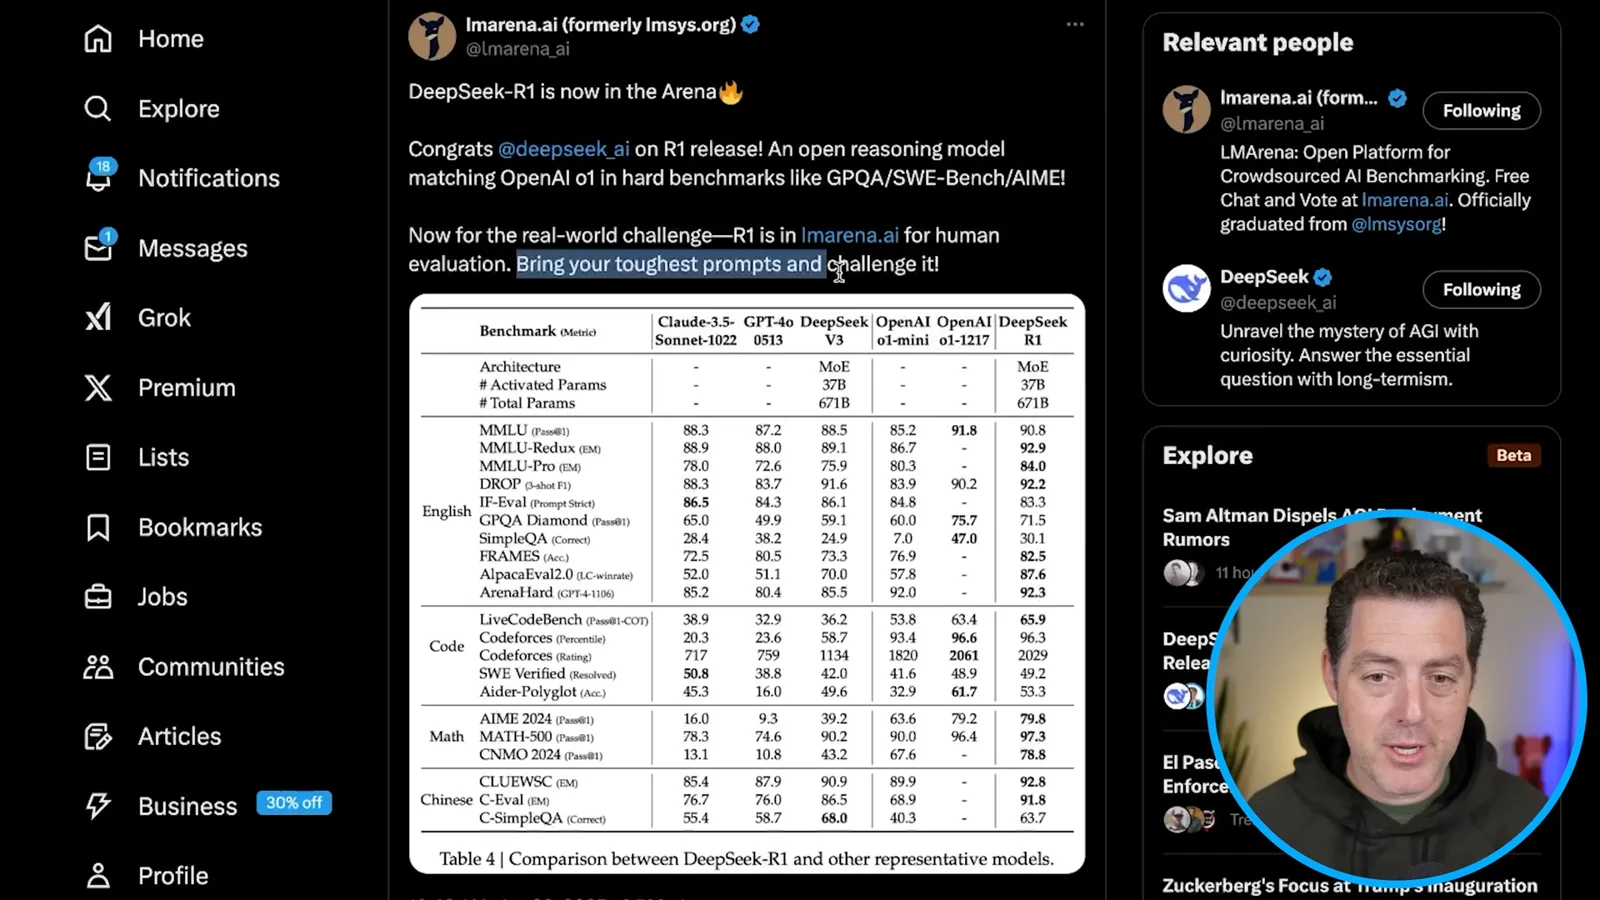
LMArena announced that R1 was available for human evaluation and cited strong results on tests including GPQA, SWE-bench and AIME. The benchmark table shown is from DeepSeek’s evaluation and scores vary by task and model. I imagine an engineer using a smaller or quantized version offline in a coding environment, subject to the available hardware and integration.
Ethan Mollick describes the release as a capable open reasoning model and notes that its smallest variants can run on a laptop. He compares selected benchmark results with o1 while distinguishing them from o1 Pro. Benchmark comparisons are useful signals, not proof that the models are interchangeable in every application.
Industry implications and forecasts
Berman surveys commentary on open models, competition and the speed of future releases.
Dean W. Ball argues that Chinese labs may continue to reach strong benchmark results and that open models have strategic value. He calls for more open releases beyond relying on one company. I agree that making capable models available more widely can matter, while predictions about future models remain uncertain.
Emad Mostaque reacts to R1 with a provocative observation about the economy and jokes about competition among frontier labs. Perplexity CEO Aravind Srinivas also comments on the speed at which reasoning is becoming less expensive. I predict an openly available o3-level model within months; that is my forecast at the time, not an established result.
Coding scores, prices and behavior
He discusses Aider results, a historical API price comparison and questions about refusals and model modification.
Aider founder Paul Gauthier reports R1 at 57% on the Aider polyglot coding benchmark, behind o1 high at 62% in his posted comparison. This reflects the benchmark and configurations used at that time. LM Studio offered distilled variants for local use; I disclose that I am a small investor in LM Studio.
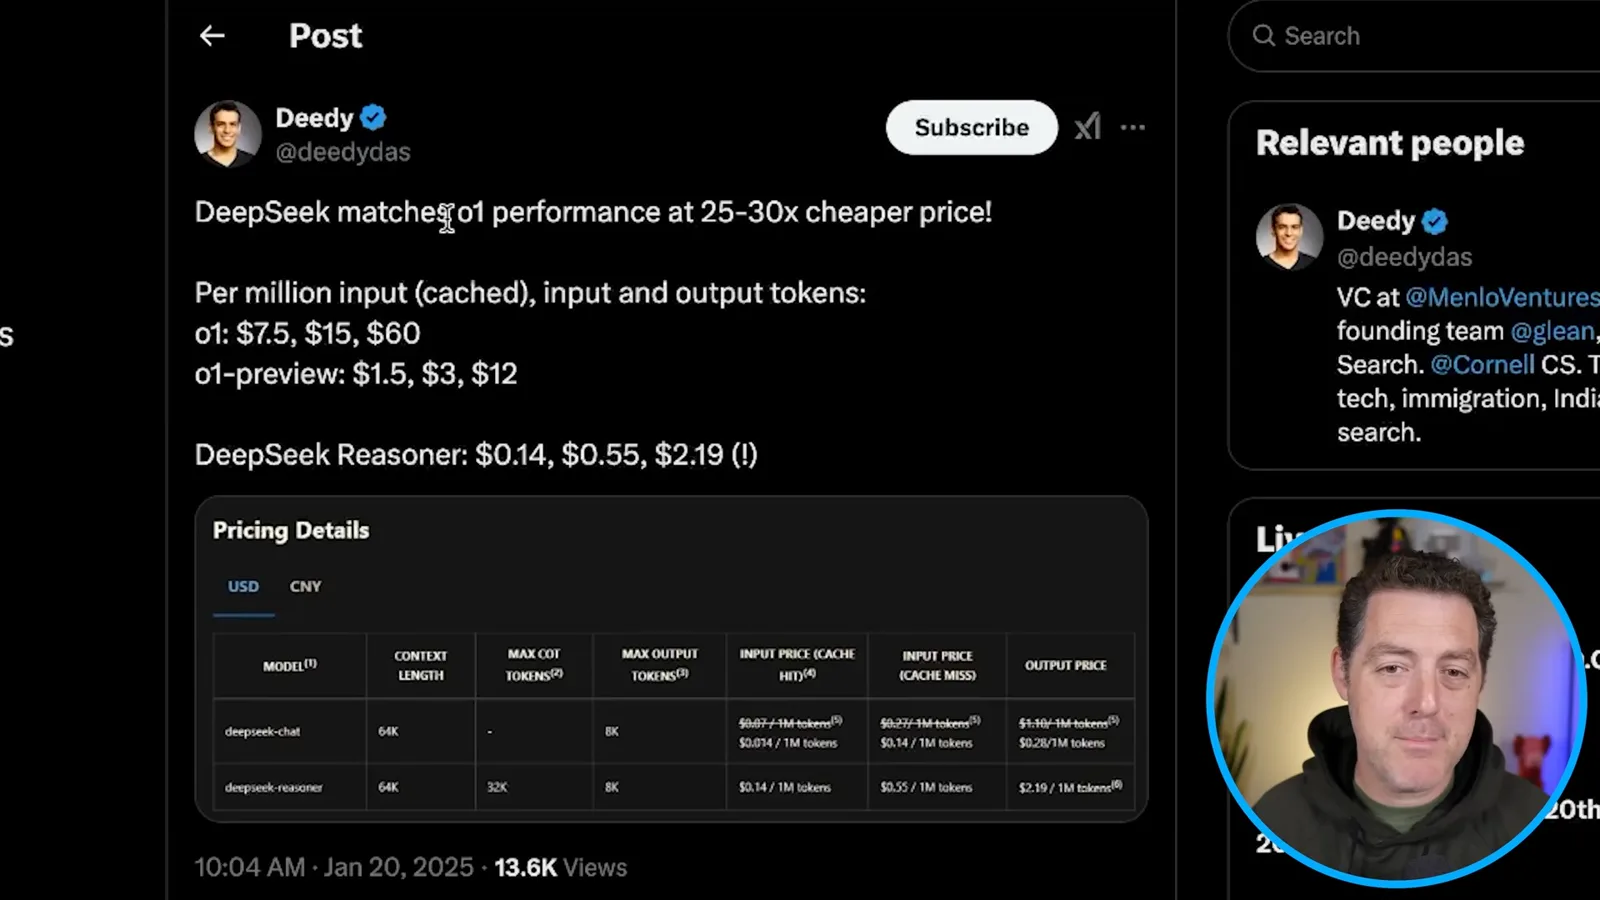
A January 2025 post compares prices per million cached input, uncached input and output tokens: o1 at $7.50, $15 and $60, versus DeepSeek Reasoner at $0.14, $0.55 and $2.19. These are historical posted rates, and the savings depend on token mix, provider and other costs. I think lower prices could make more applications viable, but that market outcome is a prediction.
I raise concerns about refusals on politically sensitive subjects such as Taiwan and Tiananmen Square. Behavior can differ between a hosted service and downloaded or modified weights, prompts and versions. Fine-tuning can change model behavior, but it does not guarantee the removal of every refusal or restriction.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.