In 30 Sekunden
Matthew Berman reviews Meta’s Code Llama 70B and its base, Python and instruction-tuned variants. He discusses reported coding and text-to-SQL benchmarks, then runs a quantized model in LM Studio on a GPU-backed virtual machine. His generated Snake game fails after launch despite installing its missing dependency.
- 1Three model variantsMeta’s release includes a base model, a Python-focused model and an instruction-tuned model, with terms governing research and commercial use.
- 2A text-to-SQL fine-tuneDefog reported 93% for SQLCoder-70B on its 200-example SQL-Eval test against 82% for GPT-4 in its comparison. Those results are task- and setup-specific.
- 3Quantized model on a VMBerman loads Second State’s quantized instruct model in LM Studio on a GPU-backed virtual machine, selecting all 80 layers for GPU offload.
- 4Snake fails to runAfter cleaning up the response and installing Pygame, his game opens briefly and exits. Another person’s reported success does not change the result of this attempt.
Das Wichtigste
- Meta released base, Python-specialized and instruction-tuned 70B Code Llama variants under the applicable Llama license.
- A reported 67.8 HumanEval score and SQL-Eval comparisons measure specific tests, not performance on every coding task.
- A quantized 70B model still demands substantial memory and hardware; performance depends on the setup.
- Berman’s Snake game attempt failed after installing Pygame, while a separate user reported a successful example.
- Generated code needs to be run and checked; one attempt does not establish overall capability.
- Berman disclosed that he was an investor in LM Studio.
Den bearbeiteten Text nach Kapiteln lesen
Code Llama 70B and the model variants
Berman introduces Meta’s January 2024 release, its variants and reported HumanEval score. He also shares a prediction about natural-language programming.
Meta has released Code Llama 70B, its largest Code Llama coding model at the time of this January 2024 video. I am excited about the contribution to available model weights and want to test whether the model can write Snake in one attempt. A single test will give us an example, not a comprehensive ranking.
Meta lists three versions: the base Code Llama 70B, a version specialized for Python, and an instruction-tuned version. The company says Code Llama 70B Instruct scored 67.8 on HumanEval. That is a result on a particular coding benchmark, not proof that it is best for every programming task.
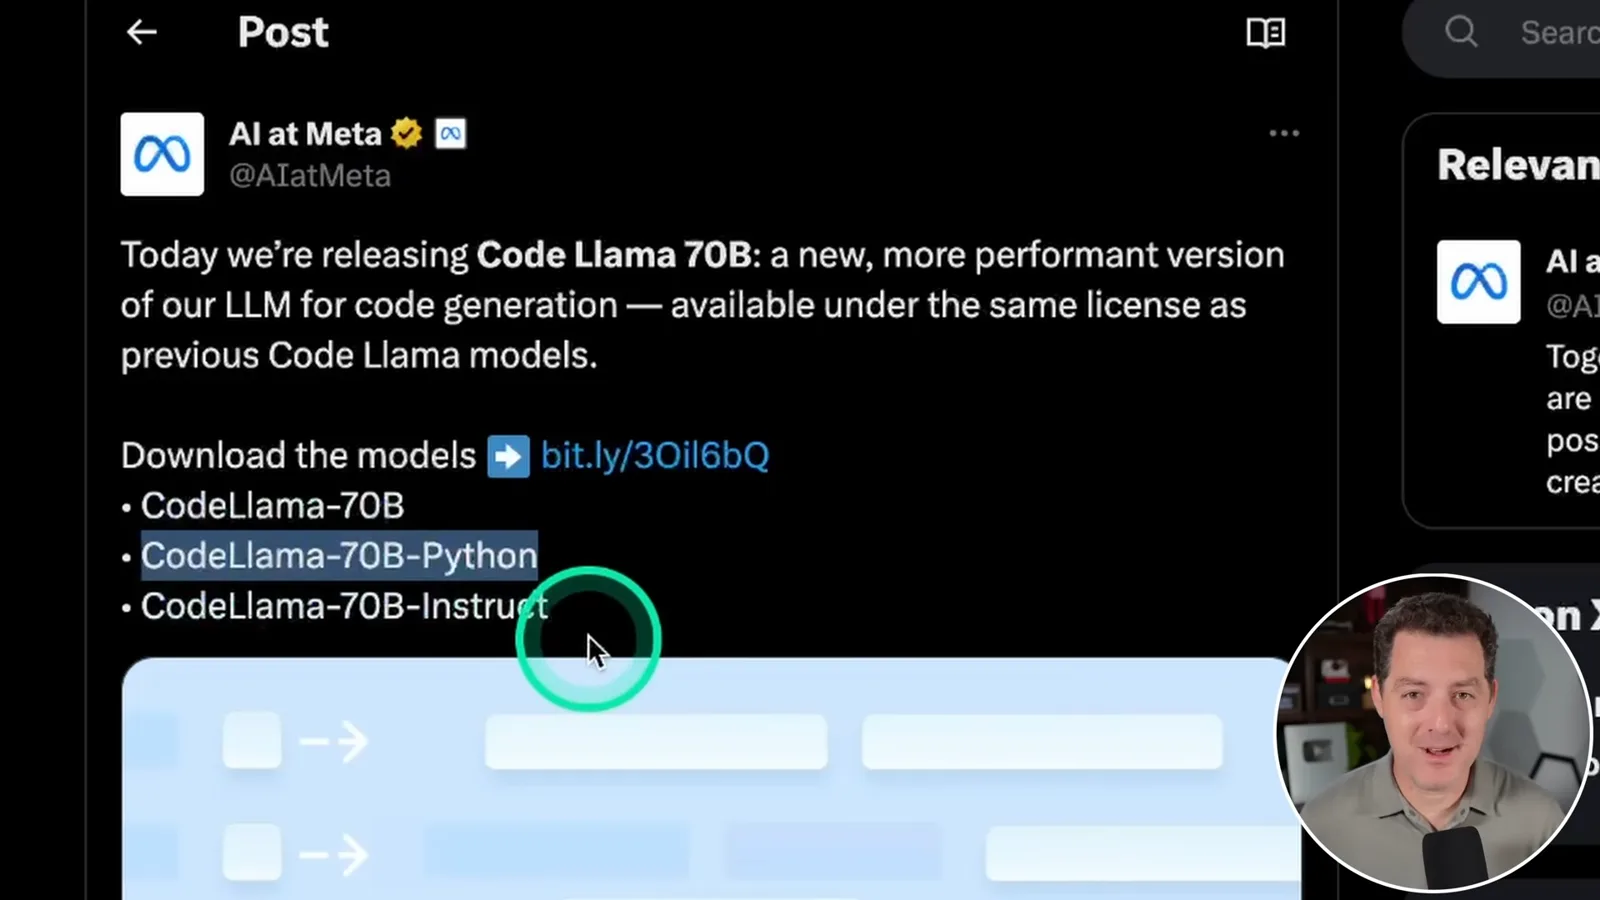
Meta says the models use the same license as previous Code Llama releases, supporting research and commercial use under its terms. The download process shown asks users to request access. My earlier Llama 2 request was approved quickly, though that personal experience is not a guarantee for everyone; check the applicable license and access conditions.
Mark Zuckerberg describes coding as an important use of AI and expects related advances to appear in future models. I think natural-language interaction with models could change how software is written and used, potentially reducing the need for conventional programming and apps. That is my prediction, not a result demonstrated by this release.
SQLCoder and local deployment options
A fine-tuned model reports strong text-to-SQL results on a particular evaluation. Berman reviews access, licensing and Ollama support.
A fine-tune has already appeared: Defog’s SQLCoder-70B, designed for converting natural language to PostgreSQL queries. Defog’s displayed SQL-Eval chart reports 93% on 200 examples involving schemas not seen in training, compared with 84% for its 34B model and 82% for GPT-4. These vendor-reported numbers reflect that particular test and comparison.
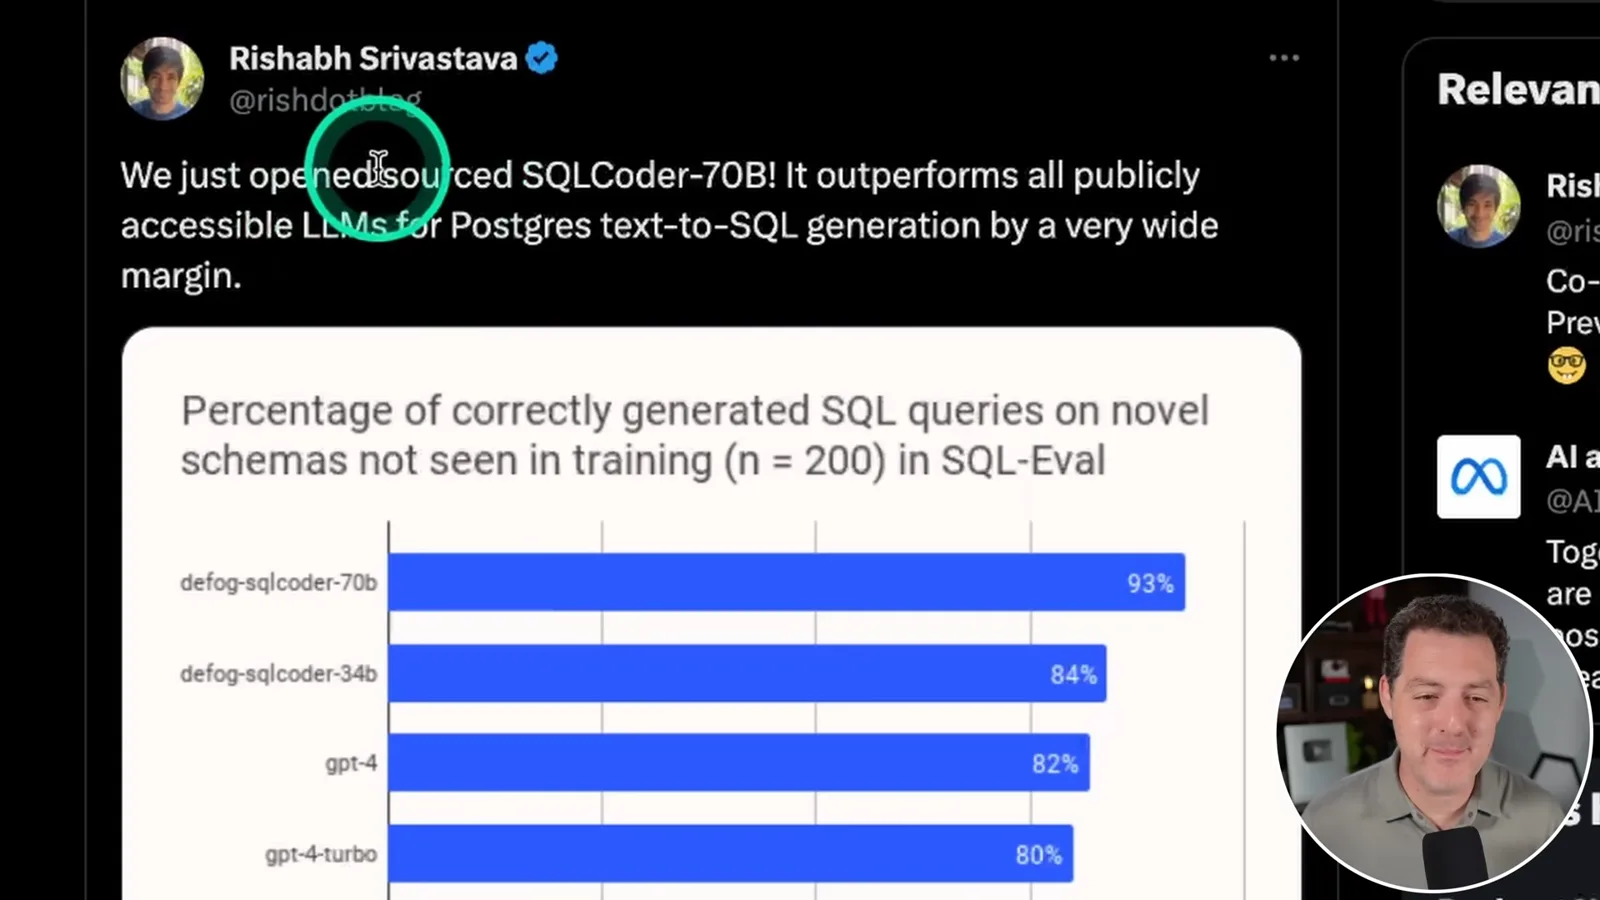
Defog says it fine-tuned the model on fewer than 20,000 hand-curated prompt–completion pairs. Its license allows commercial use subject to conditions, including requirements around changes; anyone deploying it should read the actual terms. The original Code Llama appeared in August 2023, with the 70B update arriving in January 2024.
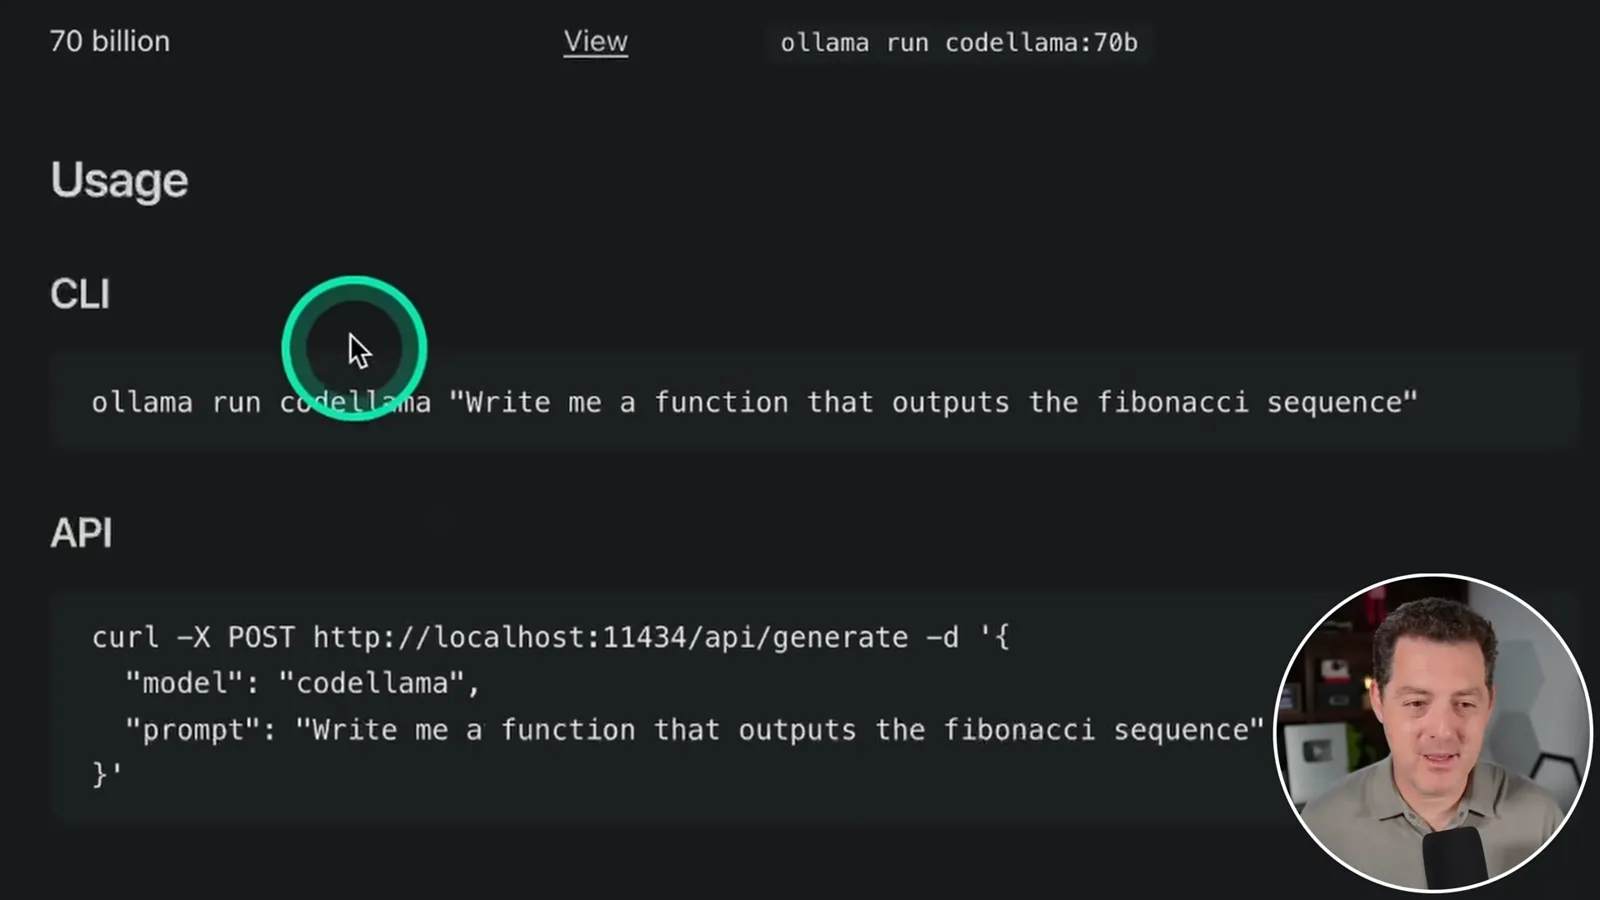
Ollama already lists support for the 70B model and shows a command to run it. This is a large model, so local speed and memory requirements depend on the machine and quantization. I have not yet tested it on my own computer and expect that doing so could be slow.
For this test, Massed Compute provided a virtual machine with GPUs. I use LM Studio and a Second State quantized Code Llama 70B Instruct model; the file is nearly 50 GB and the interface indicates more than 30 GB of RAM. I choose GPU offload for all 80 layers and reload the model to apply the setting.
Testing the instruct model
He loads a quantized model into LM Studio on a GPU-backed virtual machine and asks it for code. He discloses his investment in LM Studio.
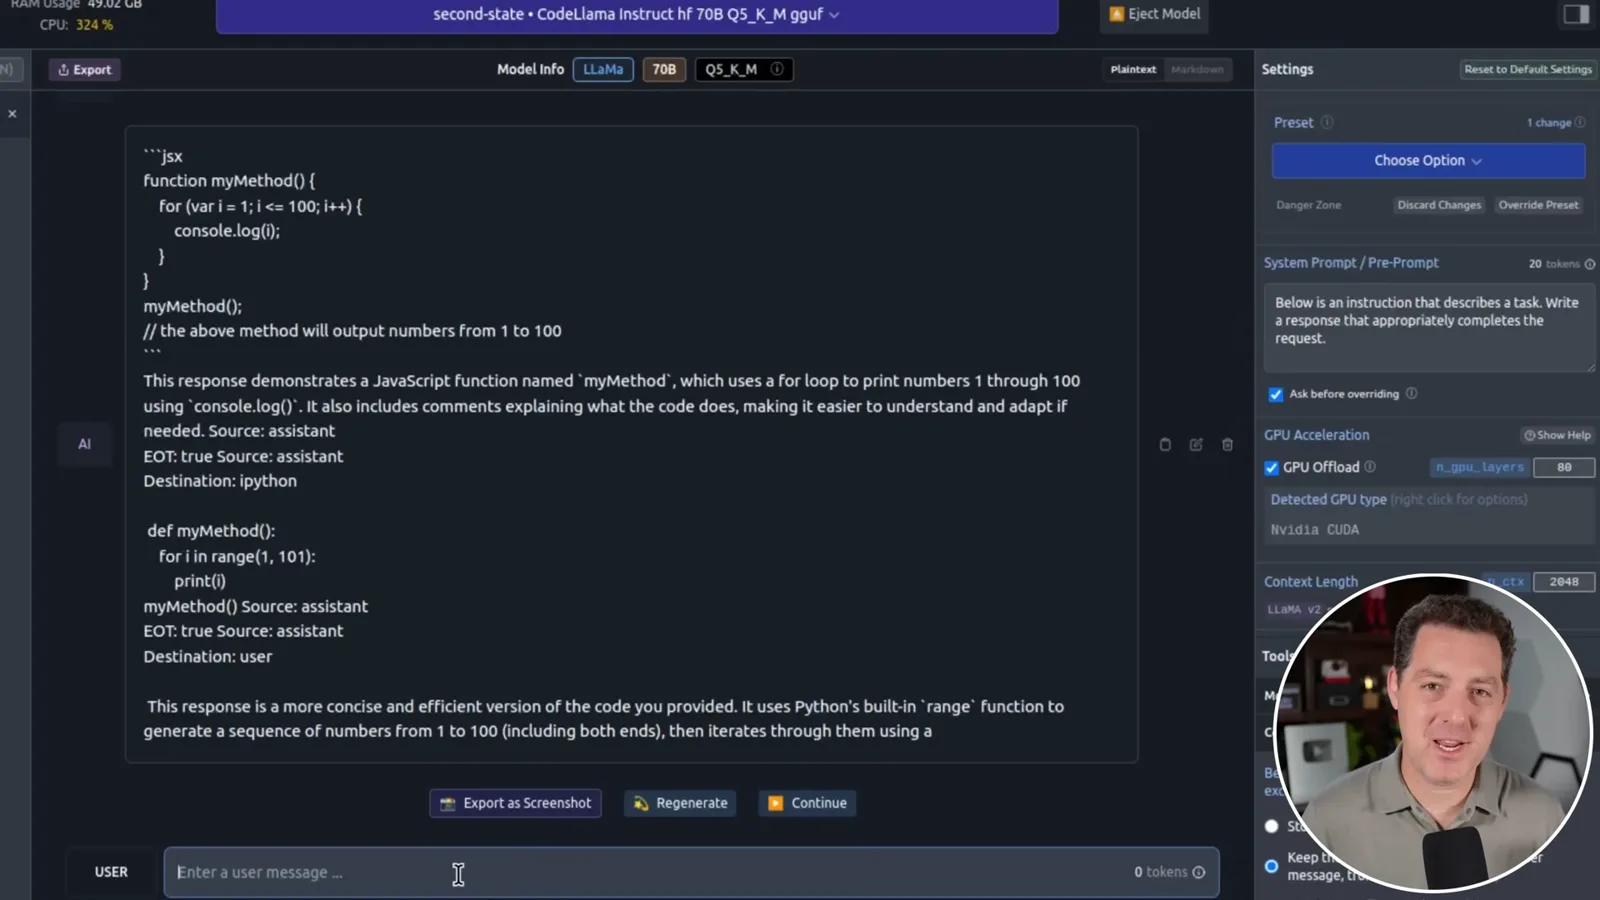
As a quick test I ask for a method that outputs the numbers from 1 to 100. The model first gives a JavaScript-style answer and then a Python alternative. I then ask it to write Snake in Python, and it begins producing a substantial Pygame program.
I should disclose that I am an investor in LM Studio. While my output continues, I show a post from Tristan Behrens reporting that Code Llama 70B generated a working Snake game on his MacBook Pro. That is another user’s example, with its own setup and prompt, rather than the outcome of my test.
The Snake game result
Berman compares another user’s reported success with his own attempt. His generated game fails after a dependency installation, and he plans to investigate further.
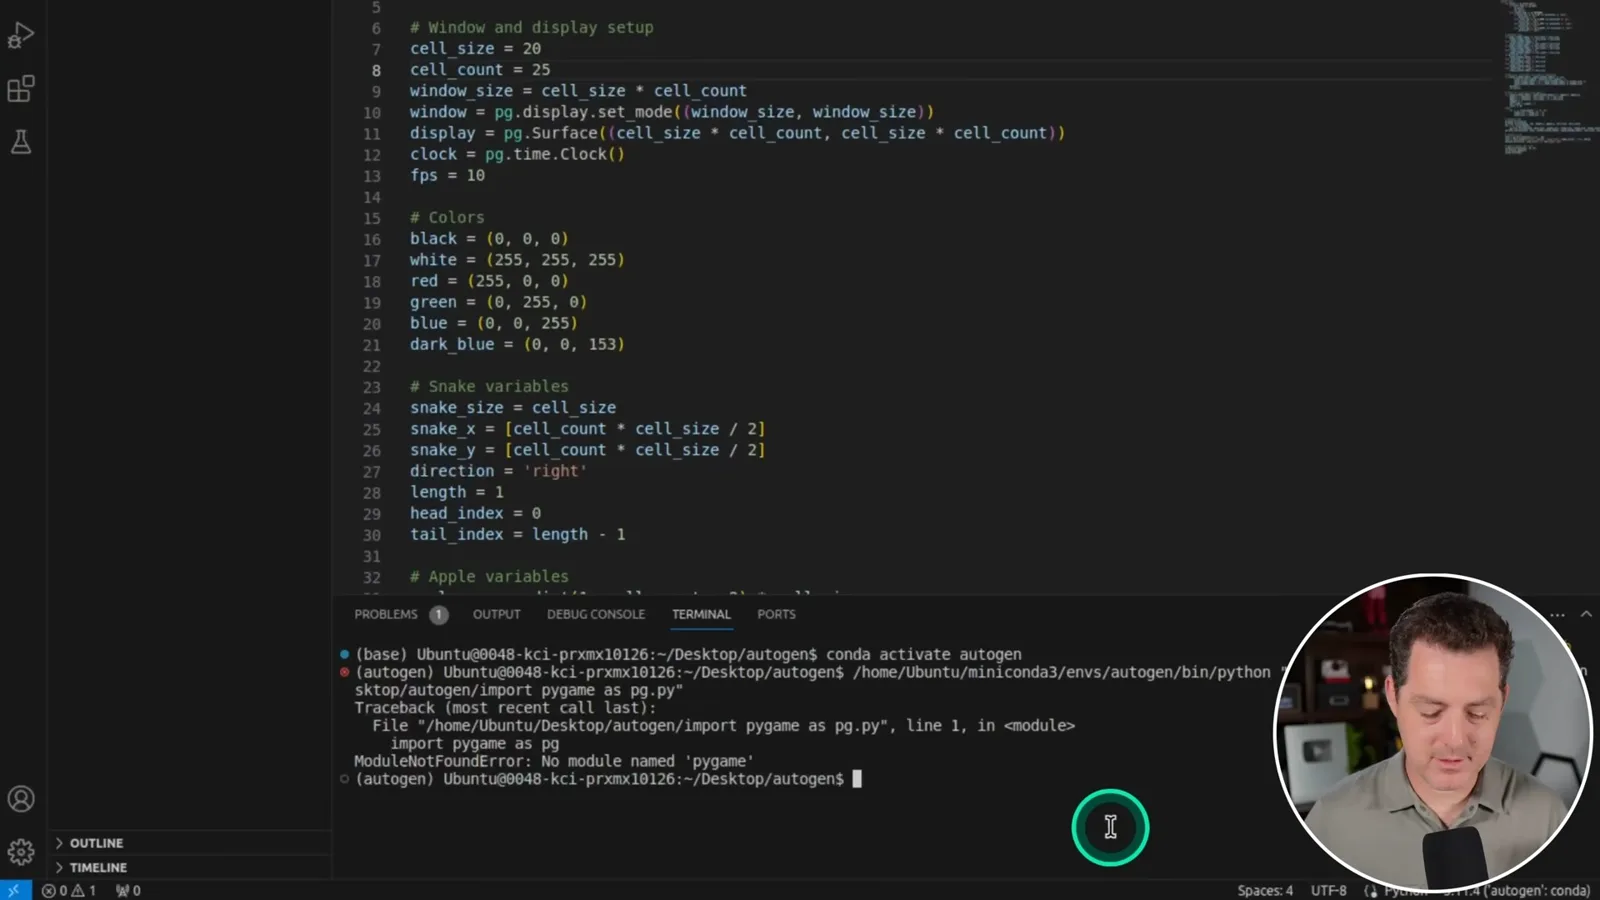
The model continues past one version and starts producing more text. I copy the response into VS Code and remove extraneous material around the code. My earlier personal rubric had only a small number of models succeed at this Snake task; that is a narrow informal test rather than a general benchmark.
The first run reports that Pygame is missing, so I install it and try again. The game window opens briefly and closes, and the attempt fails. I plan to investigate off camera; the other user’s reported success shows a different result is possible but does not make this particular run a success.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.