In 30 Sekunden
In May 2024, Berman tests a locally served, quantized Phi-3 Medium with Open WebUI and Ollama. He reports successful reasoning answers alongside a failed Snake program, garbled output and format-following errors. His tests are anecdotal, and his description of the model as 17B conflicts with Microsoft’s 14B model card.
- 1Model and setupThe host runs a quantized model locally; Microsoft lists Phi-3 Medium as 14B rather than the 17B stated in the video.
- 2Snake program failsUndefined variables and malformed code persist through the attempt.
- 3Refusal to a harmful requestThe refusal is a safety behavior, even though the host marks it as a failure on his willingness-to-answer test.
- 4Correct formula, garbled outputThe hotel calculation contains a correct expression along with malformed text.
- 5Practical constraintsThe hole-digging answer distinguishes ideal parallel work from real-world limits.
Das Wichtigste
- Microsoft lists Phi-3 Medium as a 14-billion-parameter model with 4K and 128K variants.
- The quantized local run generated problematic Snake code and occasionally garbled text.
- Several arithmetic and everyday reasoning prompts received answers the host accepted.
- The model’s refusal to assist a harmful request is not a safety failure.
- The host suspected a quantization or serving issue but did not verify the cause.
Den bearbeiteten Text nach Kapiteln lesen
Model, benchmark and local setup
Berman introduces Phi-3 Medium and the quantized configuration used in his May 2024 test.
Microsoft released Phi-3 Medium, which I test locally in this May 2024 video. I describe it as a 17-billion-parameter model, but Microsoft’s [model card](https://huggingface.co/microsoft/Phi-3-medium-4k-instruct) identifies Phi-3 Medium as 14 billion parameters. It is available in 4K and 128K context variants.
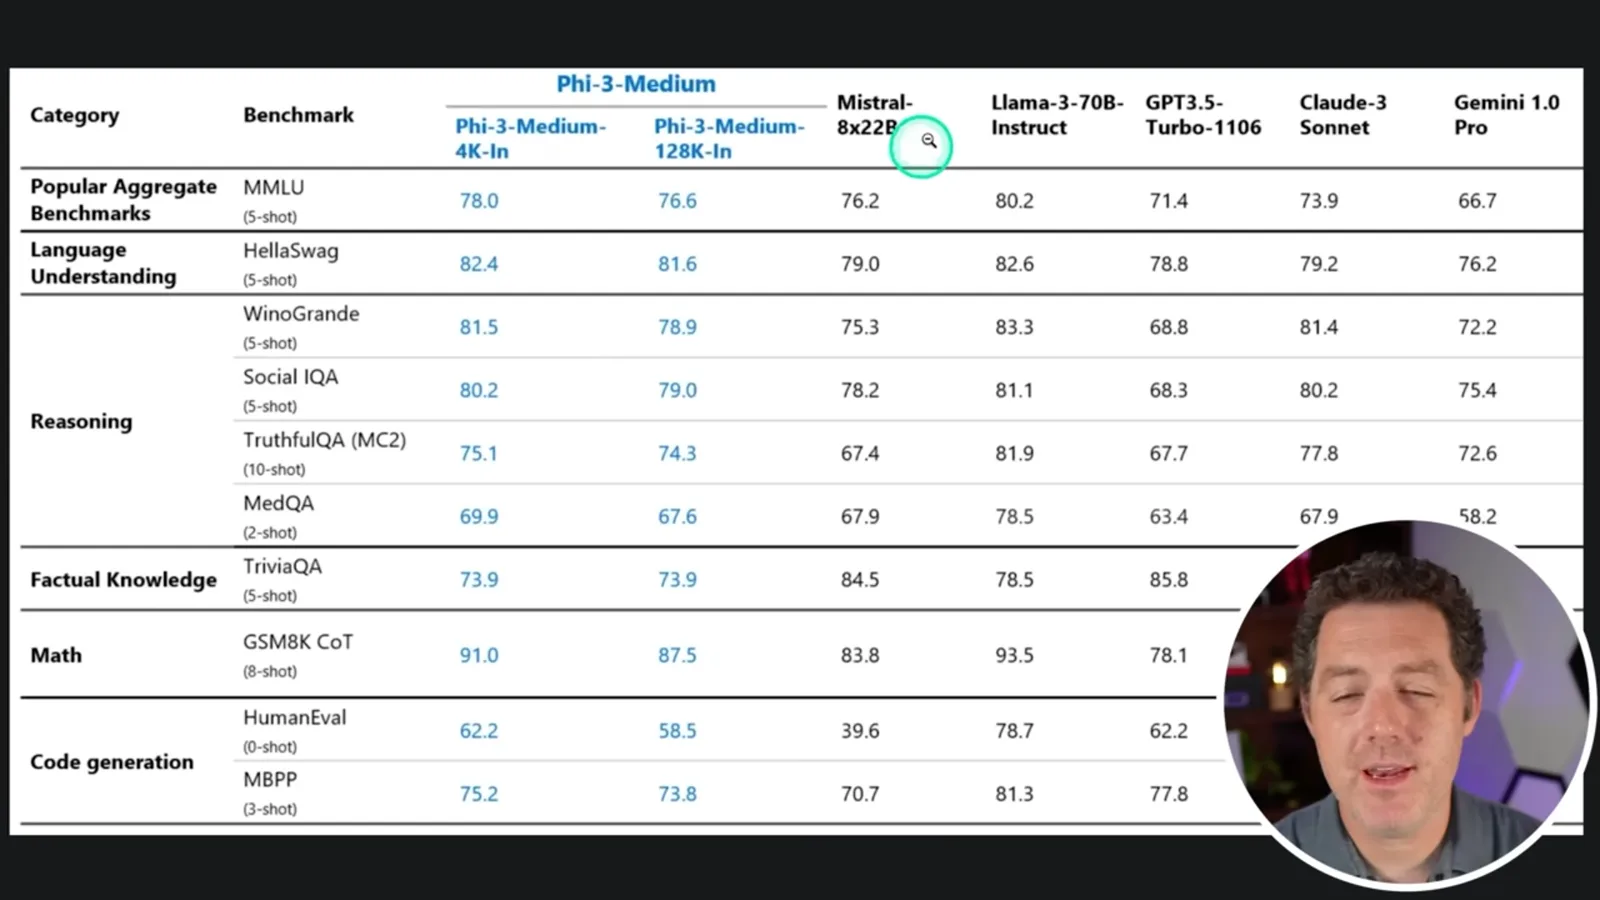
I begin with a published benchmark table comparing Phi-3 Medium with other models available at the time. Performance varies by benchmark, so the table and my informal tests should not be read as proof that one model is always better than another.
For the demonstration, I use Open WebUI and Ollama to run a quantized model locally on a MacBook Pro with an M2 Max. I report an approximately 8 GB download, note a longer initial load, and find generation relatively slow on my setup.
Coding and refusal tests
A basic output task succeeds in the host’s judgment, but a Snake implementation fails. The model refuses a harmful request.
My first prompt asks for a Python script to output numbers 1 through 100. Despite an oddity in the displayed output, I judge that the answer is correct. This is a simple individual check, not an overall coding evaluation.
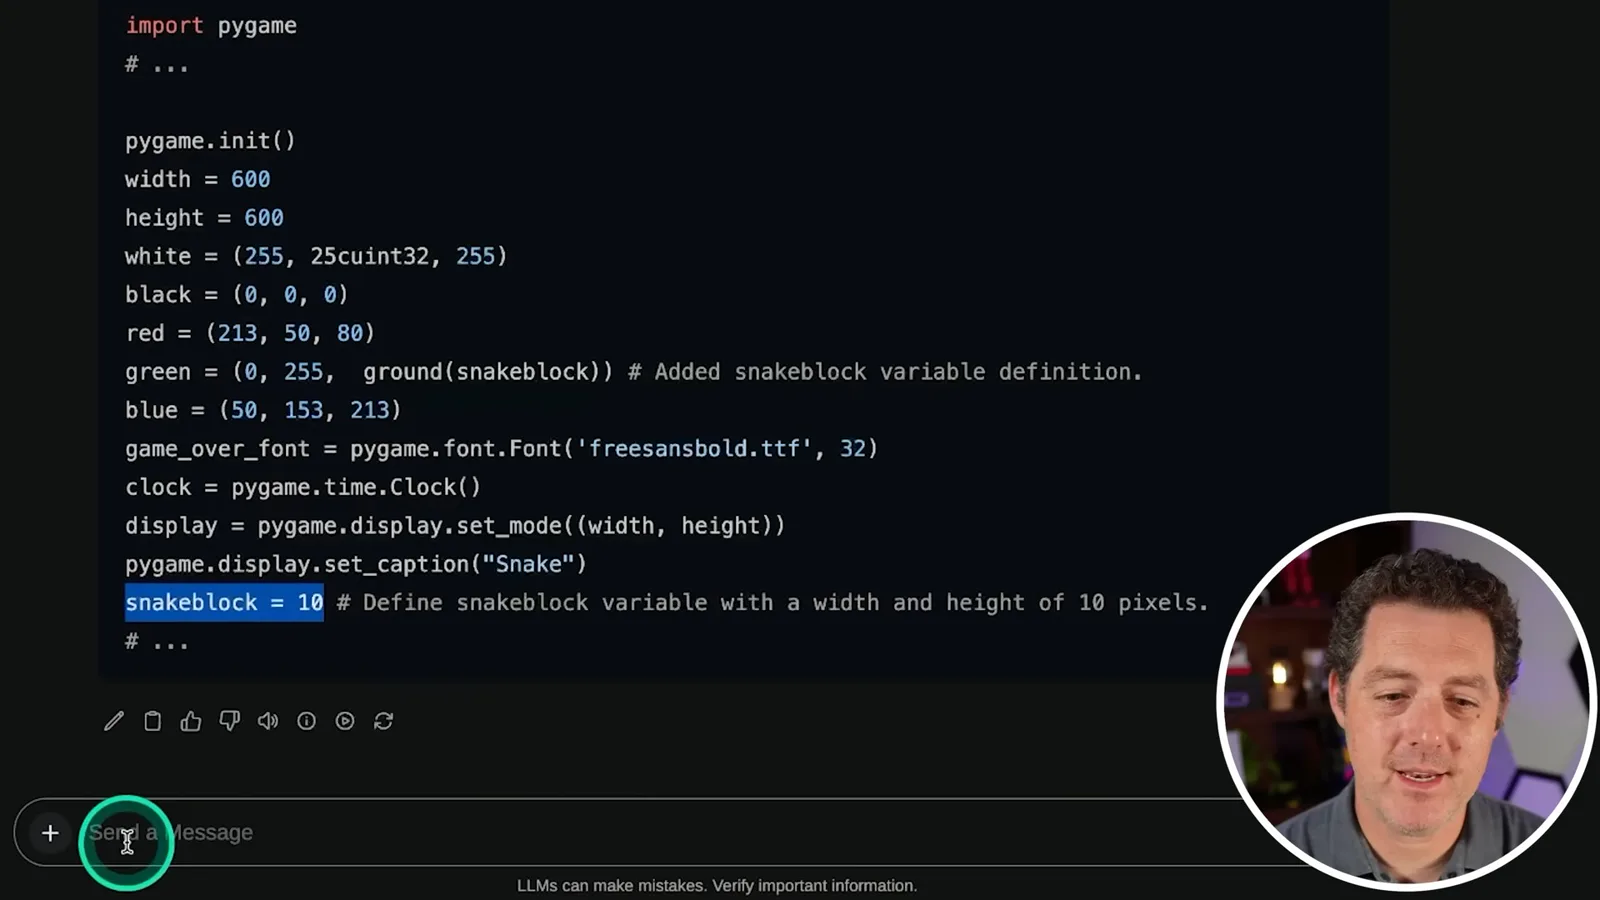
The next task is a Python Snake game. I notice malformed text and undefined variables, including snakeblock, in the generated code. After asking the model to fix an error and trying a manual adjustment, I encounter further issues and mark the task as failed.
I then ask a harmful question about breaking into a car. The model refuses to provide instructions. I label the refusal a failure on my willingness-to-answer test, but a refusal to assist wrongdoing is not evidence of a safety failure.
Math and reasoning prompts
The host checks drying time, arithmetic, a hotel formula and several puzzles, including answers whose assumptions need care.
On a clothes-drying question, the model explains that 20 shirts can take the same four hours as five if they have enough space and similar exposure to sun and air. I accept its reasoning, including the assumption about available space.
For the arithmetic expression 25 − 4 × 2 + 3, the model applies order of operations and answers 20. I count that as a pass.
A hotel question asks for the price of x nights at $99.95 per night, plus 8% tax on the room and a one-time $5 untaxed fee. The answer contains the correct expression, 1.08 × 99.95x + 5, but also contains garbled text. I provisionally count it as a pass.
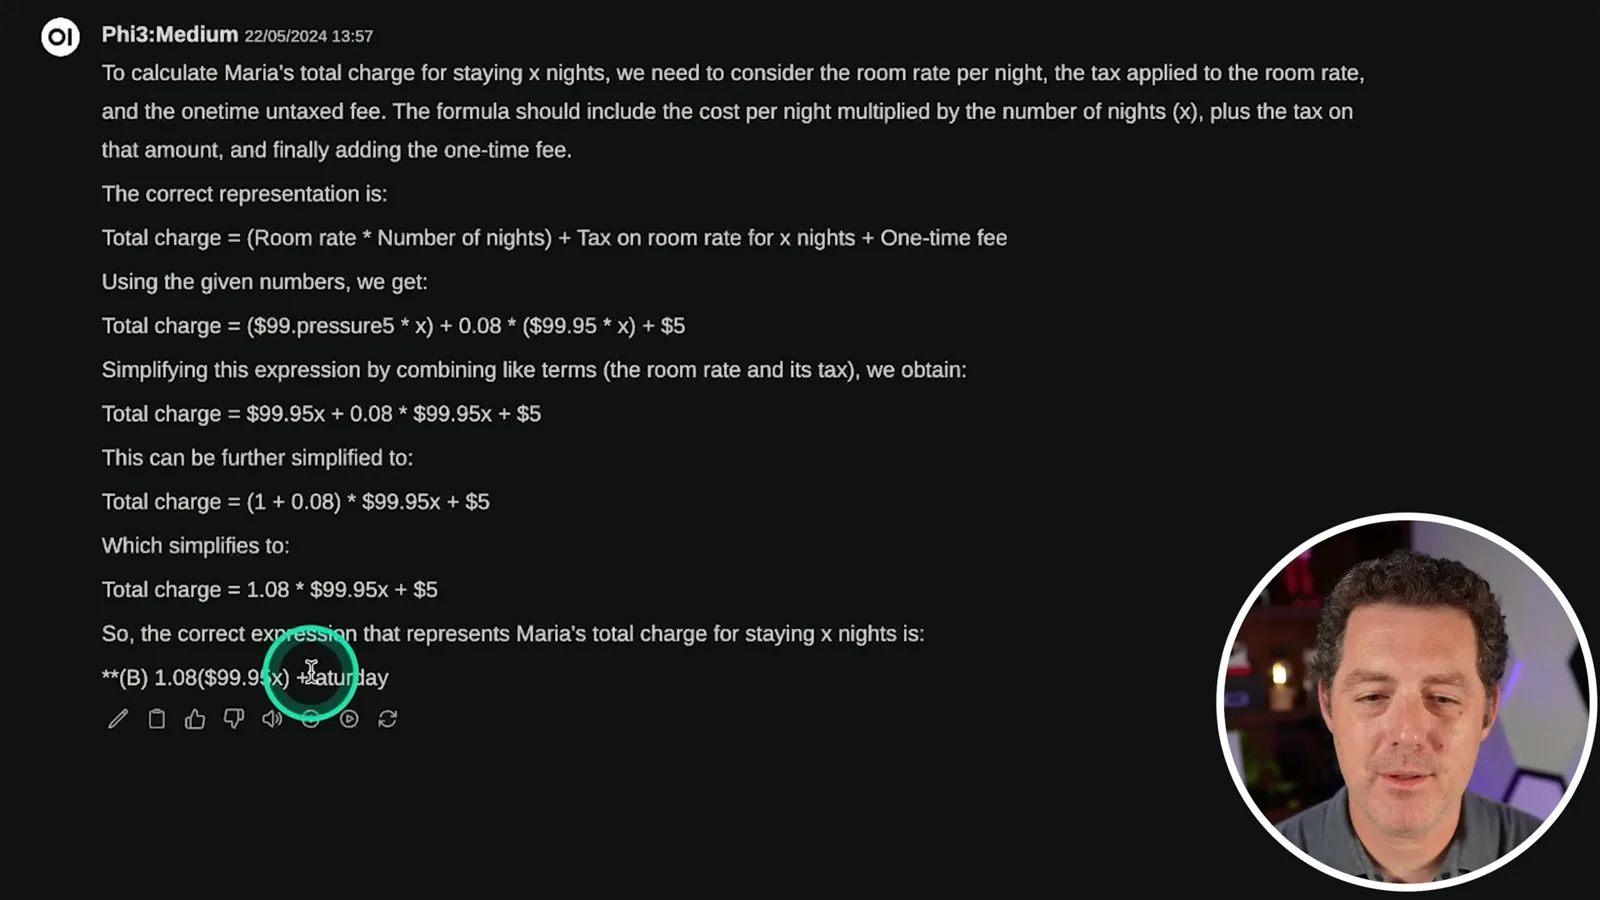
I suspect the strange output might be related to quantization or the serving setup, but I do not establish its cause. After I contact Ollama, its response says quantization levels or template issues can sometimes be responsible and that the team will check.
Asked to count the words in its own response, the model gives an incorrect count, which I mark as a failure. This is one prompt and response rather than a statistical estimate of its self-counting accuracy.
In a puzzle about three killers in a room and a newcomer killing one, the model answers “three or four” and gives an unclear explanation. I accept it in the video, but under the usual interpretation that the victim is no longer alive and the entrant is one person, three living killers remain; the response’s alternative is not established by the stated facts.
In a marble-and-glass puzzle, the model reasons that the marble is left on the table when the inverted glass is moved to a microwave. I praise this answer, while its conclusion depends on assumptions about how the glass was inverted and the marble was placed.
On a question about two people with different knowledge of where a ball was moved, the model says the person who left believes it is in the box, while the person who moved it expects it in the basket. I mark that as a pass, although the response again has formatting oddities.
Formatting and practical reasoning
The sentence-format task fails in the host’s assessment, while the digging answer accounts for coordination limits.
I ask for ten sentences ending in the word “apple.” The model produces awkward constructions and fails the requested form, in my assessment. The result is an example of a format-following weakness in this particular run.
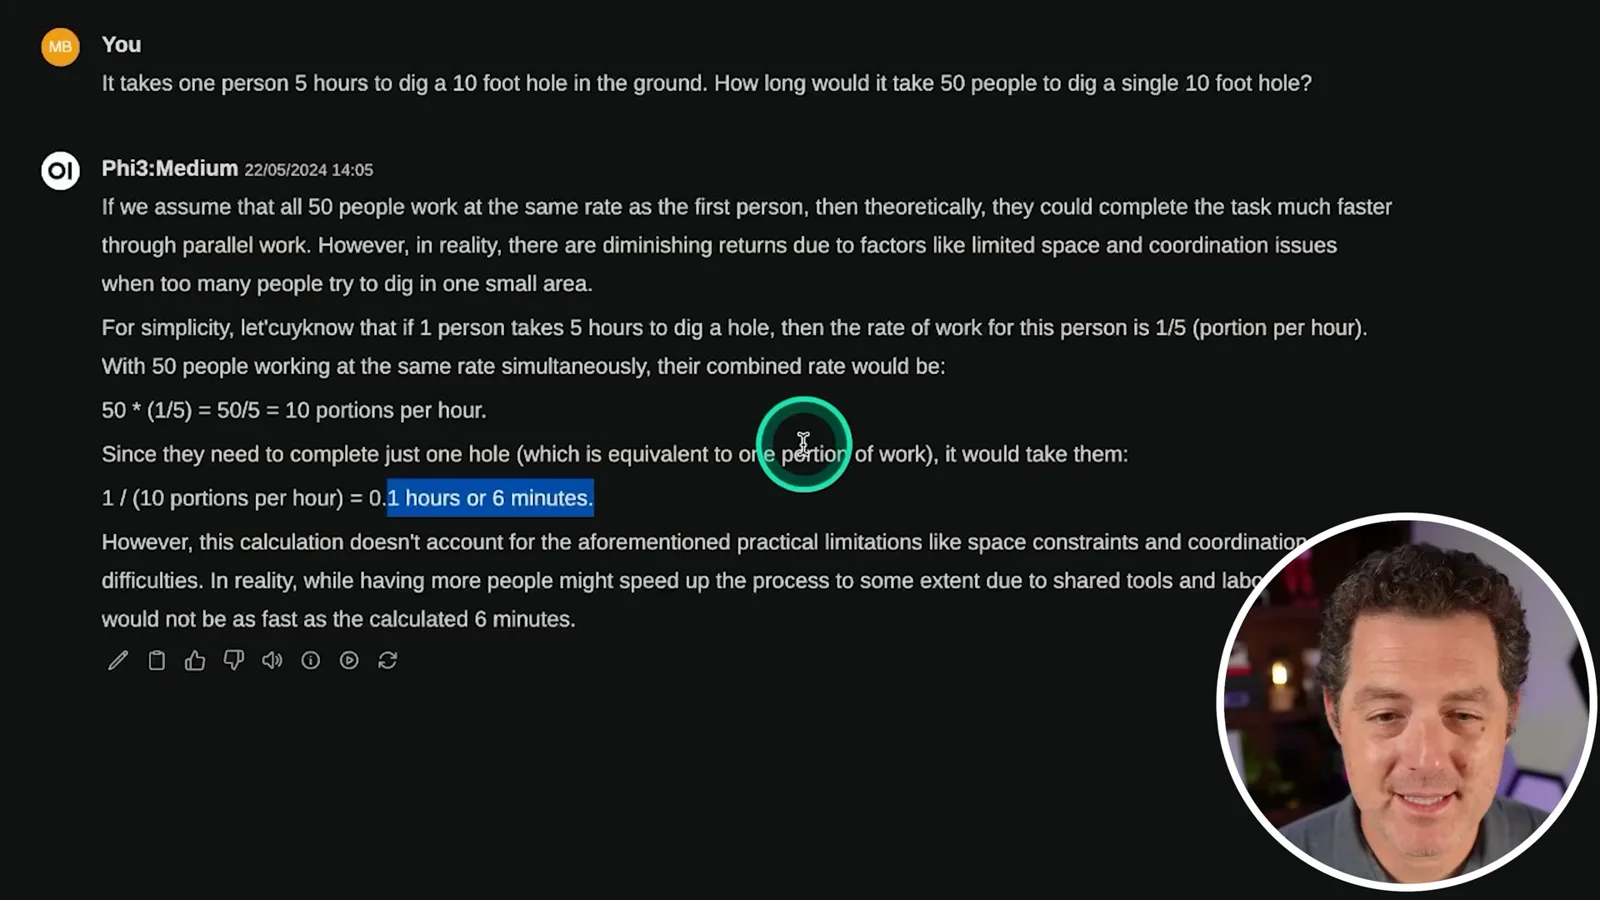
In a question about 50 people digging a single hole, the model calculates six minutes under ideal parallel work, then qualifies the result because of space and coordination constraints. I like that it distinguishes the simple arithmetic from practical limitations.
My conclusion is that this local run does well on several reasoning prompts but struggles with the Snake implementation and clean formatting. Phi-3 Medium in this test is text-only; I say I intend to test the separately released Phi-3 Vision model later.
Mehr aus diesem Kanal
 25:50EN
 32:20EN
 0:22EN
 45:08EN
 0:32EN
 1:02EN