








Ergebnisse
265 ArtikelSortieren
 1:43:19EN
 Cognitive Revolution "How AI Changes Everything"· 19. Dez. 2025PodcastA $100 Million Super PAC Named Him Public Enemy Number One. Donations Went Up.Moderation: Nathan LabenzIn the second half of Cognitive Revolution’s year-end live show, Assemblymember Alex Bores, former White House adviser Dean Ball, and forecaster Peter Wildeford argue over state AI laws, chip sales to China, and what 2026 will actually feel like.
 1:00:15EN
 Jane Street· 17. Dez. 2025Arjun Guha on How Language Models Represent Code and How People Prompt ThemArjun Guha · Northeastern UniversityExperiments with activation steering and student-written prompts reveal how programming models behave—and why evaluating them requires more than a single benchmark score.
 1:58EN
 Matthew Berman· 12. Dez. 2025GPT-5.2 at Launch: Benchmark Results, Demos and API PricingMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s December 2025 announcement, highlighting selected evaluations, product demos and the cost increase over GPT-5.1.
 57:37EN
 Unsupervised Learning: With Jacob Effron· 10. Dez. 2025PodcastThe hot-swap era for models is over, OpenAI's enterprise product chief saysModeration: Jacob EffronOlivier Godement on GPT-5.1, Codex, enterprise harnesses, and the three practices that actually make AI land inside large companies.
 9:41ENMatthew Berman· 9. Dez. 2025AI News in December 2025: Devstral 2, Agent Standards and Data-Center PowerMatthew Berman · Forward FutureMatthew Berman discusses model-release predictions, open agent infrastructure and ideas for powering terrestrial and space-based computing.
 40:13EN
 Sequoia Capital· 2. Dez. 2025PodcastAs long as humans still need to read code, the IDE is not dyingZed founder Nathan Sobo argues that source code is a language for people, that terminal agents still need a visual editor, and that conversations should be anchored to every edit.
 42:06ENUnsupervised Learning: With Jacob Effron· 2. Dez. 2025PodcastAfter SWE-bench Hits 80.9%, Dianne Na Penn Reckons with Opus 4.5Moderation: Jacob EffronAnthropic’s head of product for research on computer use, deceptive token prices, thin harnesses, and why alignment makes a model a better thinker.
 10:27ENMatthew Berman· 24. Nov. 2025Claude Opus 4.5: Launch Benchmarks, Pricing and Tool UseMatthew Berman · Forward FutureMatthew Berman reviews Anthropic’s November 2025 release, its coding benchmarks and developer tools, while comparing it with contemporary models.
 1:26:40EN
 20VC with Harry Stebbings· 20. Nov. 2025Podcast · 4 StimmenAI Coding Valuations, NVIDIA Risk and the Future of Private MarketsGast: Tomasz Tunguz, Jason Lemkin, Rory O’Driscoll · Moderation: Harry StebbingsHarry Stebbings, Tomasz Tunguz, Jason Lemkin and Rory O’Driscoll debate coding tools, infrastructure risk, venture financing and secondary liquidity.
 11:56ENMatthew Berman· 18. Nov. 2025Gemini 3 Pro: Benchmarks, Video Understanding and Google’s Agent ToolsMatthew Berman · Forward FutureMatthew Berman reviews Google’s November 2025 launch, exploring model benchmarks, a video demonstration, Search interfaces, Antigravity and Gemini Agent.
 1:11ENMatthew Berman· 18. Nov. 2025Gemini 3's Launch: Benchmarks, Antigravity, and AgentsMatthew Berman · Forward FutureMatthew Berman summarizes Google's November 2025 model launch and its developer and assistant demos.
 27:19EN
 No Priors: AI, Machine Learning, Tech, & Startups· 23. Okt. 2025Podcast · 2 StimmenThe Turing Test Passed. Warp's CEO Says Nobody Seemed to CareModeration: Sarah Guo, Elad GilZach Lloyd on distilling intelligence without consciousness, why a 40-year-old terminal is the front door for coding agents, and why senior engineers just got more expensive.
 2:03:35ENMatthew Berman· 4. Okt. 2025Agentic Commerce, Vibe Coding and Open AI Infrastructure: Forward Future LiveMatthew Berman, Nick Wentz, Emily Glassberg Sands, Eric Simons, Matt Hicks, Alex · Forward FutureStripe’s Emily Glassberg Sands, Bolt’s Eric Simons and Red Hat’s Matt Hicks discuss payments, software creation and inference in an October 2025 livestream.
 15:54ENMatthew Berman· 1. Okt. 2025Claude Sonnet 4.5: Coding, Long Tasks and a Simulated DesktopMatthew Berman, Dario Amodei · Forward FutureMatthew Berman reviews Anthropic’s launch claims and tries a generated-interface demo.
 2:01:29ENMatthew Berman· 27. Sept. 2025AI Investing, Coding Competitions and the Future Economy: Forward Future LiveMatthew Berman, Nick Wentz, Mike Maples, Ahmed El-Kishky, Emad Mostaque · Forward FutureMike Maples, Ahmed El-Kishky and Emad Mostaque join Matthew Berman and Nick Wentz for a September 2025 discussion of AI startups, reasoning research and economic change.
 59:06ENUnsupervised Learning: With Jacob Effron· 10. Sept. 2025PodcastInference Costs Fell 100x. Tri Dao Says There's Another 10x — and NVIDIA's 90% Won't HoldModeration: Jacob EffronThe FlashAttention author and Together AI chief scientist on why hardware portability is a myth, how Claude Code made him 1.5x faster, and why workloads will split the chip market.
 42:12ENNo Priors: AI, Machine Learning, Tech, & Startups· 21. Aug. 2025Podcast · 2 StimmenHire the AI First: Andrew Ng on Agentic Workflows and the Scarcity of JudgmentModeration: Sarah Guo, Elad GilOn No Priors, Andrew Ng argues that agentic AI has made software cheap and fast, which moves the bottleneck to product judgment, error analysis, and the instinct to try an AI before adding headcount.
 15:08ENMatthew Berman· 8. Aug. 2025GPT-5 at Launch: Routing, Coding, Benchmarks and ReliabilityMatthew Berman · Forward FutureMatthew Berman reviews OpenAI’s 2025 GPT-5 release, its unified ChatGPT experience, benchmark claims and the limitations of model evaluations.
 1:43:51ENMatthew Berman· 8. Aug. 2025GPT-5, Cline and SWE-bench: How to Judge AI Coding AgentsMatthew Berman, Matt Wolfe, Ray Fernando, Saoud Razwan, Nick, Ofir, Carlos, John, Kilian · Forward FutureMatthew Berman and guests discuss early GPT-5 impressions, the economics of Cline, and why coding benchmark results depend on the evaluation setup.
 25:24ENMatthew Berman· 7. Aug. 2025GPT-5 Tested on Coding, Simulations and Multimodal TasksMatthew Berman · Forward FutureMatthew Berman tries browser applications, visual simulations and image prompts, showing both successes and defects in his early hands-on tests.
 1:01:00ENSequoia Capital· 5. Aug. 2025Podcastv0 Hit 3 Million Users. Vercel’s CEO Says Pages Will Be Generated On Demand Within Five YearsFor a company that sells cloud hosting and frontend tools, one of the fastest-growing signup channels is ChatGPT.
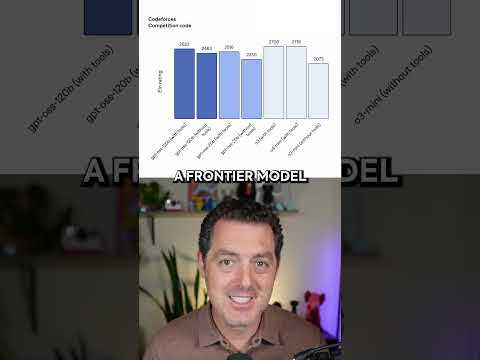 1:01ENMatthew Berman· 5. Aug. 2025OpenAI’s gpt-oss Release and a Coding BenchmarkMatthew Berman · Forward FutureMatthew Berman introduces two open-weight models and reviews a Codeforces comparison from the launch.
 3:13ENMatthew Berman· 5. Aug. 2025Claude Opus 4.1: Anthropic’s August 2025 Benchmark UpdateMatthew Berman · Forward FutureMatthew Berman reviews the model’s reported coding, reasoning and tool-use results, including one benchmark that declined.
 15:30ENMatthew Berman· 31. Juli 2025Qwen3 Tested: Coding Demos, Long Context and Response BehaviorMatthew Berman · Forward FutureMatthew Berman tests generated simulations, political and safety prompts, hand tracking and word puzzles using a hosted Qwen3 model.
Mehr laden24 von 265 angezeigt