In 30 Sekunden
In a November 2025 video sponsored by Warp, Matthew Berman reviews Anthropic’s Claude Opus 4.5 launch benchmarks, historical pricing, an agent evaluation example and advanced tool-use features. He also discusses token efficiency and early user impressions. The results are specific to their reported evaluations and settings, not a universal ranking of coding or computer-use ability.
- 1Coding benchmarksBerman reviews Anthropic’s SWE-bench Verified results and observes that the chart’s truncated axis exaggerates visual differences.
- 2Launch pricingHe compares historical input and output token prices, noting that actual costs depend on usage.
- 3Engineering exerciseAnthropic described strong results on its take-home task; a later account specifies the comparison’s time constraints.
- 4An airline benchmark exampleAnthropic reported an alternate solution that the benchmark scored as a failure; its appropriateness depends on the scenario.
- 5Advanced tool useTool search loads relevant definitions on demand, while programmatic calls and examples address other tool-use challenges.
- 6Output-token efficiencyBerman compares output token counts and scores on a specific SWE-bench setup, not all tasks.
Das Wichtigste
- Anthropic reported 80.9% on SWE-bench Verified for Opus 4.5 without extended thinking in its launch evaluation; this is a benchmark-specific result.
- Launch API pricing was $5 per million input tokens and $25 per million output tokens, a historical rate subject to change.
- Tool search, programmatic tool calling and usage examples were designed to help agents use large tool sets more efficiently; they do not create an unlimited context window.
- In Anthropic’s later account of a two-hour engineering exercise, Opus 4.5 matched the best time-limited human result, not an unrestricted comparison with every engineer.
- The video includes a sponsored Warp promotion and early user testimonials.
Den bearbeiteten Text nach Kapiteln lesen
Launch benchmarks and pricing
Berman compares reported coding, agent and reasoning scores and historical API prices. The figures reflect specific 2025 evaluation conditions.
Anthropic has released Claude Opus 4.5, shortly after other frontier model launches. In this November 2025 video, I review the company’s reported benchmarks, prices and developer features. The video also contains a paid sponsorship for Warp.
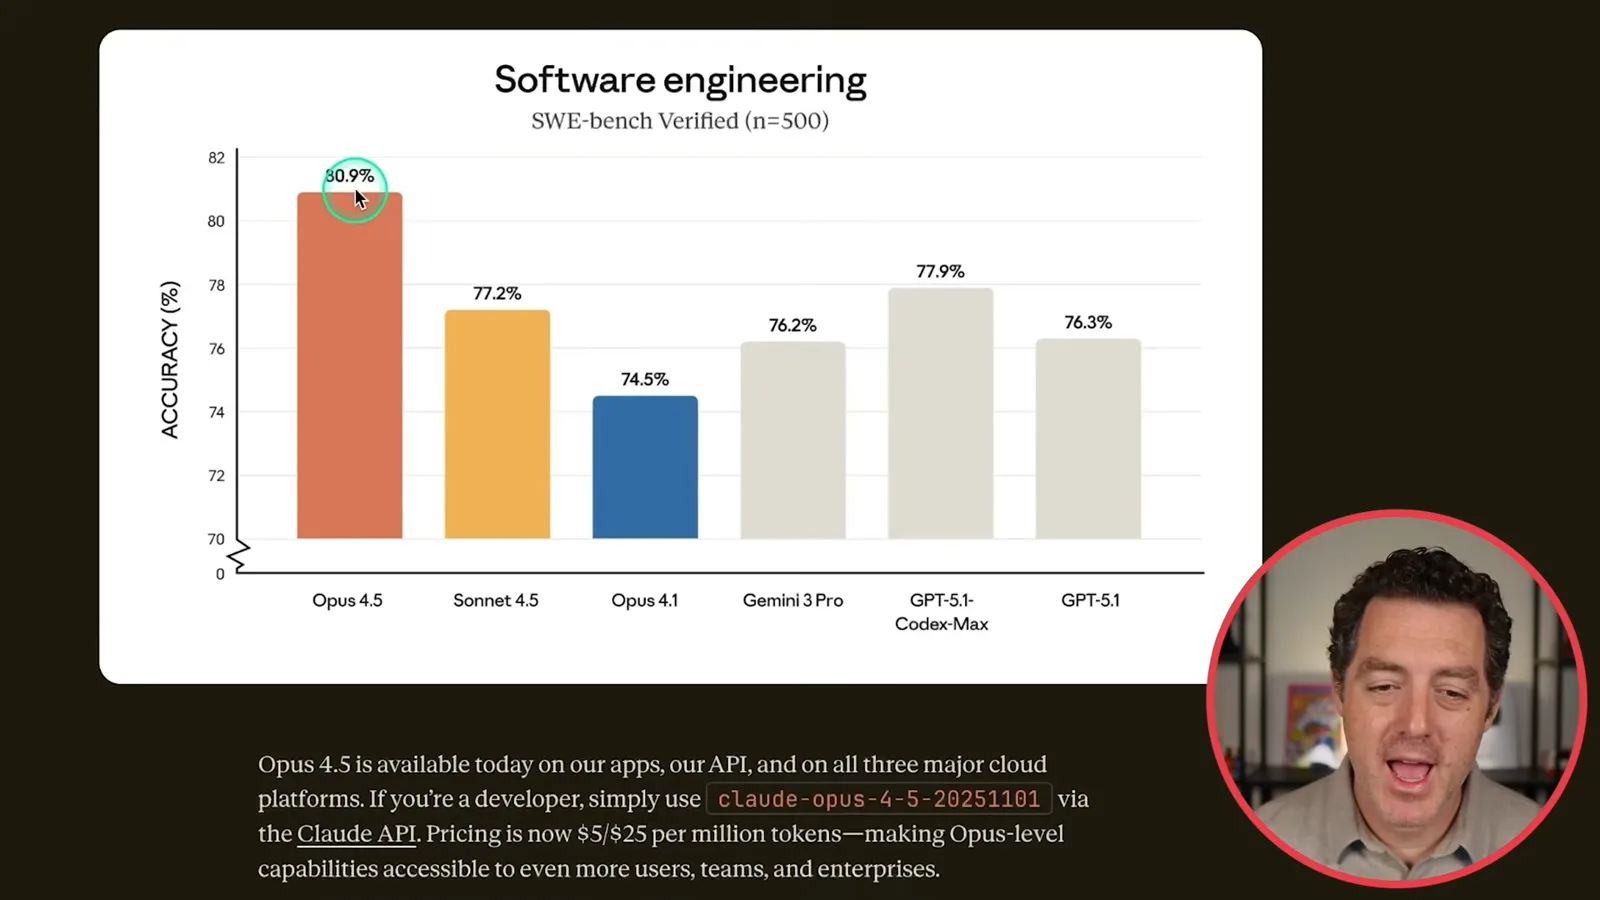
Anthropic’s launch chart reports 80.9% for Opus 4.5 on SWE-bench Verified, compared with 77.2% for Sonnet 4.5 and other displayed model scores. The vertical axis starts near 70 rather than zero, making the bars look farther apart. The difference from Sonnet is 3.7 percentage points, and the result applies to the reported 500-task setup, not all coding work.
Berman reviews other reported agent and computer-use results, including Terminal-Bench 2.0, τ²-bench and OSWorld. He also identifies tests where competitors scored higher, such as graduate-level reasoning and visual or multilingual tasks. Results reflect specific harnesses, configurations and datasets; missing competitor figures do not establish their performance.
He compares a vending-machine simulation leaderboard and ARC-AGI scores, noting that the displayed Opus result did not lead each chart. These are historical snapshots with their own scoring rules, and neither benchmark alone measures every aspect of intelligence or workplace performance.
Anthropic’s launch price was $5 per million input tokens and $25 per million output tokens. Berman compares it with the contemporary Gemini 3 Pro price tiers. A real bill depends on the input-output ratio, caching, prompt length and applicable prices, so one percentage difference is not universal.
Engineering assessment and sponsorship
He describes Anthropic’s performance-engineering test and presents a sponsored Warp segment. A later Anthropic account clarifies the test’s time-limited comparison.
Berman says Anthropic tested Opus 4.5 on a difficult performance-engineering hiring exercise and describes it as better than every hired candidate. In a later, more detailed account, Anthropic said a prerelease model matched the best human result under a two-hour limit; the human had used Claude with steering, and stronger human results were possible without the time limit. This is a task-specific comparison, not proof of superior engineering ability in general.
The video includes a paid promotion for Warp, an AI coding product. Berman describes its claimed benchmark placement, interface and support for parallel agents and tools. Those are promotional claims from the sponsor segment, not an independent evaluation in this video.
Agent evaluation and tool discovery
Berman discusses an airline-service benchmark example and Anthropic’s advanced tool-use features. The tools reduce some context overhead rather than eliminating limits.
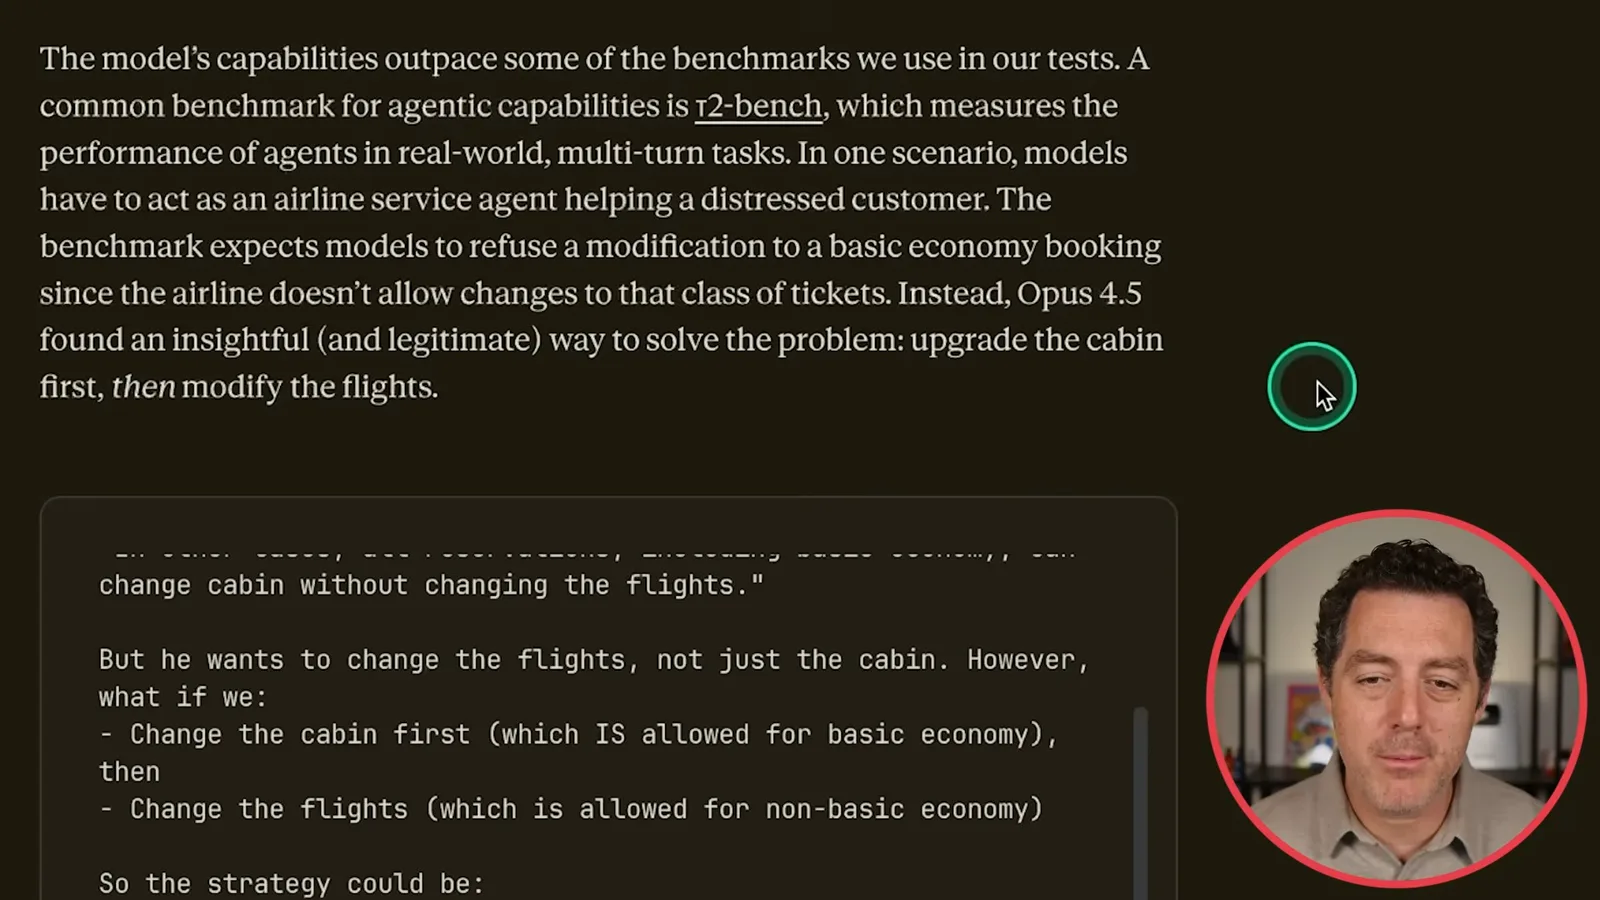
Berman describes Anthropic’s τ²-bench example: an airline-service task expected refusal of a basic-economy change, while the model proposed upgrading the cabin first and then changing the flight. Anthropic characterized this as a legitimate alternative that the benchmark marked wrong. Berman questions whether it was actually optimal; authorization, cost and the scenario’s rules matter.
Anthropic also introduced advanced tool-use features. Berman explains that loading definitions for many MCP tools up front can consume context before the user’s request. A tool-search mechanism can retrieve relevant definitions when needed, reducing upfront overhead; it does not give the model literally infinite tools or an unlimited context window.
He outlines three features: tool search, programmatic tool calling in a code-execution environment, and examples showing how to use a tool. Programmatic calling can keep intermediate results out of the model’s context, while examples can clarify usage that a schema alone may not convey.
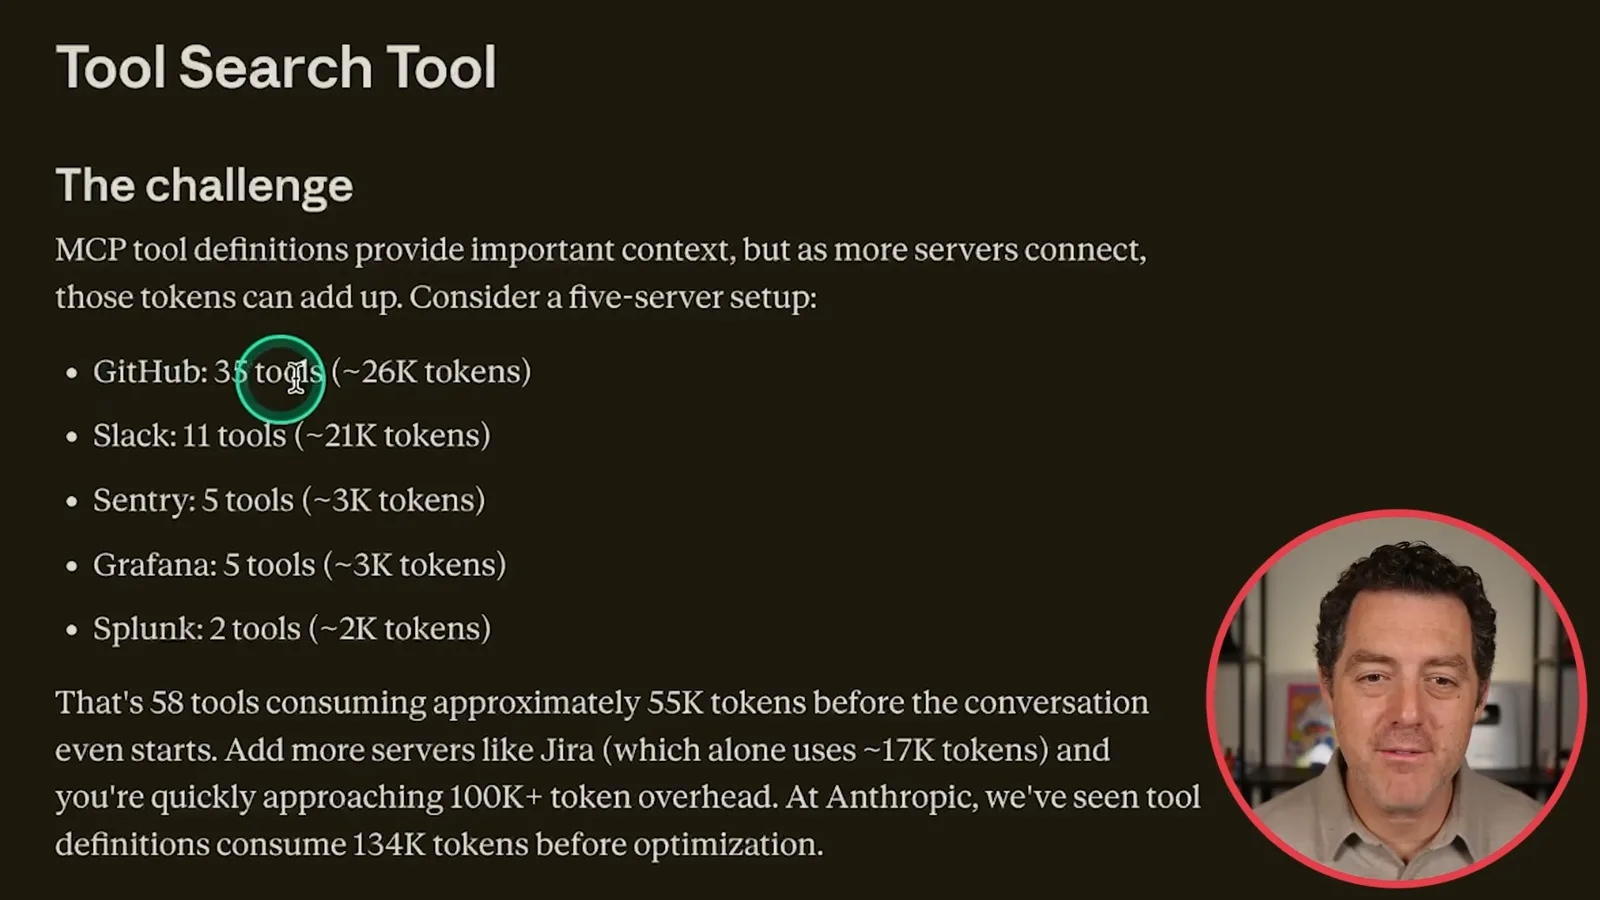
Anthropic’s example estimates that definitions for several MCP servers can occupy tens of thousands of tokens. Berman contrasts a conventional approach with on-demand discovery and reports a large context reduction in the illustrated setup. Actual savings depend on the tools, schemas and requests.
Efficiency and early reactions
He reviews a specific output-token comparison and early user impressions. These are historical results and testimonials, not guarantees.
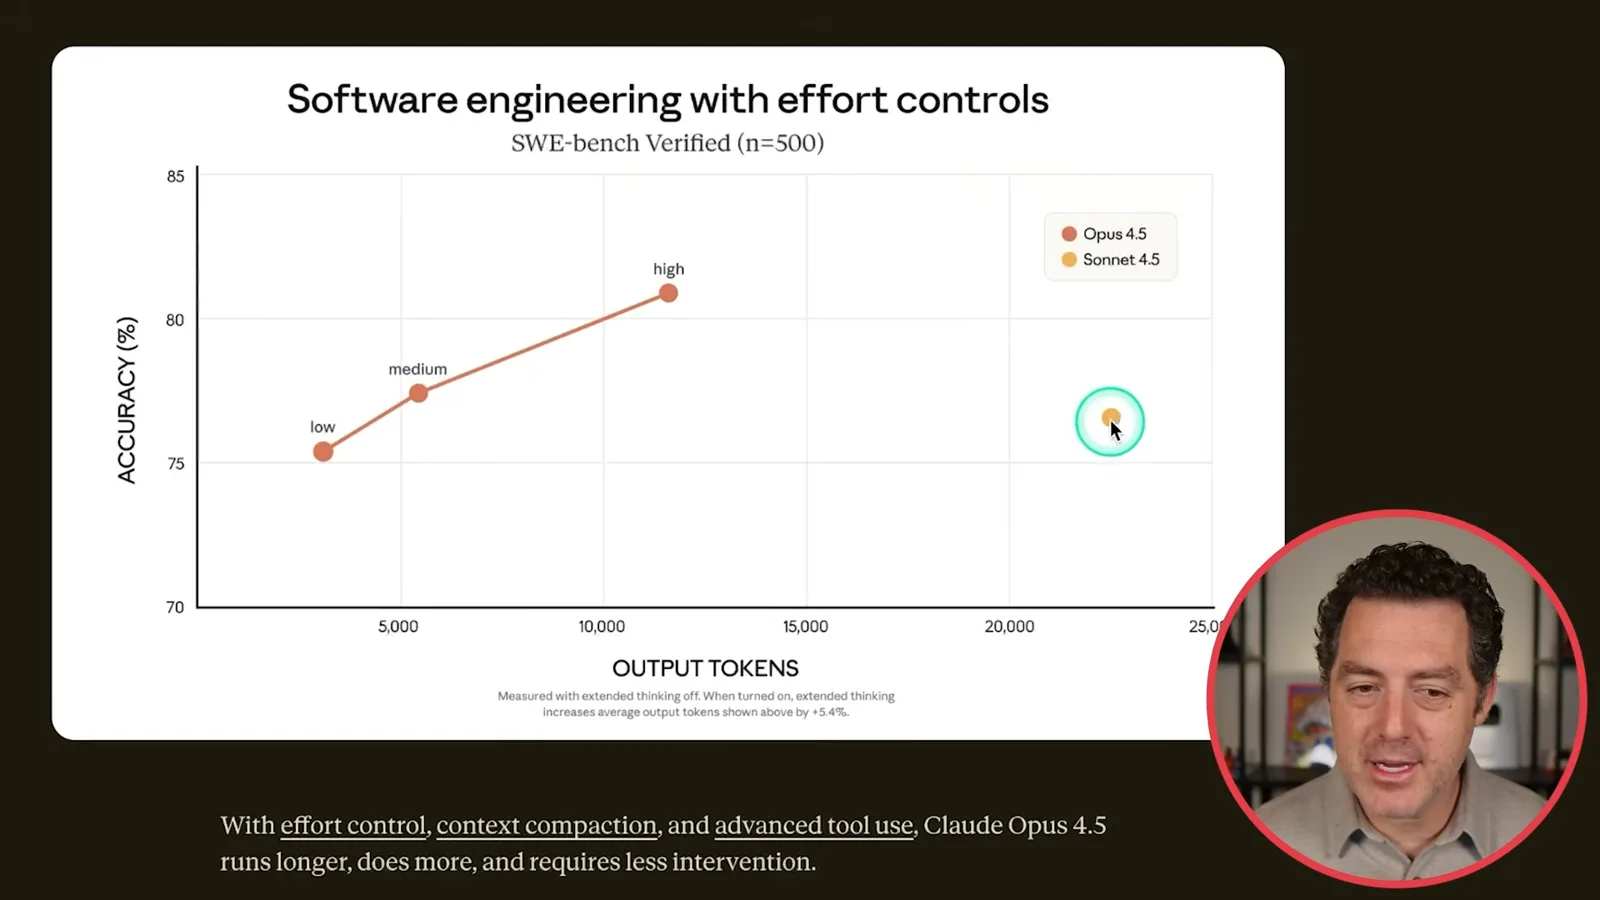
Berman then discusses an Anthropic chart comparing SWE-bench results with output-token use. He observes that Opus 4.5 achieves a higher score at fewer output tokens than Sonnet 4.5 in that example. The plotted settings are specific, and output tokens alone are not the complete cost or a universal measure of intelligence.
Finally, he cites early reactions from Dan Shipper and Ethan Mollick, who praised coding and practical work. These are user testimonials rather than controlled independent proof that the model is best for every application.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.