In 30 Sekunden
Berman examines Claude Sonnet 4.5’s reported coding results and discusses longer agent runs. He also tries an interactive desktop simulation; the video’s 30-hour run is a different measure from METR’s task-completion horizon.
- 1Reported benchmarksAnthropic compares coding and other task results under specific settings.
- 2Task horizonMETR measures task difficulty in human time at a specified success rate.
- 3A different 30-hour measureOne long run does not establish the same task horizon.
- 4Simulated desktopThe demo generates interfaces and simulated messages.
Das Wichtigste
- Launch benchmarks describe specific vendor-reported evaluations.
- A 30-hour agent run is not equivalent to a 30-hour METR task horizon.
- The desktop demo generates simulated interfaces rather than sending real mail or browsing the web.
- Efficiency and cost matter as well as the duration of an agent run.
- Pricing and rankings in the video are historical.
Den bearbeiteten Text nach Kapiteln lesen
Release and benchmarks
Berman reviews the 2025 launch and company-reported evaluations.
I review Anthropic’s Claude Sonnet 4.5 launch, focusing on coding, longer agent tasks and a generated-interface demo. This 2025 video was sponsored by Vultr; model rankings, prices and availability are historical.
Anthropic presents Sonnet 4.5 as a leading coding model and reports results on SWE-bench Verified, Terminal-Bench, tool use, computer use and math. These are company-reported evaluations under particular setups, not proof that the model is best at every task.
Long tasks and efficiency
He discusses METR’s task-horizon chart and efficiency.
I discuss METR’s work on task horizons: it measures tasks by how long a human takes and estimates how long a task a system can complete at a specified success rate. The chart in the video uses a 50% success measure on a particular task set.
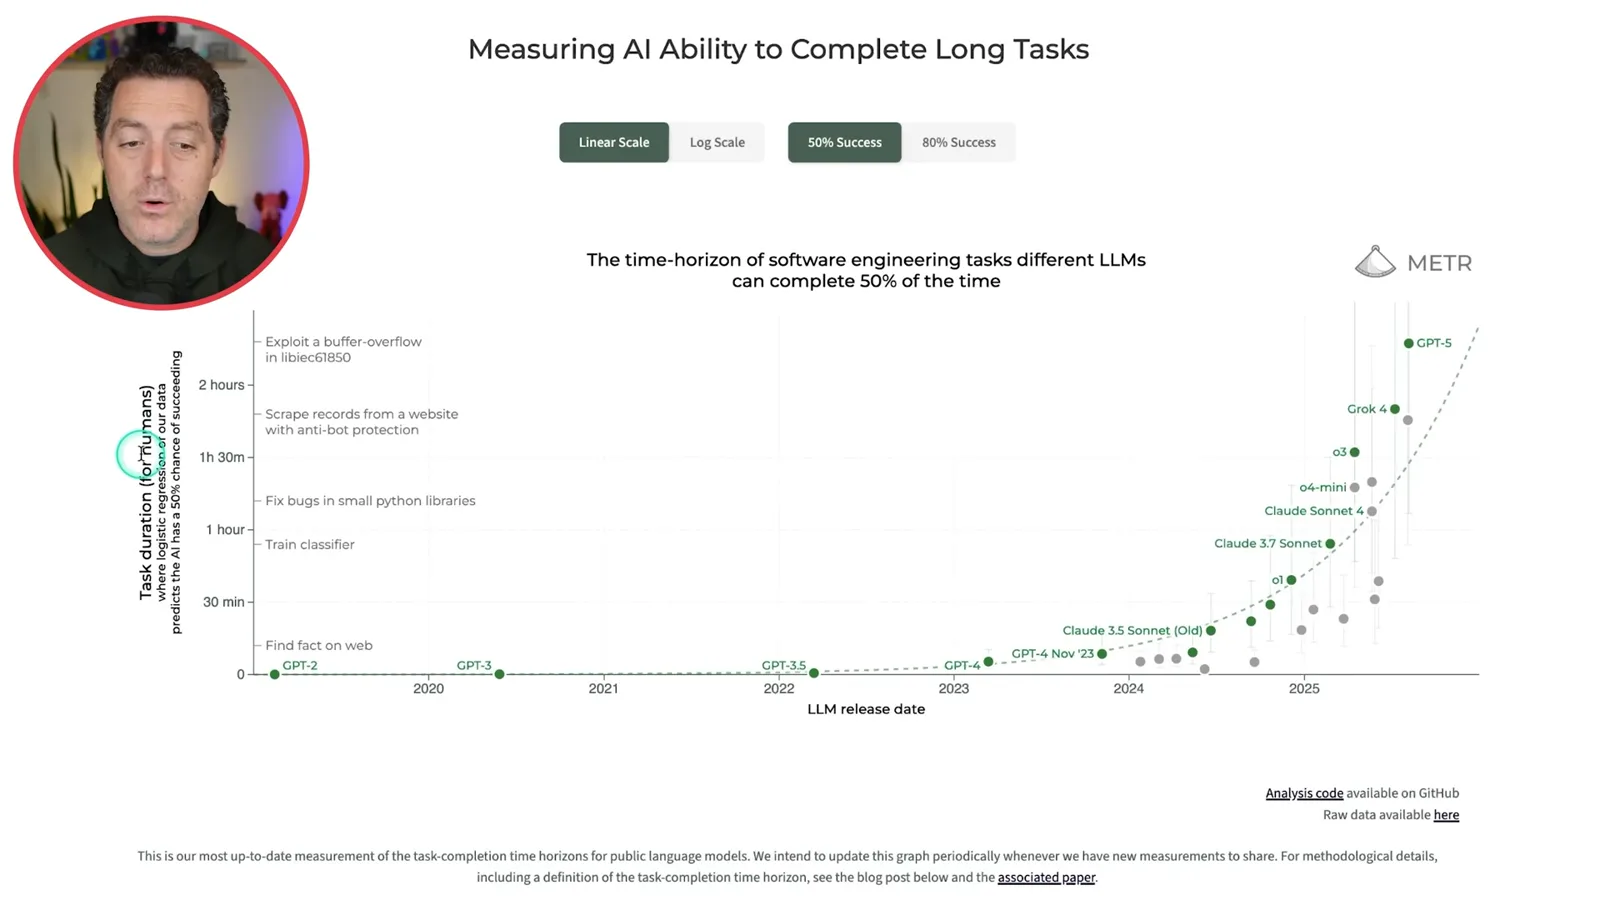
I compare that chart with an Anthropic report of a model working for more than 30 hours. These are different measurements: the elapsed length of one agent run does not establish a 30-hour METR task horizon, and the run involves a surrounding agent system.
Beyond duration, I want systems to complete tasks efficiently. I discuss Greg Kamradt’s interest in action efficiency and the notion of intelligence per watt, while acknowledging that it is difficult to define one comparable measure across tasks.
Generated desktop demo
He tests simulated email, calculator, to-do and browser interfaces.
I try an interactive concept demo called Imagine with Claude, which generates desktop-style interfaces from prompts. I see it as a possible direction for software, but that is a prediction rather than evidence that current applications are obsolete.
A prompt creates a futuristic email interface with simulated messages. Clicking and replying cause the demo to generate more interface content; I acknowledge that the example is a simulation and does not actually send an email.
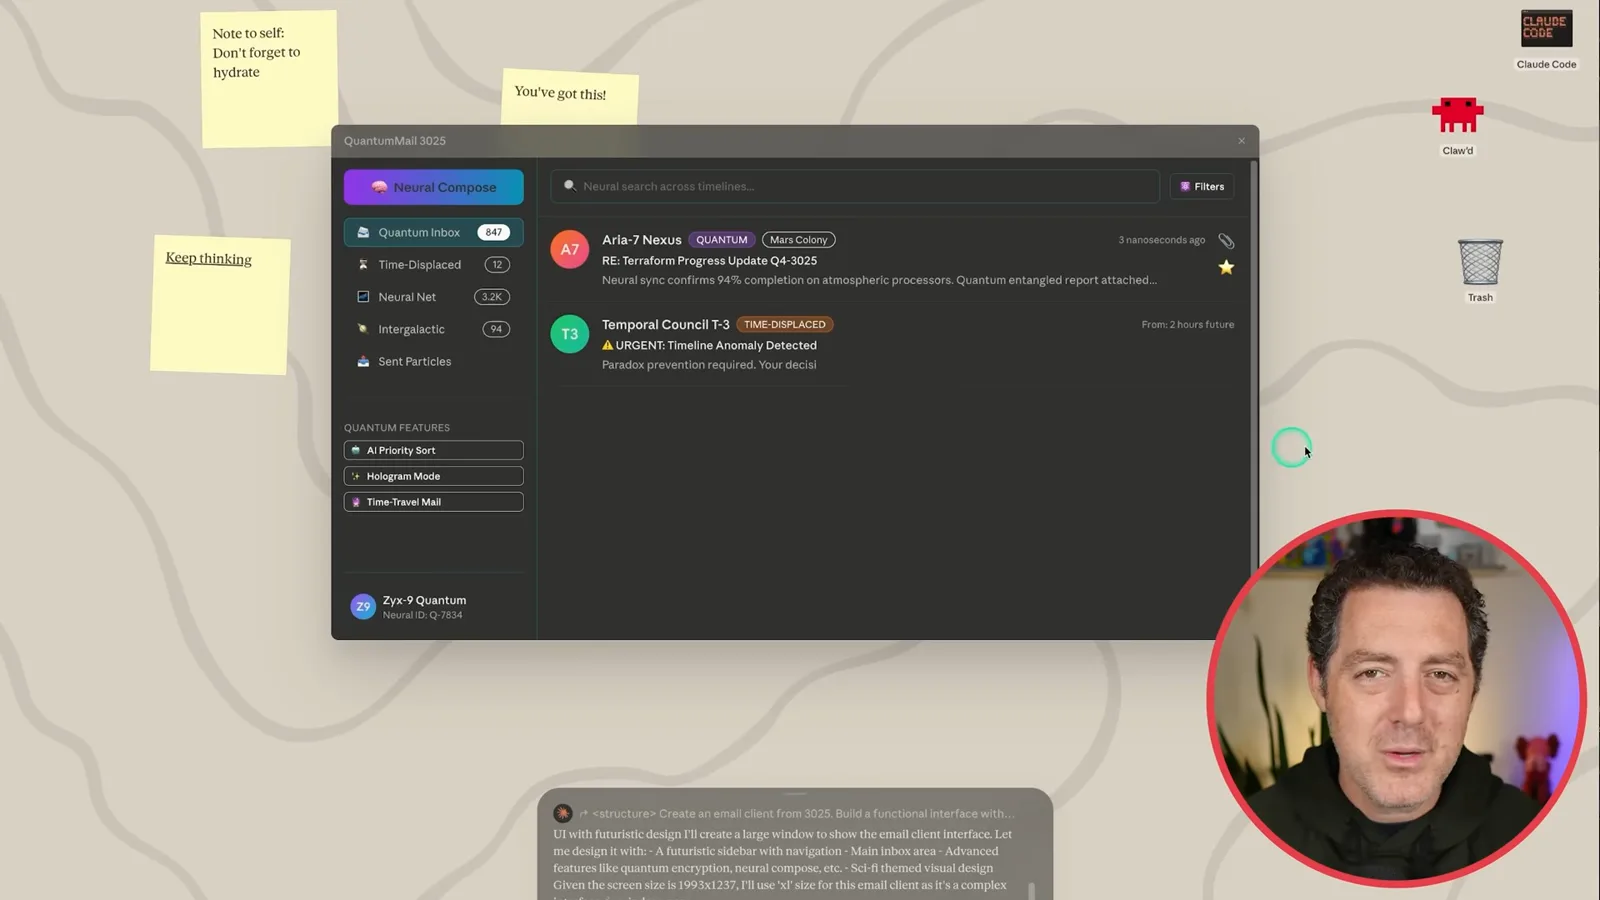
I ask for a calculator and a to-do list, then interact with the generated views. The demo illustrates dynamically produced interfaces, although the latency and underlying implementation limit what can be inferred from a few interactions.
I ask for a browser and simulated searches. The demo generates representations of Google, Wikipedia and Reddit rather than actually browsing those sites, so its pages should not be mistaken for live web results.
Reactions and claims
He discusses reported evaluations, safety claims and historical pricing.
I mention a reported jailbreak without reproducing the unsafe material, and show a playful website demo. A single reported jailbreak or playful output does not by itself characterize the model’s full safety or coding performance.
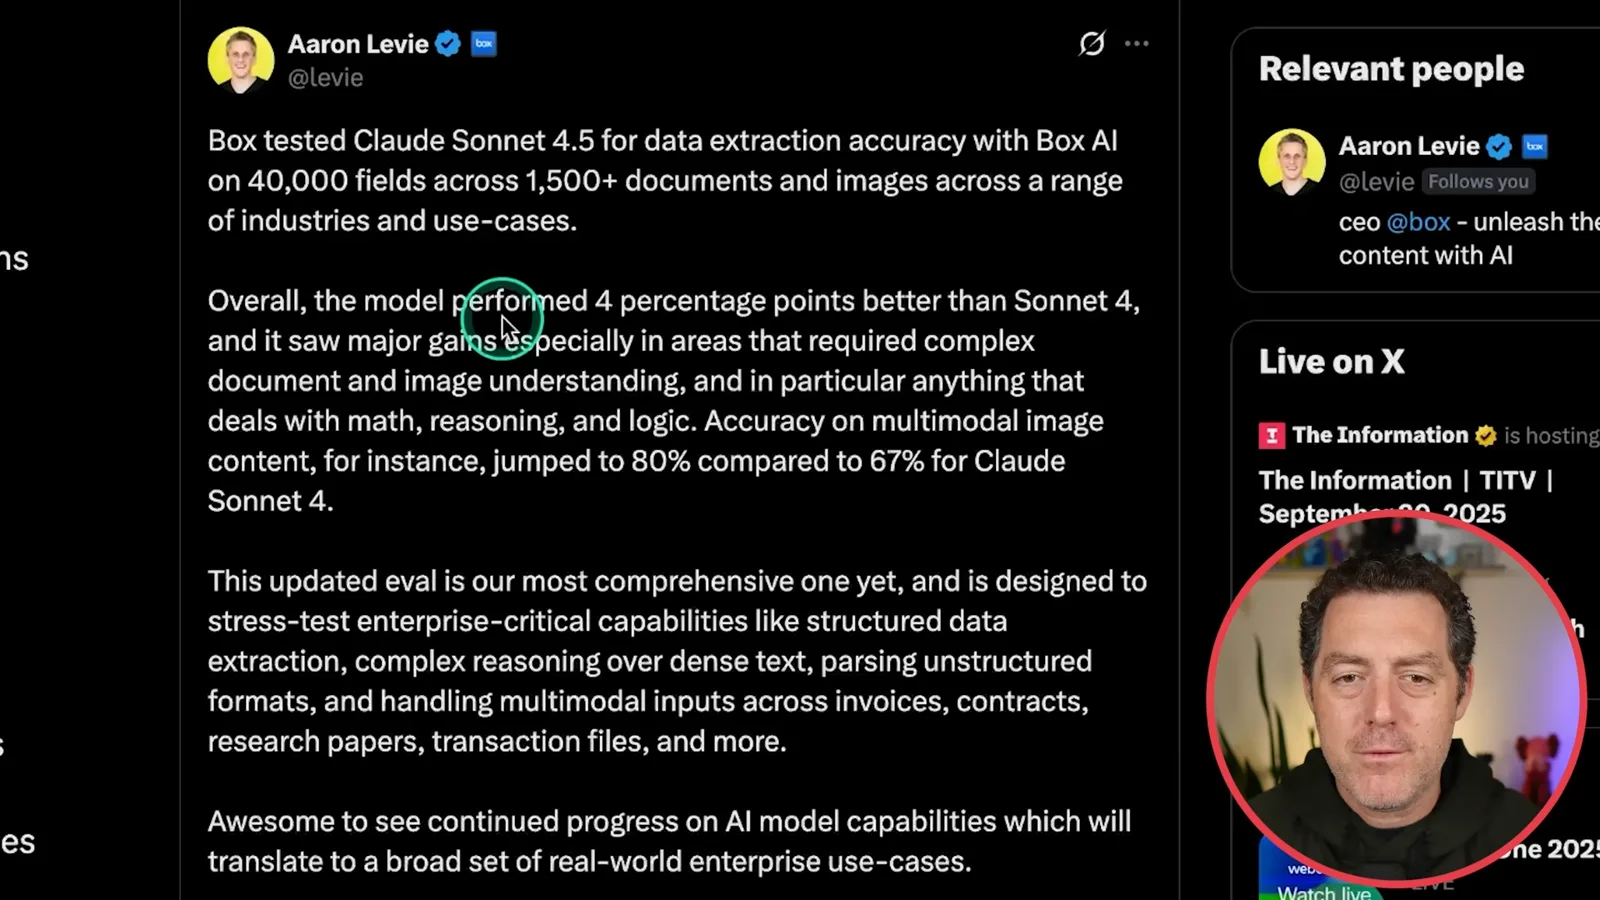
Box’s Aaron Levie reports testing 40,000 fields across more than 1,500 documents and finding a four-point overall improvement over Sonnet 4. This is a company-reported result for that evaluation, not an independent guarantee for other datasets.
I discuss a purportedly extracted system prompt and speculate about why it contains certain instructions. The video does not independently authenticate the full prompt, and my explanation of its authors’ motivations is conjecture.
Anthropic CEO Dario Amodei says Claude writes much of the code supporting Claude and future versions. I connect that claim to longer autonomous workflows; the video does not independently measure the proportion of code or prove an unrestricted self-improvement loop.
I read launch pricing and encourage viewers to try the model. Those figures describe the release period, and present-day costs and model availability may differ.
Mehr aus diesem Kanal
 34:21EN
 Matthew Berman· 27. Okt. 2026Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 25. Okt. 2026Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 25. Okt. 2026Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 24. Okt. 2026An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 24. Okt. 2026Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 23. Okt. 2026Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.