30초 요약
A skill can contain information a model already knows alongside exact details it needs. Intel’s Nikolay Petrov proposes splitting instructions into checkable items and comparing answers with and without the skill, producing a map of gains, unchanged knowledge, regressions and gaps. In one reported comparison, Opus answered 70% of items under a general criterion but 22% when exact details were required. Petrov treats this map as a starting point: remove candidate redundancy, then rerun task evaluations before deciding the shorter skill works.
- 1Start with the same tasks with and without the skillPetrov compares task success, token use and time across two arms. His three-of-five versus five-of-five example illustrates how to measure whether instructions help.
- 2Break instructions into checkable itemsEach proposition or behavioral contract gets a question and expected answer, evaluated in both conditions. Judges should not simply receive answers leaked by the questions.
- 3Four outcomes separate gains from regressions and gapsA model may answer correctly in both conditions, only without the skill, only with it, or in neither. Each pattern suggests a different next investigation.
- 4General familiarity can hide missing operational detailsPetrov reports one Opus comparison with 70% under a general criterion and 22% under a strict criterion. Those figures describe his evaluation, not all tasks or models.
- 5Use the map to propose cuts, then rerun task evaluationsAn item that looks redundant in isolation may still matter in an actual workflow. Petrov recommends confirming that end-to-end results hold after editing.
핵심 정리
- Compare the same checkable questions with and without the skill to locate gains, unchanged answers, regressions and gaps.
- Keep general knowledge distinct from exact parameters, values and steps; a model may know one without the other.
- Avoid questions that reveal their answers, and consider an independent model family or panel for judging.
- Decide whether the test measures internal knowledge or practical performance with tools; the two are different.
- Use item-level results to guide edits, then validate any shorter skill with end-to-end task evaluations.
챕터별로 다듬은 전문 읽기
What skills add and how to test them
Skills can teach new information or steer a process. Petrov starts with paired task evaluations to measure whether a skill helps.
Nikolay Petrov describes skills as reusable packages of instructions that turn repeated prompts into portable agent capabilities. Some provide new knowledge; others primarily steer a repeatable process. Both can be useful, but this talk focuses on skills intended to teach a model something it did not already know.
A basic evaluation compares the same defined tasks with and without the skill loaded. Petrov recommends tasks that can be checked as deterministically as practical. His illustration has the model solve three of five tasks without a skill and five of five with it; the comparison can also include token use and time.
Map a skill into individually testable items
Questions and expected answers allow comparison with and without the skill. Tool access and the choice of judge affect what the evaluation measures.
Even when a skill improves end-to-end evaluations, its contents may need revisiting as models evolve or token costs matter. Trying every combination of lines is expensive, while deleting text based on intuition can remove a detail the model actually needed.
Petrov proposes splitting a skill into small, independently checkable items, drawing on the idea of atomic facts from FActScore. Each item gets a question and an expected answer. An item can describe a general proposition or a more specific behavioral contract.
A skill might yield 25 or 30 such items. For each question, the team runs two arms—one with the skill and one without—and uses a model judge or panel of judges to assess the answers. Petrov recommends a judge from a different model family where practical and questions that do not reveal their own answers.
The test can run without tools to probe what the model already knows, or with tools such as web access to better reflect a practical environment. These are different measurements: external information can change what the model can answer without the skill.
Interpret the four possible outcomes
The model may know an item already, improve with the skill, degrade or fail in both conditions. Petrov visualizes the outcomes against the source text.
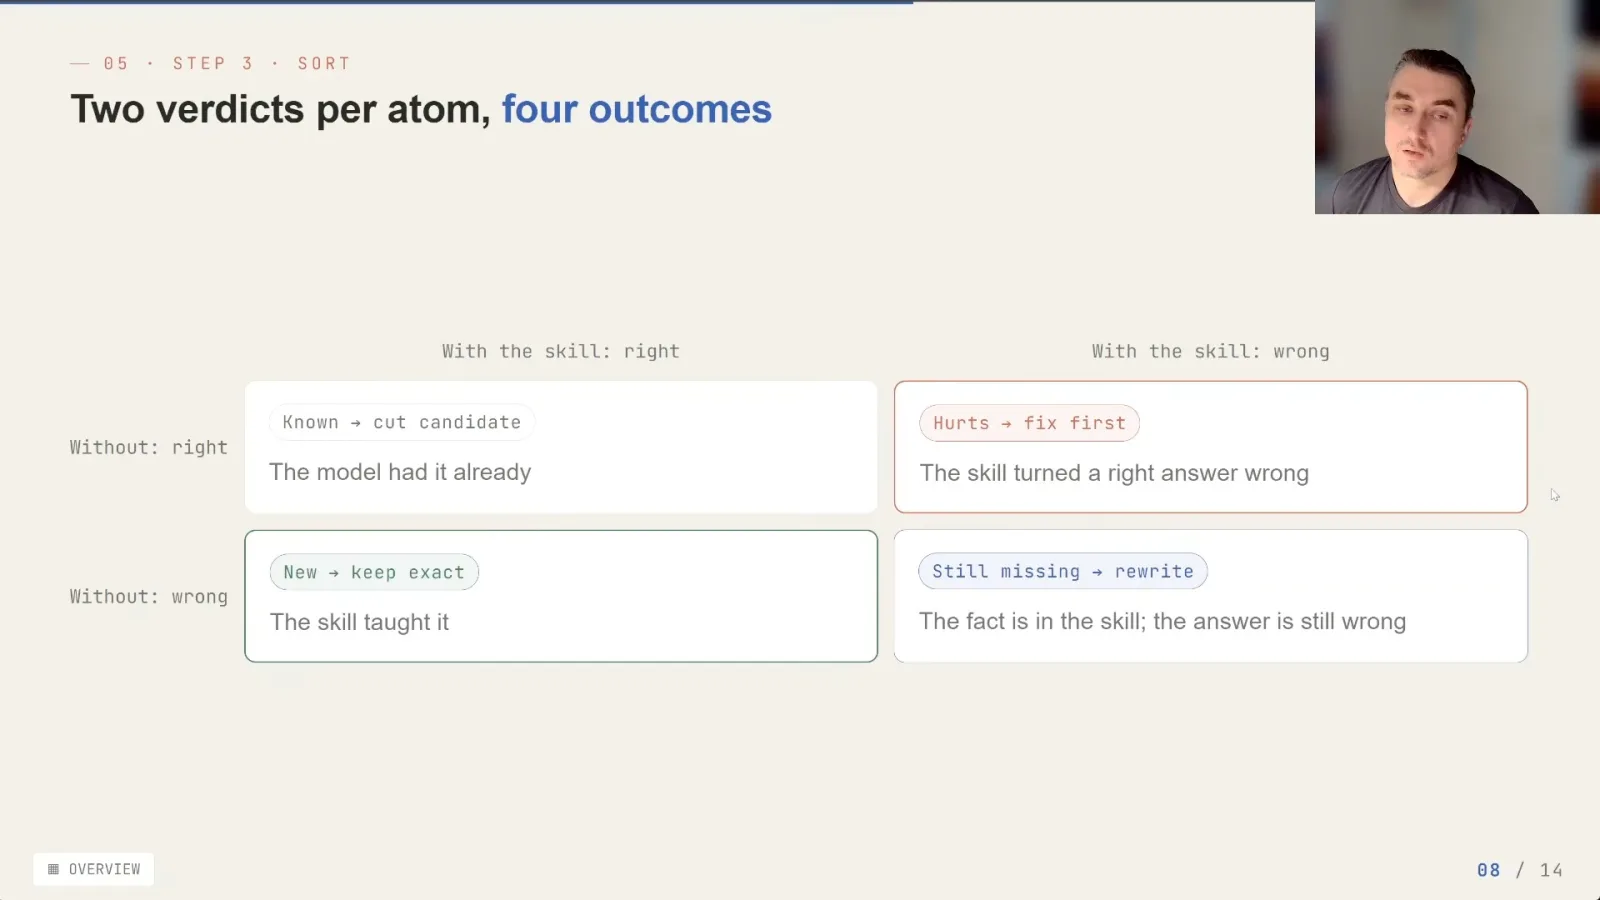
The paired outcomes form a four-way map. If the model answers an item correctly both with and without the skill, it already has enough knowledge to answer that question in the tested setting. If it succeeds only without the skill, adding the skill appears to hurt that item.
If the model fails without the skill but succeeds with it, the item represents the desired gain in that test. If it fails in both conditions, the subject may still matter, but the skill as written did not make the tested model answer successfully.
Petrov says performance-degrading items were rare in the popular skills his group examined: he points to one case among nearly 400 items in the Anthropic skills shown. He reports seeing more such cases in some smaller, less popular skills; the finding is specific to the tested skills, models and questions.
The outcomes can be visualized against the skill text to show what is helpful, already known, harmful or still missing. Petrov cautions that the unit is an item, not necessarily a line: a single line or sentence can contain items with different outcomes.
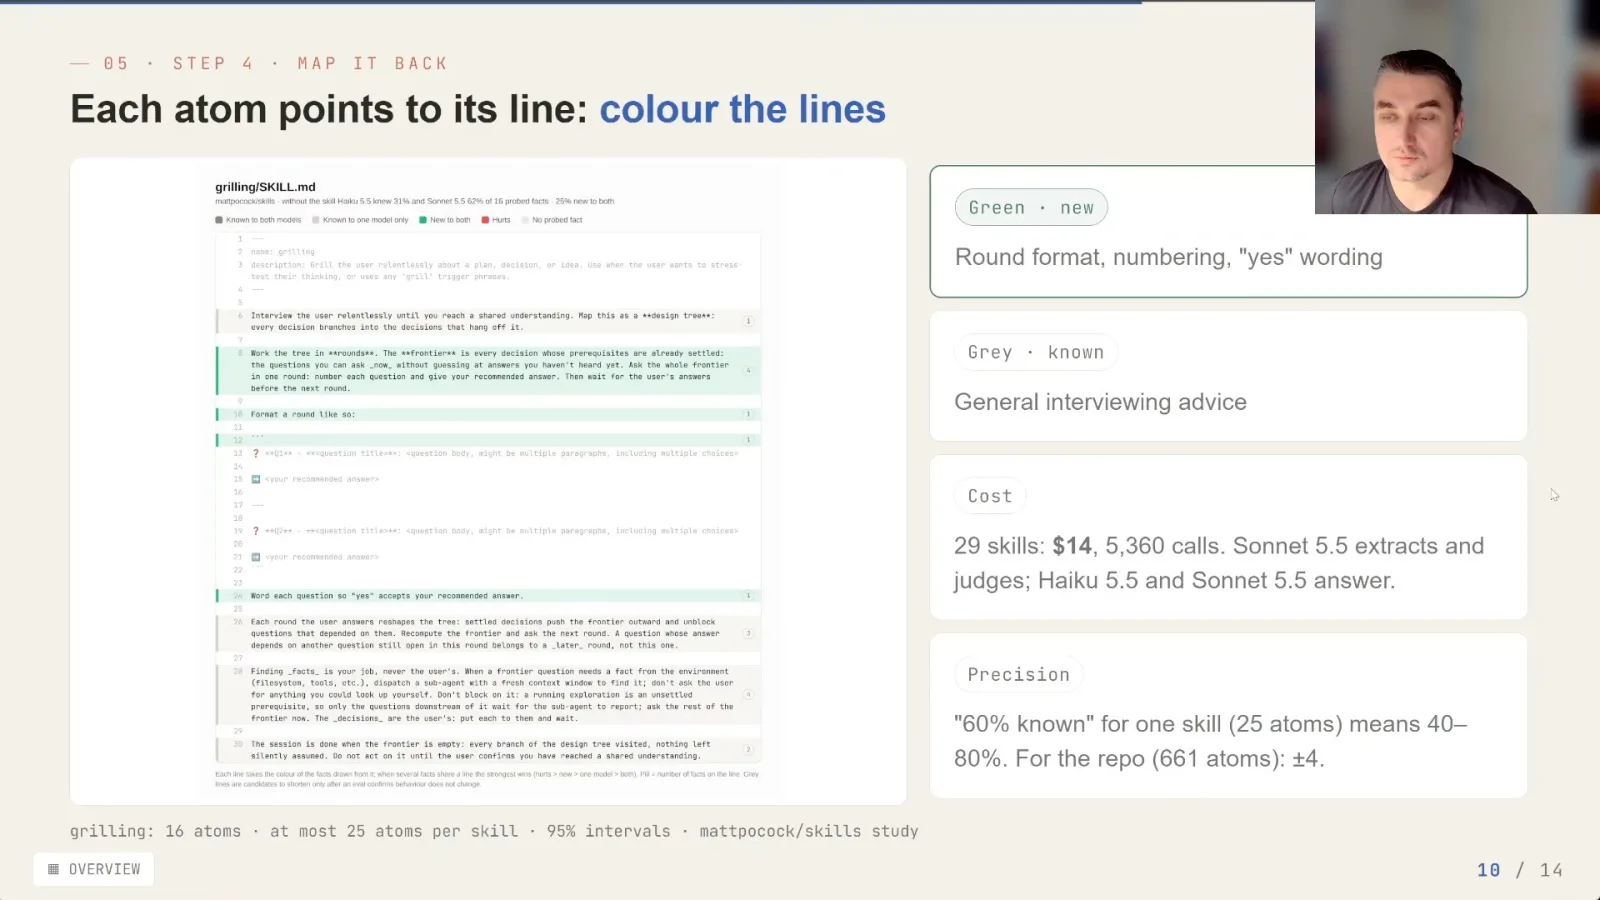
For the reported experiment, Petrov says testing 29 skills cost about $14 in Sonnet and Haiku calls, with Sonnet used as judge. The cost is a figure for that run, not a universal price for evaluating every skill.
Distinguish broad understanding from exact details
Strict and lenient scoring can produce very different results. Item-level novelty helps guide edits, but final task evaluations remain necessary.
The evaluation can also change how strictly it scores an answer. A lenient check asks whether the general idea is present; a strict check asks for specific keys, parameter values or exact steps. Knowing a concept is not the same as knowing the particulars an agent must use.
In one comparison Petrov reports that Opus answered about 70% of skill items under a general understanding criterion but 22% under a specific-detail criterion. He interprets the difference as a reason to preserve exact data and operational details even when a frontier model knows the broad concept.
Across the models and skill collections shown, smaller models generally knew less of a skill than larger ones, but results also varied significantly by skill. Some skills are meant to steer behavior rather than supply novel facts, so a low novelty measure is not automatically a defect.
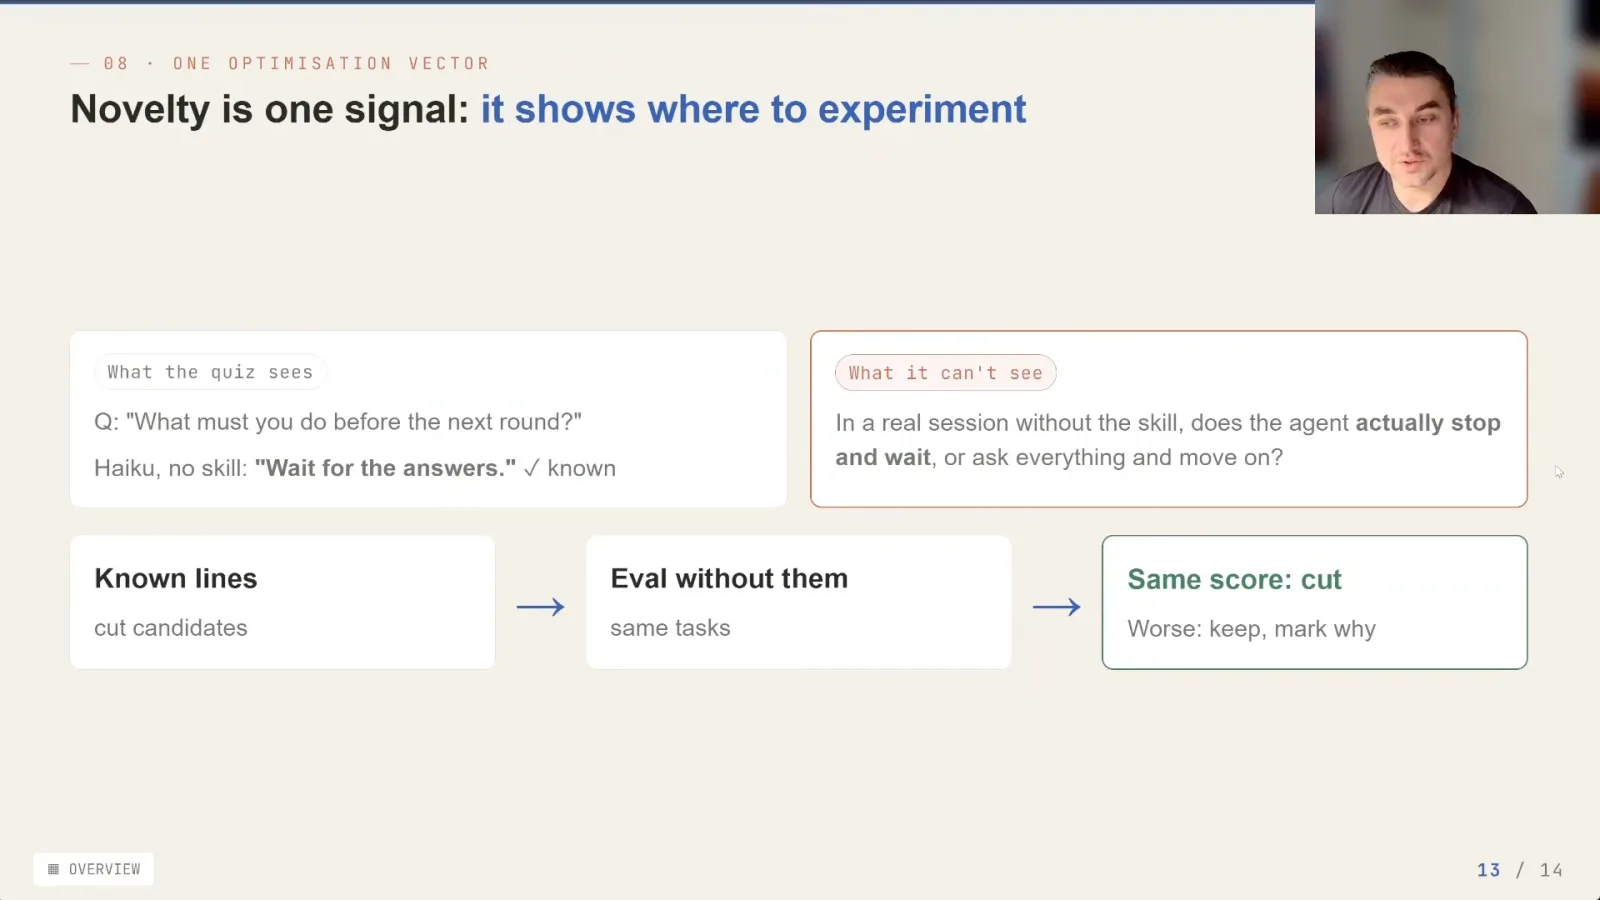
Novelty is an initial direction for optimization, not a substitute for task evaluations. Petrov suggests removing some information that appears already known, then rerunning the end-to-end evaluations. If task results hold, the shorter skill may save tokens and context; if not, the supposedly redundant material may still be useful.
The experiments used Documate, which Petrov describes as a framework for comparing agent context such as skills, AGENTS.md and MCP tools. He says it also supports evaluations of context impact, routing, descriptions and names, with the goal of making skill changes based on measurements rather than guesswork.
같은 채널의 다른 글
 17:31EN
 AI Engineer· 2026년 11월 12일Claude Code needs less steering, but unattended work needs stronger checksLydia Hallie · AnthropicLydia Hallie describes how permissions, isolated environments and verification can take over tasks people once handled during every session.
 18:03ENAI Engineer· 2026년 11월 11일Dmitry Buykin: How to Maintain Code When Agents Outrun ReviewDmitry Buykin · MaerskAt Maersk, weekly pruning, real-task replays and expert feedback help keep an agent-built system understandable.
 26:49ENAI Engineer· 2026년 11월 11일Ara Khan: Choose work that improves with AI without being replaced by itAra Khan · ClineCline’s Ara Khan explains an automated evaluation loop and urges engineers to pick problems that benefit from model progress.
 12:38ENAI Engineer· 2026년 11월 11일How Duolingo uses agents to add tests without skipping human reviewKush Agrawal · DuolingoA scheduled pipeline raised iOS coverage by generating tests, repairing CI and routing pull requests to engineers for approval.
 38:50ENAI Engineer· 2026년 11월 10일LinkedIn’s self-improving agent first had to fix its judgesZiwei Guo, Saloni Gandhi · LinkedInA prompt-optimization loop improved a career agent, but unreliable evaluators required human calibration first.
 12:48ENAI Engineer· 2026년 11월 10일Brian Douglas: Turn agent corrections into reusable review knowledgeBrian Douglas · Paper ComputeThe Paper Compute developer captures expert pushback in coding sessions and tests ways to reuse it during review.