30초 요약
Matthew Berman reviews xAI’s August 2024 Grok 2 beta announcement and tests Grok 2 mini on a marble puzzle and FLUX-powered image generation. He finds the puzzle answer wrong, encounters an initial image-generation failure, and later observes appealing images that do not always follow complex prompts.
- 1Grok 2 and minixAI introduced two beta models and identified an early Grok 2 version on the LMSYS leaderboard.
- 2Evaluating factualityxAI describes human comparison of model responses for instruction following and factual accuracy.
- 3The marble testThe mini model’s response incorrectly places the marble inside the inverted cup.
- 4Image generationAfter an initial failure, Berman generates images and observes weak adherence to some complex requests.
핵심 정리
- xAI identified the anonymous sus-column-r model as an early Grok 2 version and released a mini variant.
- Leaderboard and benchmark comparisons reflect the 2024 test conditions and do not establish performance on every task.
- Grok 2 mini failed Berman’s marble puzzle in this example.
- Image generation initially failed, then worked, although complex prompts were not consistently followed.
- FLUX variants had different access and license terms; open availability does not mean every variant was fully open source.
챕터별로 다듬은 전문 읽기
The beta release and benchmarks
Berman reviews xAI’s model announcement, leaderboard position and evaluation approach. He discusses mini and the larger model in the historical context of 2024.
The mystery model called sus-column-r was an early version of Grok 2, according to xAI, and the Grok 2 beta has now been announced. I previously tested the anonymous model, so here I review the announcement and try the mini model and image generation. This is a snapshot of the August 2024 release, not a current product comparison.
xAI introduced Grok 2 and the smaller Grok 2 mini as successors to Grok 1.5, with chat, coding and reasoning capabilities. At launch the company said the two models were available to X Premium and Premium+ users and planned an enterprise API. Their weights were not released with this announcement.
xAI reported that the anonymous early version was ahead of Claude 3.5 Sonnet and GPT-4 Turbo on the LMSYS leaderboard at the time. I compare its position with several GPT-4o and Gemini versions. Those rankings are time- and methodology-dependent, not proof that one model wins every task.
The company describes having AI tutors compare pairs of responses, focusing on instruction following and factual accuracy. It also reports improvements in reasoning over retrieved content and tool use, including identifying missing information and discarding irrelevant posts. I value factual accuracy, but these are xAI’s evaluation claims rather than a guarantee that responses are true.
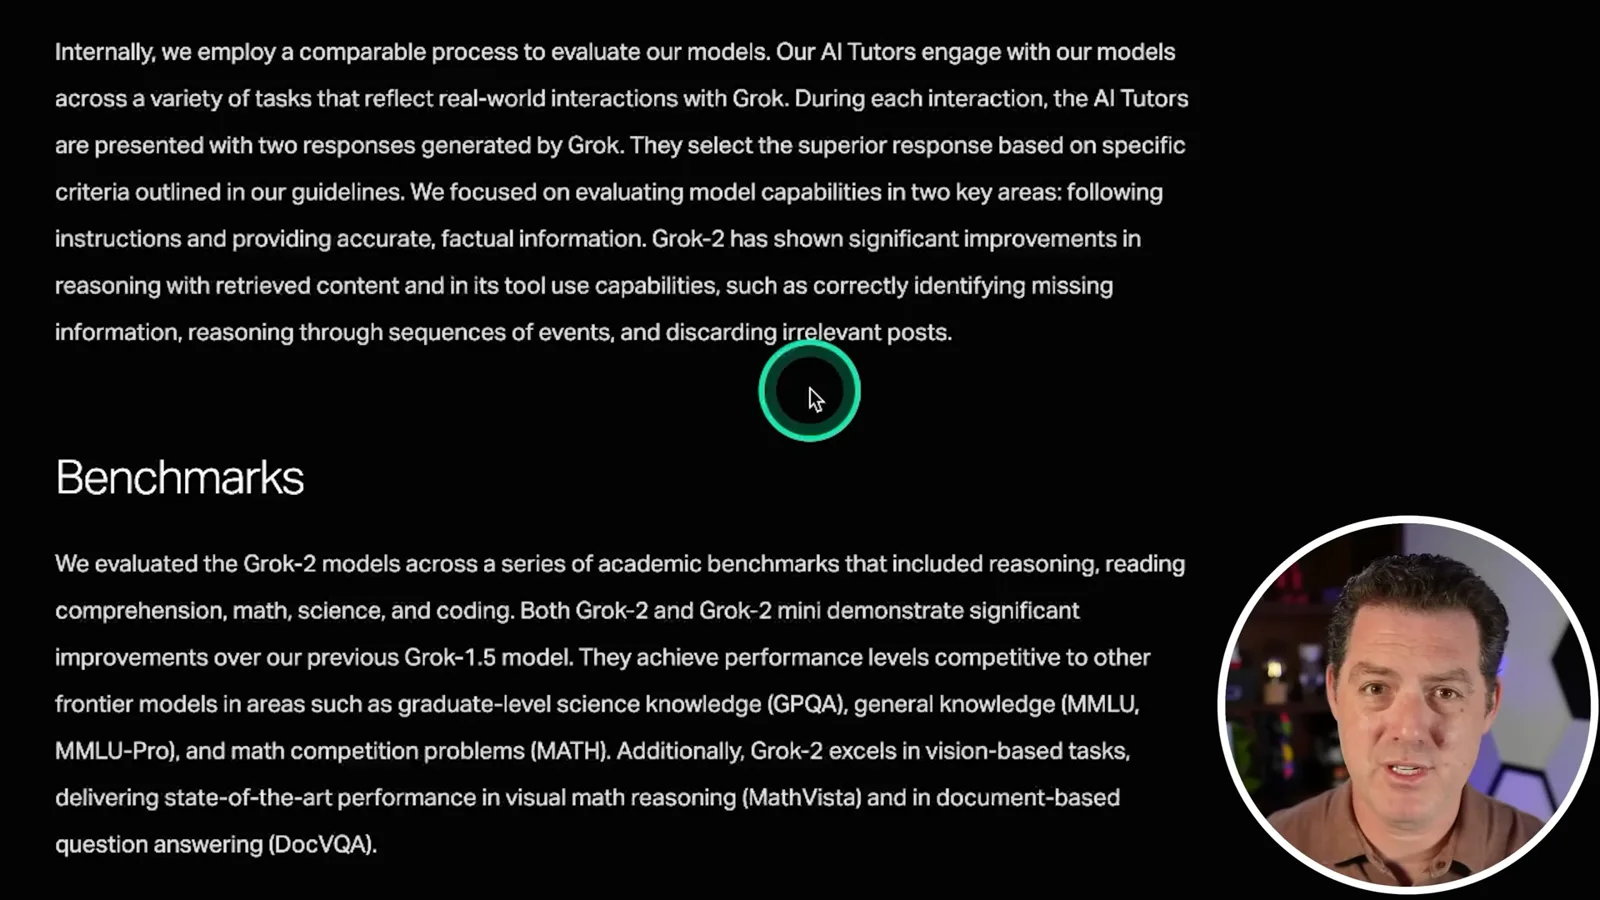
I compare the reported academic benchmark scores for Grok 2 and mini and note that many are fairly close. I expect a smaller model might become faster and cheaper, though that is an assumption rather than a measured result here. I also point out the strong comparison from Llama 3.1 405B, an open-weight model.
The release includes a redesigned interface and image generation in collaboration with Black Forest Labs using FLUX.1. I describe the model family as open source and attribute the team to Midjourney, but Black Forest Labs identifies its founders with latent diffusion and Stable Diffusion work; FLUX.1 variants also had different licenses: schnell used Apache 2.0, dev had non-commercial terms and pro was served through an API.
FLUX and the marble test
He discusses the image-generation partnership and tests Grok 2 mini on a physical reasoning puzzle. The response fails the test.
I am excited about an image generator that appeared less restrictive in my examples and about the competition among AI providers. Still, those examples do not establish that every request is allowed or that safeguards are absent. Capabilities, policies and availability can change.
In Grok 2 mini’s fun mode I ask where a marble ends up after a glass containing it is inverted, placed on a table, lifted and put in a microwave. The model gives a lengthy answer saying the marble is most likely inside the glass. I judge it wrong: under the ordinary interpretation the marble falls out or stays on the table rather than traveling inside an inverted glass.
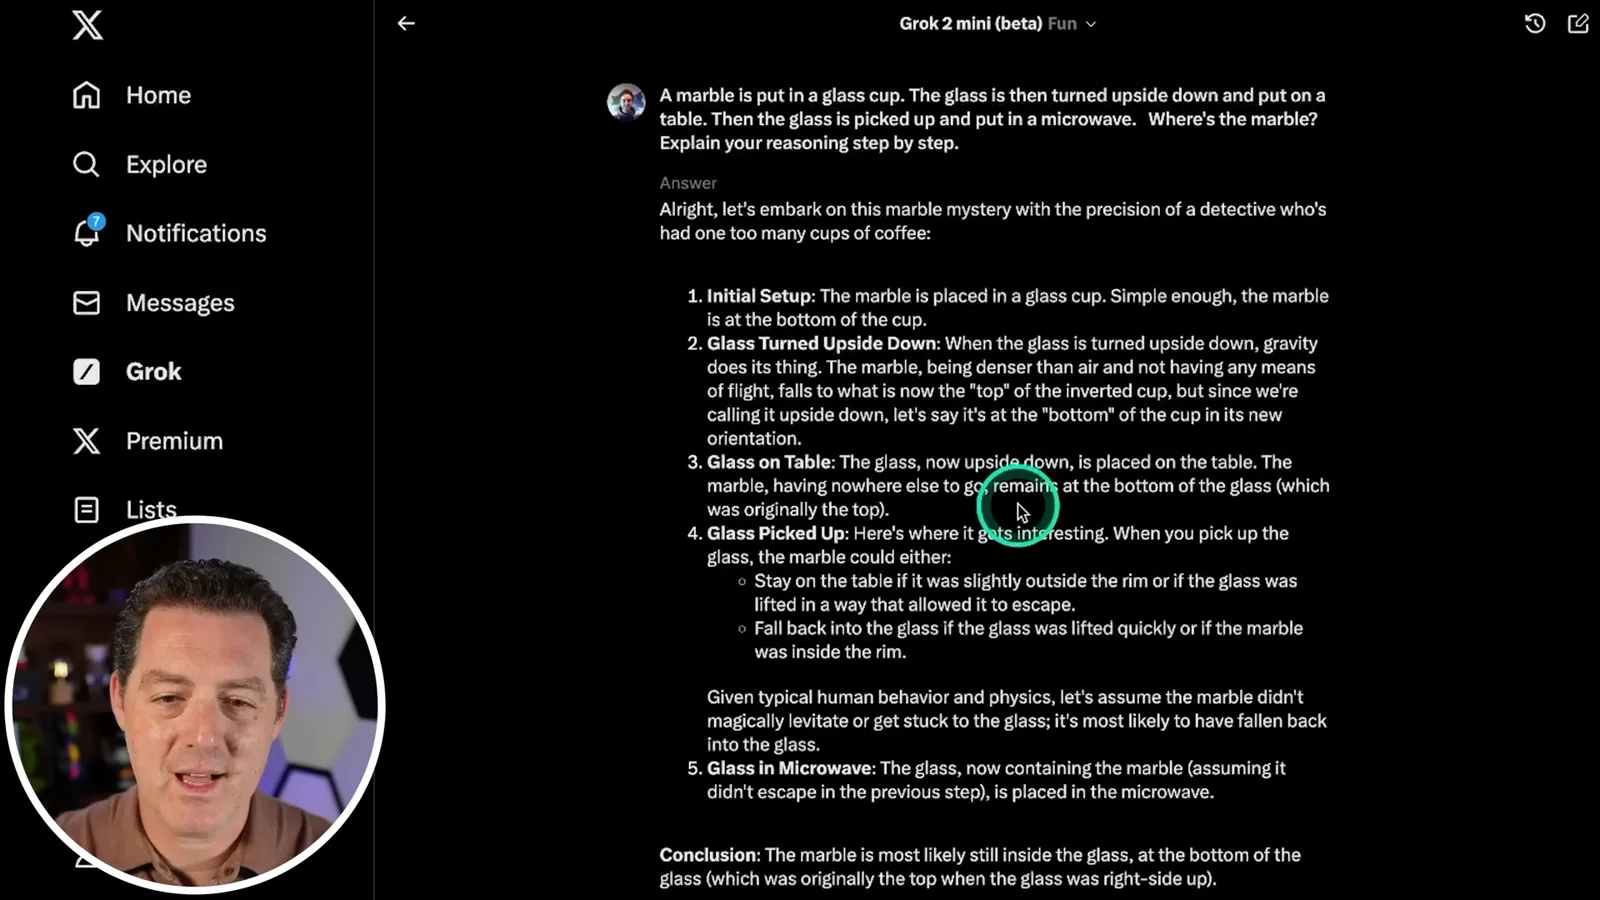
Image generation and current events
After initially encountering errors, he generates images and tests prompts involving public figures and fictional characters. He also asks for headlines and notes the spread of synthetic imagery.
My first requests for a llama image repeatedly produce an error, which I suspect may be due to load; the video does not establish the cause. I show other users’ synthetic images of public figures. Their appearance in a feed is not evidence that the depicted events occurred.
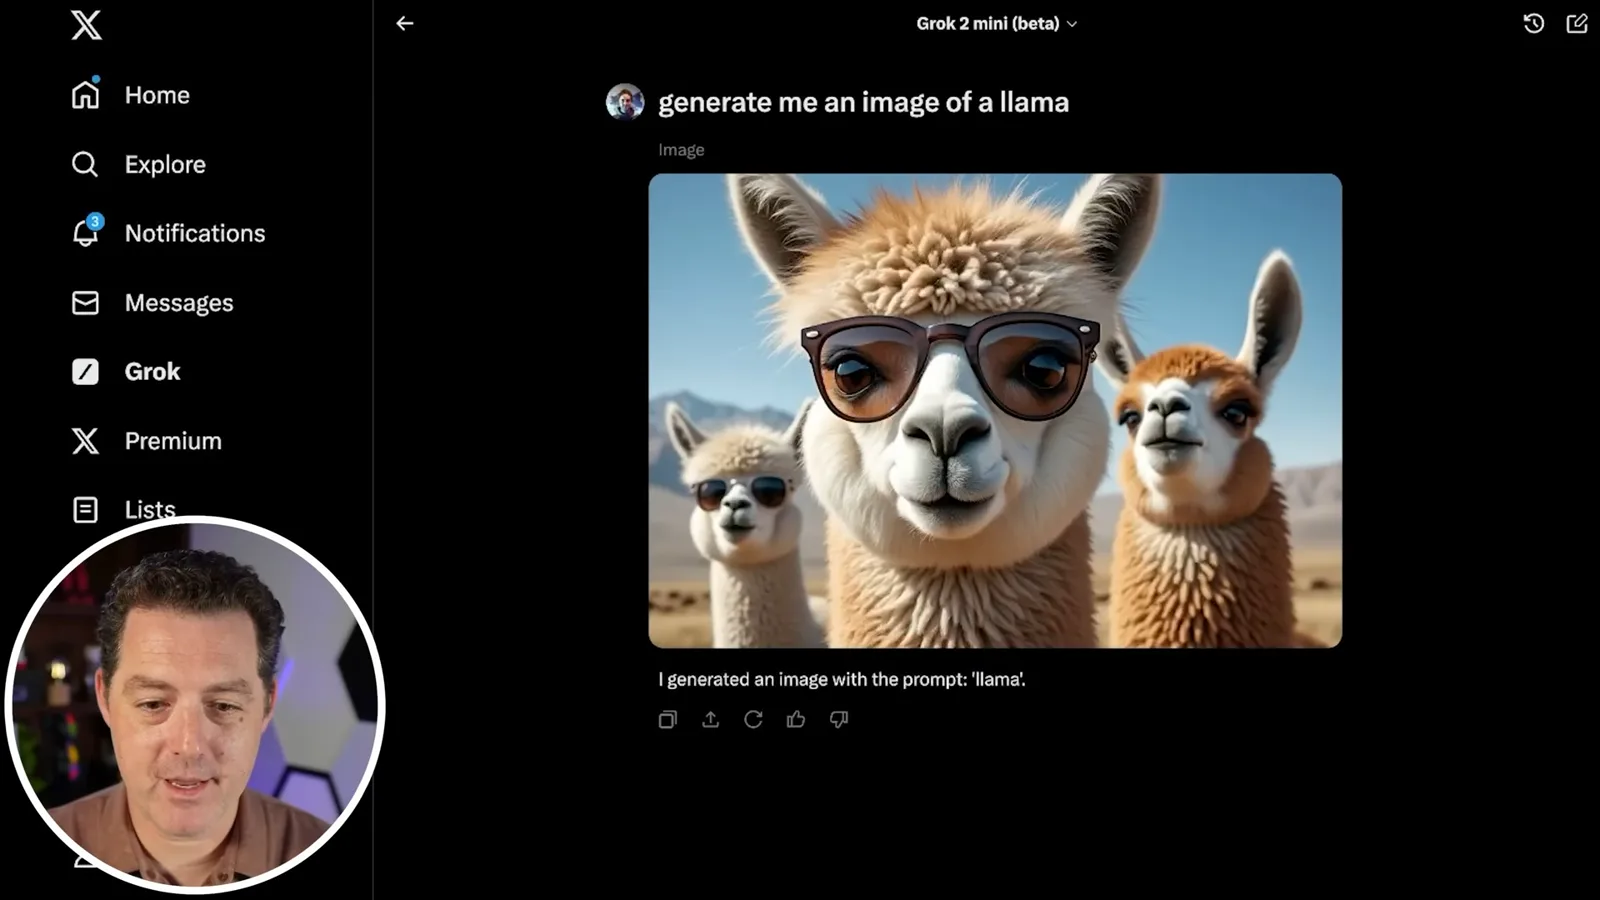
About an hour later image generation works, and a simple llama prompt produces an image. I then try a fictional character and several public-figure prompts, including a deliberately absurd image of Elon Musk. Some outputs are recognizable, while others miss parts of the request; they are generated images, not photographs of real events.
I ask for Mark Zuckerberg with different styling and for a Breaking Bad character, with mixed results. A more complex prompt involving Zuckerberg, Musk and Donald Trump also fails to represent the requested scene cleanly. The images look polished to me, but the complex prompt following is unreliable in this small test.
Finally, I ask for the day’s headlines and see a list of current events. Grok’s access to X posts can provide recent information, but a generated headline still needs verification. I close by observing how quickly striking synthetic images of public figures are spreading across the platform.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.