30초 요약
In November 2025, Matthew Berman surveys reactions to Gemini 3 Pro and argues Google has gained an advantage through models, infrastructure and distribution. He discusses Artificial Analysis results, scaling, Antigravity's connection to Windsurf, coding demos and ARC-AGI. Rankings, prices, anecdotes and predictions are specific to their time and conditions. Dell Technologies sponsored a portion of the video.
- 1A leading index resultArtificial Analysis reported Gemini 3 Pro Preview leading five of ten evaluations and its composite index at launch. The findings are specific to that suite and date.
- 2Scaling debateBerman cites Oriol Vinyals on improvements in pre-training and post-training and interprets them as evidence that scaling continues; the comments do not isolate parameter count as the cause.
- 3Antigravity and WindsurfAn interface reference to Cascade led observers to discuss Windsurf's connection to Google's new IDE. A nonexclusive license and hiring deal is distinct from an outright purchase.
- 4Sponsored segmentDell Technologies sponsored a promotion for Dell Pro Max laptops with NVIDIA RTX Pro hardware.
- 5ARC-AGI progress and remaining errorsMike Knoop highlights a leap on ARC-AGI-2 and a single fast solve, while noting mistakes on easier ARC-AGI-1 tasks.
핵심 정리
- Artificial Analysis placed Gemini 3 Pro Preview three index points above GPT-5.1 in its November 2025 evaluation; that is a specific benchmark result, not a permanent universal ranking.
- Fewer tokens on a benchmark do not automatically mean lower total cost: the model's historical API rates made its index run relatively expensive.
- Google licensed Windsurf technology nonexclusively and hired some staff; Cognition subsequently acquired Windsurf's remaining business and intellectual property.
- Google had already trained Gemini 1.0 on TPUs, so Gemini 3 was not the first Gemini model trained on them.
- ARC-AGI results and a single task's timing indicate progress under particular conditions, not general human-level intelligence.
- Dell Technologies sponsored the laptop promotion in the video.
챕터별로 다듬은 전문 읽기
Early benchmark reactions
Berman reviews Artificial Analysis results, historical pricing and speed. He then discusses reactions about scaling and training.
Google released Gemini 3 about a day ago, and the industry response is strong. I consider it the best model at the time, but any such judgment depends on the tasks, evaluation and date. I'm looking at reactions from analysts, researchers and builders.
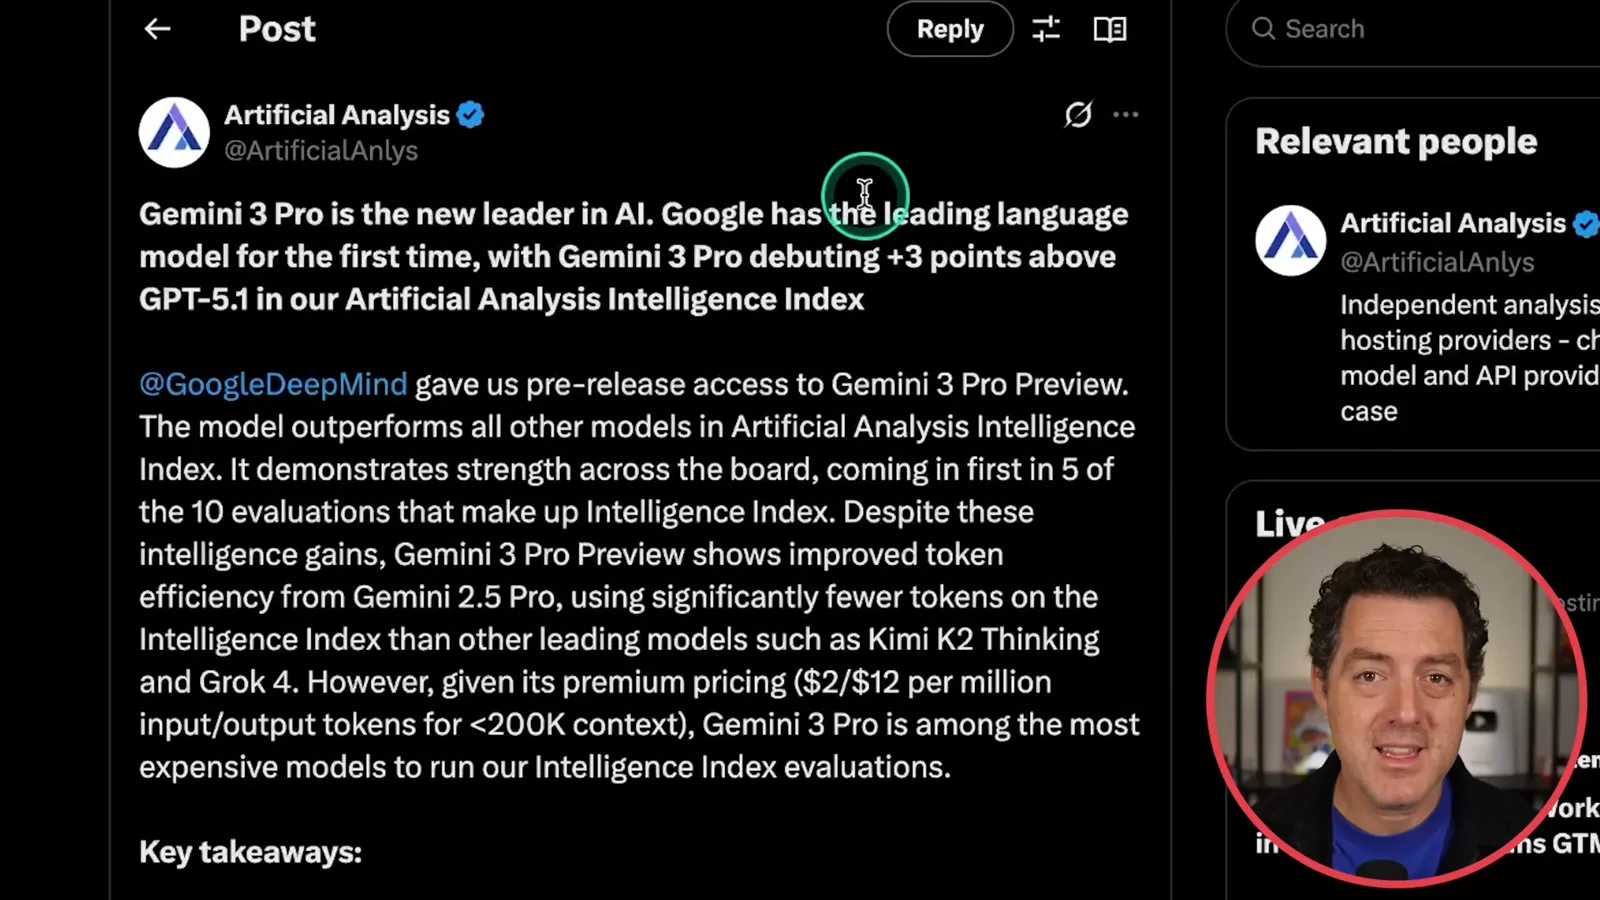
[Artificial Analysis](https://artificialanalysis.ai/articles/gemini-3-pro-everything-you-need-to-know) reported Gemini 3 Pro Preview three points ahead of GPT-5.1 on its Intelligence Index in November 2025, leading five of its ten component evaluations. It measured 37% on Humanity's Last Exam, more than ten percentage points above its previous best. These are results for that evaluator's particular methods and model configurations, not a guarantee of superiority on every task.
Artificial Analysis also reported improved token efficiency relative to Gemini 2.5 Pro and fewer tokens than some competing models on its index. At launch, Google listed $2 per million input tokens and $12 per million output tokens for prompts up to 200,000 tokens; despite token savings, Artificial Analysis found the index run comparatively expensive. Those are historical rates, not current pricing.
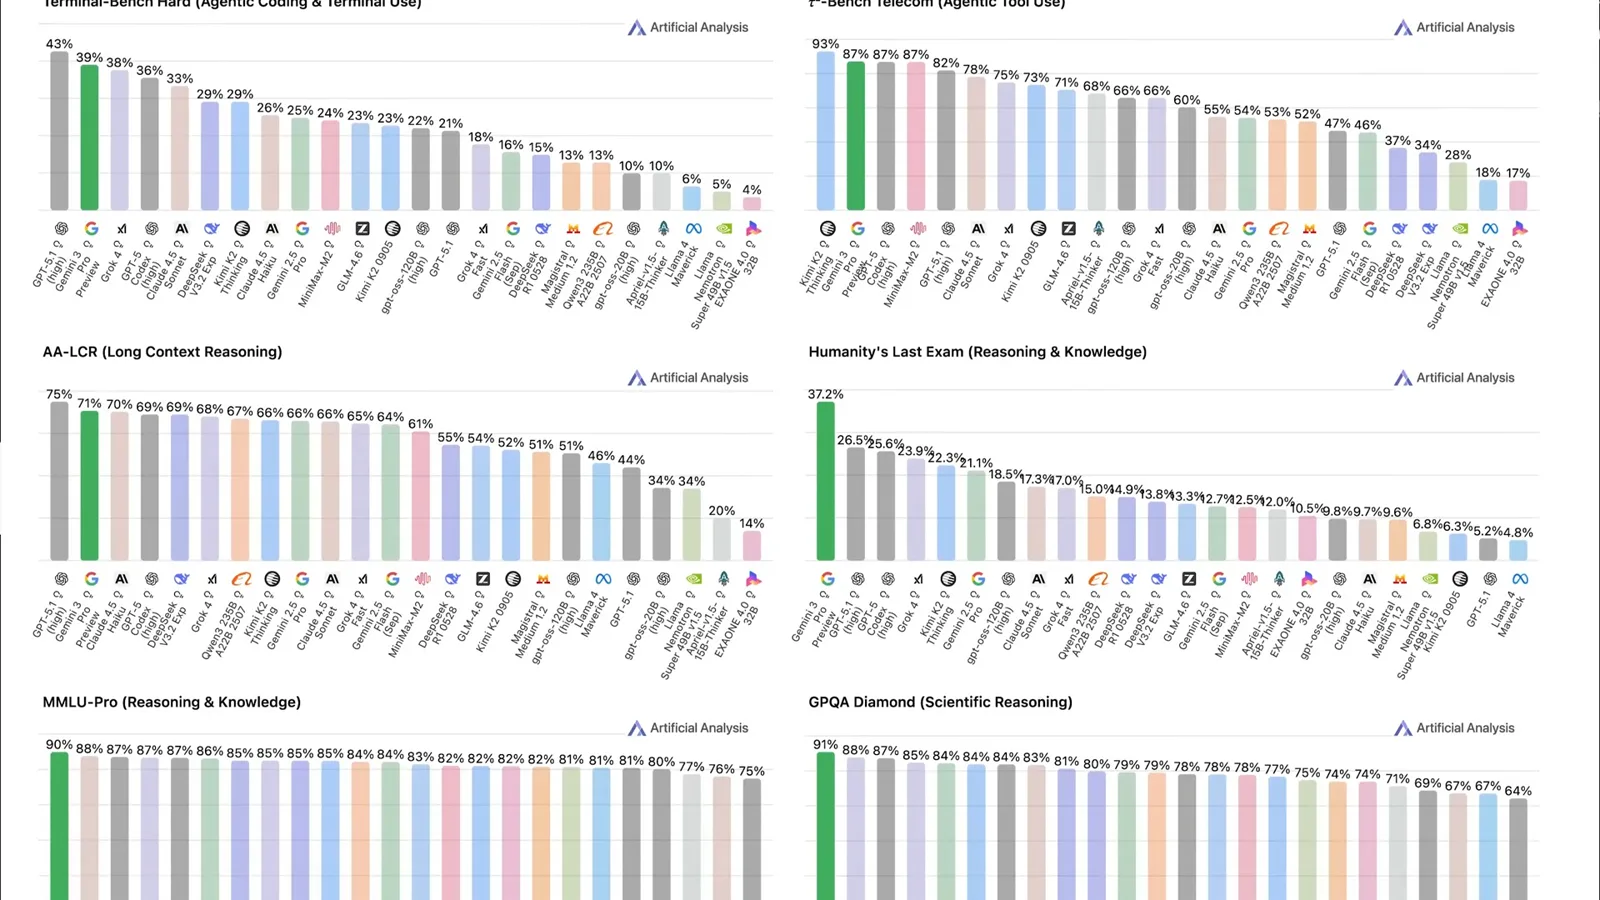
The analysis highlighted coding and multimodal results and measured about 128 output tokens per second, comparable to Gemini 2.5 Pro in its setup. I suspect Google's custom TPUs help with inference speed, but the observed throughput alone does not establish the cause, and speed depends on workload and serving conditions.
I also mention a free Gemini 3 prompt-engineering guide from my team, available in exchange for newsletter signup. It is a promotion for my own material.
Google DeepMind's Oriol Vinyals attributes progress to improvements in pre-training and post-training and says the jump from Gemini 2.5 to 3 was large. OpenAI's Boris Power also expressed optimism about scaling. I take these remarks as evidence that scaling remains promising, but neither statement establishes that increasing parameter count alone caused the improvement or guarantees indefinite gains.
Antigravity, Windsurf and sponsorship
He examines a leftover Cascade reference and the history of Google and Cognition's Windsurf transactions. A Dell-sponsored segment follows.
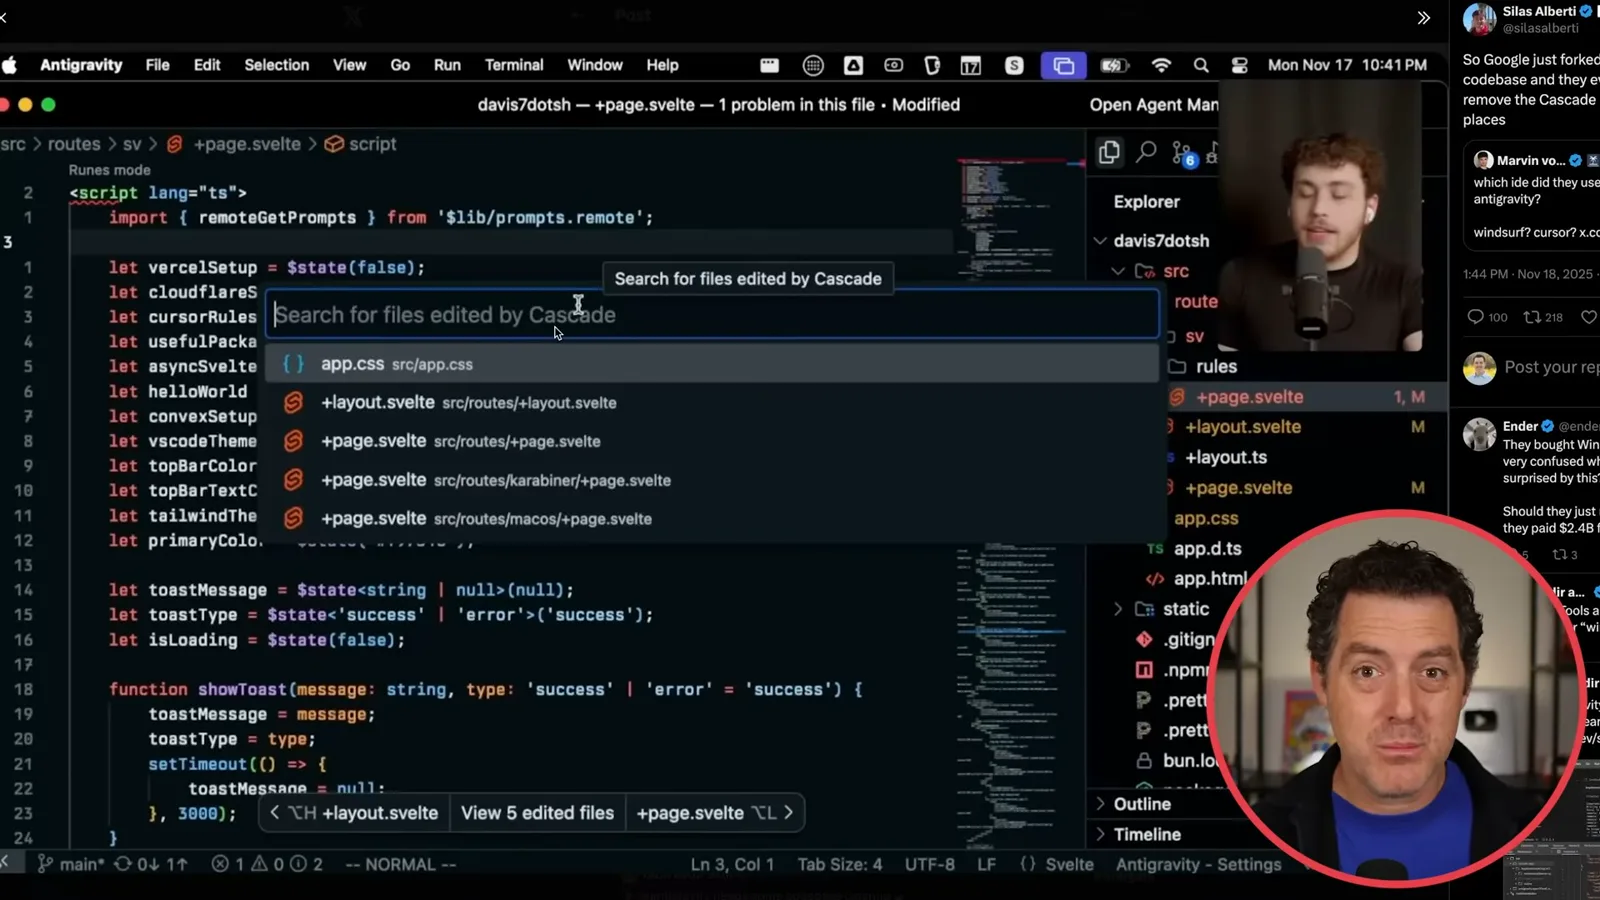
Google also launched Antigravity, an agentic coding environment associated with former Windsurf CEO Varun Mohan. Observers noticed an interface reference to Cascade, Windsurf's agent feature, and debated how much technology was reused. A leftover label suggests a connection but does not by itself establish the full architecture or make Antigravity simply a clone.
Google hired Mohan and some Windsurf staff and obtained a nonexclusive license to certain technology; reporting put the deal at about $2.4 billion. It did not buy the entire company or outright own all of Windsurf's IP through that arrangement. Cognition subsequently acquired Windsurf's remaining business, product and intellectual property, as its [transaction counsel](https://www.lw.com/en/news/latham-watkins-advises-cognition-in-acquisition-of-windsurf) described. Scott Wu joked about the remaining Cascade label.
Dell Technologies sponsored this portion of the video. Berman promotes Dell Pro Max laptops with NVIDIA RTX Pro Blackwell graphics, describing 14- and 16-inch configurations and up to 32 GB of GPU memory. Product configurations and availability depend on the specific model and date.
Google's business position and demos
Industry figures congratulate Google, and Berman discusses design rankings, custom chips and distribution. He shows illustrative coding demos.
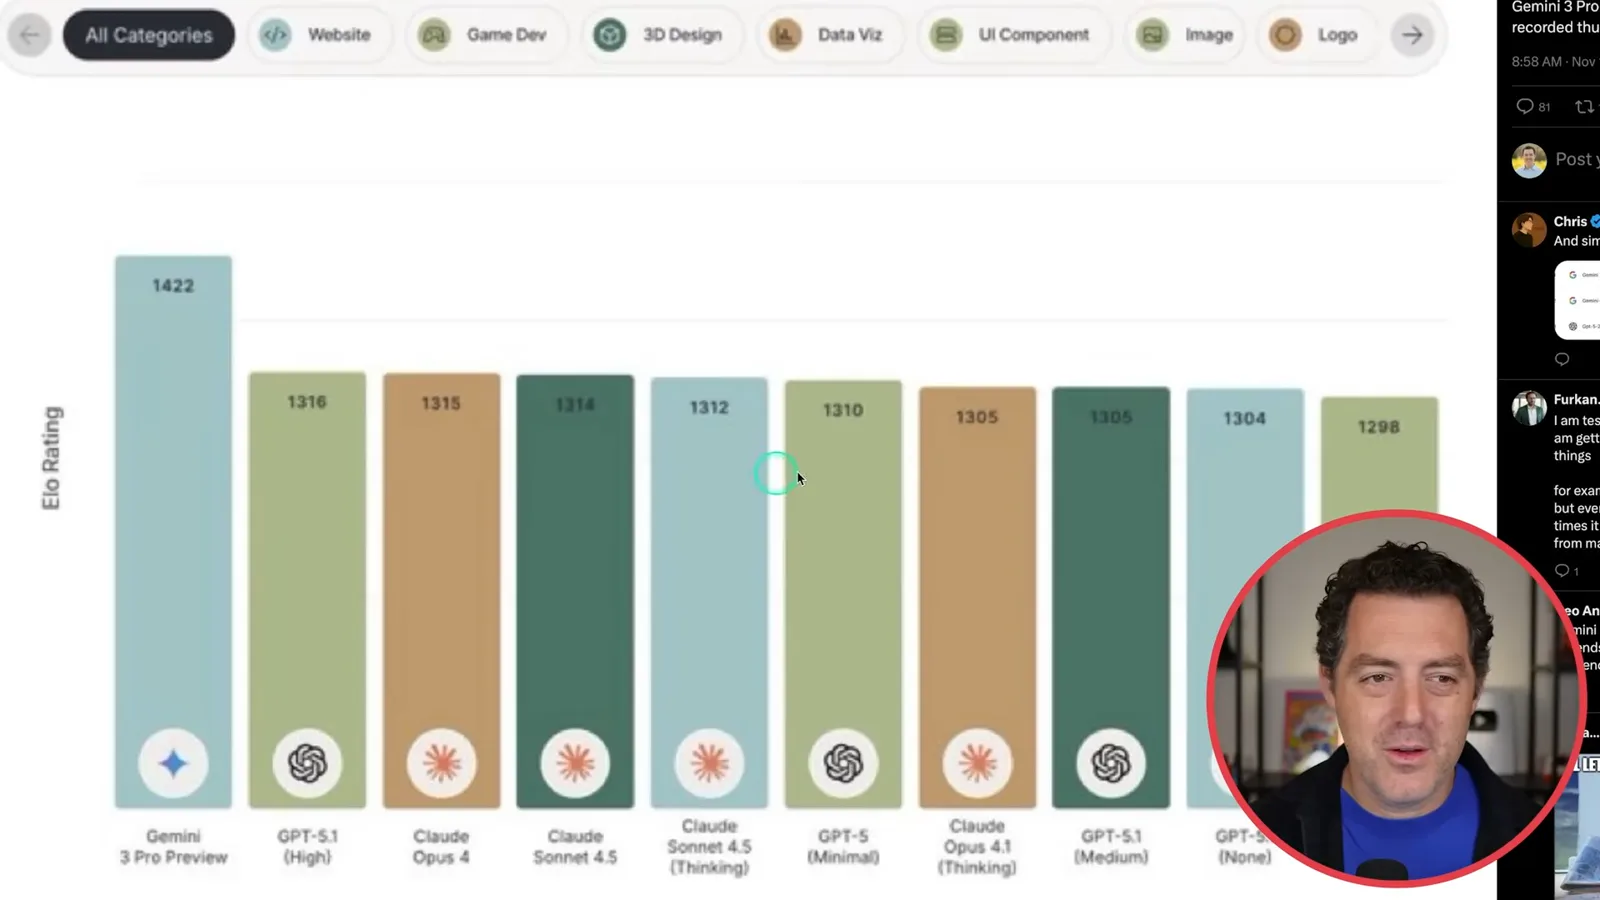
Sam Altman and Elon Musk publicly congratulated Google on the release. I like seeing competitors acknowledge one another while continuing to compete. Google AI Studio lead Logan Kilpatrick also shared a Design Arena screenshot showing Gemini 3 Pro Preview at 1422 Elo versus GPT-5.1 at 1316; this is a particular historical preference ranking, not a universal design-quality score.
Investor Deedy Das argues that Google combines model capability, distribution and custom chips. I agree that its user base and infrastructure are advantages, although the $2/$12 launch rates are premium rather than obviously cheap. Owning chips does not alone prove a particular unit cost or margin.
I speculate that training Gemini 3 on TPUs might be a first for the family, but [Google said Gemini 1.0 was already trained on TPU v4 and v5e](https://blog.google/innovation-and-ai/technology/ai/google-gemini-ai/). I see Google's data, products, distribution, hardware and research as a strong combination, and compare it with the other large technology companies. These competitive assessments are opinions, not settled market outcomes.
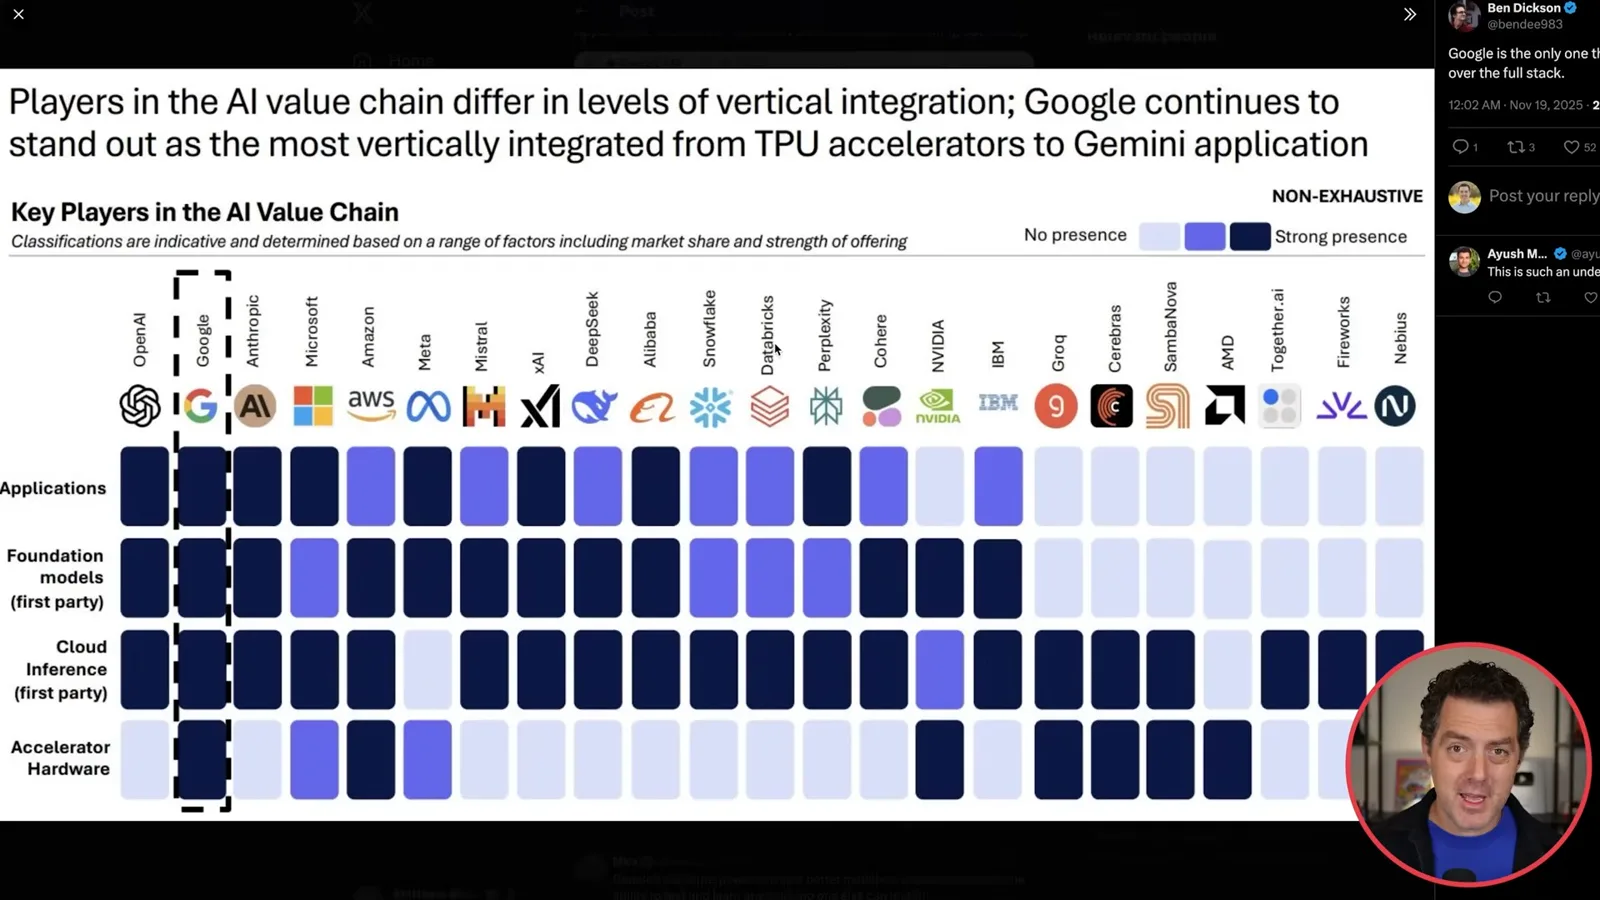
A graphic presents Google's position across applications, foundation models, cloud inference and accelerators; its classifications are indicative rather than an exhaustive audit. Ryan Petersen jokes that Google could end up dominating AI after a period when its position seemed weaker. I describe that change as a striking turnaround, while the competitive picture remains fluid.
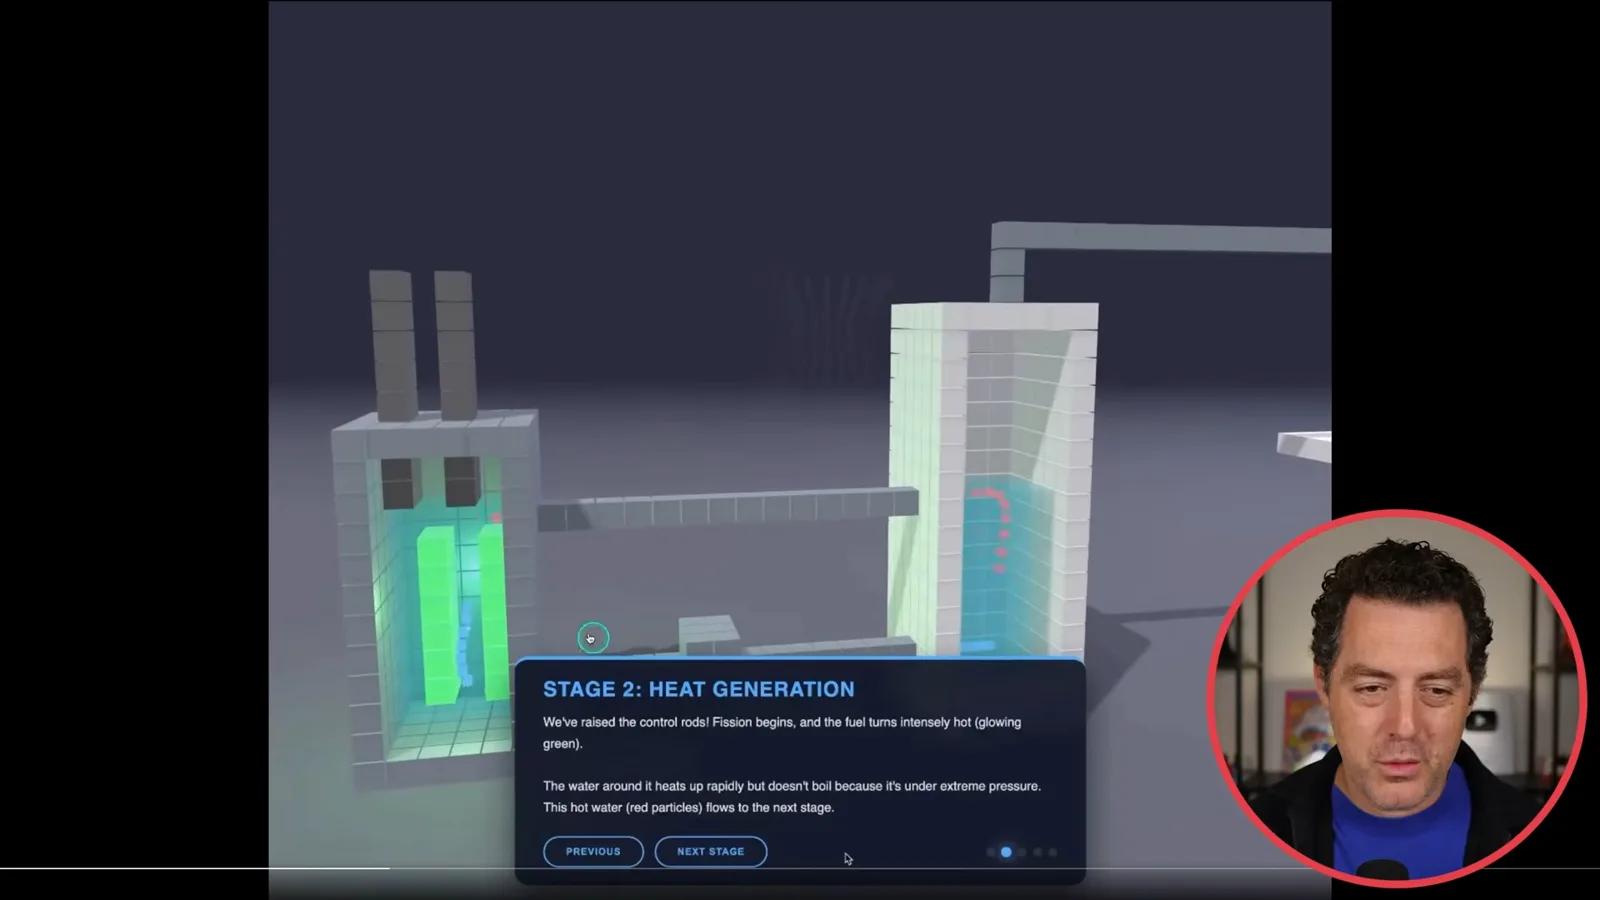
One shared demo shows an interactive voxel-style explainer of a nuclear reactor, reportedly made in two attempts, with stages such as heat generation. I clarify that zero-shot and one-shot traditionally refer to the number of examples supplied in a prompt, though people sometimes use the terms for the number of attempts. A visual demonstration is not validation of reactor accuracy or a controlled comparison.
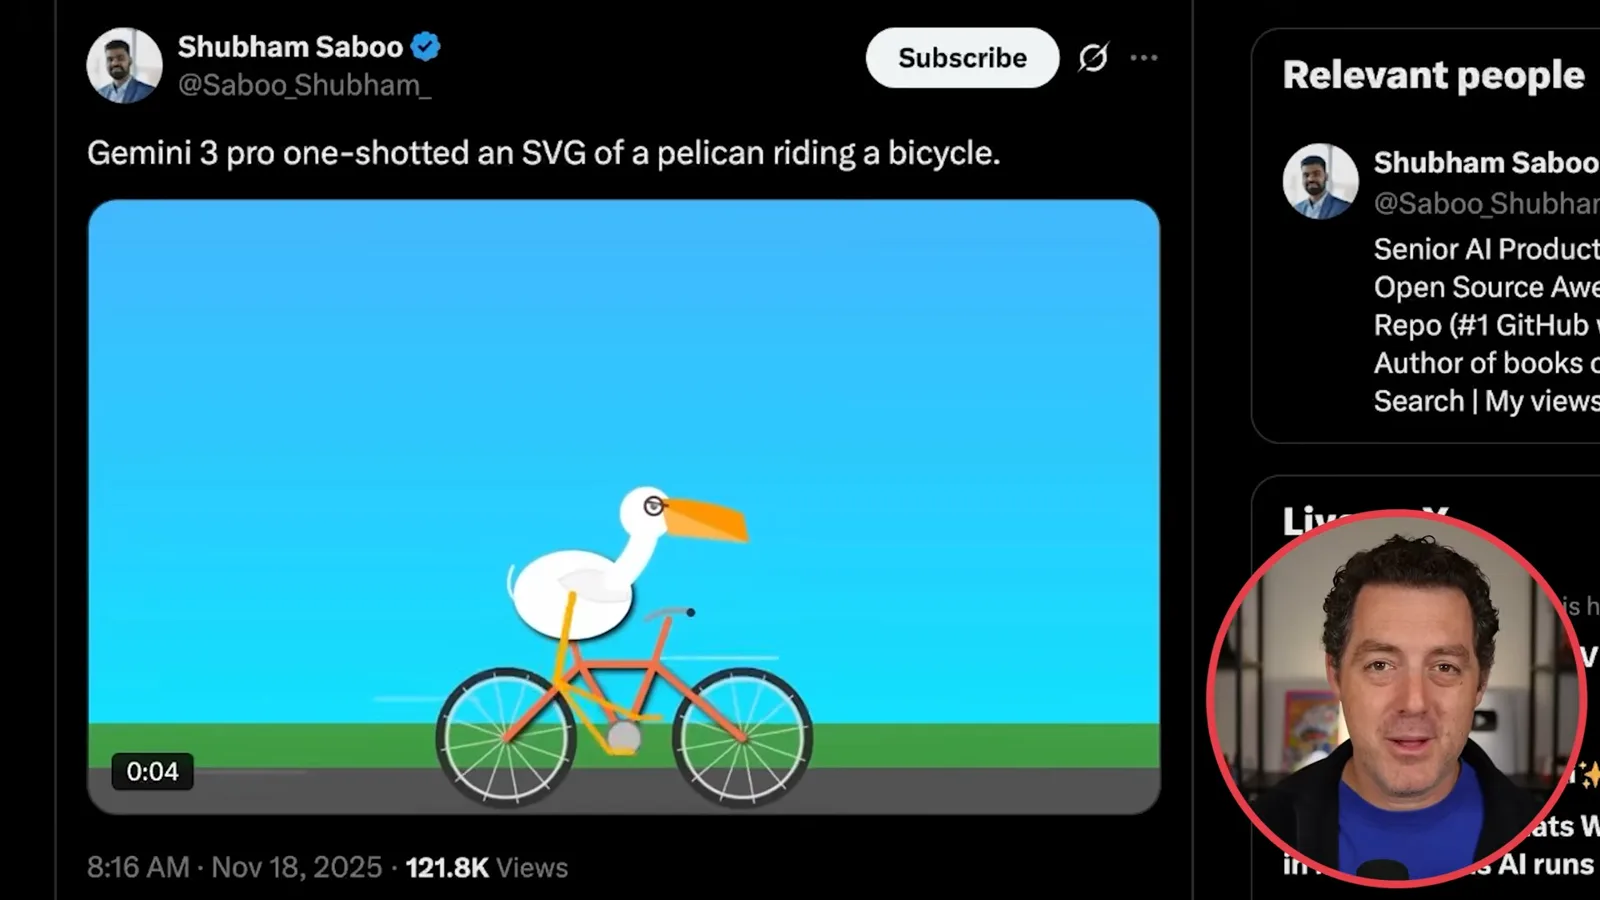
Another shared example reportedly produces an animated SVG of a pelican riding a bicycle in one attempt. I find the result impressive, but a selected demo alone cannot show typical success rates or the amount of work behind it.
Efficiency and ARC-AGI
Berman discusses token efficiency and autonomy before reviewing ARC-AGI results. He notes that stronger performance on version 2 did not eliminate errors on version 1.
Emad Mostaque emphasizes token and tool-call efficiency. I argue that the value of an agent depends on what it accomplishes in a given time, not merely how long it runs unattended. Token count, latency, task quality and price all matter, and none by itself captures a general quantity of intelligence.
ARC Prize's Mike Knoop reported a large ARC-AGI-2 improvement for Gemini 3 Pro and Deep Think in the initial comparison. The [ARC leaderboard](https://arcprize.org/leaderboard) lists the standard Gemini 3 Pro at 31.1% on ARC-AGI-2 and 75.0% on ARC-AGI-1 under its specified evaluation, with different configurations carrying different costs. These puzzle scores do not establish AGI or broad human equivalence.
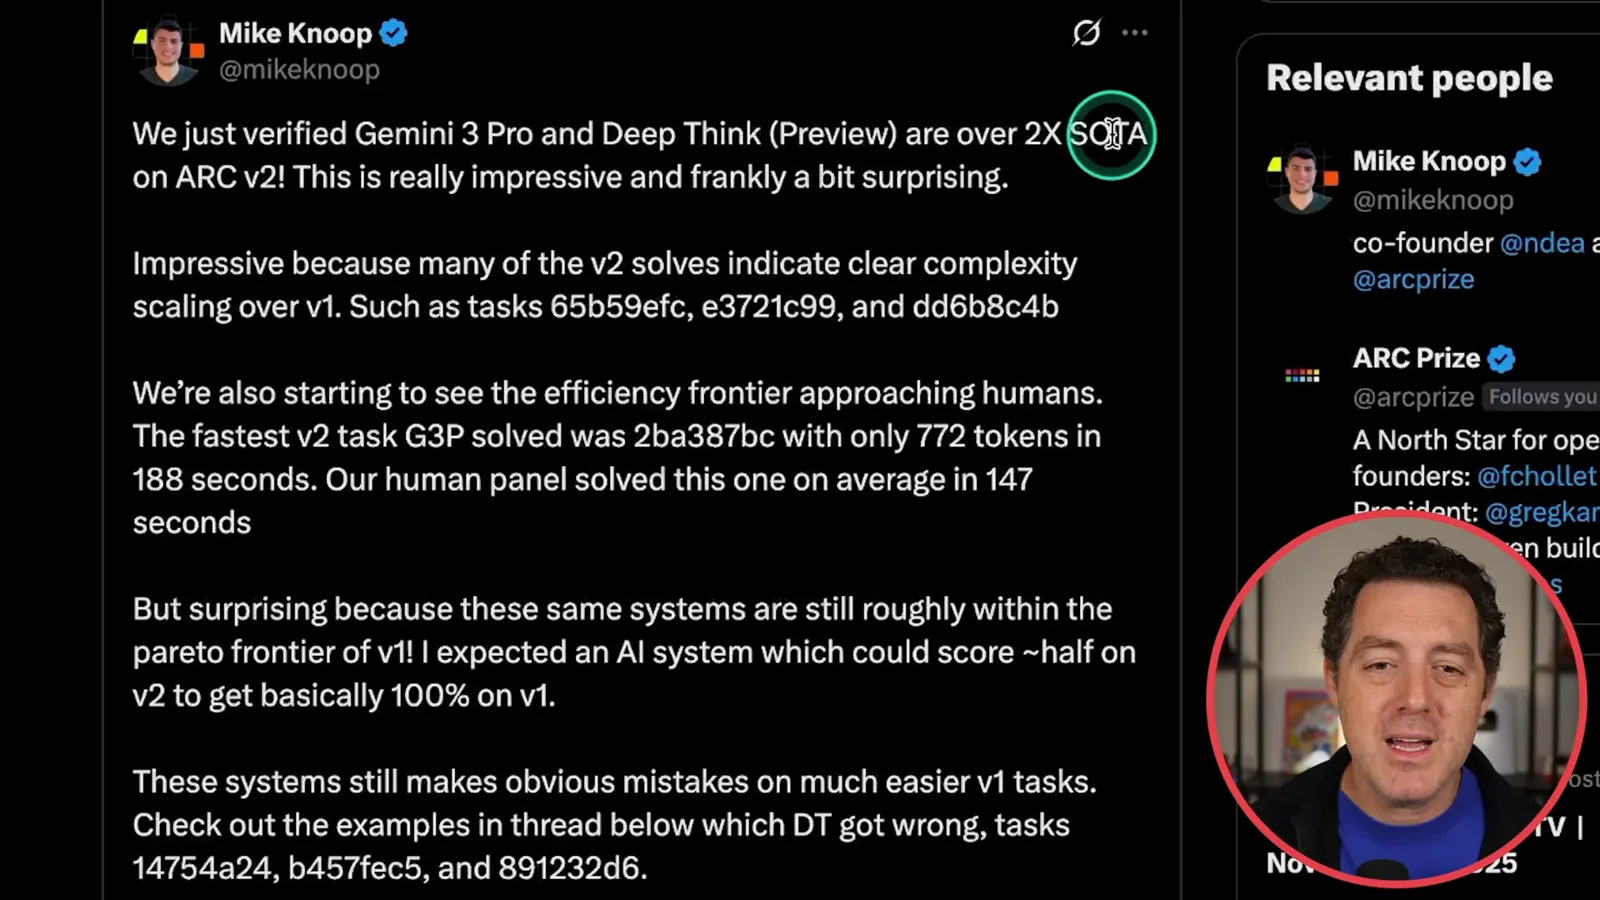
Knoop highlighted one fastest solved ARC-AGI-2 task: Gemini 3 Pro used 772 tokens and 188 seconds, while the human panel averaged 147 seconds on that task. One selected task and two different measures are not a general comparison of human and model efficiency. He also found it surprising that the systems still made mistakes on easier ARC-AGI-1 tasks even after their version 2 gains.
The results suggest improvement in some areas alongside persistent errors in others. My team is preparing a separate Gemini 3 testing video with more demonstrations.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.