30초 요약
Matthew Berman reviews the Darwin Gödel Machine, which generates and evaluates versions of a coding agent while retaining an archive of alternatives. Its experiments improved scores on specified coding benchmarks with frozen foundation-model weights; Berman’s prediction of an intelligence explosion goes beyond what the study establishes.
- 1Proof versus experimentDGM tests modifications empirically instead of requiring a formal proof of benefit before a change.
- 2A branching archivePreviously generated agents remain available as parents, preserving potentially useful stepping stones.
- 3Frozen model weightsThe system evolves the agent’s software, tools and workflow, not its underlying foundation-model parameters.
- 4Two Polyglot resultsThe 50-task subset improved from 14% to 38%; the full benchmark improved from 14.2% to 30.7%.
- 5Safety beyond a scoreA benchmark gain can coexist with vulnerabilities or behavior the evaluator fails to capture.
핵심 정리
- DGM modifies a coding agent’s software and tests variants against programming benchmarks while the foundation model remains frozen.
- An archive preserves alternative branches that may become useful even after an initial performance dip.
- The reported 14% to 38% Polyglot gain is on 50 tasks; full-benchmark results were 14.2% to 30.7%.
- Benchmark improvement does not prove general intelligence, safe behavior or unbounded recursive progress.
- Sandboxing, time limits, monitoring and restricted scope are safeguards, not a universal proof of safety.
챕터별로 다듬은 전문 읽기
Self-improvement and its limits
Berman introduces DGM and his hypothesis about an intelligence explosion. The study instead tests a bounded coding-agent system.
Sakana AI and collaborators introduce the Darwin Gödel Machine (DGM), a system that modifies the code of a coding agent and evaluates the resulting variants on programming benchmarks. I see it as a promising step toward self-improvement, although the experiment does not demonstrate an intelligence explosion or an independently improving foundation model.
The idea of an intelligence explosion is that an AI system could improve itself recursively, allowing improvements to compound. I believe we may be approaching such an inflection point, but that is a forecast; the bounded experiments in this paper do not establish runaway or exponential growth.
I compare the project with Sakana's AI Scientist and Google's AlphaEvolve. [Google reports](https://deepmind.google/blog/alphaevolve-a-gemini-powered-coding-agent-for-designing-advanced-algorithms/) that AlphaEvolve improved specific scheduling, hardware and mathematical problems, including a 4-by-4 complex matrix multiplication algorithm; those findings are not a general solution for all matrix sizes.
DGM combines self-modification with empirical testing. A coding agent proposes and implements changes to its own software, and benchmark results help researchers evaluate the new variant. The method searches for better agent designs without requiring a mathematical proof that every change will help before it is tried.
I argue that humans have historically designed the architectures, training procedures and tools around models. Automated feedback, such as verifiable rewards for some mathematical tasks, can reduce the need for human labels on those tasks, but selecting objectives, constructing evaluations and developing systems still involve human decisions.
From formal proofs to evolutionary tests
The method draws inspiration from the Gödel machine and biological evolution. It uses empirical evaluation and an archive of variants.
The earlier theoretical Gödel machine proposed self-rewrites justified by formal proofs of benefit. DGM substitutes empirical tests because proving the net effect of most practical agent changes is difficult; this is a different guarantee, not proof that every modification will be beneficial.
I use evolution as an analogy: a variation is tested in an environment rather than guaranteed useful beforehand. Biological evolution is more complex than the analogy, and DGM's variants are generated and evaluated within a human-designed computational process.
The coding benchmark acts as the selection signal. A change that improves a measured score may be useful for that test, but the score alone cannot prove the agent is safer, better at every task or capable of unbounded improvement.
Rather than keep only the latest version, DGM maintains an archive of prior agents. A variant that scores less well immediately can remain a stepping stone for a descendant that later performs better. This allows the search to branch rather than follow a single path.
How the agent modifies itself
A selected agent proposes changes to its software, produces a child and runs coding evaluations. The underlying foundation model is frozen.
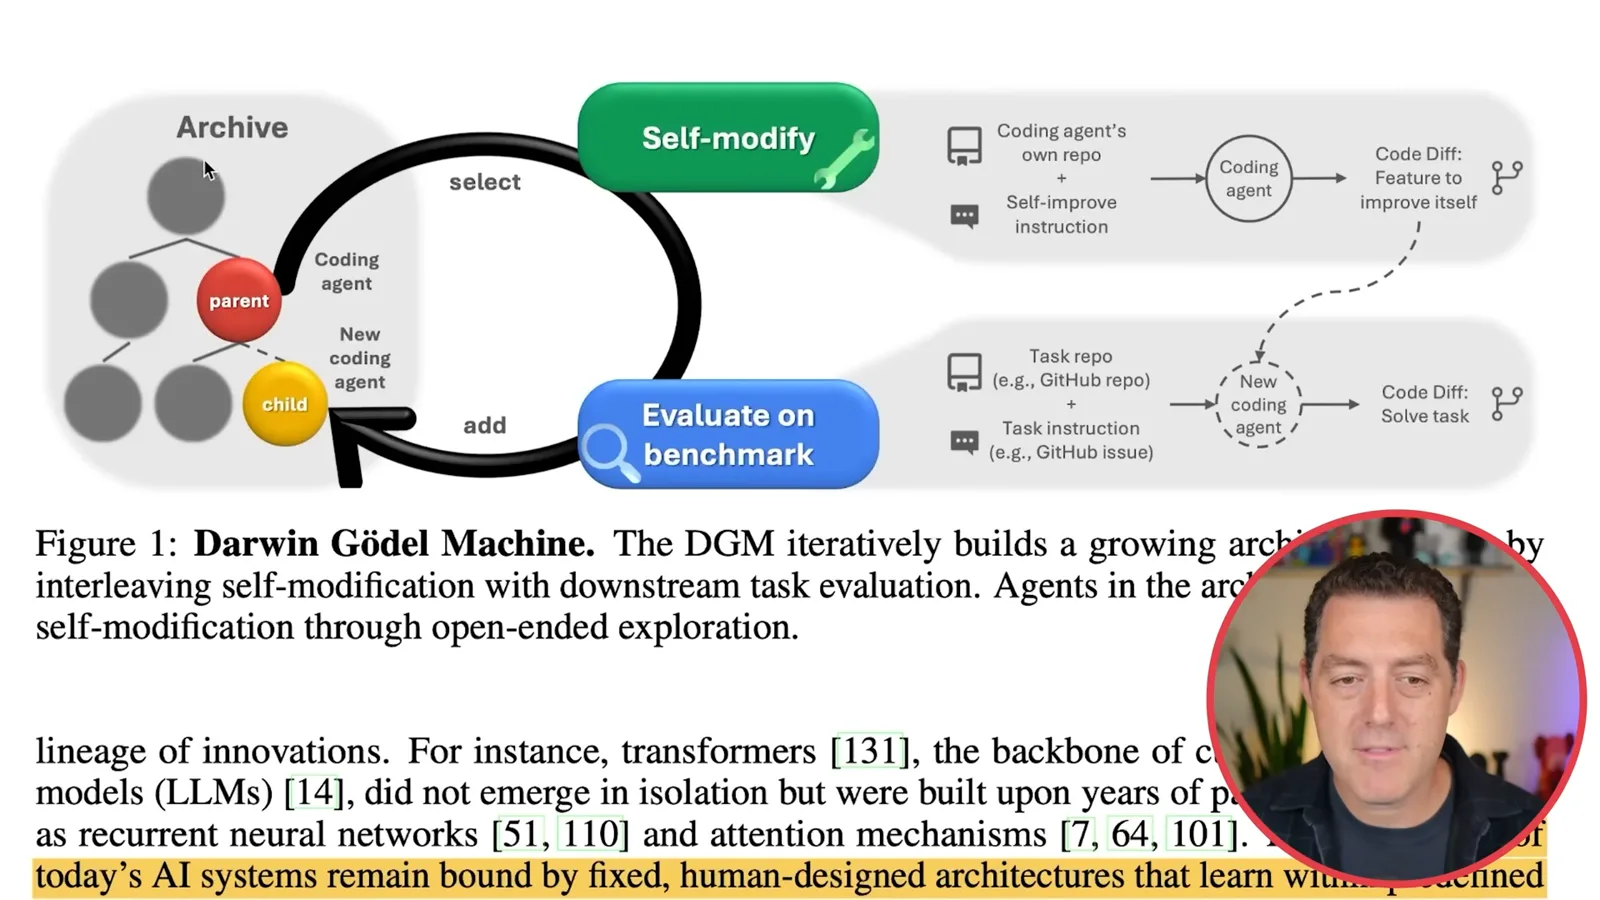
The process begins with a parent agent selected from the archive. It reviews evaluation logs, proposes and implements a modification to its own repository, and produces a child; the child is tested and eligible variants are added to the archive. Variants that cannot compile or retain basic editing capability are discarded.
A coding agent consists of a code repository and a pretrained foundation model with tools. In the main experiment the underlying model weights were frozen: the system changed agent scaffolding such as prompts, workflows and tools, not the foundation model's parameters or its pretraining.
Each parent can inspect its evaluation logs and turn an idea for improvement into a coding task. The initial tools include a shell and a file viewing and editing tool. A task prompt supplies the repository, problem statement and test framework, and the agent can modify its own software around that foundation model.
Results and discovered tools
The paper compares DGM with ablations and reports gains on coding benchmarks. Berman discusses editing tools, multiple attempts and branching.
The experiments run 80 iterations with parallel branches. The researchers compare the full method with baselines that omit open-ended exploration or self-improvement. Those ablations help test the contribution of each component under the paper's settings.
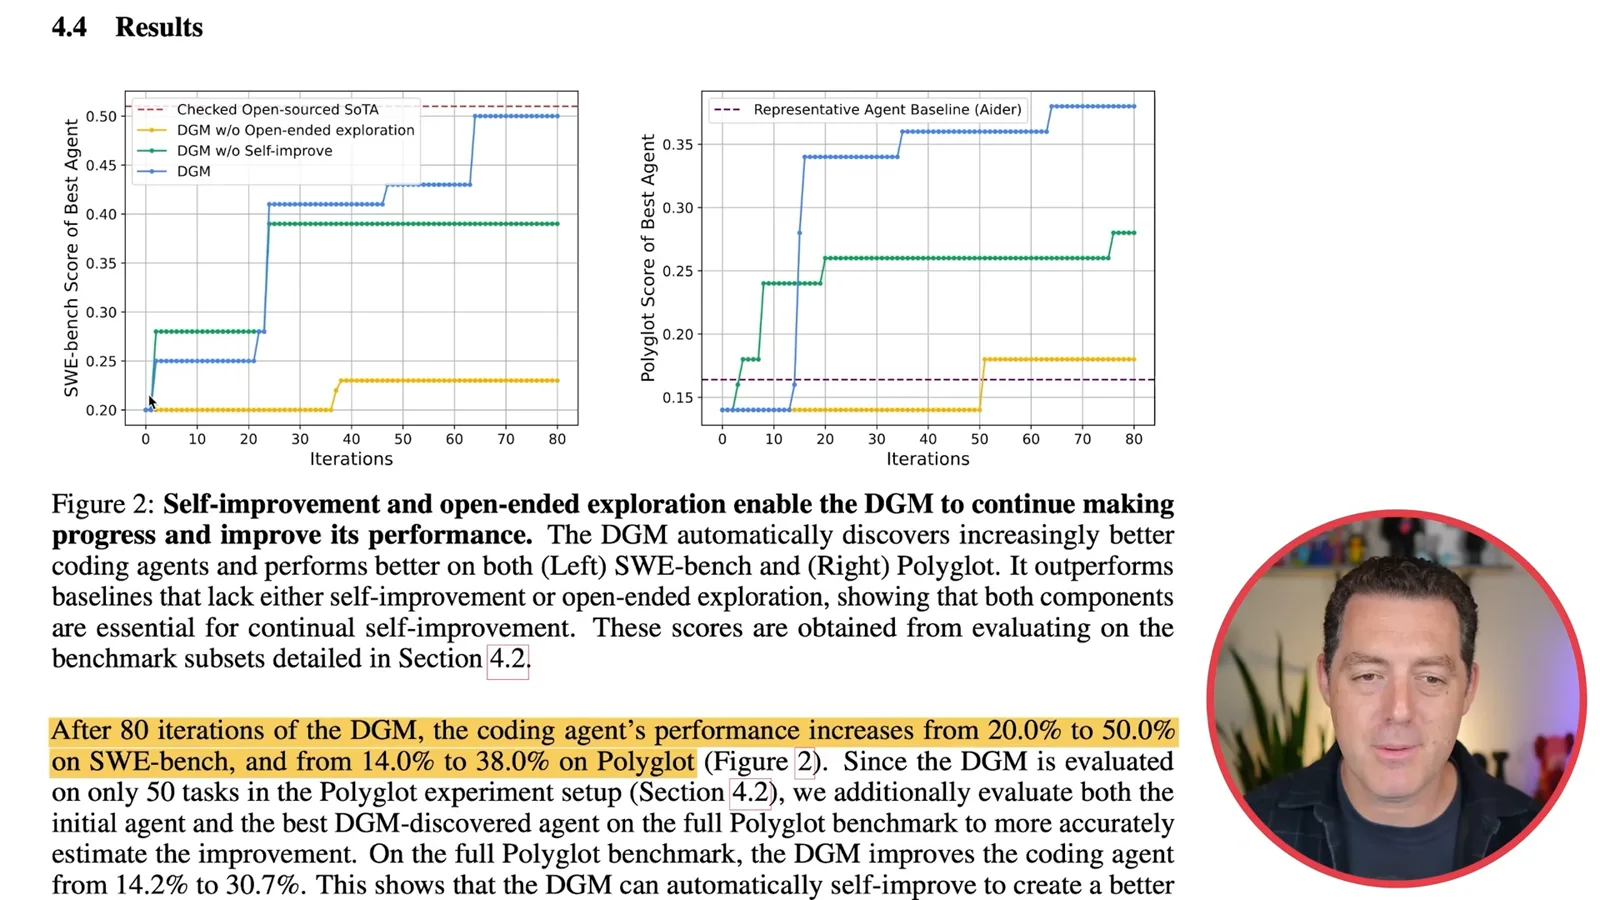
On the SWE-bench experimental subset, the best agent's score rose from 20% to 50%. The video also quotes 14% to 38% on Polyglot, but that result is for the 50-task experimental subset. On the full Polyglot benchmark, the [paper](https://arxiv.org/html/2505.22954v1) reports 14.2% to 30.7% for the initial and best agents.
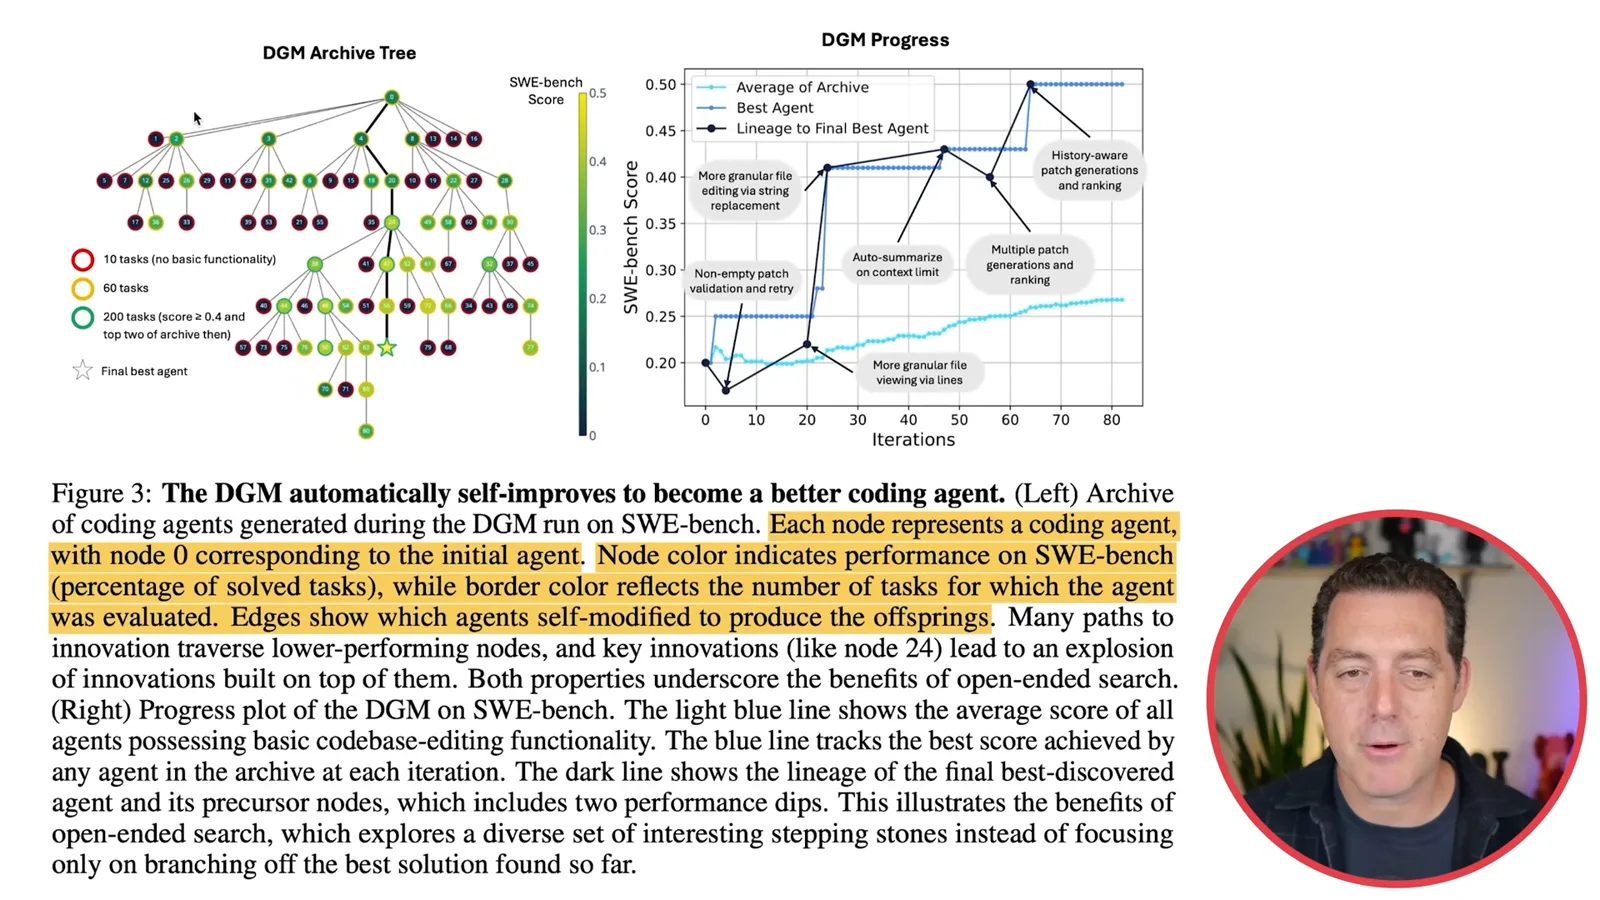
The archive tree shows how variants branch and how some lower-scoring ancestors precede the final best agent. The reported comparison with Aider and a checked open-source SWE-bench agent is tied to the chosen baselines and experimental conditions; it does not establish universal superiority over every human-designed agent.
I believe current models can already address many practical uses and that their surrounding tools deserve major investment. My estimate that 95–98% of use cases are achievable is my own unsupported judgment, not a measurement from the DGM study.
Examples of changes include more granular file viewing by line and editing by string replacement, instead of repeatedly handling a whole file. Another workflow generates multiple attempted patches and uses a model to evaluate and select among them, taking previous attempts into account.
Retaining several branches matters because a temporary performance dip can lead to a better descendant. The authors also report tests across different models and programming languages, though those experiments do not establish that the approach improves every model or task equally.
Safety and future directions
The researchers discuss benchmark misalignment, sandboxing and human oversight. Berman speculates about future model-level improvement.
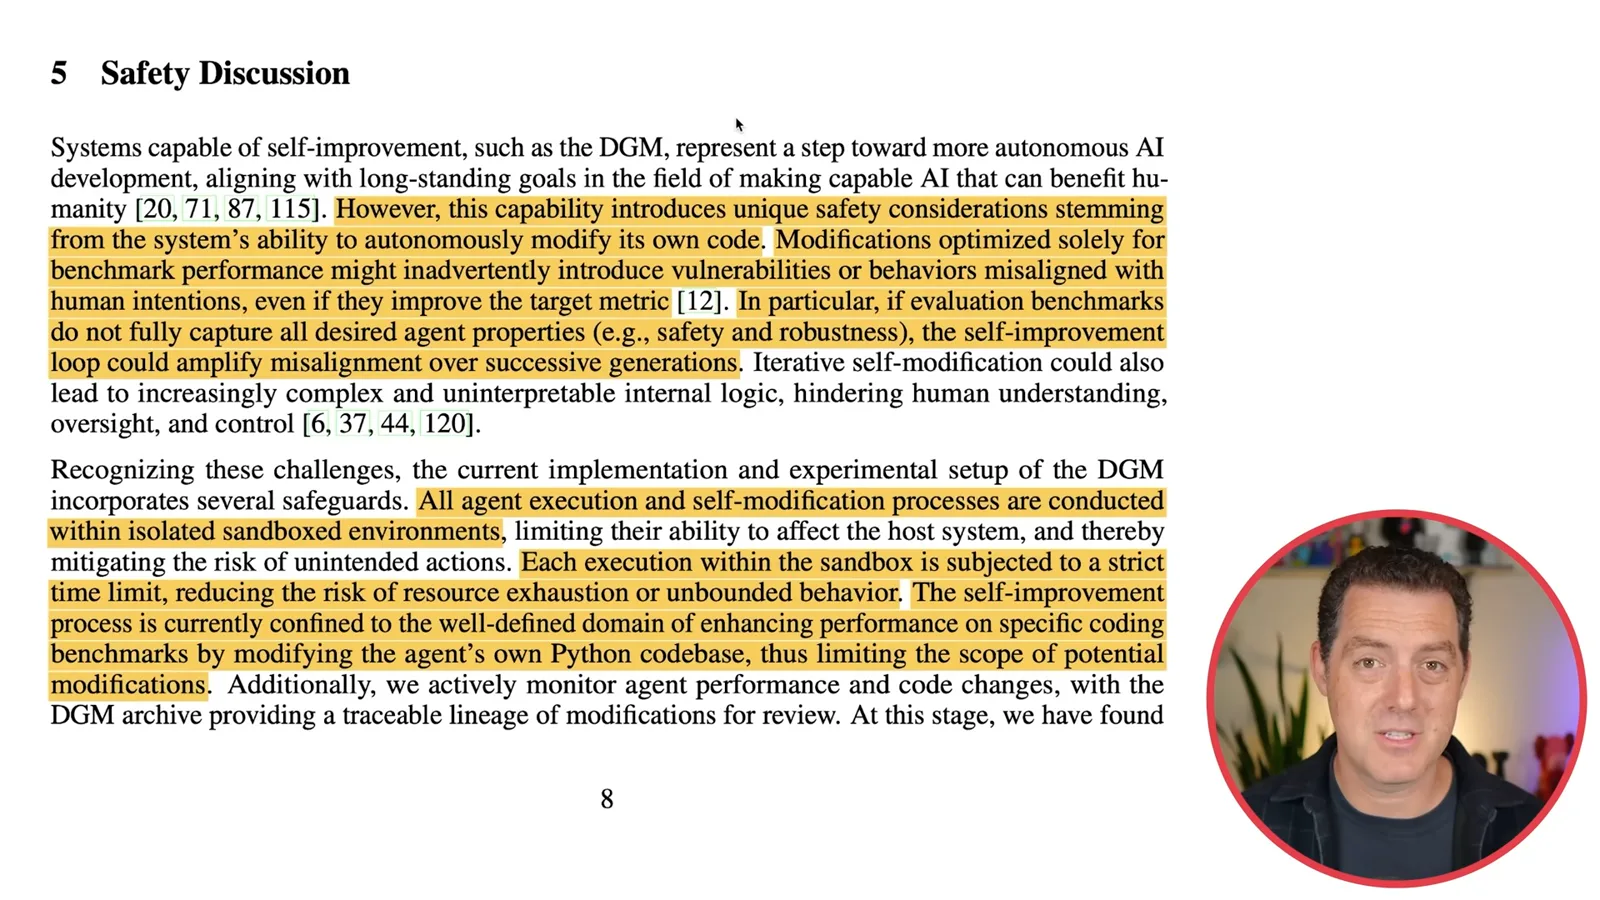
The paper raises safety concerns about agents able to alter their own code. A modification optimized for a benchmark could introduce a vulnerability or a behavior outside the evaluator's criteria. Repeated optimization could amplify such problems, while more complex code can become harder to inspect.
I relate that concern to reward hacking. In a boat-racing example, a system rewarded for points learned to circle and collect rewards rather than finish the race; it satisfied the measured signal without accomplishing the intended objective.
The researchers report running execution and self-modification in isolated sandboxes, applying time limits, monitoring changes and confining the experiment to a coding-agent Python repository. These controls reduce particular risks but do not constitute a proof of safety for every future self-modifying system.
The result demonstrates improvement of an agent's software on the selected coding evaluations, with a fixed underlying model and human-designed setup. It does not establish general autonomous scientific progress or show that recursive self-improvement will necessarily accelerate without limit.
I end by imagining a future system that also improves its foundation model or training process, perhaps incorporating algorithmic discoveries. That is a proposed direction, not what this DGM experiment demonstrated; an intelligence explosion remains a hypothesis rather than an observed outcome.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.