30초 요약
An agent may need to resume work days later, briefly use many CPUs or GPUs, and share files with other agents—all without running expensive compute while idle. Modal CTO Akshat Bubna describes separating the agent’s control loop from the environment executing its tools, persisting workspace state and enforcing fine-grained network rules. Usage from Ramp’s coding agent illustrates why provisioning every sandbox for its peak would waste resources. Bubna argues that reliability, isolation and scaling deserve deliberate engineering.
- 1A spreadsheet of agents needs isolation and shared stateBubna describes an agent per cell, with a separate tool-execution container and shared storage for collaboration.
- 2Keep the workspace when the compute stopsAn accounting agent may wait days for a person; persisted state allows it to resume without paying for idle compute.
- 3Peak resource demands vary sharply between and within agentsRamp Inspect usage illustrates why reserving every sandbox for the highest CPU and memory peak can be uneconomic.
- 4Domain allowlists alone may not protect sensitive dataBubna describes credential isolation and a sidecar proxy with rules for specific operations and paths.
- 5Sandbox infrastructure needs reliability, security and scaleThe Modal CTO argues that rare failures, evolving security boundaries and large workloads require deliberate system design.
핵심 정리
- Persist workspace state separately from idle compute so an agent can resume after a human response.
- Separate the agent control loop from tool execution and protect the boundary between them.
- Size CPU and memory for changing demand rather than assuming every agent needs its peak continuously.
- Control network destinations and individual operations; keep credentials out of the agent’s view where possible.
- Expose logs, utilization and budget information to agents as well as people.
챕터별로 다듬은 전문 읽기
What a spreadsheet full of agents needs
Bubna uses a financial-analysis spreadsheet to explain sandboxes, separate tool execution and shared storage. Many agents must start and stop quickly.
What infrastructure do agents actually need? Akshat Bubna, co-founder and CTO of Modal, starts with a financial-analysis spreadsheet in which each cell can be backed by its own agent. An analyst could ask a question across portfolio companies without manually repeating the work for every row.
A Modal customer has built a product along these lines, he says. The question is what happens underneath when a single spreadsheet query starts many independent agents and later brings their work together.
In the architecture he presents, each agent uses a sandbox: an isolated environment for running code. The agent loop, or harness, calls the model and decides which tools to use; the actual tool execution is separated into another container for isolation.
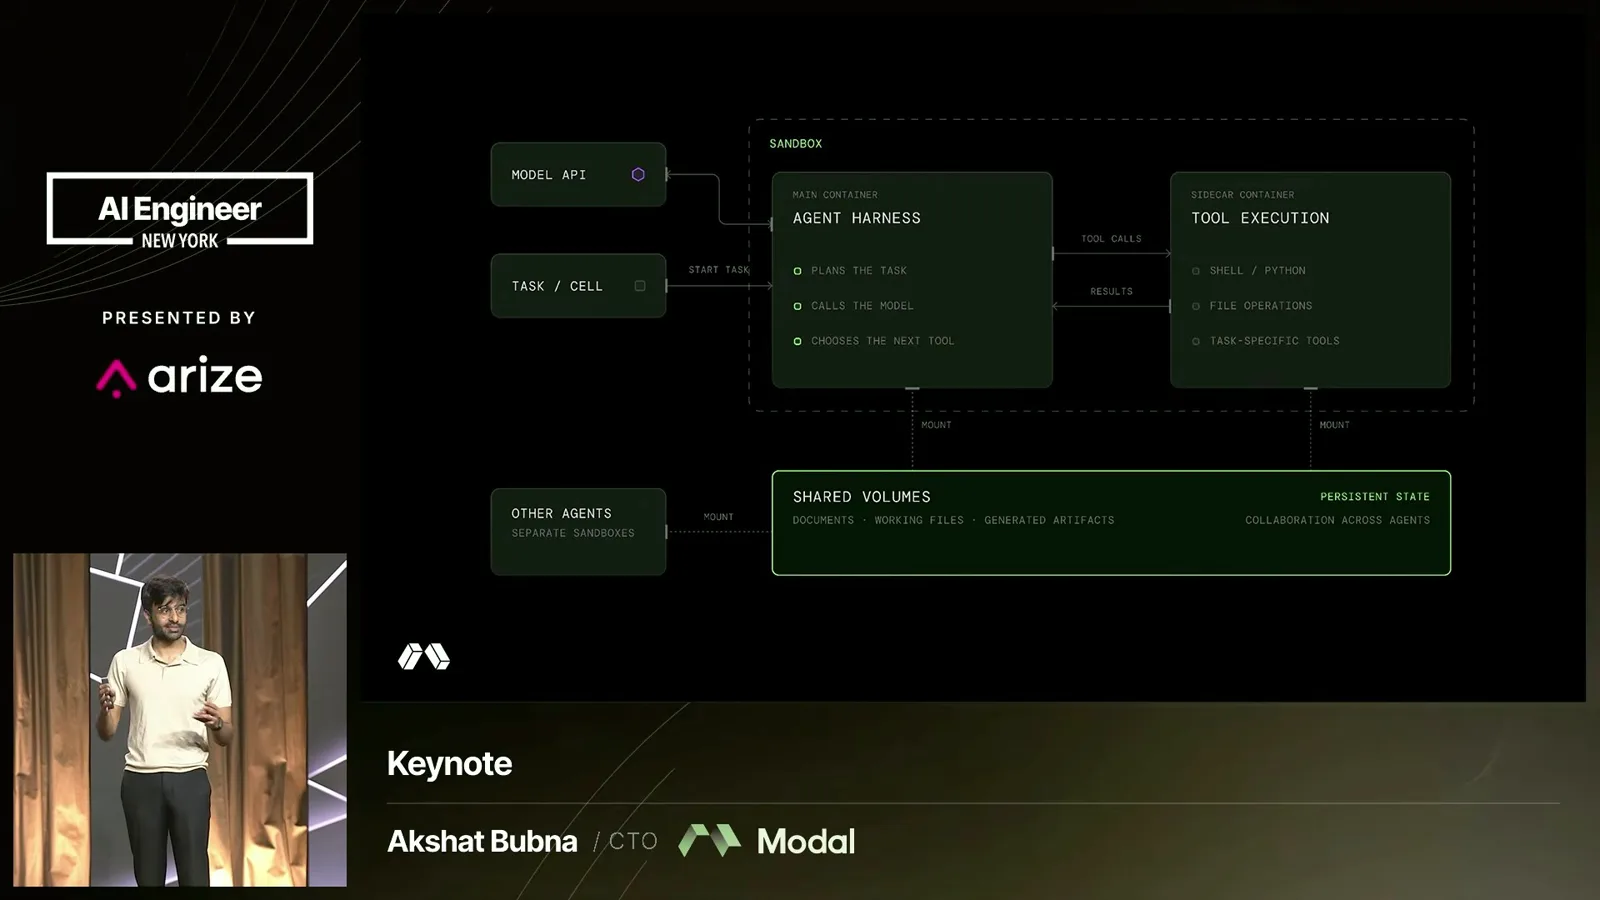
Shared storage lets agents collaborate. For example, the agents in a spreadsheet row might share a volume, while the agent’s main container and a sidecar also share selected files. The system must start many environments quickly and release them when work is complete.
Modal builds infrastructure for AI workloads including inference, training, batch functions and sandboxes. Bubna focuses on the primitives an agent platform needs rather than the prompts that tell a model what to do.
Preserve workspaces and adapt resources
Agents need their working files to survive long waits without keeping compute running. CPU, memory and accelerator demand can vary substantially during a task.
Every agent needs a workspace appropriate to the job. A coding agent needs a repository, dependencies and development services; an accounting agent needs documents, work papers and scripts; a game-development agent needs its engine and assets.
The workspace also needs to survive pauses. An accounting agent may process documents, then wait days for an accountant’s response. When the person responds, the agent should resume from where it stopped without paying for compute throughout the wait.
Different kinds of persistence serve different jobs: a snapshot of the whole filesystem, a snapshot of one directory, or a shared volume. A team might preserve dependencies while updating its base image, for example, rather than treating all state identically.
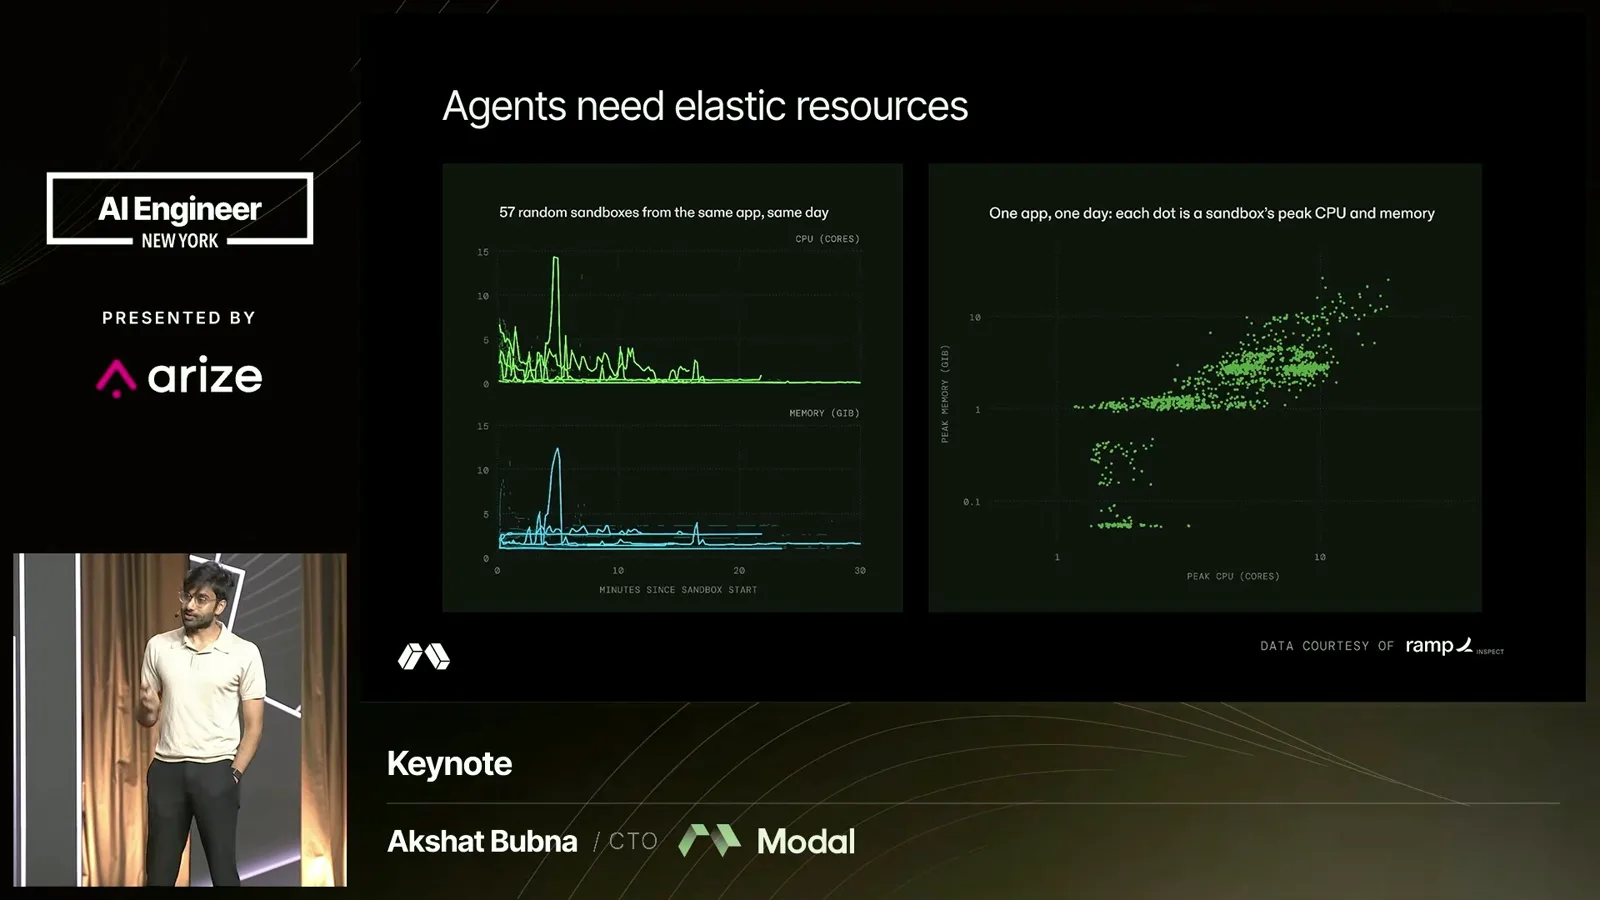
Resource requirements also fluctuate. Bubna shows CPU and memory data from Ramp Inspect, a coding agent, with substantial variation both across sandboxes and over the life of one sandbox. Compiling code or analyzing a large dataset can briefly need much more capacity.
Provisioning every environment for the highest observed peak—he gives an example around 15 CPU cores and 15 GB of memory—would be expensive. Modal’s approach, he says, is to provide resources when needed and charge for their use during that period.
Some tasks need accelerators only for certain steps. Bubna cites Claude Science, where computational work can be offloaded to a Modal sandbox when a researcher needs more CPUs or GPUs. He also mentions game design, video and 3D work as workloads that may require GPUs.
He describes agents running many training experiments, changing hardware and comparing variants as part of iterative research. The infrastructure must provide the requested resources and let the agent inspect the results of those experiments.
Share files while limiting access
Collaboration and memory need performant shared storage. Fine-grained network and credential controls limit what an agent can access.
As agents collaborate with subagents and people, a shared filesystem becomes part of the coordination mechanism. Bubna says it needs performance and consistency that developers can reason about. Agents can also save and update memory as files over time.
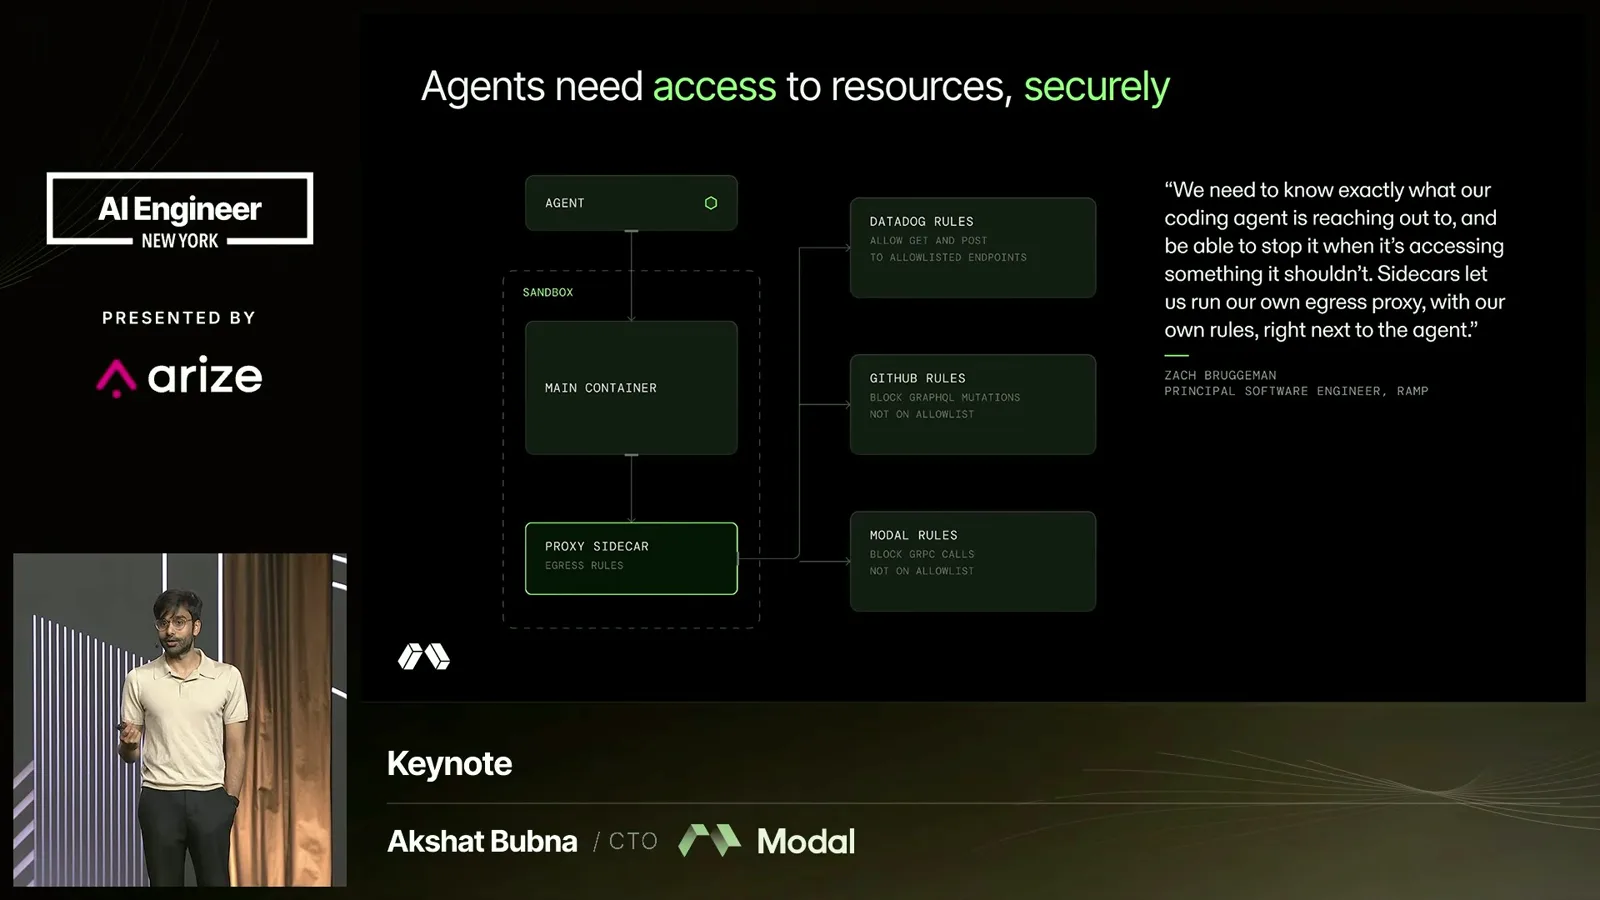
Agents can make mistakes or leak sensitive data, so control over their environment matters. Bubna lists authentication, which incoming IPs can connect, which destinations the agent can reach and how service credentials are provided.
He says a domain-level allowlist is not always enough: an organization may want to permit only specific paths or operations on a service. A sidecar proxy can enforce custom outbound rules, and he cites Ramp as an example of this pattern.
Make failures observable and design for scale
Agents need access to logs, utilization and budgets to respond to failures. Bubna argues that sandbox platforms demand careful work on reliability, security and scale.
Observability matters to the agent as well as to the human operator. If a training run fails, the agent should be able to read its logs, understand the failure and try different parameters. During a run, it may need utilization metrics and a spending budget.
Why not simply have a model generate a sandbox platform? Bubna argues that reliability, security and scale require careful engineering. Rare failures are difficult to reason about; security boundaries must be maintained as threats and systems change.
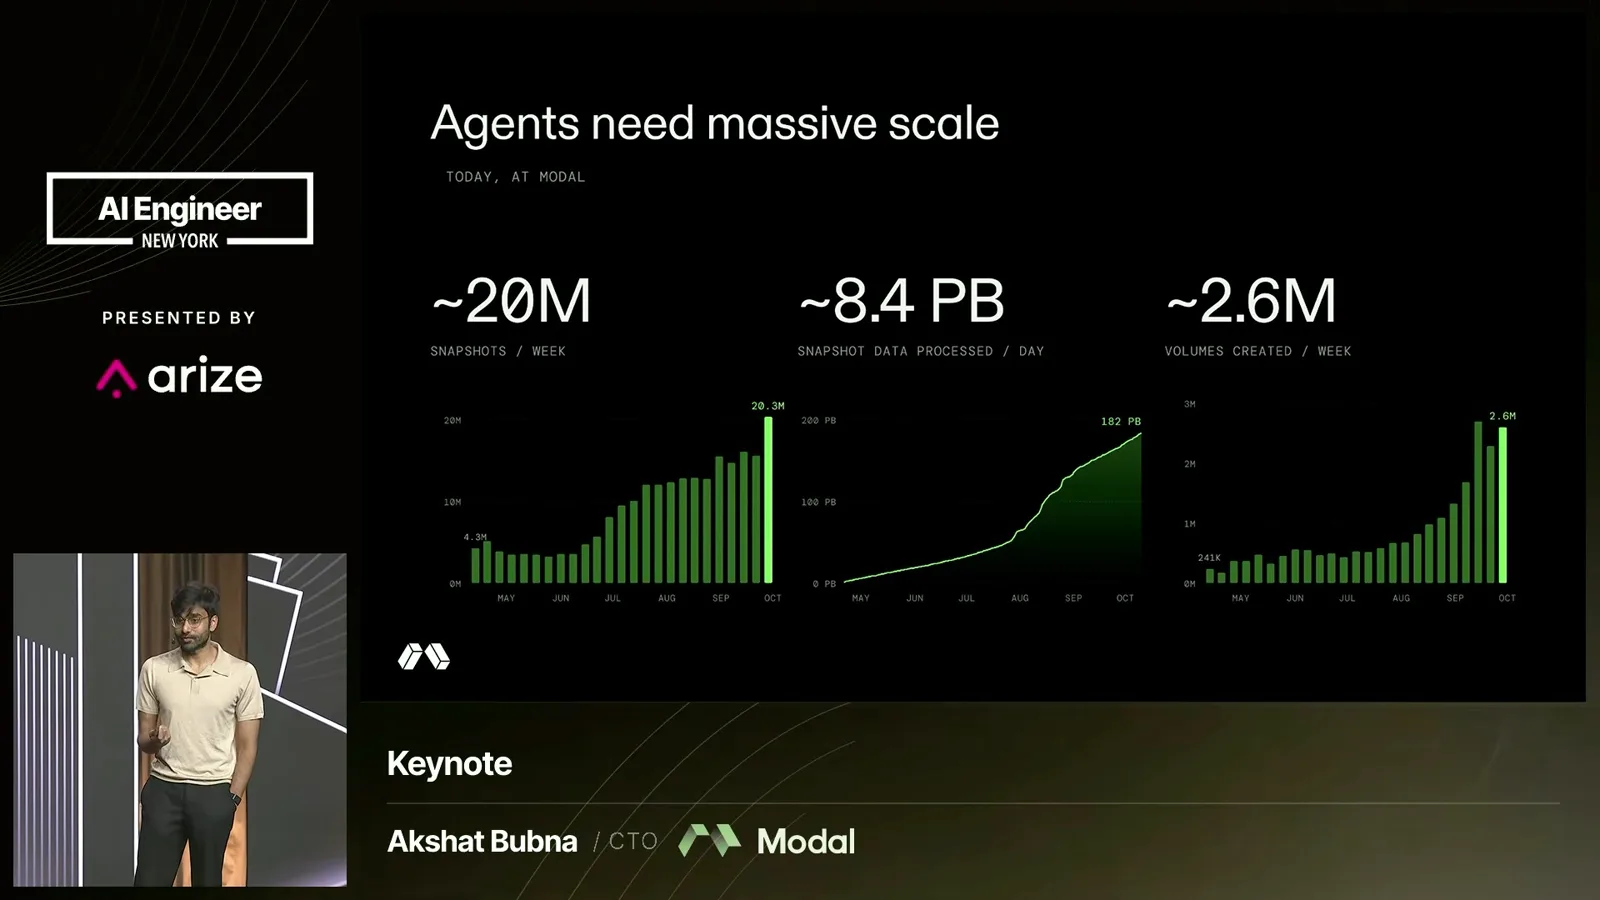
At the time of the talk, Bubna reports roughly 20 million snapshots and 2.6 million volumes created per week on Modal, with about 8 petabytes of snapshot data processed daily. He gives a customer workload needing up to 10,000 sandbox starts per second and nearly a million short-lived sandboxes.
Those environments may last only a few minutes, he says, but need to become interactive in less than a second. He adds that CPU capacity can be constrained as well as GPUs, so Modal aggregates capacity across several providers.
Separate the agent’s decisions from its execution environments
Bubna expects agents to create, snapshot and adjust environments dynamically. He contrasts this with treating every deployment as an identical server.
Looking ahead, Bubna expects a stronger separation between the agent loop that makes decisions and the execution environments that do the work. An agent could create environments as needed, snapshot them for later and adjust their resources dynamically.
He contrasts individually managed servers with interchangeable containers, then suggests that future agents may coordinate a more varied set of environments. His conclusion is that dependable compute, storage and networking primitives give agents more room to work dynamically.
같은 채널의 다른 글
 19:41EN
 AI Engineer· 2026년 11월 9일A high-reliability automation starts by routing the hard cases awayMatthew Jewkes · Standard CyberneticsMatthew Jewkes describes separating critical errors, ambiguous decisions and unusual exceptions in a biopharma indexing workflow.
 22:01ENAI Engineer· 2026년 11월 9일Zach Lloyd: make the software factory measurable and editableZach Lloyd · WarpWarp’s CEO proposes recording agent runs, scoring failures and testing changes to the workflow on real tasks.
 27:35ENAI Engineer· 2026년 11월 9일Uber traded an always-green trunk for faster AI-scale mergesPreetam Dwivedi, Manjari Akella · UberIts merge queue now relaxes some conflicts and validates the combined state after landing, with a verified-good fallback.
 15:25ENAI Engineer· 2026년 11월 9일Hassan and Omar El Mghari: When an AI financial forecast is right for the wrong reasonsHassan El Mghari, Omar El Mghari · Together AIA Costco membership-fee model passed basic checks and landed close to reported results, but an audit uncovered offsetting assumptions.
 14:38ENAI Engineer· 2026년 11월 9일Jemima Abu: Give coding agents accessibility rules from the startJemima Abu · CAISA product engineer shows how semantic HTML, reusable components and explicit agent skills can help teams build more usable interfaces.
 21:12ENAI Engineer· 2026년 11월 9일Tom Moor: Give coding agents the product context that code cannot showTom Moor · LinearLinear’s workflow carries customer requests, past decisions, review history and human feedback from intake through implementation and review.