30초 요약
Matthew Berman reviews GPT-4o mini's July 2024 launch pricing and specifications and runs informal comparisons with GPT-4o. He tests a small game, arithmetic, puzzles and image understanding, while observing differences in latency. The article preserves the sponsor disclosure and explains the limitations and ambiguities of the small sample.
- 1Launch pricingBerman reviews GPT-4o mini's 2024 price, context window and OpenAI's reported MMLU result.
- 2Coding examplesThe generated Snake game runs, although the demo shows a self-collision limitation.
- 3Reasoning testsLaundry and arithmetic examples are small informal tests; the laundry answer assumes sufficient simultaneous drying space.
- 4Sponsored laptop segmentHP and Intel sponsor the video, and Berman describes the supplied laptop.
- 5Vision observationsThe two models answer several image questions, while the observed latency and token counts apply only to these runs.
핵심 정리
- OpenAI announced GPT-4o mini at $0.15 per million input tokens and $0.60 per million output tokens in July 2024.
- The informal coding and reasoning examples are not a controlled benchmark or proof that the mini model is generally better.
- The Snake demo runs but permits moving through the snake's body, which differs from standard rules.
- Some puzzles require assumptions, including simultaneous laundry drying and the marble's physical movement.
- The video includes an HP and Intel sponsored segment and product claims.
챕터별로 다듬은 전문 읽기
GPT-4o mini launch and coding
Berman reviews launch specifications and compares simple coding prompts. The game demo exposes a rule limitation.
OpenAI has released GPT-4o mini, a smaller and less expensive model. This video is sponsored by HP and Intel, which provided an EliteBook 1040 G11 for the demonstration.
OpenAI reports an 82% MMLU score and launch API pricing of 15 cents per million input tokens and 60 cents per million output tokens. It says the model supports text and image inputs, has a 128,000-token context window and an October 2023 knowledge cutoff. These are launch-era claims and prices.
I compare GPT-4o mini with GPT-4o in the Playground, with a helpful-assistant system prompt and a large output limit. This is an informal selection of prompts, not a controlled benchmark.
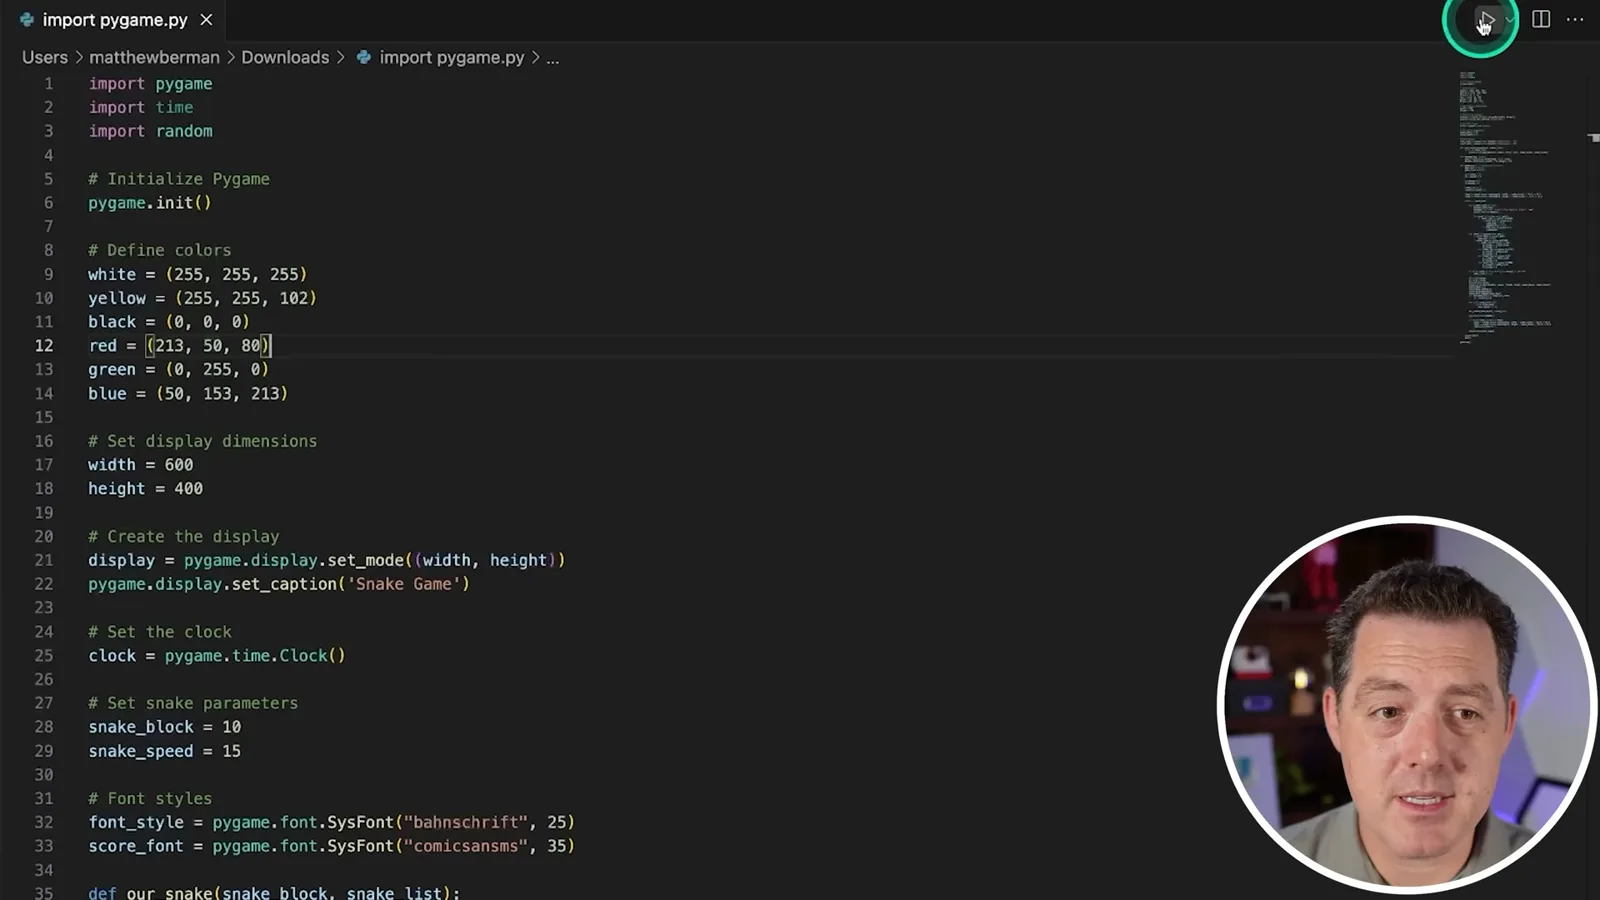
Both models write a Python script to print numbers from one to 100. For a Snake game, the mini model produces code quickly and the game opens on the first try. I notice that the snake can pass through its own body, so the result is playable but not a complete implementation of the usual rules.
Safety and reasoning prompts
He tests jailbreaks and several puzzles. Their results are anecdotal and some questions require assumptions.
I also test a safety bypass prompt and observe responses from both models. A single attempt cannot establish a model's overall safety or justify treating a refusal as a defect. I expect defenses and behavior to change.
For the laundry question, the model answers that 20 shirts can dry in four hours if all have enough sunlight and airflow. The answer depends on simultaneous drying and similar conditions. Both models also answer a basic arithmetic problem and a hotel-cost expression correctly in the displayed tests.
The mini model correctly counts the words in one response. For a puzzle about three killers and a new person entering and killing one, both answer three living killers; the result depends on whether the dead person is included in the word 'killers' and whether the entrant was already one.
Sponsored laptop and more tests
Berman presents the HP and Intel laptop segment. He then compares a marble puzzle and numerical prompts.
In the sponsored segment I describe the HP laptop's mobility, Intel processor, camera and audio features, screen and locking behavior. I also cite battery life up to 20 hours; that is a product claim and actual battery life depends on use.
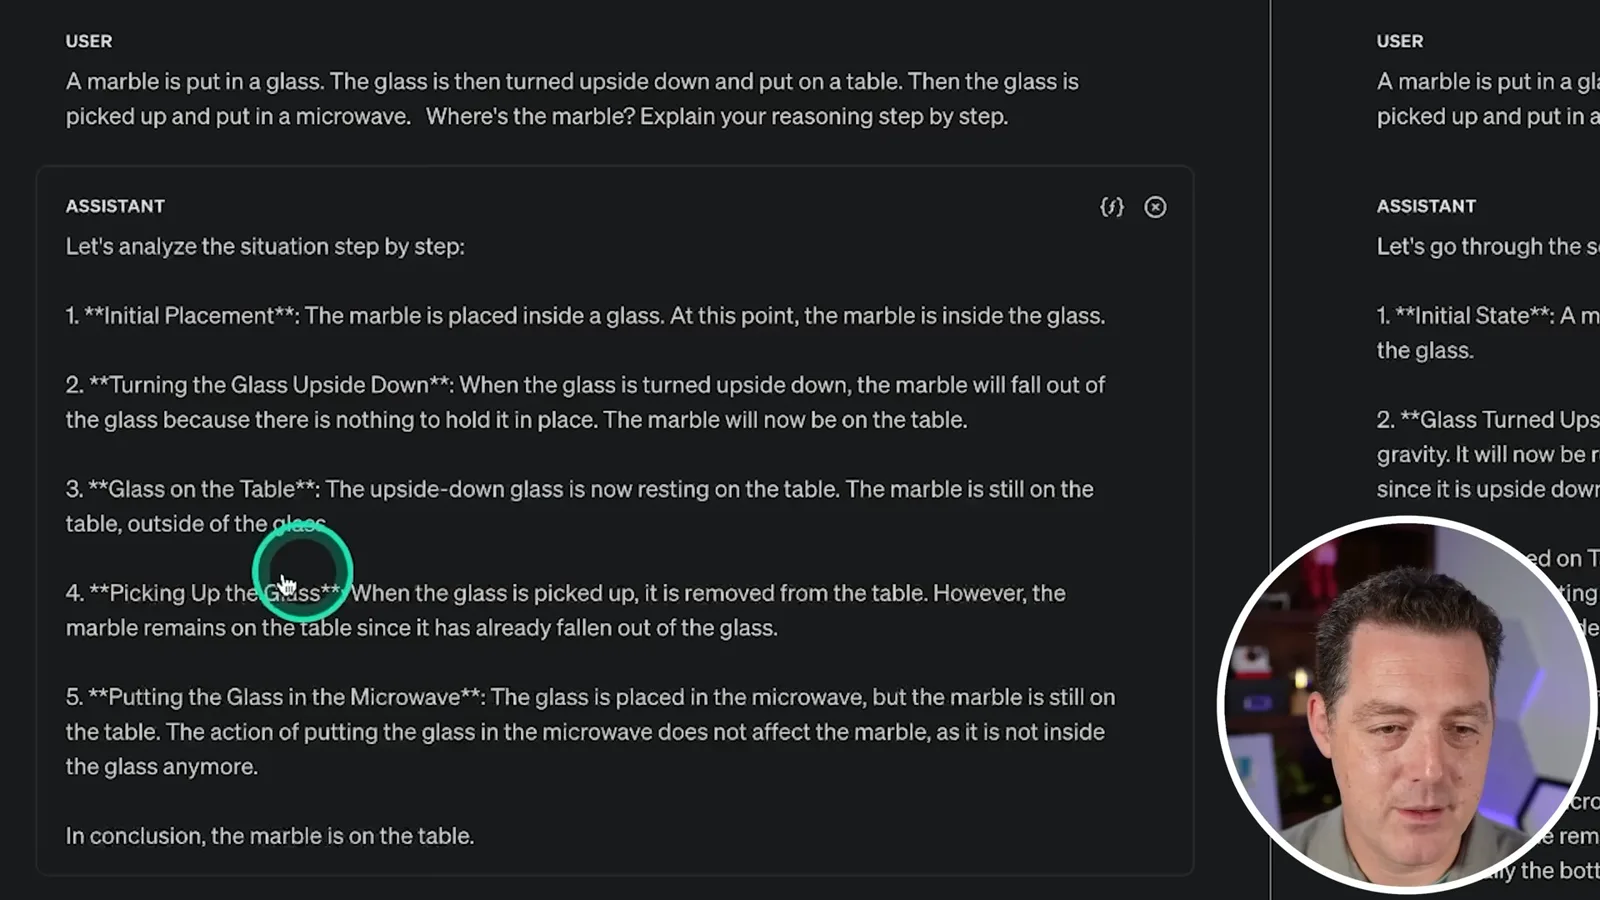
I ask where a marble ends up after a glass is turned upside down, placed on a table, lifted and moved. Mini answers that it remains on the table, while GPT-4o gives a different answer. The original wording leaves details of the inversion and placement unspecified, so the result depends on physical assumptions.
Both models miss one of ten requested sentences ending in 'apple' in my test. Both correctly say 9.9 is greater than 9.11. These individual answers are useful examples, not a comprehensive comparison.
Vision comparisons
The models interpret images and a spreadsheet screenshot. Berman reports observations about latency and token counts.
For vision, both models explain a meme contrasting startups and large companies. I observe a much higher reported token count and slower start for mini in this run, although I do not know whether the display reflects a bug or a general property.
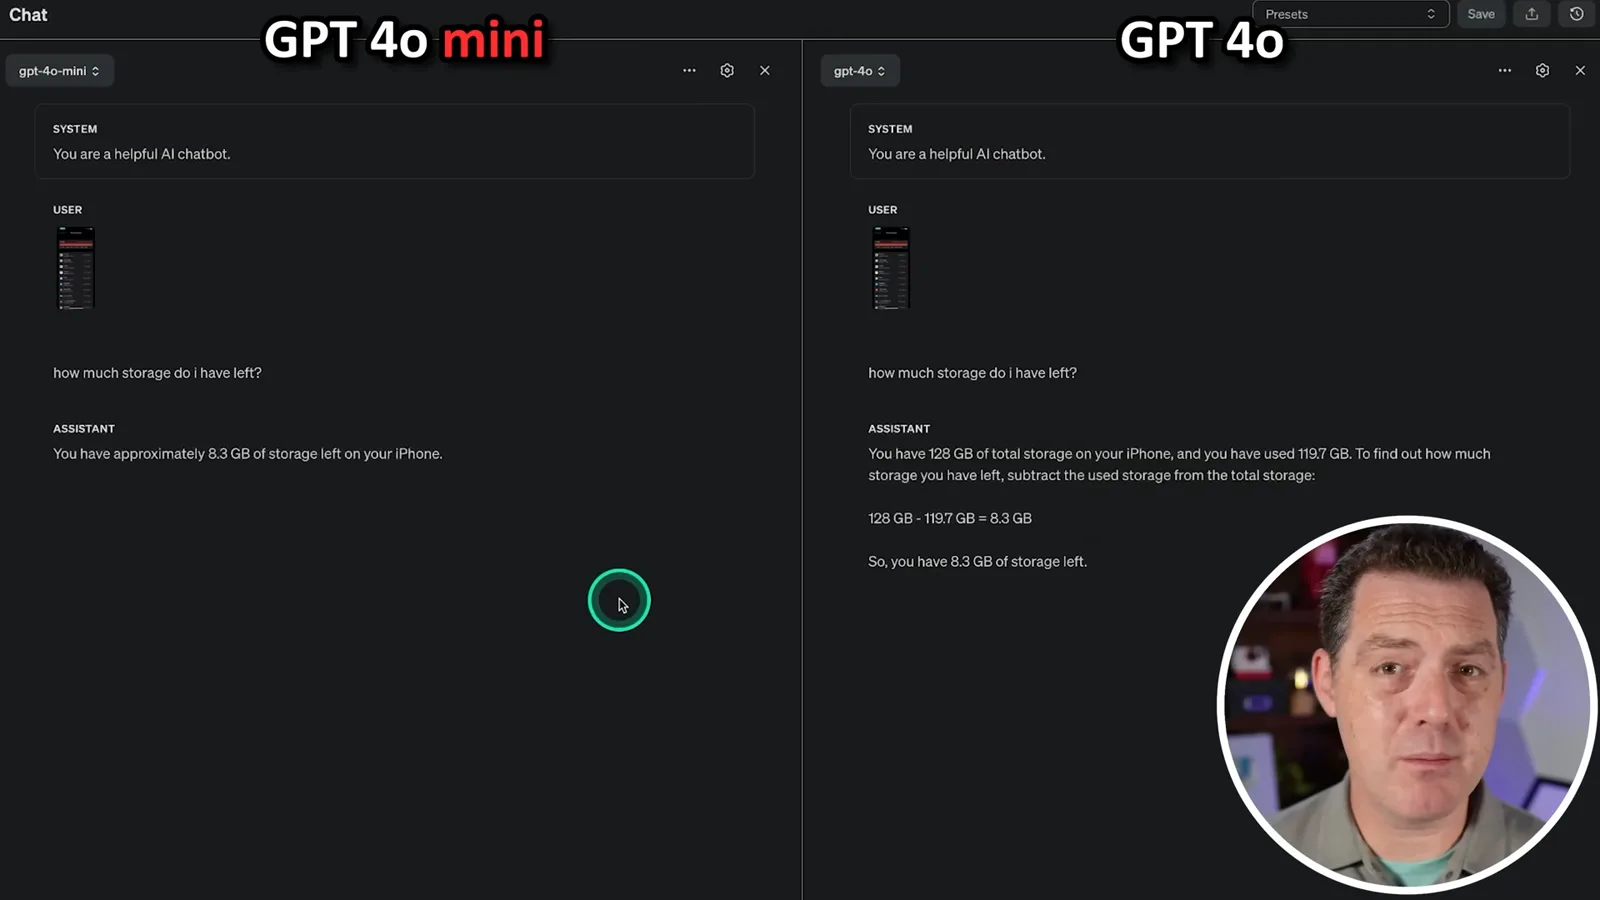
I ask both models to turn a spreadsheet screenshot into CSV, then query an iPhone storage screenshot. In the shown run they give the same remaining storage and identify Photos as the largest listed app. The apparent differences in vision latency and token counts are observations from these specific requests.
I'm impressed by the small model's speed, price and performance on this selection of prompts. I suggest choosing the larger model when vision latency matters, but the sample is too small to establish a universal ranking. I thank HP and Intel for sponsoring the video and providing the laptop.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.