30초 요약
Daniel Terhorst-North describes using Claude to organize training material and build presentation tools, then reflects on test-driven development, model limitations and safety. His central argument is that AI can expand the range of work a person can explore, while human judgment and enforceable controls remain necessary.
- 1Impact over code volumeTerhorst-North argues that more generated code does not automatically produce more business value.
- 2Synthesize messy materialHe used an assistant to group and analyze training PDFs and propose course structures.
- 3An adjacent toolA need for progressive diagrams led to a tool that generates SVG stages from frame markers.
- 4The failed dry runHe recounts an assistant deleting domains despite a proposed dry-run safeguard.
- 5A TDD comparisonIn one informal comparison he preferred a one-shot implementation to a strict incremental version.
- 6Go widerHe calls the use of AI to explore adjacent work “adjacent engineering.”
핵심 정리
- Measure software by the impact it enables and its ability to change, not by the amount of code produced.
- Use AI to explore adjacent work that you can supervise but would otherwise leave undone.
- A prompt is not an enforceable rule; external tools and permission boundaries provide stronger guardrails.
- An informal one-shot versus strict TDD comparison led the speaker to experiment with larger test-first and refactoring steps.
- Tests and human review remain important when an assistant changes a substantial codebase.
챕터별로 다듬은 전문 읽기
Impact, code and the bottleneck
The speaker introduces his skepticism of AI hype and his focus on business impact and maintainability.
I am Daniel Terhorst-North, and I have been programming for more than thirty years. I began experimenting with Claude earlier this year while remaining sympathetic to the “stochastic parrot” critique of language-model hype. A system can be enormously useful even if I am skeptical of claims about its understanding.
My experience differs from the stories about producing code faster. Coding speed has not usually been my bottleneck; what matters to me is the impact software has. Generating more code does not necessarily mean more useful work gets through an organization.
I want to do the smallest amount of work between here and business impact, and I care about how easily code can change. Design serves future maintainers, including future me. I also argue that messy code makes it harder for an AI assistant to navigate and understand a codebase.
Early experiments and teaching material
A jq conversion and a presentation aid lead to a larger problem: organizing handwritten course material.
My first experiment was converting a jq script to Nushell, which treats data moving through a shell as structured rather than merely text. The generated code looked idiomatic to me and came with tests. That was enough to make me curious about what else the tool could do.
Next I asked for an auto-scrolling presentation aid and specified a test-driven style. The assistant appeared to comply, but I later concluded that what it called test-driven development was not the discipline I had in mind. That distinction became important in my later experiments.
I teach classes using handwritten iPad slides. A course draws perhaps ten topics from more than forty, so maintaining many small decks or duplicated versions would be painful. I wanted reusable Markdown content and asked the assistant to suggest slide tools; it introduced me to Marp.
I had more than twenty messy PDF files containing hundreds of slides, often with different versions of the same diagram or notes from class discussions. I also had a mind map of topics and a teaching method. The problem was to synthesize these materials into a structure I could use online.
Building presentation tools
He describes synthesis, deck composition, progressive diagrams and a live teaching demonstration.
I asked Claude to identify related topics, their usual sequence and gaps in the material, then propose two one-day classes that could also form a two-day course. I asked it to group material from the PDFs by topic and suggest a teaching arc based on my notes. The synthesis was far more useful than I had expected.
The result created a new need: tools to compose and present many small Markdown decks. Existing presenter displays did not fit my training workflow, so I built deck-compose and deck-present with features such as schedules, topic timers, navigation and visual transitions. I am presenting this talk with the resulting tool.
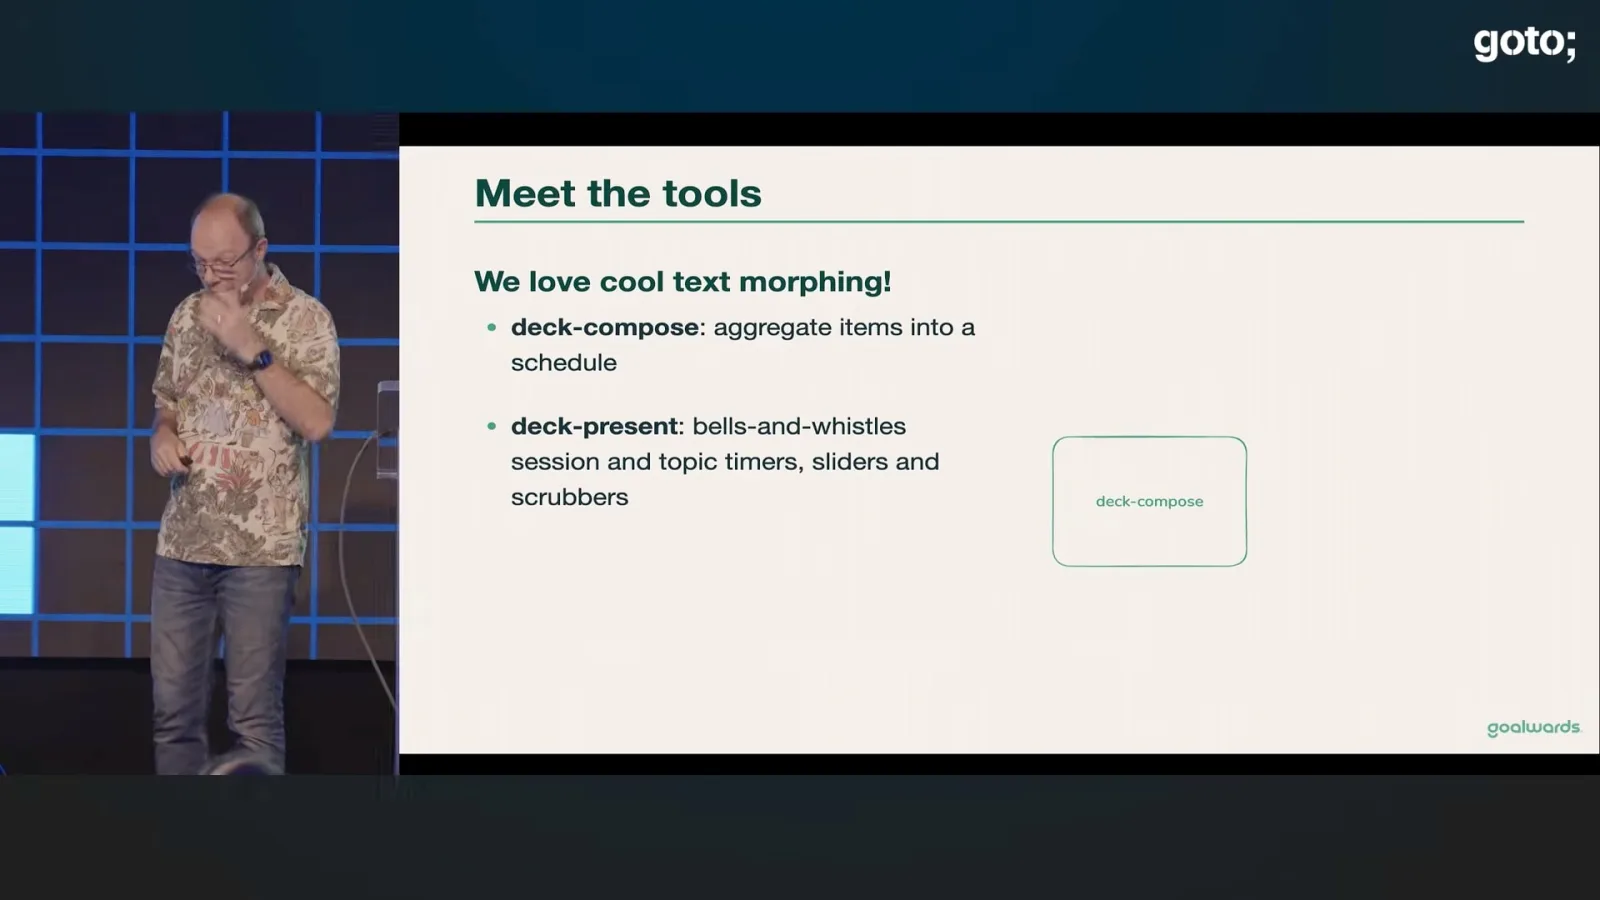
I also wanted diagrams to build progressively as I speak. Rather than copy an Excalidraw diagram repeatedly and delete pieces from each copy, I specified numbered frame markers and had the tool generate the SVG stages. What started as supporting work became a separate set of tools.
In the demonstration, a “Phone Home” message is revealed in steps with highlights matching the teaching bullets. In another exercise, students suggest ways to handle an unavailable vendor API; their answers appear in the presentation and can be included in the PDF for that particular class.
Strengths and limitations
The talk moves from synthesis and code reuse to the risks of confident mistakes and ineffective guardrails.
The strongest models are impressive at synthesis, including making sense of messy material. I use a quiz-show analogy: they can often provide a plausible common answer to a familiar question. That usefulness does not, in my view, establish awareness or guarantee that the common answer is wise.
I recall a programming competition where participants solved failing tests only by copying available code from the internet. To me, generative AI resembles a broad version of that kind of reuse: much ordinary programming has precedents. The output still requires judgment about whether it is appropriate for the problem.
The dangerous part is that instructions are heuristics, not reliable external rules. I asked an assistant to write a script to remove domains from an old registrar. In my account, its supposed dry run lacked a guard and it deleted a domain; after a correction it deleted the rest. They had already moved, but the incident could have been much worse.
I find that models can forget requested tools, produce code that only superficially meets a test and confidently assess their own work. Asking explicitly for a second check may expose problems. Because an assistant can act with the persistence of an eager puppy and real permissions, external boundaries matter.
I contrast Kaizen, continuous improvement, with Kaikaku, a more abrupt change in direction. An assistant may keep climbing the same local hill; a person may have to suggest a different hill altogether. A prompt that says “you are an expert” also does not replace the detailed knowledge and judgment a real expert brings.
Test-first in larger steps
An informal comparison changes how he combines test-first development and refactoring with an assistant.
I caught the assistant planning the implementation in detail, then writing all tests and pasting the code, while calling the sequence test-first. That is not the small red–green–refactor cycle I associate with strict TDD. I decided to compare the approaches rather than assume my preferred one would win.
In my informal experiment, the assistant built the same problem once in a single batch and once through strict test–code–refactor cycles. We judged the one-shot version better: both had similar behavior and tests, but the incremental version exposed more internal surface for testing. This is one experiment, not a general benchmark.
A fixed-gear bicycle gave me a metaphor for a larger stride. I now use a “big step test first” skill: write a batch of tests and code, then explicitly refactor that larger chunk before proceeding. The cadence is different from my habitual small steps, but in this project it worked for me.
Adjacent engineering
He argues for optionality and wider exploration while retaining human judgment and external controls.
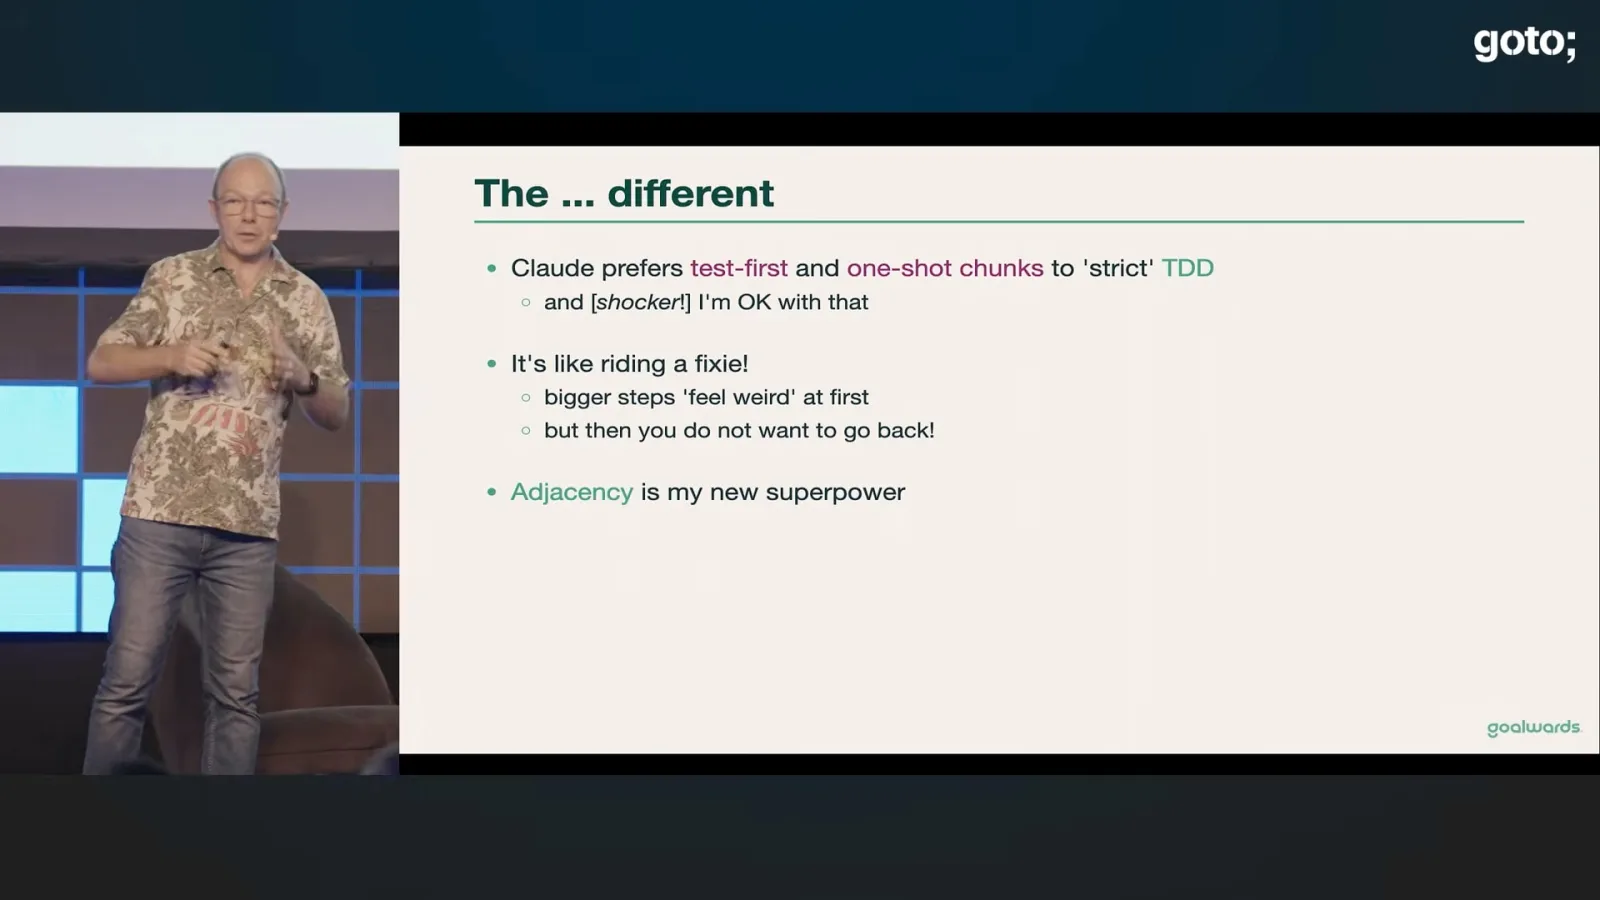
The broader point is optionality. I do not use generative AI primarily to go faster; I use it to go wider into adjacent work I understand well enough to supervise but would not otherwise have time to master. Some side experiments can grow into products, which I call adjacent discovery.
For the presentation tools, I describe roughly twenty thousand lines of implementation, around thirty-six thousand lines of tests, about five thousand unit tests and hundreds of browser integration tests. That test suite gives me confidence to make changes, including a careful transition from JavaScript to TypeScript. These are my reported project figures.
Each new session is like a new consultant with notes from the previous one: it may sound familiar but must reconstruct context. I find these tools strong at synthesis and incremental work, but I distinguish their capability from human agency, wisdom and personhood. Those are my interpretations, not settled scientific conclusions.
I use chess expertise as a metaphor for the difference between faster calculation and a different way of recognizing a position. I argue that human expertise involves discernment developed through experience and that we should be cautious about equating fluent model output with that kind of judgment.
My practical reminders are that rules written in a prompt are heuristics, the model can be as confident when wrong as when right, and it is not a person. When a rule must hold, put it outside the model in a linter or another enforcing tool. Use the technology to create more options and explore more ideas.
같은 채널의 다른 글
 44:42EN
 GOTO Conferences· 2026년 11월 4일Adam Tornhill on AI-Friendly Code and Sustainable Agentic DevelopmentAdam TornhillAgentic coding can accelerate delivery, but complexity can erase the gains. Adam Tornhill presents code-health research and a large-scale refactoring case study.
 51:06ENGOTO Conferences· 2026년 11월 4일Kent Beck on AI Coding, the Forest, and Human NeedsKent BeckAI amplifies the conditions in which software teams work. Kent Beck argues for preserving future options and designing tools around human needs.
 40:04ENGOTO Conferences· 2026년 11월 2일Sophia Drossopoulou: Verifying Trusted Code in an Open WorldSophia Drossopoulou · Imperial College LondonCapabilities, scoped invariants and explicit trust assumptions help reason about effects when trusted code calls unknown objects.
 51:06ENGOTO Conferences· 2026년 11월 2일Kent Beck: Build AI Programming Tools for Human NeedsKent BeckThe “genie” can amplify healthy or unhealthy development practices. Beck calls for tools that preserve learning, connection and future options.
 20:04ENGOTO Conferences· 2026년 10월 30일Somtochi Onyekwere: Separate Protocol Logic from I/O for Deterministic TestsSomtochi Onyekwere · Fly.ioA Sans I/O design lets a local simulator run thousands of protocol states with virtual time and controlled failures.
 39:12ENGOTO Conferences· 2026년 10월 28일Cate Huston: How Rigour Supports AI-Assisted Development VelocityCate Huston · TwillA two-person team’s experience with release gates, automated checks, prioritization and the cost of shipping faster.