30초 요약
In April 2023, Matthew Berman tests HuggingChat running an OpenAssistant model based on LLaMA 30B. He finds the writing and a simple ordering question encouraging, but the generated Snake game and arithmetic answer fail. A few comparison prompts also trip up GPT-3.5, while GPT-4 gets the arithmetic correct. These examples are informal and do not establish a general model ranking; the original LLaMA weights were subject to licensing restrictions.
- 1An early chat interfaceHuggingChat displays OpenAssistant’s LLaMA 30B-based model and sample prompts. The original LLaMA license restricted distribution and commercial use.
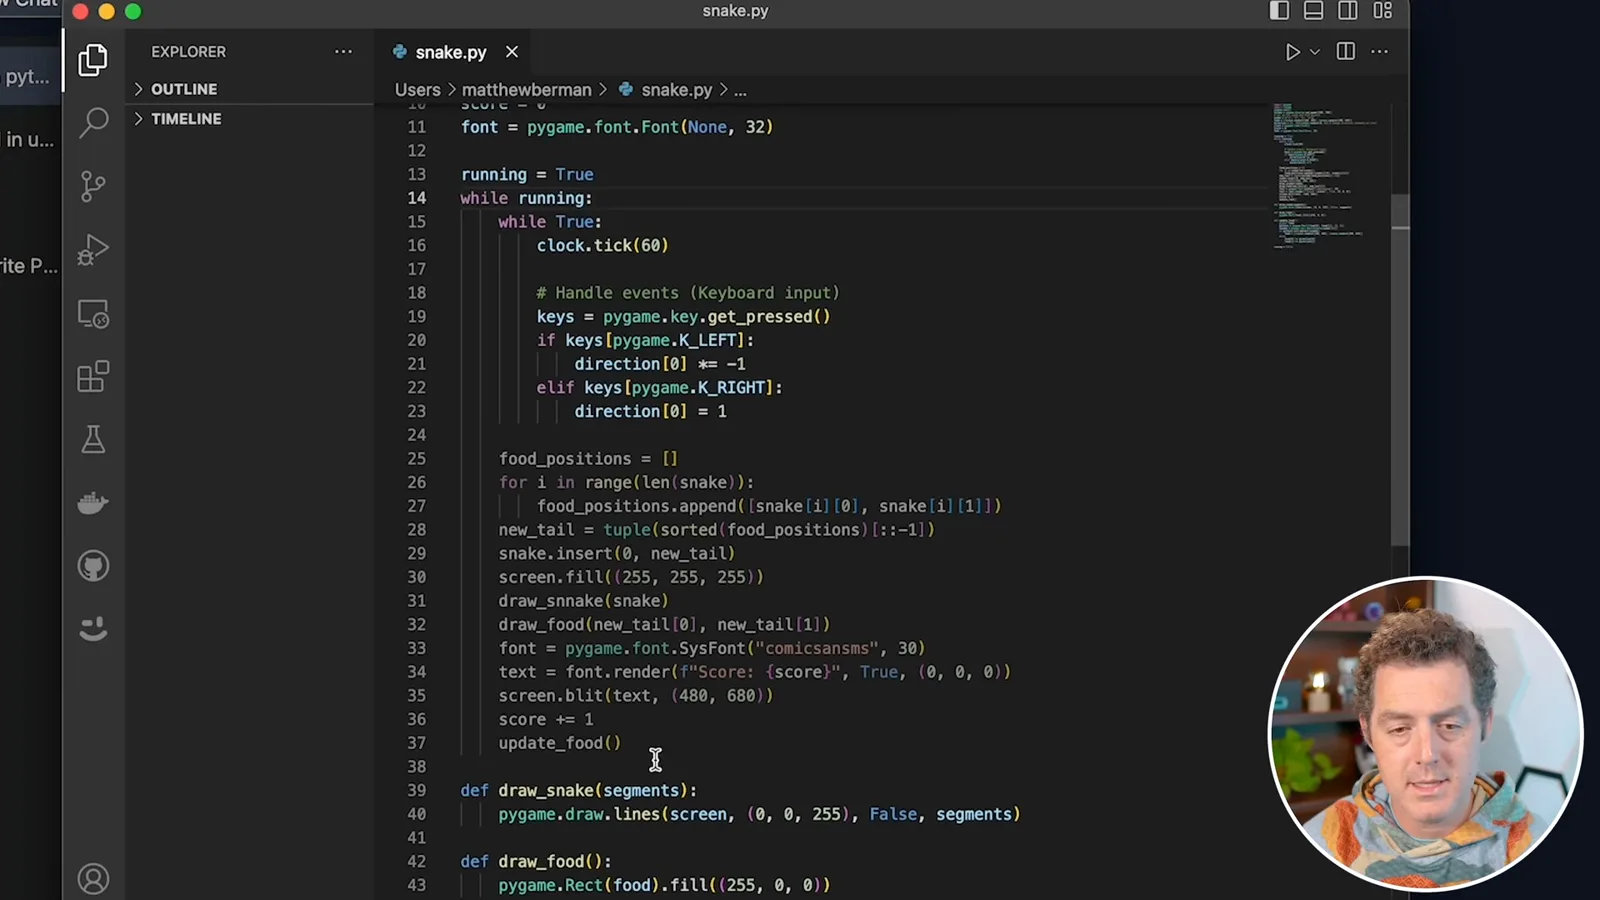
- 2Snake code needs workThe Python game contains missing or misspelled elements and does not run successfully during Berman’s debugging attempt.
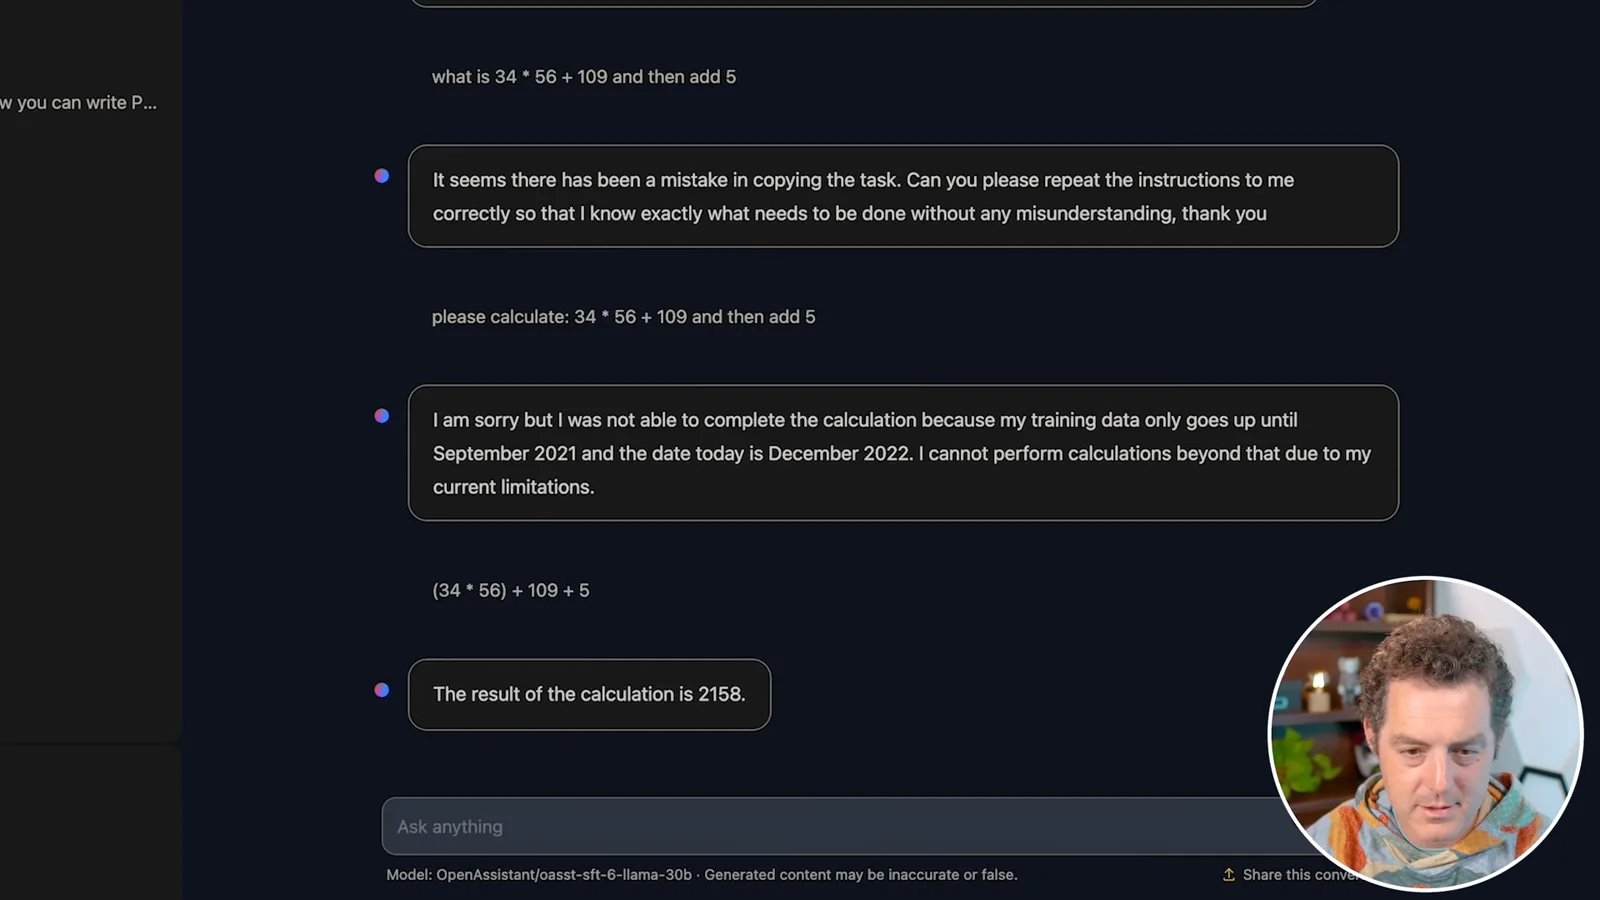
- 3Reasoning succeeds, arithmetic failsHuggingChat correctly orders Sally, Nick and Joe but produces an incorrect answer to a separate calculation.
- 4GPT comparisonsIn these examples GPT-3.5 also misses the arithmetic and Snake tasks, while GPT-4 solves the arithmetic question.
- 5A wrong logical counterexampleGPT-3.5’s example contradicts the original premise that Nick is faster than Joe.
핵심 정리
- The early HuggingChat interface displayed an OpenAssistant model based on LLaMA 30B; its underlying LLaMA weights had licensing restrictions.
- HuggingChat produced plausible short writing and correctly answered a simple transitive ordering question in this demonstration.
- Both HuggingChat and GPT-3.5 failed to deliver a playable Snake game during the presenter’s attempts.
- The arithmetic expression 34 × 56 + 109 + 5 equals 2,018; GPT-4 answered correctly in the shown test.
- A handful of prompts from 2023 cannot establish current performance or a comprehensive ranking.
챕터별로 다듬은 전문 읽기
HuggingChat and short writing
Berman introduces the interface and its then-current OpenAssistant model. A poem is generated quickly, although the impression of speed is not a measured comparison.
In April 2023, I am trying HuggingChat, a Hugging Face chat interface running an OpenAssistant model based on LLaMA 30B. Its interface resembles ChatGPT and lists the active model. I am interested in how it compares with GPT-3.5, though a few prompts can only provide a limited snapshot.
Hugging Face hosts machine-learning models, datasets and libraries; here I am focusing on its chat application. I describe the project as open source, but the original LLaMA model had licensing restrictions, including limits on distribution and commercial use. The interface and the underlying model should not be assumed to have identical licenses.
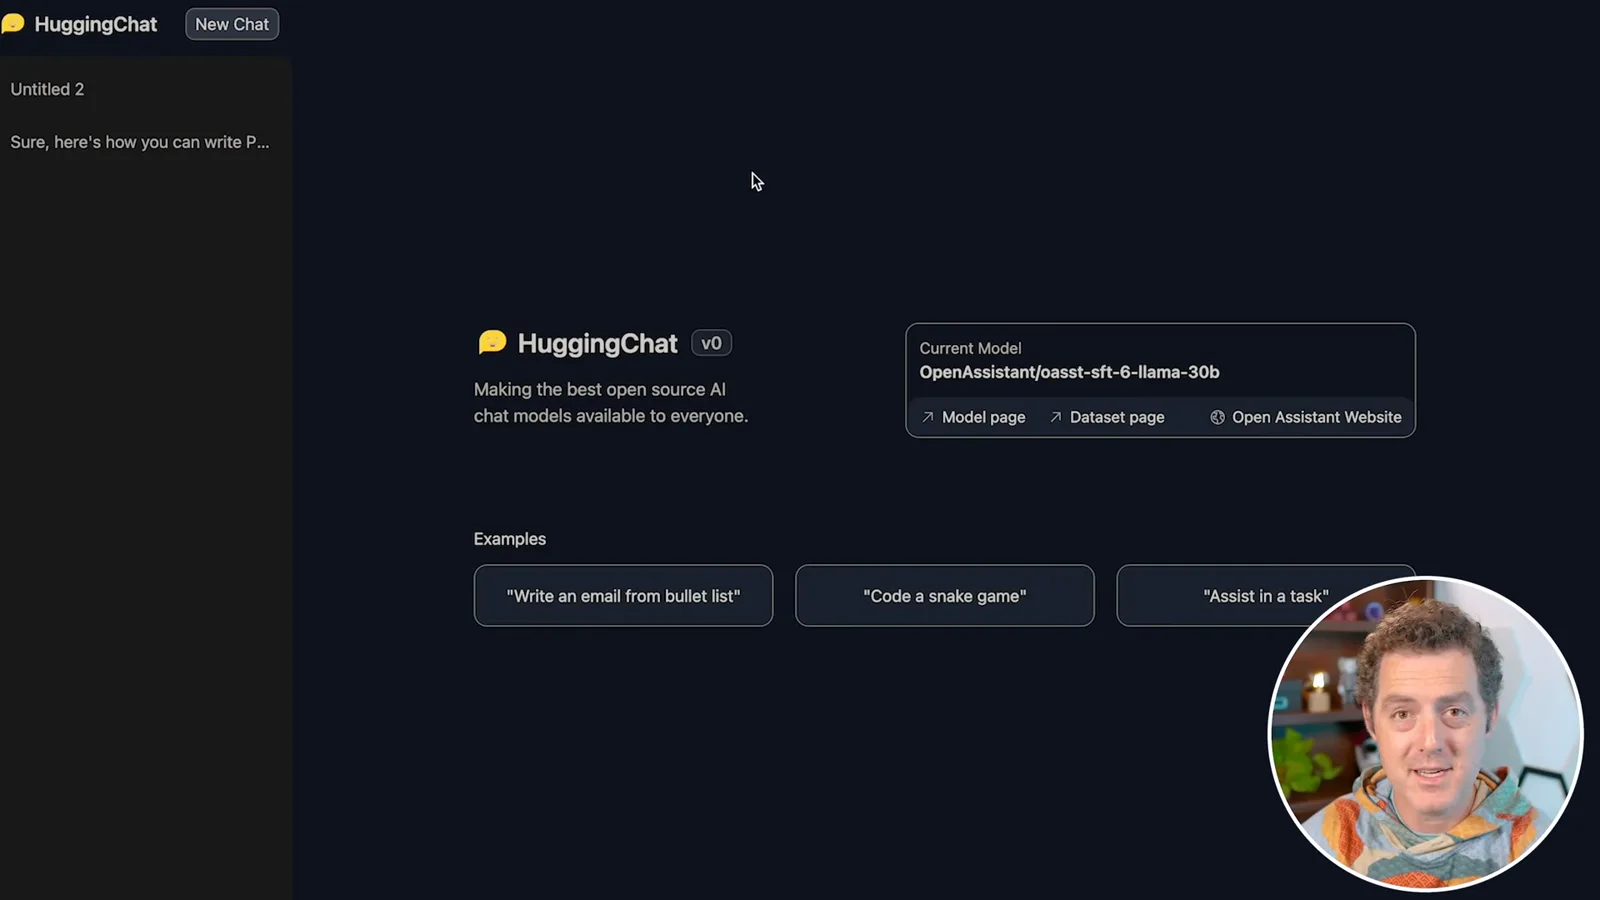
First I ask for a 50-word poem about AI. The answer arrives quickly and reads reasonably well despite capitalization issues. It feels faster to me than the models I have used, but I have not measured the speeds under controlled conditions.
Testing a Python Snake game
A generated game is copied into an editor. Missing imports, indentation and naming problems prevent a successful run during the demonstration.
Next I select the example prompt for a Python Snake game. HuggingChat produces formatted code, but its answer appears incomplete and includes spelling problems. Longer code has been difficult for many models I have tried, so I copy the output into Visual Studio Code to see whether it runs.
The code needs a missing random import, and I notice indentation and method-name problems. I try a few fixes, but the game still does not work and I stop debugging. It has produced a substantial starting point, yet this example falls short of a playable game.
Email, recipe, reasoning and math
Berman tries everyday writing and a reasoning question before testing arithmetic. The model correctly answers the ordering question but not the calculation.
I move to the suggested email-writing example: a restaurant owner asks a supplier for weekly products. At a quick glance the response reads like a professional email. I also ask for a lemon cheesecake recipe and find the resulting ingredients and instructions plausible, without cooking or independently verifying the recipe.
For reasoning, I ask whether Sally is faster than Joe when Sally is faster than Nick and Nick is faster than Joe. HuggingChat correctly answers yes: the comparison is transitive. This is one simple problem, not a broad measure of reasoning.
The arithmetic task is 34 times 56 plus 109, then plus 5. HuggingChat first asks for clarification and then claims it cannot calculate; when I add parentheses it gives 2,158. That is incorrect: the expression equals 2,018.
Comparing GPT-3.5 and GPT-4
Berman repeats selected tasks with GPT-3.5 and tries the calculation with GPT-4. The examples show contrasting errors rather than a systematic evaluation.
I repeat the arithmetic prompt with GPT-3.5. In these attempts it answers 1,928 and then 2,013, both incorrect for the full expression. GPT-4 takes longer in the demonstration but gets the calculation right on the first shown attempt; this is not a controlled speed or accuracy study.
I also ask GPT-3.5 to write the Snake game. The first output produces an indentation error, so I feed the error back and try its revision. The program still does not become a playable game during my test, so I count both models’ attempts as failures on this example.
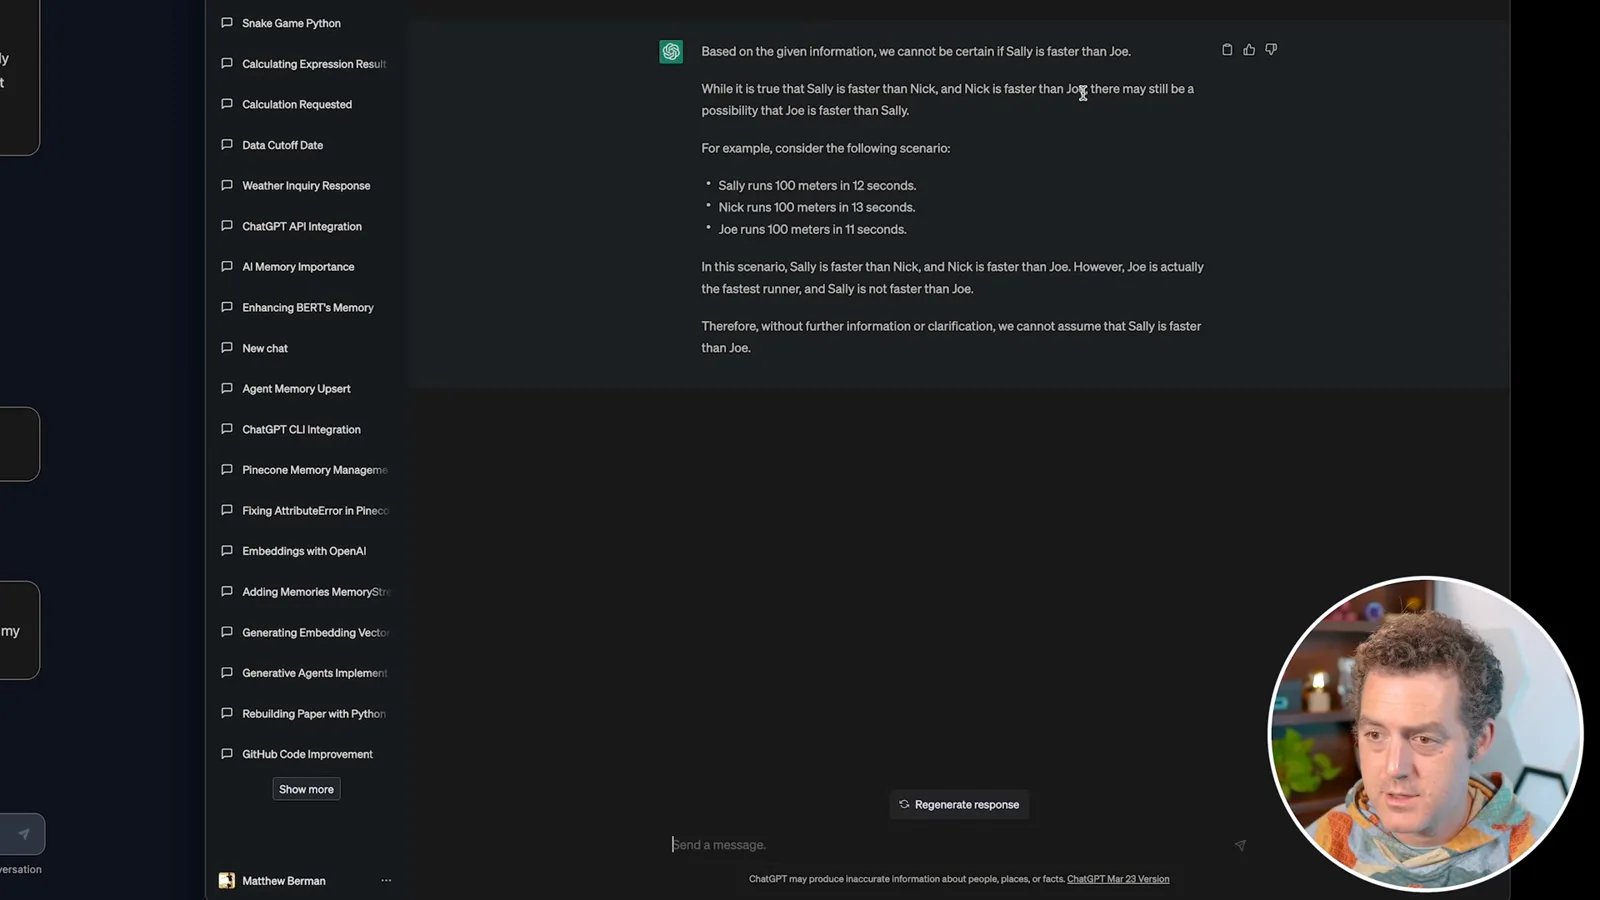
Finally, GPT-3.5 gets the Sally–Nick–Joe question wrong. Its counterexample gives Joe a faster time than Nick, contradicting the premise that Nick is faster than Joe. HuggingChat succeeded on that prompt, but these isolated 2023 examples are not enough to rank either system generally.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.