30초 요약
In August 2023, Matthew Berman tests a quantized Phind fine-tune of Meta’s Code Llama 34B against GPT-4 using separate interfaces. He checks a Snake game, Python exercises and refactoring, finding both successes and failures. His demonstrations are a small collection of single runs with different environments and settings. Phind’s cited HumanEval scores and Berman’s impressions should not be treated as a universal or current ranking.
- 1Phind’s benchmark claimPhind reported HumanEval pass@1 scores for its fine-tuned models against a cited GPT-4 figure, a benchmark-specific comparison.
- 2Different test environmentsThe quantized Phind model runs through a hosted interface with specified generation settings, while GPT-4 runs in ChatGPT.
- 3Snake defectsThe Phind game opens but the snake grows continuously and fails the shown self-collision check.
- 4List exerciseThe Phind variant passes the all-equal site check while GPT-4’s answer fails in this run.
- 5Harder challengeBoth model outputs fail the alternating odd-even substring check.
- 6Refactoring resultThe last Phind refactoring request produces no usable response; Berman cannot identify the cause.
핵심 정리
- Meta’s original Code Llama was built on Llama 2 and released under its community license in several sizes and variants.
- The tested 34B model is a Phind fine-tune and GPTQ quantization, rather than the unmodified Meta release.
- The Phind Snake game opened but grew continuously and missed self-collision in the demonstrated run.
- The Phind model passed the displayed all-equal test that GPT-4’s output failed; both failed the alternating-substring exercise.
- Different interfaces, generation settings and a few single samples limit the comparison.
챕터별로 다듬은 전문 읽기
Code Llama and Phind’s claim
Berman introduces Meta’s code-focused Llama 2 models and the benchmark claim for Phind’s fine-tuned variant. He explains the separate test environments.
In August 2023, Matthew Berman compares a Phind-fine-tuned Code Llama model with GPT-4 on a handful of Python tasks. He is investigating a claim about coding performance, but the two interfaces, model settings and small number of one-off prompts do not establish a universal ranking.
Meta’s Code Llama builds on Llama 2 with additional code-focused training. Its initial release included 7B, 13B and 34B sizes and Python and instruction-tuned variants, under Meta’s Llama 2 community license. Availability of weights does not mean all uses are free of license conditions.
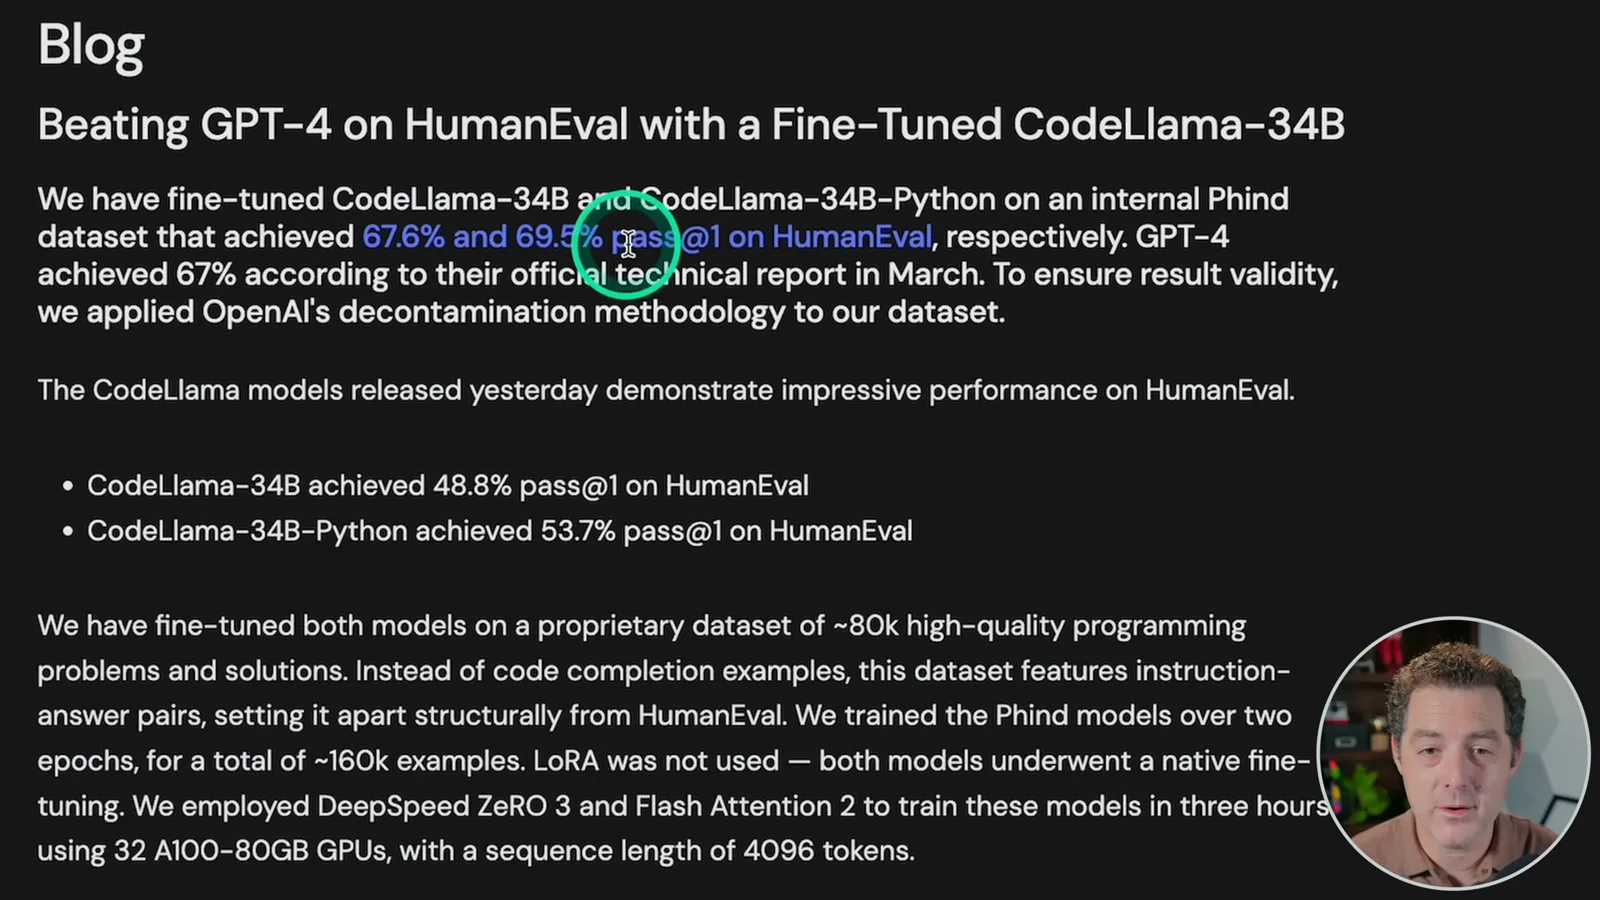
Berman shows Phind’s claim that its fine-tuned 34B models achieved 67.6% and 69.5% pass@1 on HumanEval, compared with a 67% GPT-4 figure it cites. Those are reported results for that benchmark and those versions; the Phind variant is not simply the unmodified Meta model, and the comparison is not a general proof that it is better at all coding tasks.
For his own test, Berman loads a GPTQ-quantized Phind Code Llama 34B variant in a hosted RunPod text-generation interface, while GPT-4 runs in ChatGPT. He uses a 2,048-token generation limit and temperature 0.01 for Code Llama. Different serving environments and settings limit how directly the runs can be compared.
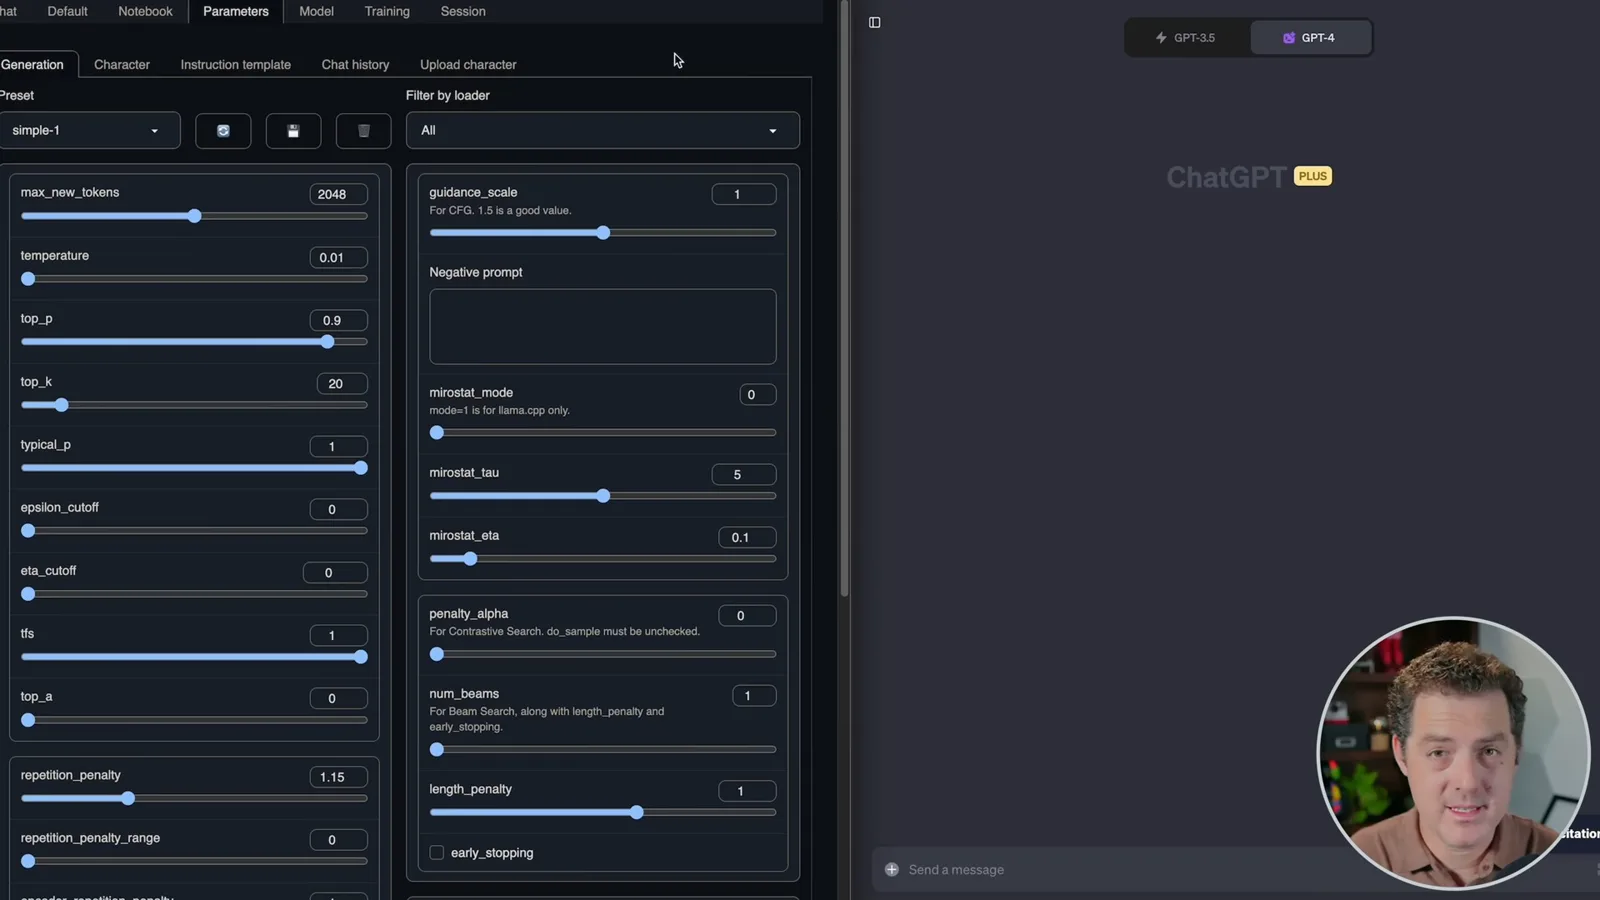
Python and Snake
Both models print a sequence and generate a Pygame Snake game. The Phind game opens but has growth and collision defects in the trial.
Both models produce Python code that prints the integers from 1 through 100, and Berman runs the outputs successfully. He then asks each to implement Snake using Pygame, a more demanding exercise than a short isolated function.
The Phind Code Llama game opens and moves, but Berman notices that the snake grows indefinitely and does not end when it hits itself; a wall collision does end it. He praises the working window while acknowledging the defects and suggests further prompting might improve it.
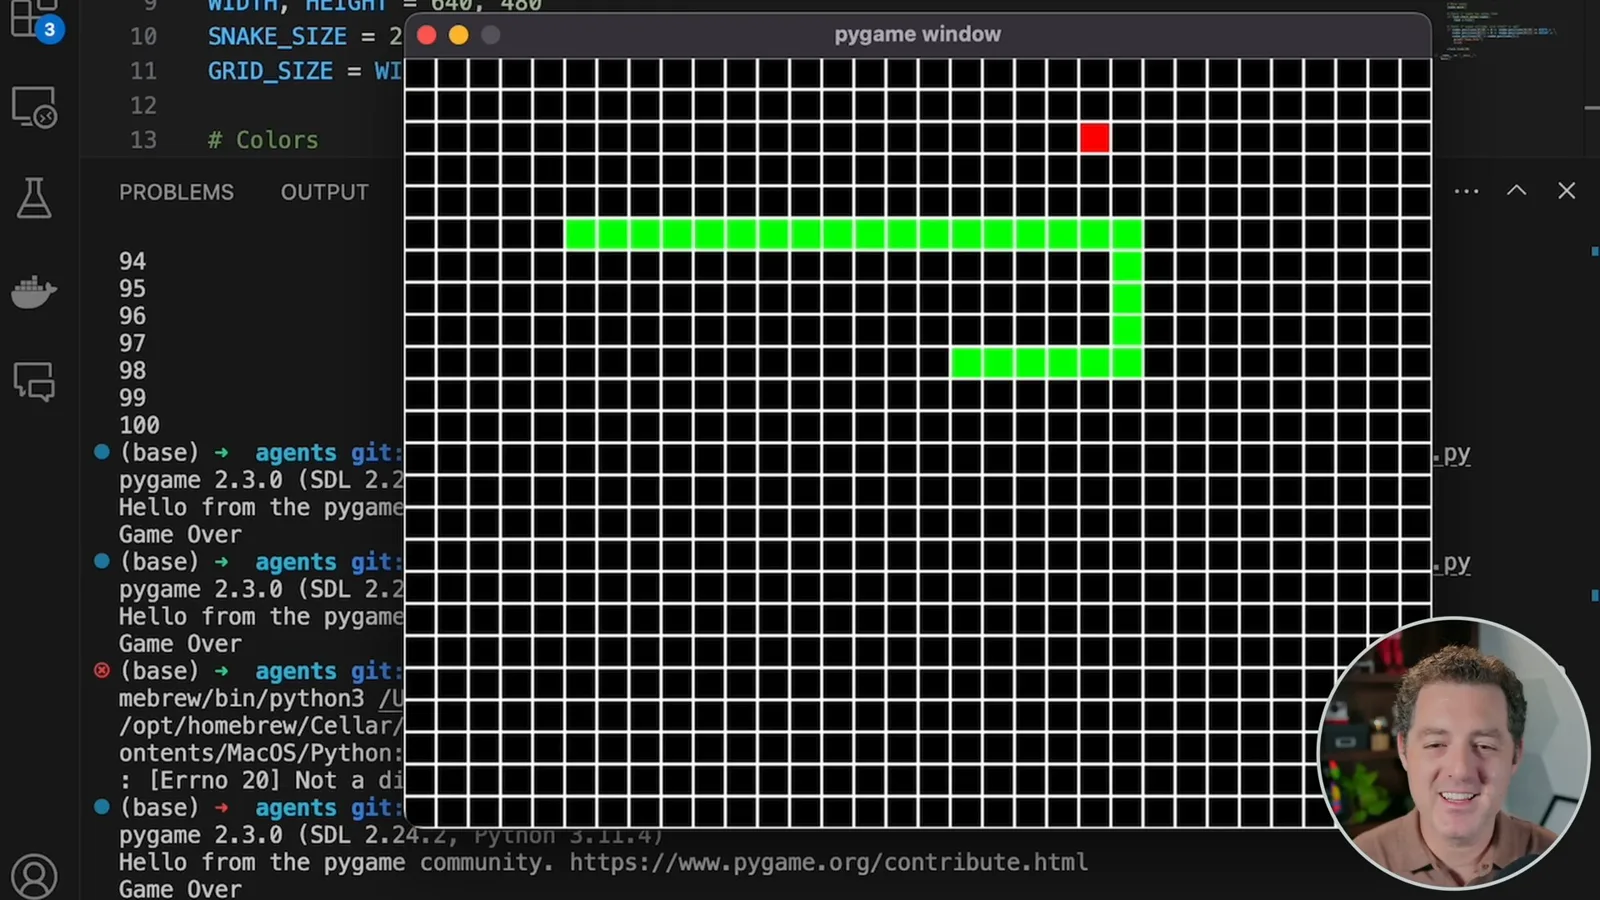
GPT-4’s Snake version also opens. In his short trial, the snake grows after eating and the game ends on self-collision, so Berman judges this run more successful. These observations are limited to the examples shown and do not verify every game mechanic.
Programming challenges
The models take list, formatting and alternating-substring exercises. Their outcomes vary by task.
He moves to Python Principles exercises. Both models pass a function that returns positions of capital letters. In an “all equal” list challenge, the Phind variant passes the site’s check while GPT-4’s generated version fails a test, which Berman highlights as a win for the former.
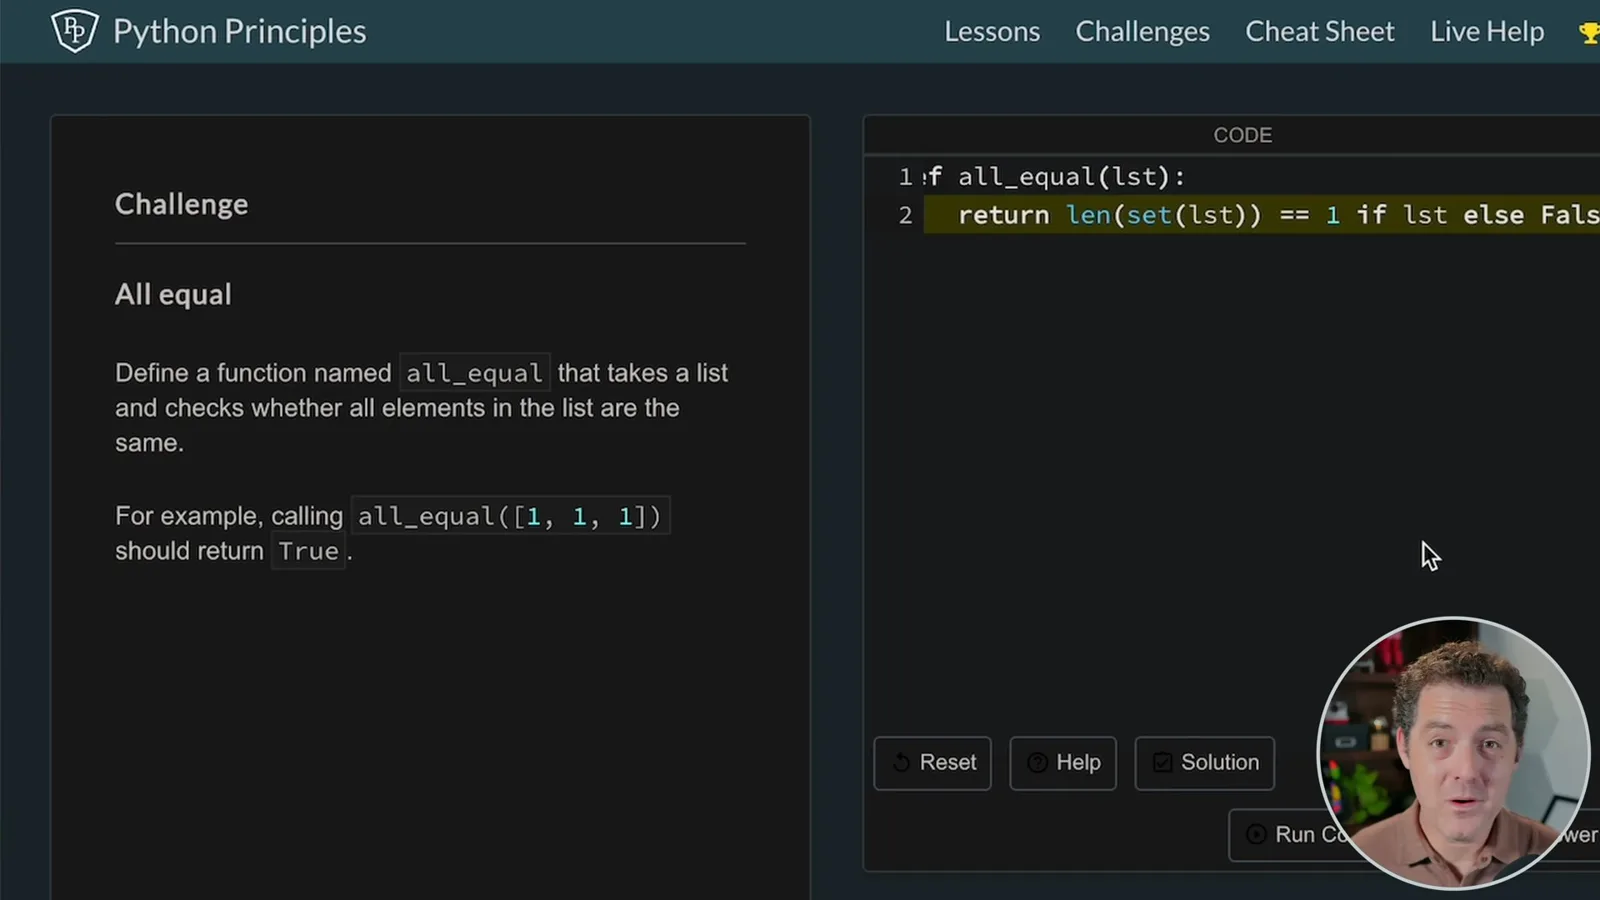
The next exercise formats a non-negative number with thousands separators. Both models produce concise Python using formatting and pass the demonstrated check. Berman then tries a harder problem: return the longest substring of alternating odd and even digits, breaking ties by earliest occurrence.
The Phind variant’s alternating-substring attempt raises an error, and GPT-4’s answer also fails the site’s check. Berman treats both as failures. A few problems and single samples reveal specific strengths and weaknesses but cannot measure overall production reliability.
Cross-model refactoring
Berman runs original and rewritten examples, then encounters an empty response in the final direction of the refactoring test.
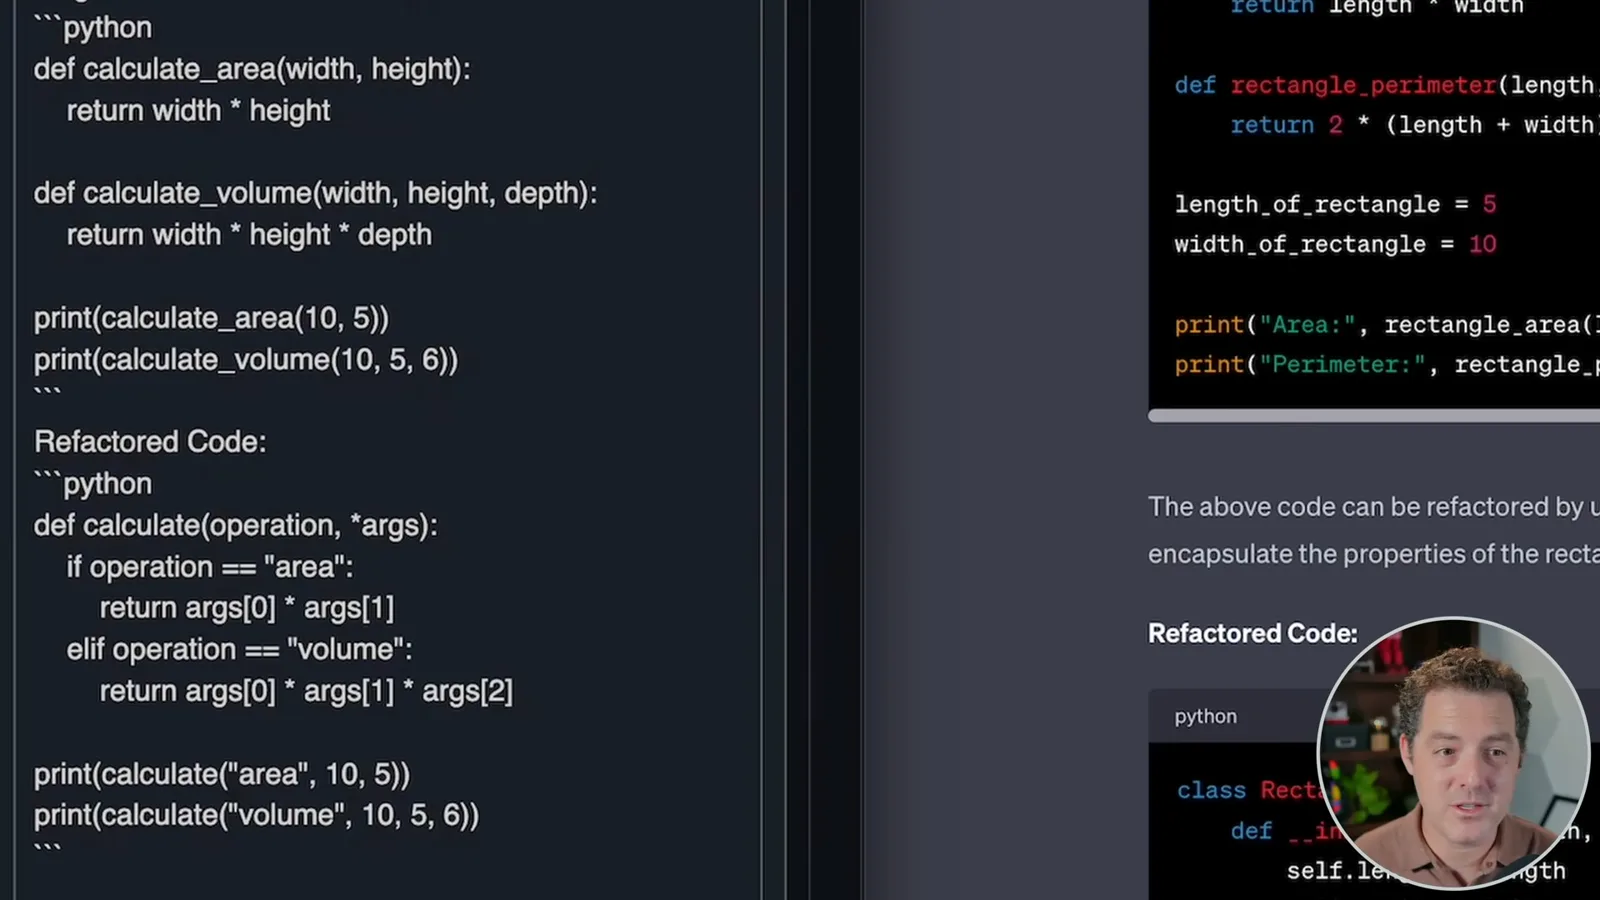
For a refactoring experiment, Berman asks the Phind model to produce original and refactored Python examples, runs each, and sees the same outputs. GPT-4 then rewrites the example using a class; he finds it longer than he wanted, although it also runs with the expected displayed values.
Berman reverses the direction: GPT-4 generates its own example and refactor, and both print the displayed area and perimeter. When he asks the Phind model to refactor GPT-4’s example, the interface returns no usable response. He records a failure while saying he does not know whether the issue lies in his setup.
Berman concludes that the tested Phind Code Llama held its own against GPT-4 on his small set of tasks, including one list exercise where GPT-4’s answer failed. His favorable assessment captures the 2023 examples, not a current model ranking or evidence that either model is uniformly better.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.