30초 요약
Matthew Berman shares his early impressions of Claude Opus 4.6 and summarizes Anthropic’s claims about coding and longer agentic tasks. He also shows a task-horizon chart and mentions the model’s one-million-token context window, which Anthropic announced in beta at launch. The chart reflects performance on a specified evaluation, not a general guarantee of autonomous work.
- 1Early impressionBerman says his early access to Claude Opus 4.6 left him impressed relative to Opus 4.5.
- 2Anthropic’s coding claimsThe launch post describes better planning, work on larger codebases, review, and debugging.
- 3A chart of task horizonsThe displayed graph estimates the human task duration at which models have a 50% chance of success on its software-task evaluation.
- 4A larger context windowAnthropic announced a one-million-token context window in beta at launch.
핵심 정리
- Berman reports positive early impressions of Claude Opus 4.6 compared with Opus 4.5.
- Anthropic claims improvements in planning, coding, review, debugging, and longer agentic tasks.
- The chart’s task horizon describes a 50% success estimate on a particular set of software tasks, not a universal autonomous runtime.
- Anthropic announced a one-million-token context window in beta at launch.
챕터별로 다듬은 전문 읽기
Opus 4.6 and coding
Berman shares his positive early impression and recaps Anthropic’s launch claims. He highlights planning, longer tasks, and code review.
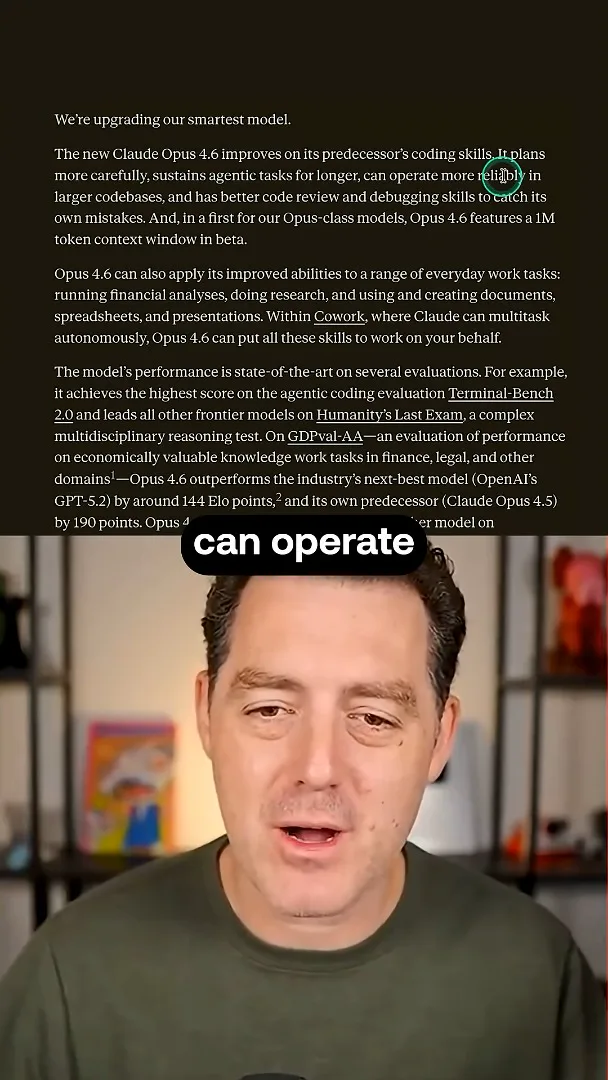
Claude Opus 4.6 is here. I had early access, and based on my experience I consider it a significant step forward over Opus 4.5. Anthropic’s [launch announcement](https://www.anthropic.com/news/claude-opus-4-6) says it plans more carefully, handles longer agentic tasks and larger codebases more reliably, and improves code review and debugging. Those are the company’s claims and my early impressions, not a complete independent evaluation.
Task horizons and context
He shows a chart of model performance on software tasks. He also points to the one-million-token context window announced in beta.
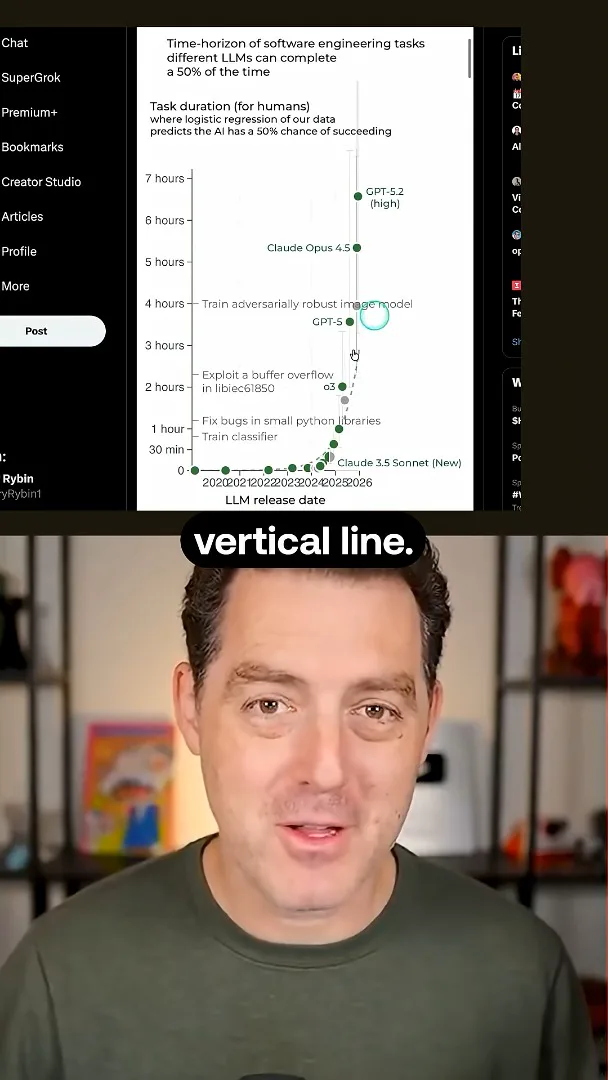
I show a chart illustrating progress in model task horizons and describe the rise as nearly vertical. The graph labels the horizon as the human task duration for which its model predicts a 50% chance of successful completion on the evaluated software tasks. It is a measure tied to that evaluation and its setup, not a guarantee that an agent can run any task autonomously for that long.
Anthropic also announced a one-million-token context window in beta at launch. I describe that as a milestone and compare it with offerings from other companies at the time. Context-window size, however, is not itself a guarantee that all information within it will be used reliably; availability and product terms can change.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.