30초 요약
Matthew Berman examines Google’s February 2024 launch of Gemini Advanced with Ultra 1.0, its subscription and integrations, then tries a Snake game, reasoning puzzles and an image prompt. His short, informal tests produce mixed results: some puzzles work, but the game and the first image description fail.
- 1Bard becomes GeminiGoogle renamed its chatbot Gemini and launched Gemini Advanced with Ultra 1.0, alongside a mobile rollout.
- 2The original paid planAt launch Google One AI Premium cost $19.99 per month in the United States, with a two-month trial and 2 TB of storage.
- 3Snake game failsThe initial Python game did not run as expected, and the follow-up fix opened a blank window.
- 4Mixed logic resultsGemini answered the shirt-drying and misplaced-ball questions correctly but missed Berman’s killer puzzle and response word-count task.
- 5Image descriptions varyThe first draft invented LaMDA text that was absent from the image; a second draft recognized a stylized llama.
핵심 정리
- In February 2024, Google renamed Bard to Gemini and introduced Gemini Advanced using its Ultra 1.0 model.
- The original Google One AI Premium plan cost $19.99 a month in the United States, included 2 TB of storage and began with a two-month trial.
- Gemini’s extensions connected it to selected Google services, providing a potential product advantage.
- Berman’s generated Snake game did not work even after a follow-up correction.
- The model answered some reasoning questions correctly but failed others and produced inconsistent image descriptions across drafts.
- A few informal prompts cannot establish an overall ranking against GPT-4.
챕터별로 다듬은 전문 읽기
Gemini Advanced launch
Berman introduces Google’s new product and plays a launch clip. He explains the Bard rebrand and the distinction between Gemini Advanced and Ultra 1.0.
Google has launched Gemini Advanced with Ultra 1.0, and I think it could challenge ChatGPT. I want to look at the distinctive Google features and then try coding and reasoning prompts, including my usual test of whether the model can create Snake in one go. This is a first look at the February 2024 release, not a comprehensive evaluation.
Bard is now called Gemini. The product names can be confusing: Gemini Advanced is the paid experience that gives access to the Ultra 1.0 model, while the existing Gemini experience uses Pro 1.0. Google said Ultra 1.0 was stronger at complex coding, logical reasoning, nuanced instructions and creative collaboration; I want to test some of those claims.
Google said it planned to add expanded multimodal features, interactive coding and deeper data analysis. At launch the US Google One AI Premium plan cost $19.99 per month, the same general price as ChatGPT Plus at the time, and offered a two-month trial and 2 TB of storage. Google also said subscribers would later get Gemini in Gmail, Docs, Slides and Sheets, features previously known as Duet AI.
Pricing, mobile and integrations
The original subscription included storage and a trial, with Workspace integration planned. Berman examines mobile access and extensions for Google services.
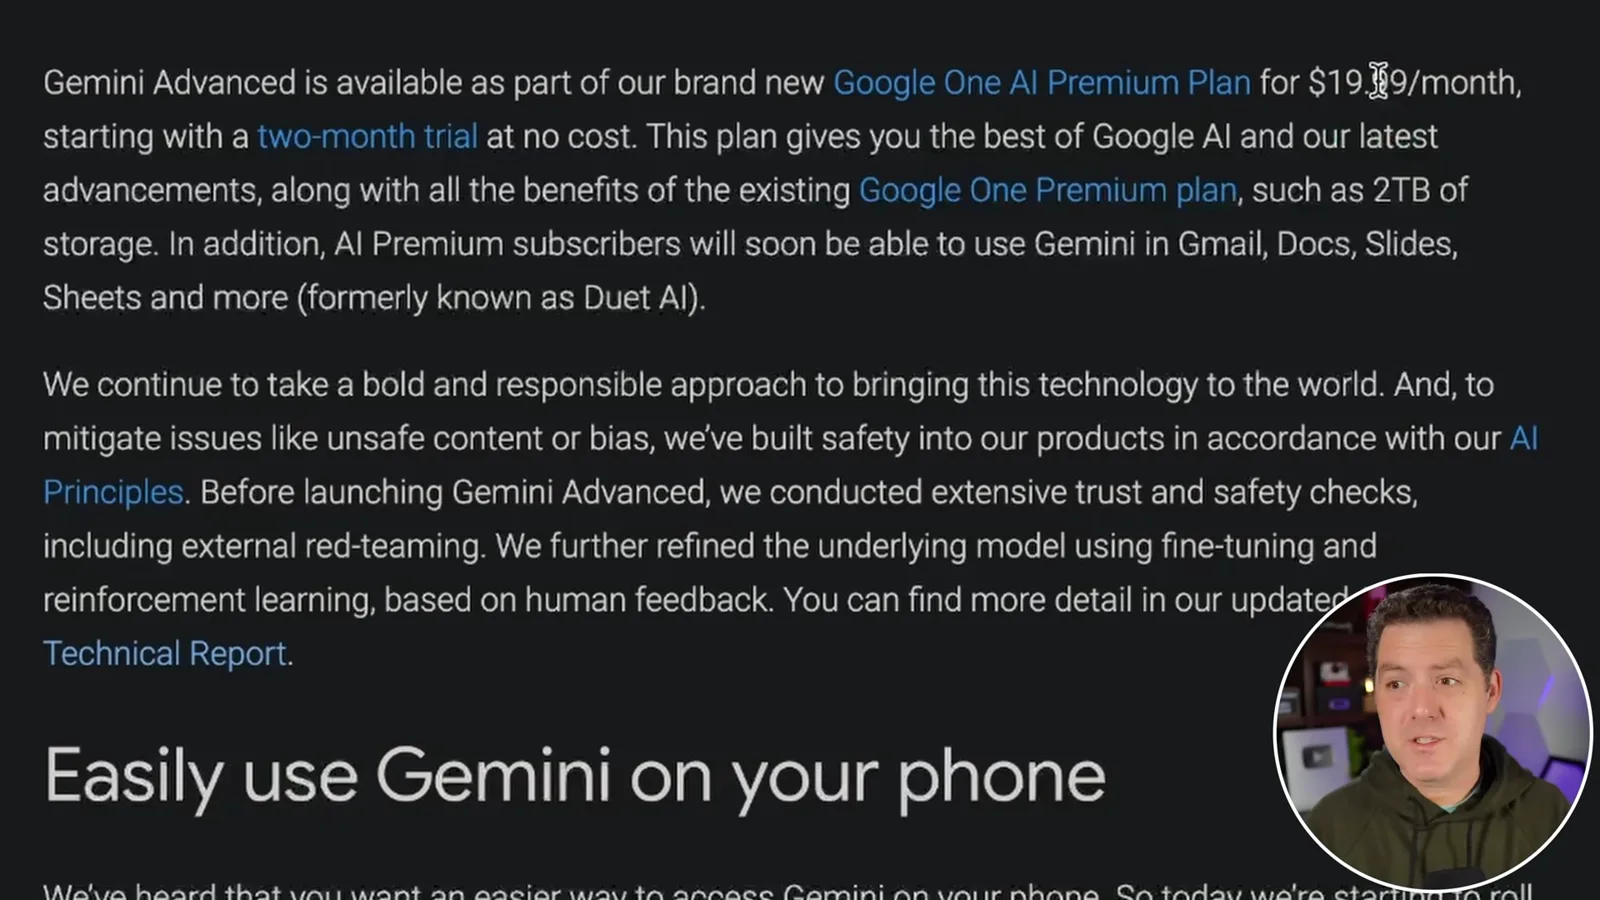
Google was rolling out a dedicated Android app and said Gemini access would come to iOS through the Google app in the coming weeks. On Android, an optional overlay could offer contextual help, including discussion of an image. I wonder whether Gemini will eventually replace Google Assistant, but that is my speculation rather than an announcement.
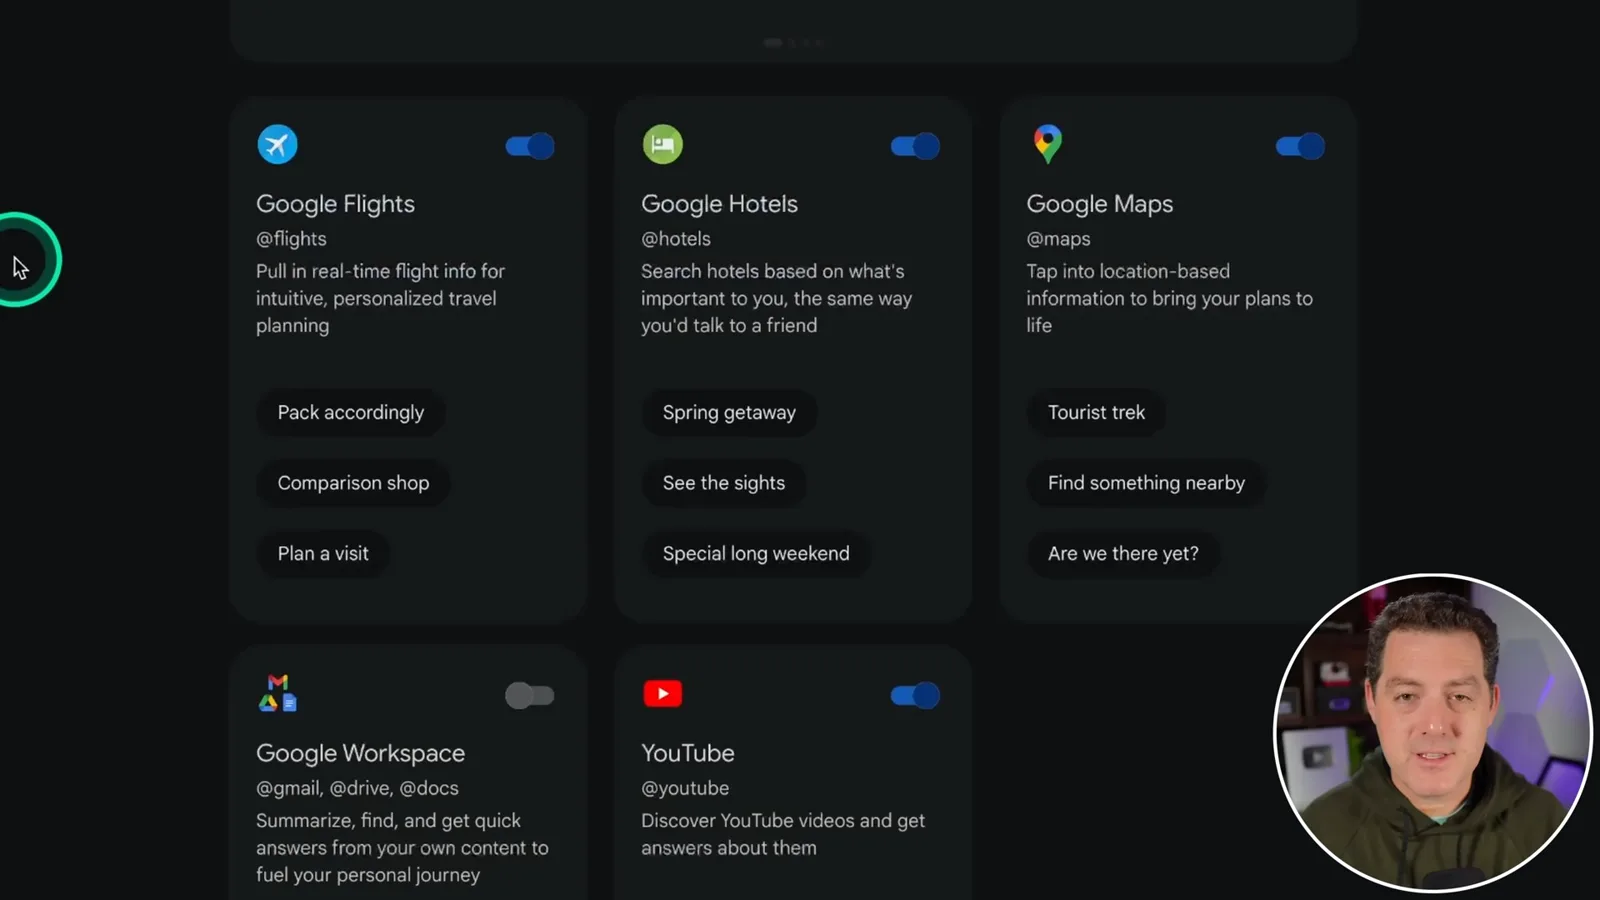
After subscribing, I select Gemini Advanced in an interface that reminds me of ChatGPT. The extensions page offers connections to Google Flights, Hotels, Maps, Workspace and YouTube. I see those integrations as a major possible advantage because they can bring relevant Google services and, where enabled, a user’s own content into the experience; the available connections and permissions matter.
Coding and reasoning tests
Gemini fails to produce a working Snake game in the demonstrated attempts. Several simple logic prompts give mixed results.
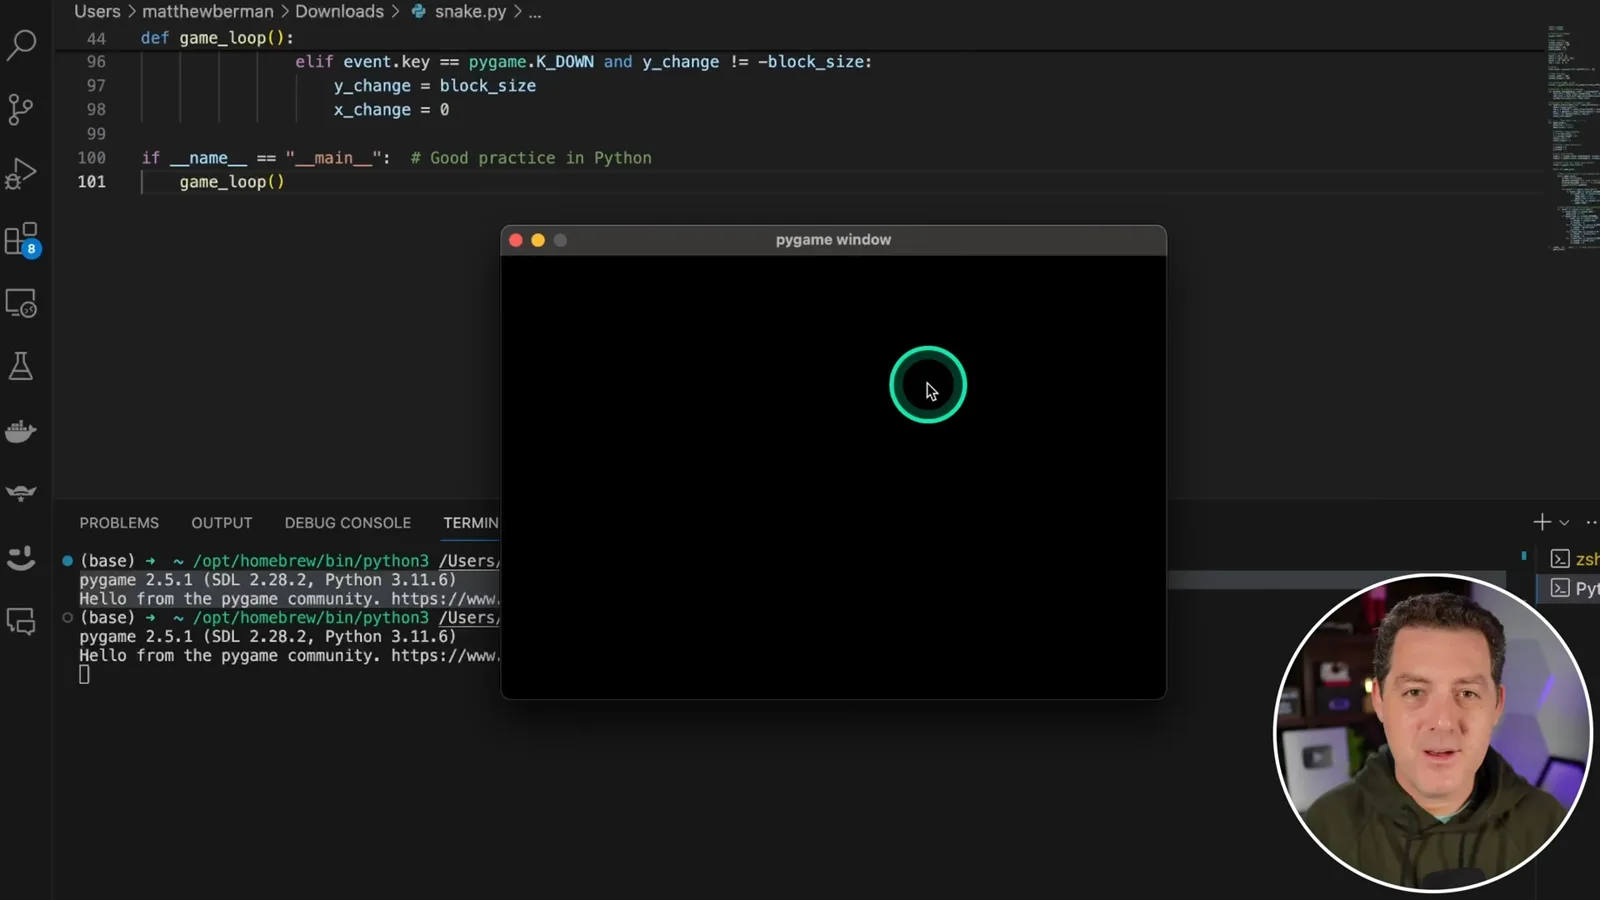
For my first test I ask it to create Snake in Python. The response appears very quickly, but when I paste the code into Visual Studio Code I notice that “screen” is undefined, and the game does not open correctly. I tell Gemini about the error and the lack of a visible result; it suggests updates, including a loop, but the revised program only opens a blank window.
Next I ask how long 20 shirts take to dry if five shirts laid out in the sun take four hours. Gemini correctly says approximately four hours, assuming they can all dry in parallel under comparable conditions. For a self-referential word-count question it suggests using a word counter rather than answering; GPT-4 also gives an incorrect count in my comparison.
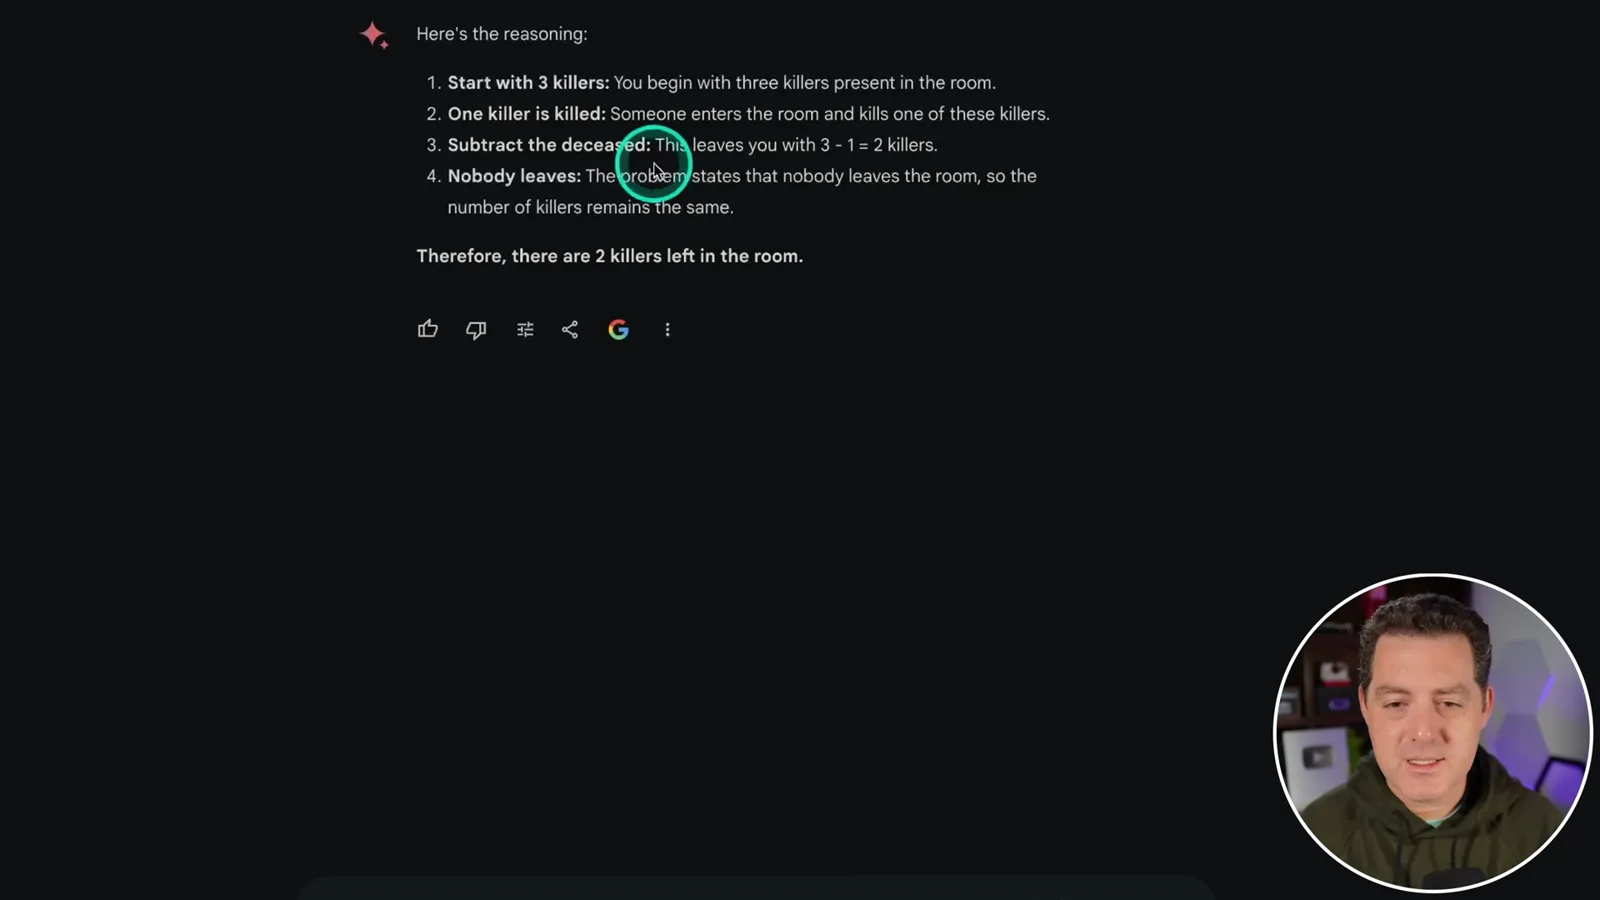
In the killer puzzle, three killers are in a room and someone enters and kills one. Gemini answers that two killers remain, overlooking that the entrant is also a killer; on the intended interpretation, three are still alive in the room. It then succeeds on a perspective-taking puzzle: John thinks a ball remains in the box where he left it, while Mark knows he moved it to the basket.
Interface features and image recognition
Berman explores response modification, search-based checking and alternative drafts. His image test reveals a false initial description and a more accurate second draft.
The interface includes controls to make an answer shorter, longer, simpler, more casual or more professional without rewriting the prompt. A double-check control searches Google, and users can also see alternative drafts or have the response read aloud. I like the flexibility, though it is worth asking which of these features prove useful in practice.
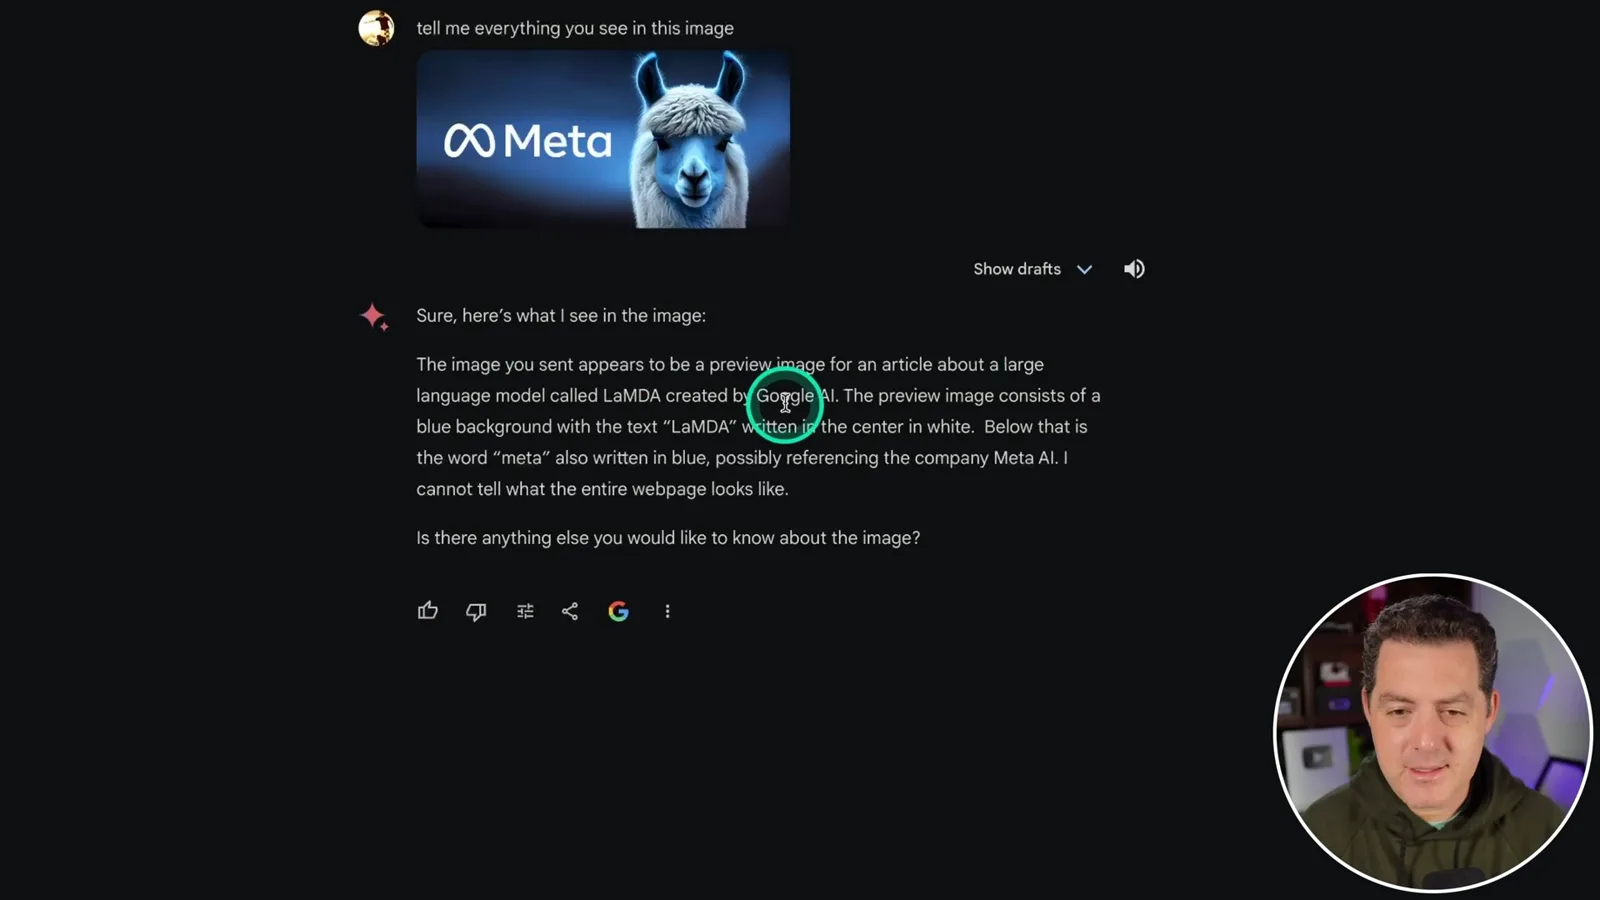
For an image test I upload a picture showing a stylized llama and the Meta logo. The first draft incorrectly describes an image about Google’s LaMDA and invents text that is not present. A second draft recognizes a blue-and-white llama and is much closer to what is shown. My brief first impression is positive about the competition, but these few examples leave me unsure whether Gemini Advanced is better than GPT-4 overall.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.