30초 요약
Theo Browne shares experiences from DEF CON and discusses Thomas Ptacek’s prediction that AI agents will change vulnerability research. He distinguishes demonstrated findings and human validation from uncertain forecasts about attacks, defenses and regulation.
- 1Puzzles are not attacksTheo reports a model solving a difficult puzzle but does not equate that with a real-world compromise.
- 2A result that did not repeatAn expert was initially surprised by an early model response, then failed to reproduce the behavior.
- 3Human-validated findingsAnthropic reported more than 500 high-severity vulnerabilities, with extensive validation and human involvement in initial patches.
- 4Maintainers need supportAutomated reports can be wrong or correct, and both require triage and coordinated fixes.
- 5Defenses still matterExperts cited in the discussion disagree about how easily agents will overcome layered defenses.
핵심 정리
- Solving puzzles, discovering vulnerabilities and compromising real systems are different capabilities.
- AI can accelerate investigation, but model outputs require evidence and expert validation.
- Anthropic reported more than 500 validated high-severity vulnerabilities with human participation in the work.
- Maintainers must handle both erroneous reports and real defects that need coordinated fixes.
- Layered defenses, timely updates and responsible disclosure remain important.
챕터별로 다듬은 전문 읽기
Why AI-assisted security research matters
Theo distinguishes reported findings from his fears about future misuse. Discovery and real-world compromise are separate steps.
AI coding tools can help find vulnerabilities as well as write software. I worry that faster, cheaper investigation could change the balance between attackers and defenders. This video was recorded before the Mythos announcement; the examples and predictions reflect what I had seen at that time.
Some public examples involve researchers and labs reporting flaws so they can be fixed. That is encouraging, but it does not tell us how often attackers are finding or using similar issues privately. Vulnerability discovery, a working exploit and an actual compromise are distinct steps.
Experiences at DEF CON
Puzzle tests and Theo’s recollection of a competition shaped his concern. He also describes a security test that did not reliably repeat.
My concern grew at DEF CON, where I saw both cryptography puzzles and security competitions. A puzzle can test persistence and reasoning, but solving one is not the same as compromising a real system. I use the stories as signals of capability, not a direct measure of offensive success.
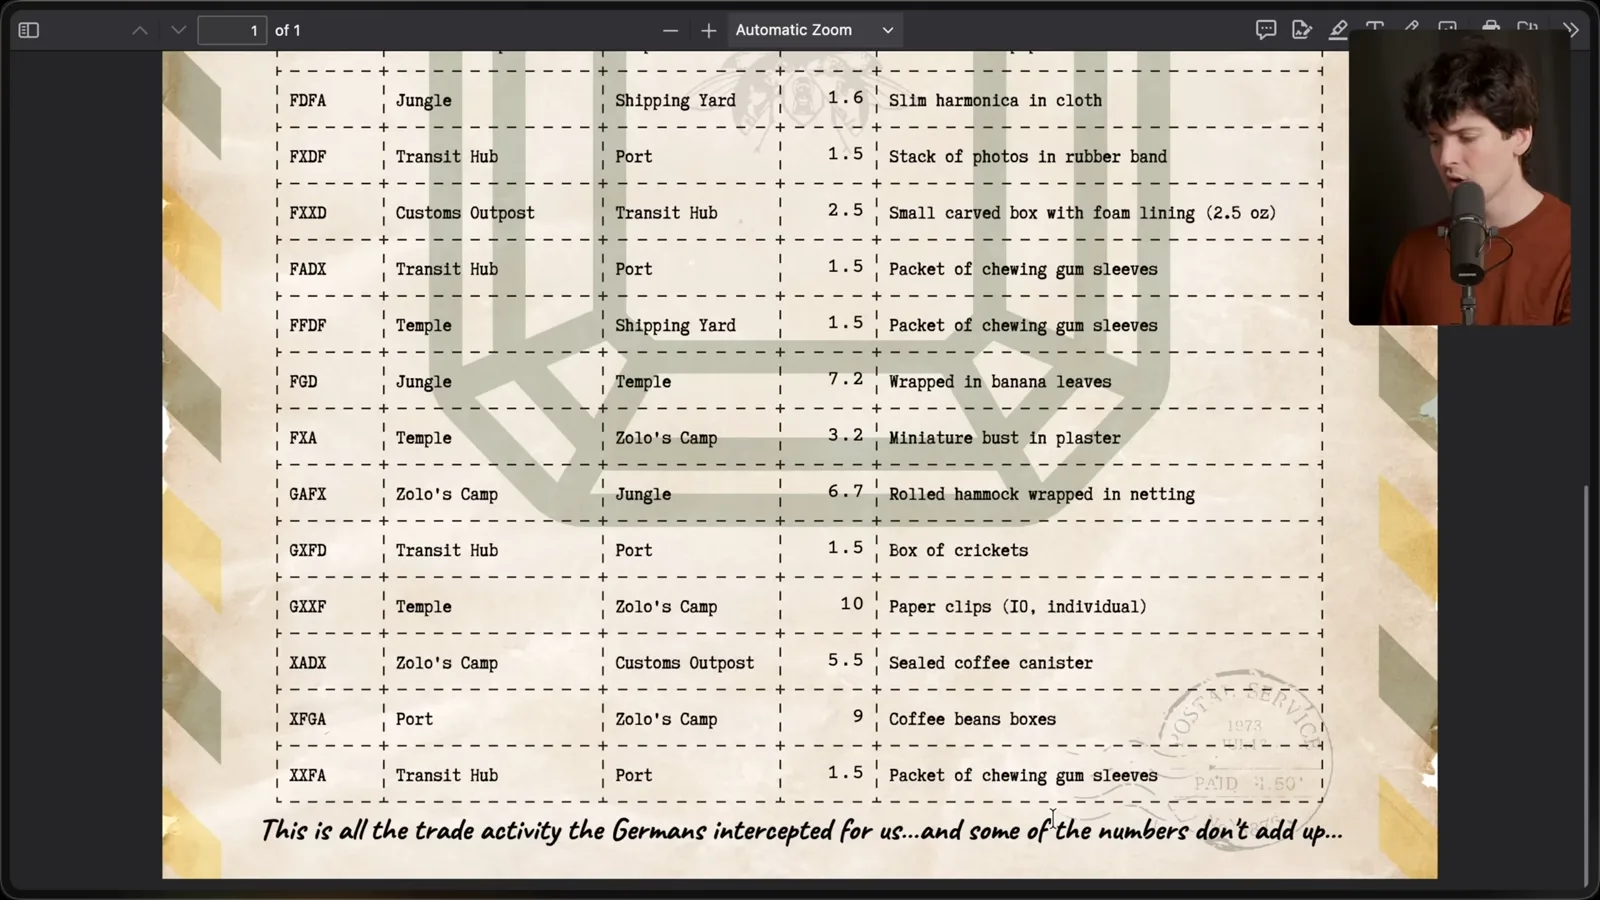
Gold Bug presents unusual puzzles requiring a hidden phrase. One challenge, Smugglers Manifest, occupied me for two days and involved reasoning through a fictional shipping document. At the time, the AI tools I tried did not help much; later models got further, sometimes with a little guidance.
Another puzzle, Sea Shanty, had bottles with phrases and a poem. My team spent a long time on it. I report that GPT-5.4 Pro later solved it in roughly 16 minutes, including time checking its answer. This is my account of a particular test, not a controlled benchmark of hacking ability.
I also recall organizers saying AI had contributed meaningfully to a DEF CON capture-the-flag competition. I could not find the relevant closing-ceremony recording or exact figures, so this remains my recollection rather than independently documented evidence. Competition environments differ from production systems.
In a hotel room, a security expert I knew tested an early GPT-5 model on an obscure Windows issue. The response appeared useful enough to surprise him, although it did not find or complete the issue. Later attempts failed to reproduce the behavior and he became less impressed; that uncertainty matters.
I discuss reports about how providers route or restrict some security-related requests. Those policies and model behavior can change, and my description is not evidence of a universal routing rule. The wider issue is how to enable legitimate security work while managing the risk of misuse.
The economics of vulnerability research
Theo discusses Thomas Ptacek’s forecast and historical security work. The proposed shift in expert attention remains a prediction.
I cite Anthropic's work with Mozilla and its reports of vulnerabilities found during testing. I then turn to security researcher Thomas Ptacek's essay on how agents may change the economics of vulnerability research. His claims about what will happen next are forecasts, even where they are grounded in real examples.
Ptacek argues that AI may produce a flood of discovered vulnerabilities, not only vulnerabilities introduced by AI-written code. If a tool can investigate many projects quickly, a larger number of previously unknown issues may reach maintainers. Whether that happens at the scale and speed he predicts remains uncertain.
The essay describes a shift from specialized human effort toward more parallelizable investigation. I worry that many systems contain unknown flaws that have not yet been found or fixed. That is a reason to strengthen review and response, not proof that every particular system is exploitable.
Ptacek draws on the history of exploit research, where practitioners learned obscure implementation details because they were exposed to untrusted input. His point is that weaknesses can appear far from an application's obvious authentication or security code. Understanding the whole path from input to processing matters.
A second part of his argument is that limited expert attention has historically influenced which components receive scrutiny. If agents make analysis cheaper, neglected devices and applications could receive much more attention from both defenders and attackers. This is an argument about changing incentives, not a claim that sound defenses never mattered.
Automated investigation and validation
Models can help explore code and hypotheses, but outputs require expert verification. Anthropic reported human-validated findings and patch work.
I ask a model about relationships among Linux subsystems without web search to illustrate the breadth of information it can draw on. I am not a kernel specialist, and a plausible answer is not automatically correct. Domain experts still need to check claims against source code and evidence.
Ptacek argues that agents can repeatedly compare patterns, inspect code and test hypotheses without getting tired. This can speed up parts of research, but tests, tools, compute, permissions and expert judgment still matter. Finding a suspicious pattern is not the same as proving impact.
Anthropic reported more than 500 high-severity vulnerabilities found and validated during its open-source security work with Opus 4.6. Its report says findings were extensively validated, and human researchers checked initial bugs and wrote patches. The number is a report of validated vulnerabilities, not a count of unattended attacks.
Ptacek describes Nicholas Carlini using repeated agent runs across source files and then reviewing candidate reports. He reports strong results for that workflow, but the quoted near-100% figure lacks enough detail in the discussion to treat it as a general accuracy or success rate. Human validation and responsible disclosure remain essential.
The essay describes a web application flaw as an example of a finding that goes beyond memory corruption. The lesson is that established code and familiar components can still contain defects. A report needs reproducible evidence and coordinated remediation rather than confidence based only on a model's explanation.
Patching and maintainer burden
More attention to neglected targets could increase pressure on maintainers. Existing layered defenses and careful disclosure continue to matter.
Ptacek predicts that more targets will become economical to investigate, including devices that are difficult to update. I agree that slow patching creates risk. Keeping supported systems updated and planning for devices that cannot be updated can reduce exposure, although no single measure guarantees safety.
Open-source maintainers already face low-quality automated reports. They may also face more valid reports that require triage and fixes. Both false positives and real findings create work, so researchers should validate reports and coordinate with maintainers rather than simply increase volume.
The essay raises memory-safe languages, sandboxing and attack-surface reduction as existing defenses. It predicts that agents will eventually make chained attacks easier, but that is a forecast. Layered defenses still increase attacker effort, and the effectiveness of automated research against them requires measurement.
Ptacek also argues that keeping source closed is not a complete defense, because binaries can be analyzed. Openness and secrecy can change the effort required for different actors, but neither eliminates vulnerabilities. Organizations need patching, isolation and monitoring regardless of source availability.
Regulation and uncertainty
Ptacek worries about rules that burden legitimate research. Other experts emphasize defenses, specialist tools and continuing human roles.
A further worry is regulation that accidentally burdens legitimate vulnerability research while doing little to stop misuse. Ptacek expects political pressure after damaging incidents, while acknowledging disagreement among people who work on security policy. This is a concern about possible future rules, not a statement of current law.
One researcher Ptacek consulted believes exploit chains will remain difficult because of layered defenses such as sandboxes and virtualization, and expects specialized analysis tools to retain value. Another sees room for human researchers at the highest end, particularly where techniques are not documented. These are meaningful qualifications to the more sweeping forecast.
Ptacek expects agents to displace much human vulnerability research; I find his warning compelling and unsettling. The outcome is not settled, and the stories here do not prove that every system can be compromised by AI. What is clear is the need to support defenders, validate findings and get fixes to users.
같은 채널의 다른 글
 38:47EN
 Theo - t3․gg· 2026년 10월 28일Theo’s Long-Running Agent Experiments: Verification, Compute and CostTheo Browne · Ping LabsA skateboard game and two compiler projects show how repeated checks and flexible compute can sustain agent work—and how expensive those loops can become.
 36:07ENTheo - t3․gg· 2026년 10월 27일Theo on Token Costs, Coding Agents, and the Price of AI CapabilityTheo Browne · Ping LabsA viral estimate of Lauren's AI spending prompts a closer look at cache pricing, benchmarks, and the changing work of coding agents.
 30:37ENTheo - t3․gg· 2026년 10월 26일Theo’s Three Skills for Reviewing and Shipping with Coding AgentsTheo Browne · Ping LabsHow sol-loop, full-send and full-stop encode review, verification and different levels of merge authority.
 0:43ENTheo - t3․gg· 2026년 10월 23일Theo Distinguishes Security Vulnerabilities from Active AttacksTheo Browne · Ping LabsA short explanation of why disclosed software flaws and reported attacks are different kinds of security news.
 29:22ENTheo - t3․gg· 2026년 10월 22일Theo on Security Vulnerabilities, Stolen API Keys and AITheo Browne · Ping LabsA look at the gap between vulnerability disclosure and patching, and a speculative account of why stolen inference keys may be valuable.
 31:13ENTheo - t3․gg· 2026년 10월 20일Theo on Why Smarter Models Help More Than DevelopersTheo Browne · Ping LabsFrom game modifications to compiler experiments, Theo revisits his assumptions about who benefits from more capable AI.