30초 요약
Matthew Berman proposes a single API that routes requests among local, open-weight and proprietary models, with optional workflow techniques, benchmarking and caching. He presents it as an unbuilt idea, drawing on RouteLLM and Apple Intelligence as reference points. The article distinguishes his estimates from measured results and explains the tradeoffs of routing and caching.
- 1A single routing endpointBerman proposes a drop-in API connecting local, open-weight and proprietary models.
- 2RouteLLM evidenceThe research reports benchmark-specific cost savings, not a universal guarantee.
- 3Measure qualityCustom benchmarks could test models and workflows against an organization’s own tasks.
- 4Cache carefullyReusing an answer can cut latency and cost when context, permissions and freshness allow it.
핵심 정리
- The proposed API would route each request among multiple models based on customer priorities.
- Routing results depend on the evaluated tasks, model pairs and quality thresholds.
- Local inference can reduce external calls but still consumes resources and requires privacy controls.
- Agentic techniques and caching require task-specific evaluation rather than guaranteeing quality.
- Built-in benchmarks and prompt management are proposed extensions, not demonstrated features.
챕터별로 다듬은 전문 읽기
The optimization problem
Berman shares an unbuilt startup concept for teams using language models. He describes cost, latency and dependence on a single provider.
I have a business idea but not enough time to build it, so I'm sharing it in the hope someone else will. I call it Abstract AI: an abstraction layer above language models for companies building AI products and organizations deploying AI internally. The aim is to make it easier to choose and operate models efficiently.
My premise is that many developers send every request to one frontier model through a single provider, even when a smaller model might suffice. They may pay more than necessary and become exposed to changes in that provider's prices, policies or availability. I estimate that 90–95% of use cases do not require a frontier model, but that is my judgment, not a measured universal statistic.
The proposed product targets latency, cost and flexibility. In my view, developers care less about a model's name than whether its responses are consistently good enough, fast enough and affordable at scale. Even modest savings could matter when an organization processes very large numbers of tokens, though actual results would depend on workload and infrastructure.
A routing API
The proposed endpoint would choose among models and techniques. RouteLLM provides an example of benchmark-specific cost and quality tradeoffs.
Developers also have a growing menu of techniques, including model routing, chain-of-thought prompting and mixtures of agents. Implementing and evaluating them takes work, and the field changes quickly. I envision a service that maintains these choices so application teams can focus on their own products.
Abstract AI would be a drop-in API endpoint connected to proprietary, open-weight and local models. For each request, a router would choose a model and, where appropriate, a workflow according to the customer's priorities for quality, speed and cost. These goals can conflict; no routing layer can guarantee the cheapest, fastest and best answer simultaneously for every prompt.
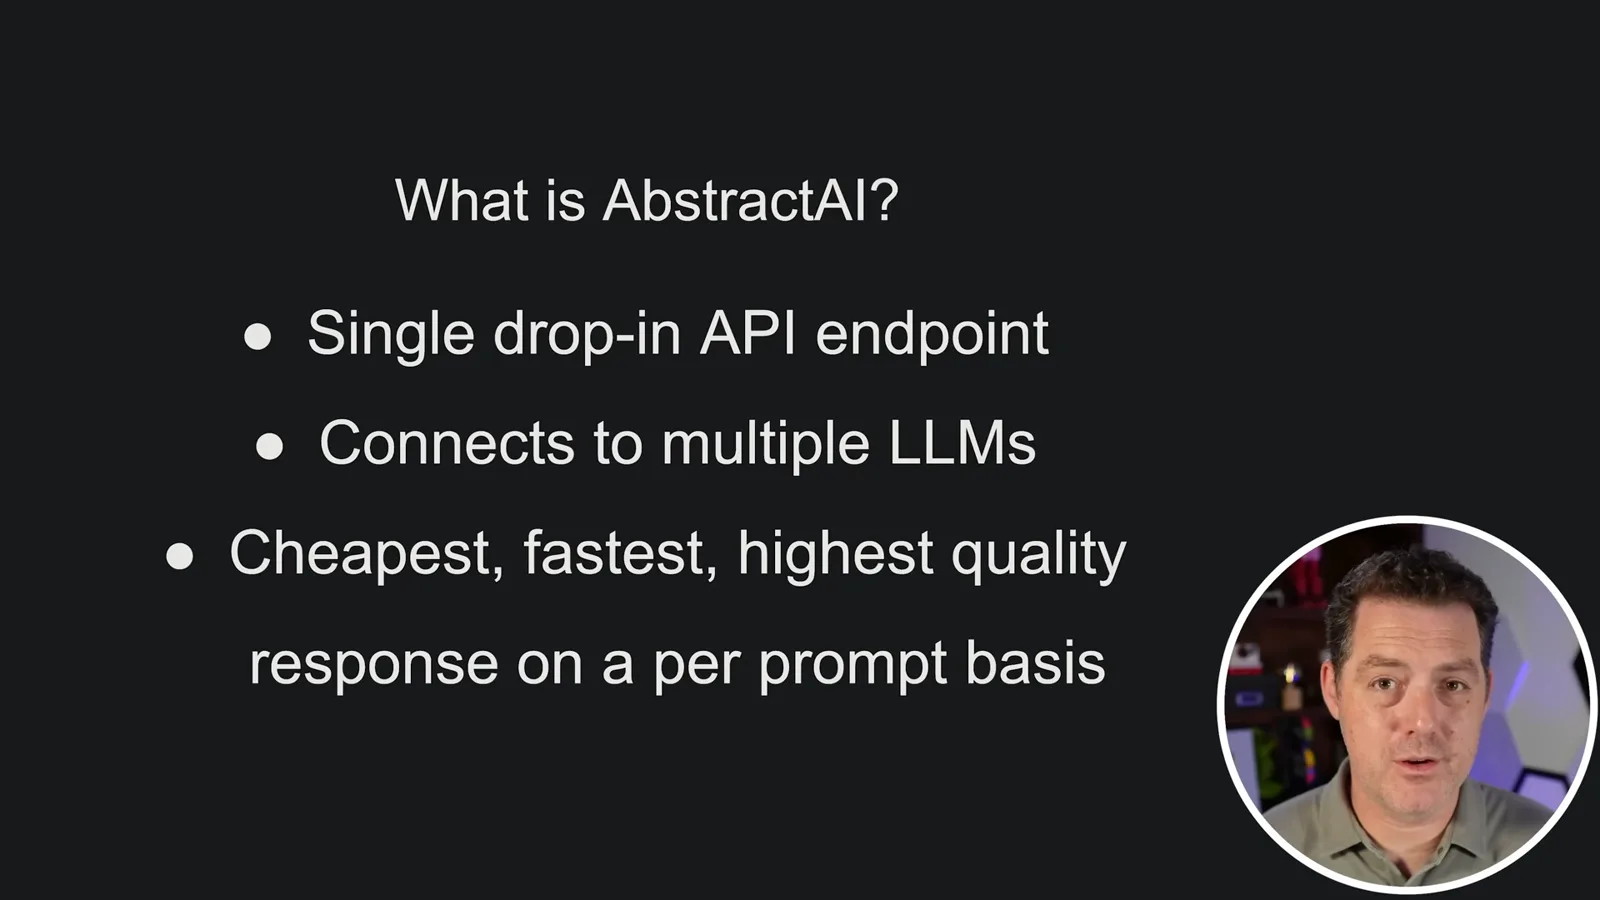
I cite RouteLLM as evidence that routing can reduce cost while preserving much of a stronger model's quality. The [RouteLLM researchers](https://www.lmsys.org/blog/2024-07-01-routellm/) report over 85% cost reduction at 95% of GPT-4 performance on MT Bench in their tested setup, with smaller reductions on other benchmarks. Those results are benchmark- and model-pair-specific, not a promise of the same savings for every application.
Local models and customer priorities
He imagines handling some requests locally and routing harder ones to cloud models. Customers could prioritize quality or speed.
A company might run a small model on employee devices and send harder requests to private or external cloud models. I speculate that most prompts could be handled locally, potentially reducing external API use and data transfers. The actual proportion, quality, hardware cost, latency and privacy depend on the workload and implementation; local inference is not literally cost-free.
I compare the idea with Apple's proposed combination of on-device processing, Private Cloud Compute and, with permission, external model assistance. The analogy illustrates a routing pattern, not proof that Abstract AI would provide Apple's privacy guarantees or use the same decision rules.
The routing component could be trained or calibrated for a company's particular tasks and available models. I also imagine combining it with agent frameworks, mixtures of agents or chain-of-thought techniques. These methods may help particular tasks but can add calls, cost and latency, and need evaluation rather than an assumption that they always improve quality.
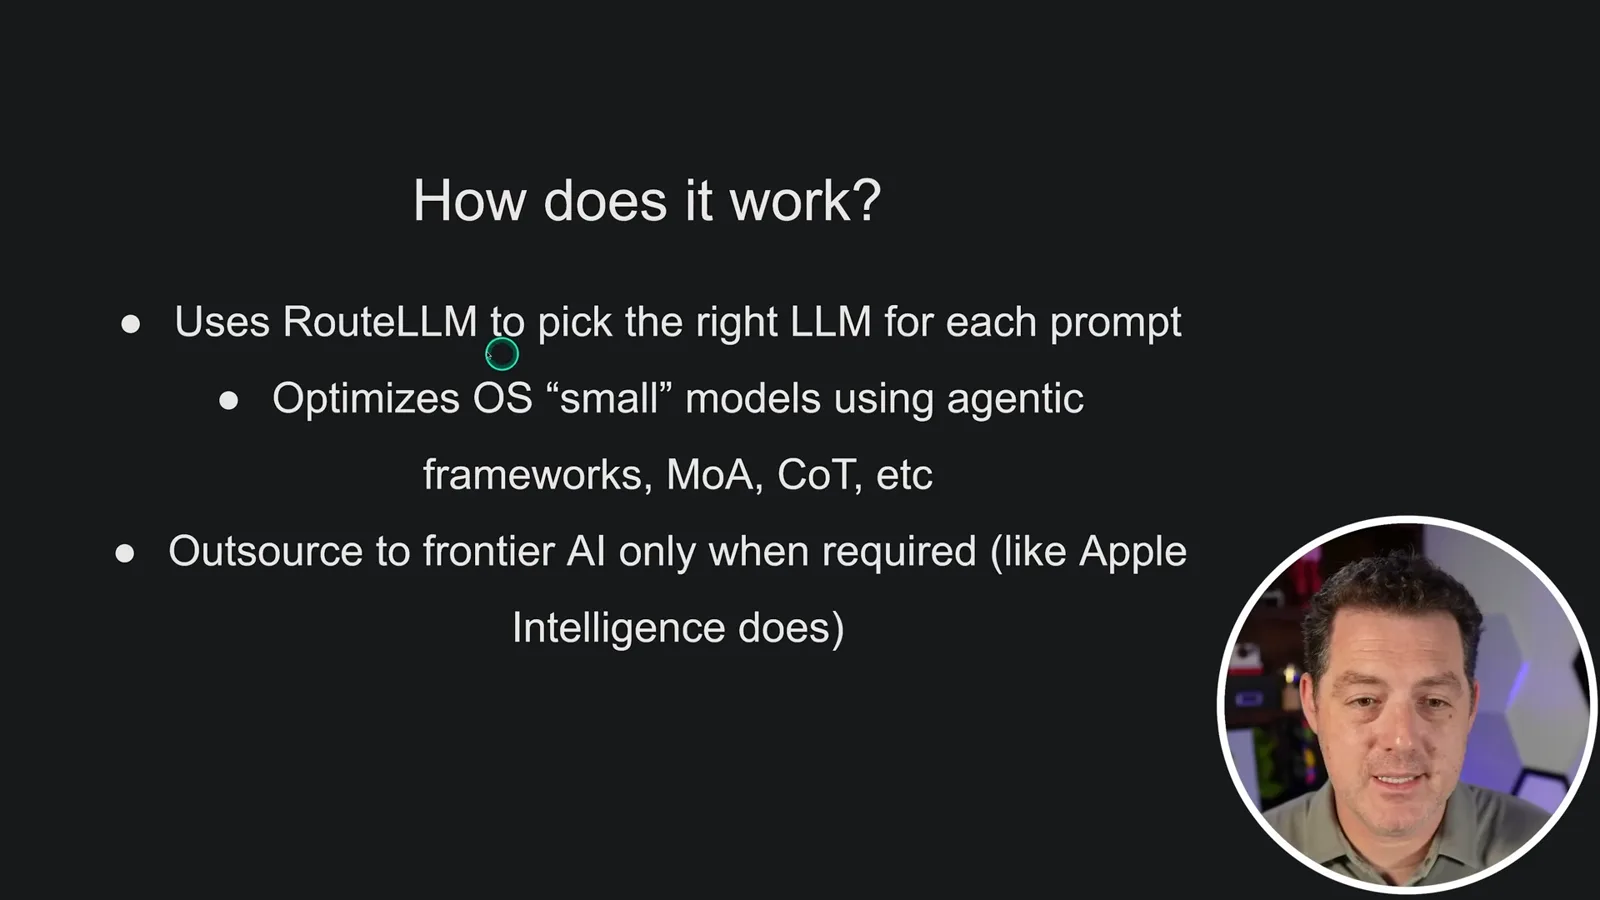
A customer could tell the API whether speed or answer quality matters most, and the router could adjust accordingly. It would use a frontier model when the estimated benefit justifies it. The difficult engineering problem is to measure those tradeoffs and monitor them as models, prices and user needs change.
Benchmarks, caching and expansion
Berman proposes custom evaluation and caching, followed by prompt management. The video closes by inviting others to build the idea.
Built-in benchmarking would test both response quality and consistency against a company's own examples. Each candidate model or workflow could be evaluated before being added to routing. This makes the promised optimization measurable for a real use case instead of relying only on generic leaderboards.
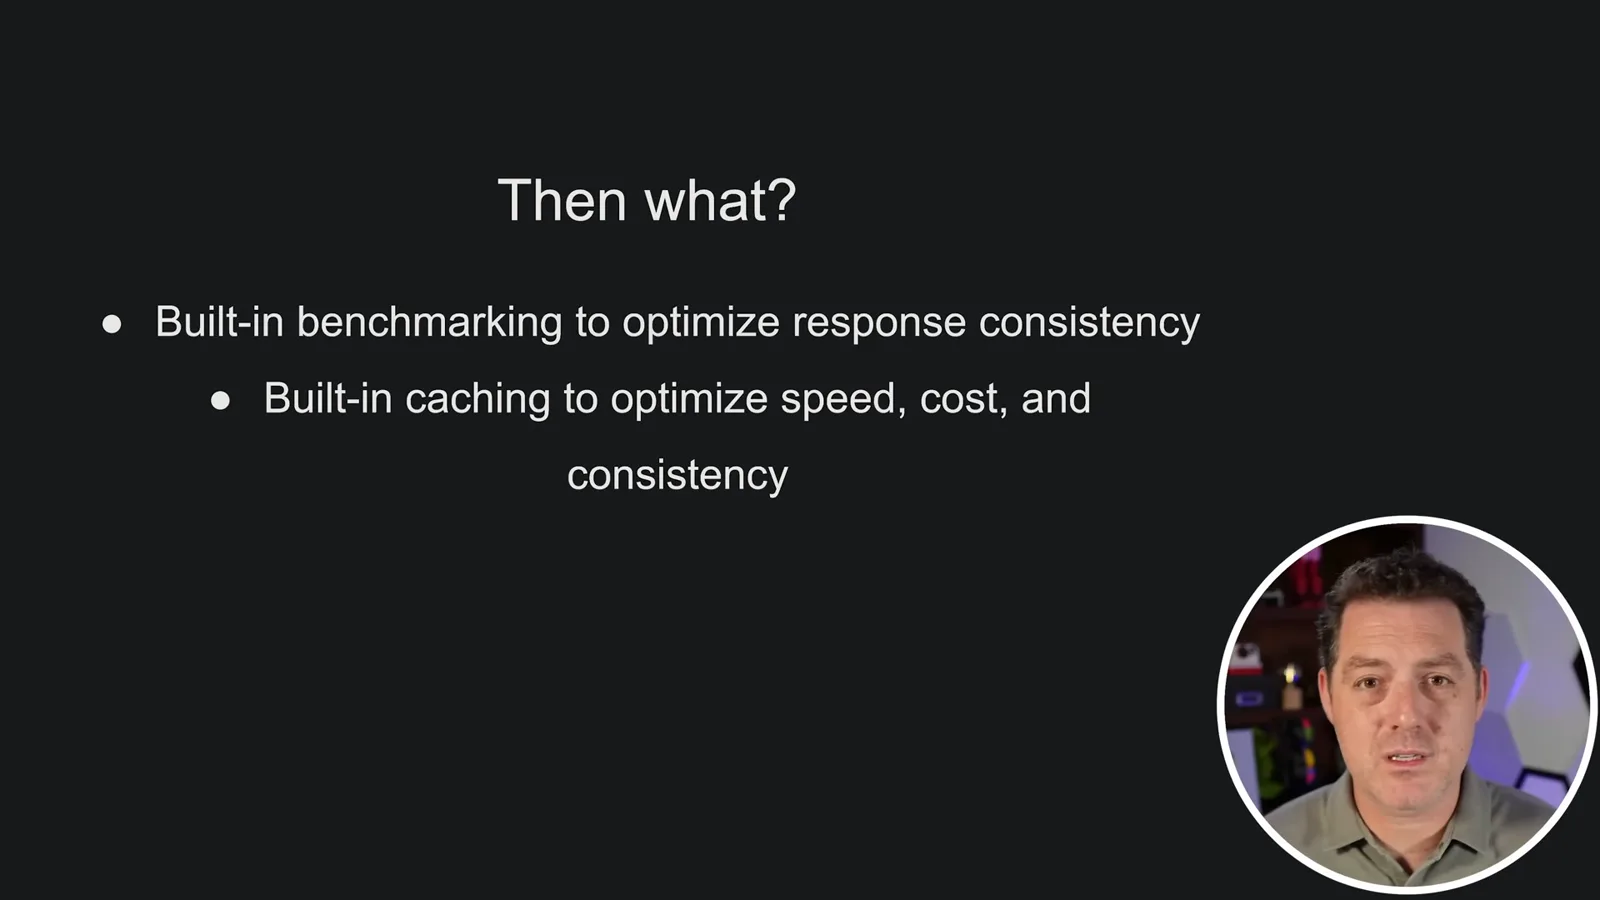
I also propose caching repeated requests so a previous answer can be returned without another model call, improving speed and consistency and potentially lowering cost. Whether reuse is appropriate depends on context, freshness, permissions and the desired variability; a cached answer can be stale or wrong, so caching alone does not guarantee quality.
Because the service would sit in the path of many AI requests, it could later expand into prompt management: user and group permissions, company rules, prompt versions and benchmarking those versions. That would make the API layer a broader operational tool, although it would also need to handle sensitive data and access controls carefully.
This is a rough product idea rather than a finished system. I think there could be a valuable product or business here, and I would like to hear from anyone who decides to build it. The proposed savings and quality improvements need to be established with real workloads and careful measurement.
같은 채널의 다른 글
 34:21EN
 Matthew Berman· 2026년 10월 27일Matthew Berman Examines Anthropic’s IPO Filing, AI Growth and GovernanceMatthew Berman, Sam Altman · Forward FutureThe presenter reviews the S-1’s financial metrics, compute strategy and voting structure while questioning the tension between rapid AI development and safety.
 0:26ENMatthew Berman· 2026년 10월 25일Sam Altman on Human Values and Problem-Solving in an AI WorldSam Altman · OpenAIIn a short interview excerpt, Altman considers the enjoyment of solving hard problems and the human role in interpreting results.
 0:36ENMatthew Berman· 2026년 10월 25일Kimi K3.1 and a Rubik’s Cube Solver DemonstrationMatthew Berman · Forward FutureMatthew Berman shows a scrambled virtual cube being solved and gives the Kimi K3.1 test a favorable assessment.
 0:21ENMatthew Berman· 2026년 10월 24일An AI-Generated Kimi Benchmark Chart Used Invented ScoresMatthew Berman · Forward FutureMatthew Berman asks for a graph of Kimi K3.1 Pro benchmarks, then discovers that the displayed figures are illustrative placeholders.
 25:50ENMatthew Berman· 2026년 10월 24일Kimi K3.1 Pro Tested: Strong 3D Demos, Uneven Results and Competitive PricingMatthew Berman · Forward FutureMatthew Berman tests the open-weight model on coding, 3D rendering and visual explanations, then compares benchmark results and prices.
 32:20ENMatthew Berman· 2026년 10월 23일Who Is Local AI For? The Costs, Trade-offs and a Hybrid FutureMatthew Berman · Forward FutureMatthew Berman weighs data control and independence against hardware cost, setup complexity and inference speed.