30초 요약
Nathan Lambert derives the policy-gradient estimator and maps reinforcement-learning concepts to language models. He compares REINFORCE, PPO and GRPO, explaining baselines, clipping, value functions and newer stability-oriented variants.
- 1Language models as policiesThe next token is an action and the prompt plus prior tokens form a state.
- 2The log-derivative identityIt makes the gradient of expected return estimable from sampled trajectories.
- 3BaselinesA state-dependent, action-independent baseline can reduce variance.
- 4PPO clippingA conservative surrogate limits further improvement from overly large probability-ratio changes.
- 5Group-relative advantagesGRPO compares multiple completions of the same prompt instead of training a value model.
핵심 정리
- Policy gradients weight log-probability gradients by a measure of action quality.
- An action-independent baseline can reduce variance without changing the expected gradient.
- PPO uses clipping and often a learned value function to make sample reuse practical.
- GRPO estimates advantages from a group of responses without a separate critic.
- The old policy and the reference policy serve different purposes.
챕터별로 다듬은 전문 읽기
RL for language models
Lambert introduces the policy, reference and reward models and maps language generation to an RL episode.
This lecture covers policy-gradient algorithms for language-model reinforcement learning, from the underlying theorem to REINFORCE, PPO and newer variants. A following lecture focuses on implementation. Lambert places RL in the larger post-training pipeline alongside instruction tuning and reward modeling.
A simplified RLHF setup has a trainable policy, a frozen reference model and a reward model. The policy generates a completion; the reward model scores it; and a KL-based penalty discourages excessive movement from the reference. The combined signal drives a policy update.
Lambert observes that policy-gradient methods originally developed for agents have worked surprisingly well on pretrained language models. In his experience, RL on a narrow domain can improve behavior without necessarily destroying broad capabilities, although the reasons and limits remain research questions.
The same core RL mathematics applies to both human-feedback and verifiable-reward training. Their rewards differ, and the practical tradeoffs can differ, but PPO- or GRPO-family methods can be used in either setting.
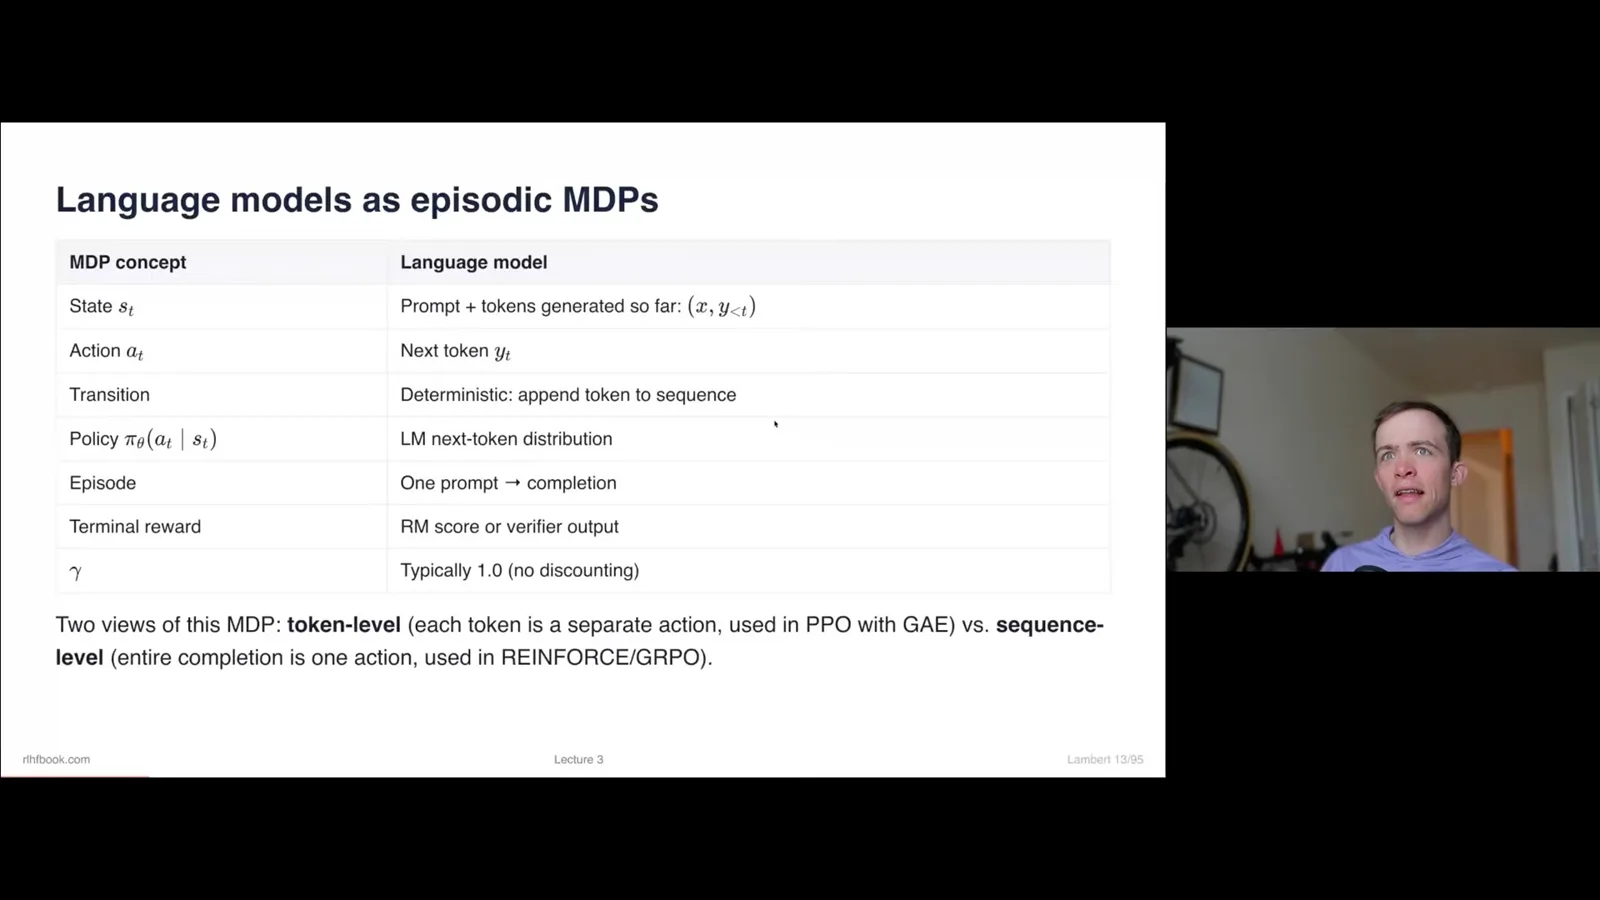
In classical RL an agent acts in an environment. For a simple language-model episode, the state is the prompt plus generated tokens so far, the action is the next token, and the policy is the model’s next-token distribution. A completion can be treated as an episode with a terminal score.
The lecture uses state and action notation, while language-model papers often use prompt x and completion y. A trajectory groups the sequence of states and actions; the discount factor is often set to one for a single completion, though more complex agent environments can differ.
Policy-gradient intuition and derivation
Values and advantages weight sampled actions. The log-derivative identity turns expected reward into a sample-based gradient estimator.
The objective is expected cumulative reward under the policy. We cannot enumerate every trajectory, so we sample a finite number and estimate a gradient showing how to change model parameters to improve expected return.
The policy-gradient update combines a gradient of log action probability with a scalar describing how good the action was. As an intuition, positive advantage encourages an action and negative advantage discourages it. Sampling makes the estimates noisy.
A value function estimates expected future return from a state. An action-value function conditions on both the state and an action. Advantage compares an action’s value with the state’s baseline value. These related quantities offer different ways to weight a policy update.
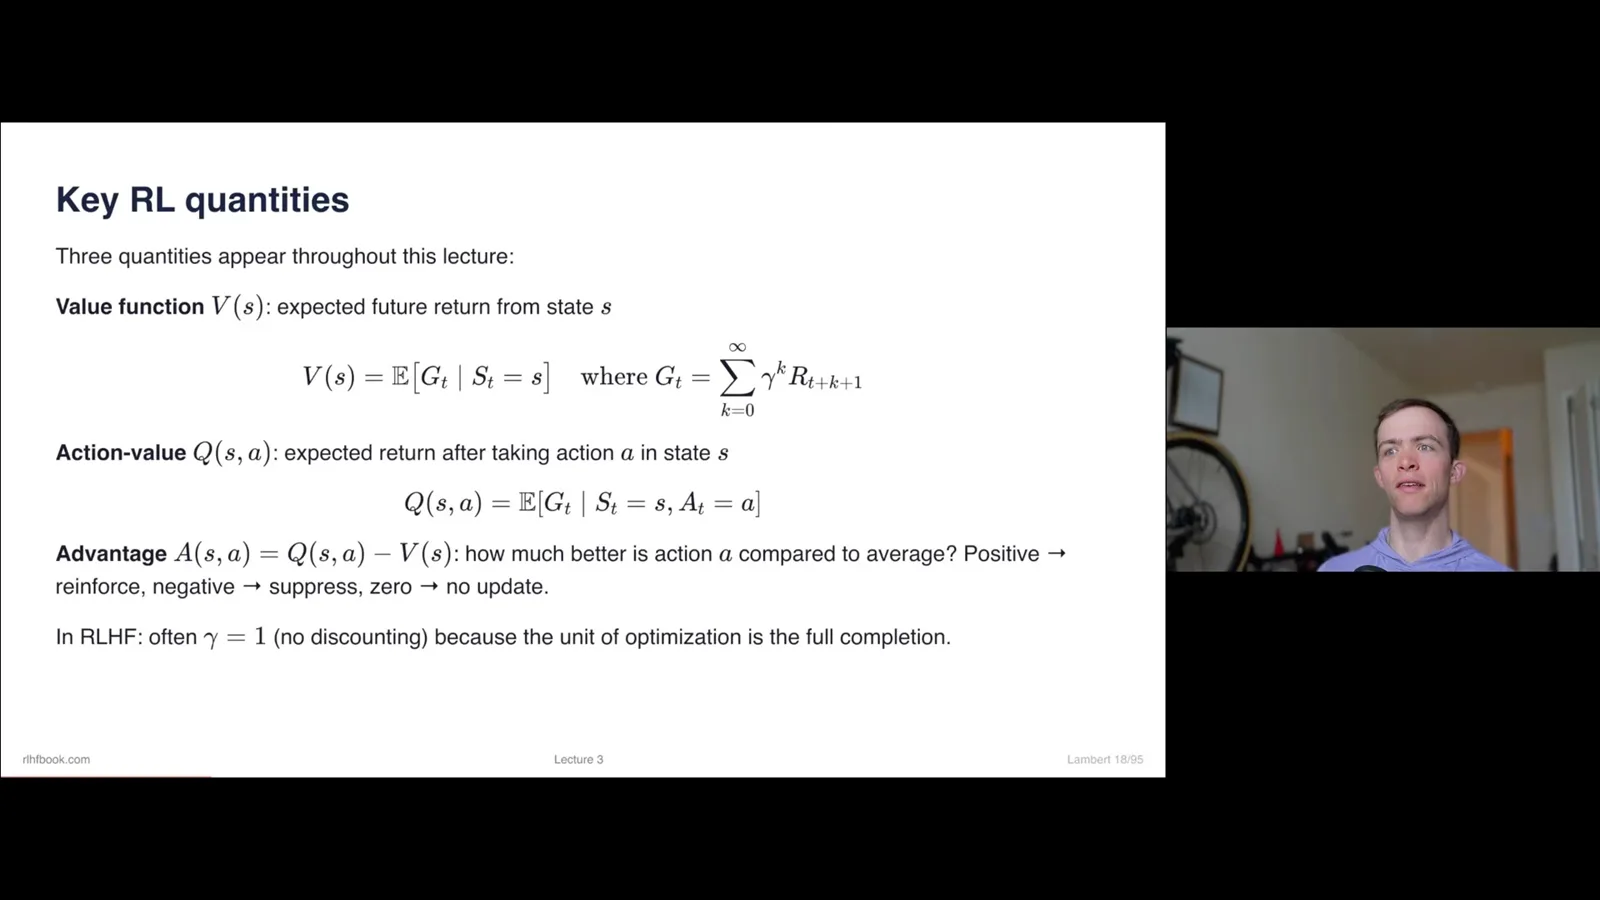
Possible weighting signals include total trajectory return, future return, a baseline-adjusted return, action value and temporal-difference estimates. They have different bias, variance and computation tradeoffs, depending on the estimator and implementation.
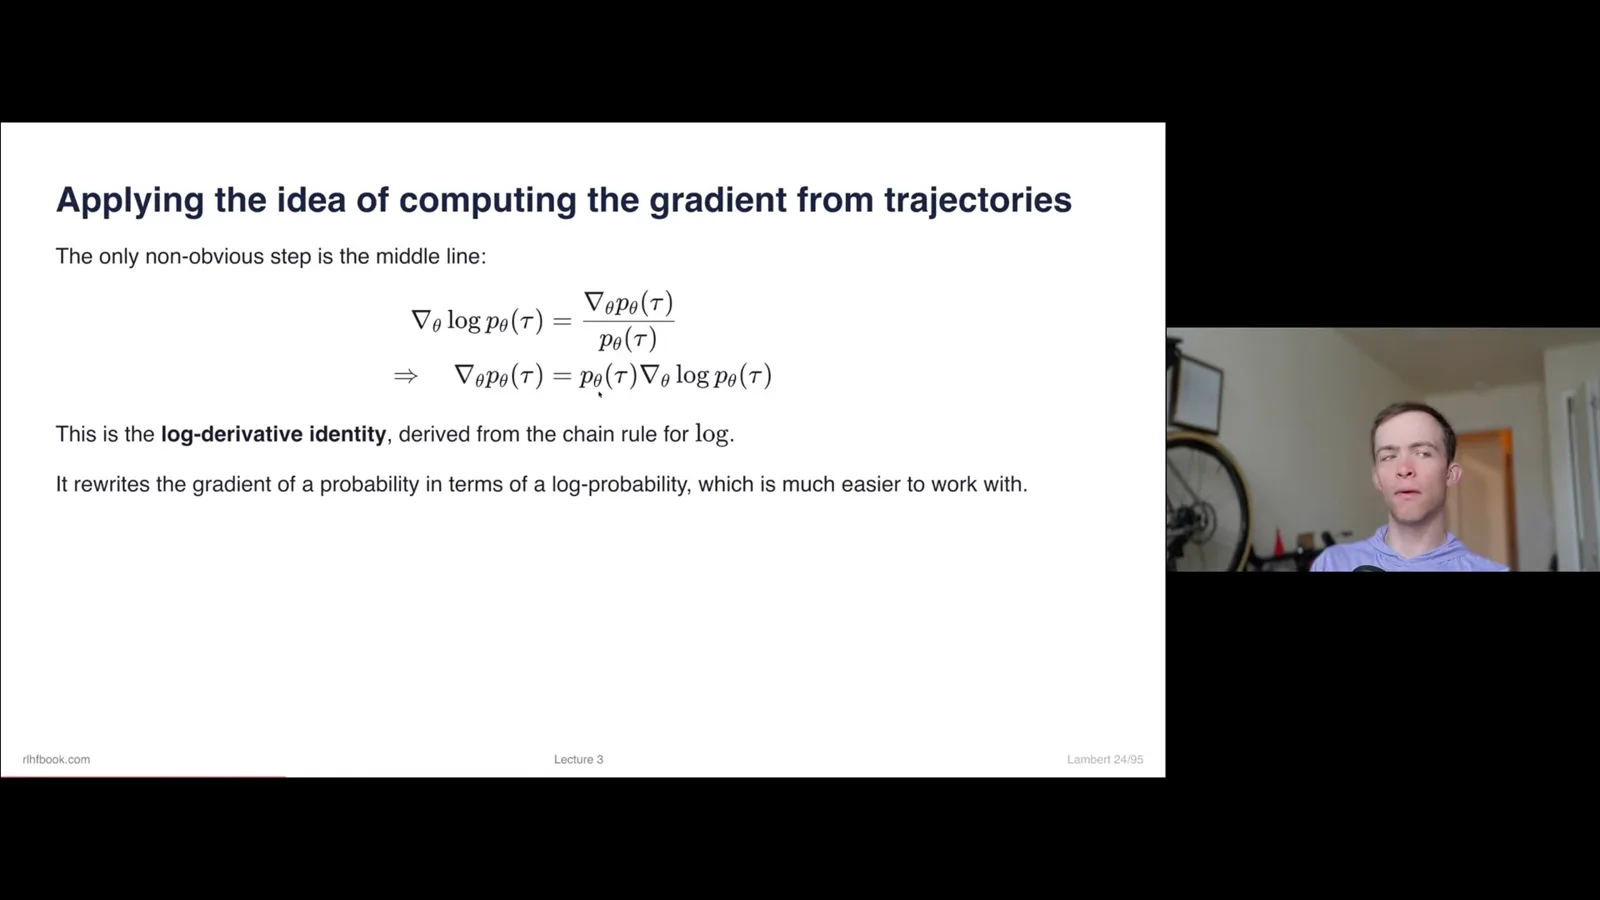
To derive the policy gradient, write expected reward as an integral over trajectories and differentiate with respect to policy parameters. Directly manipulating the gradient of the trajectory distribution is awkward, so the derivation uses a log-derivative identity.
The identity rewrites the gradient of a probability as that probability times the gradient of its log. This converts the expression into an expectation that can be estimated with sampled trajectories.
A trajectory probability factors into an initial-state distribution, policy action probabilities and environment transitions. After taking logs and differentiating, terms that do not depend on policy parameters drop out. What remains is a sum of policy log-probability gradients over steps.
In code, log probabilities are summed and weighted by an advantage-like signal; automatic differentiation computes parameter gradients. The gradient is present in the backward pass even if the code does not spell out the theorem term by term.
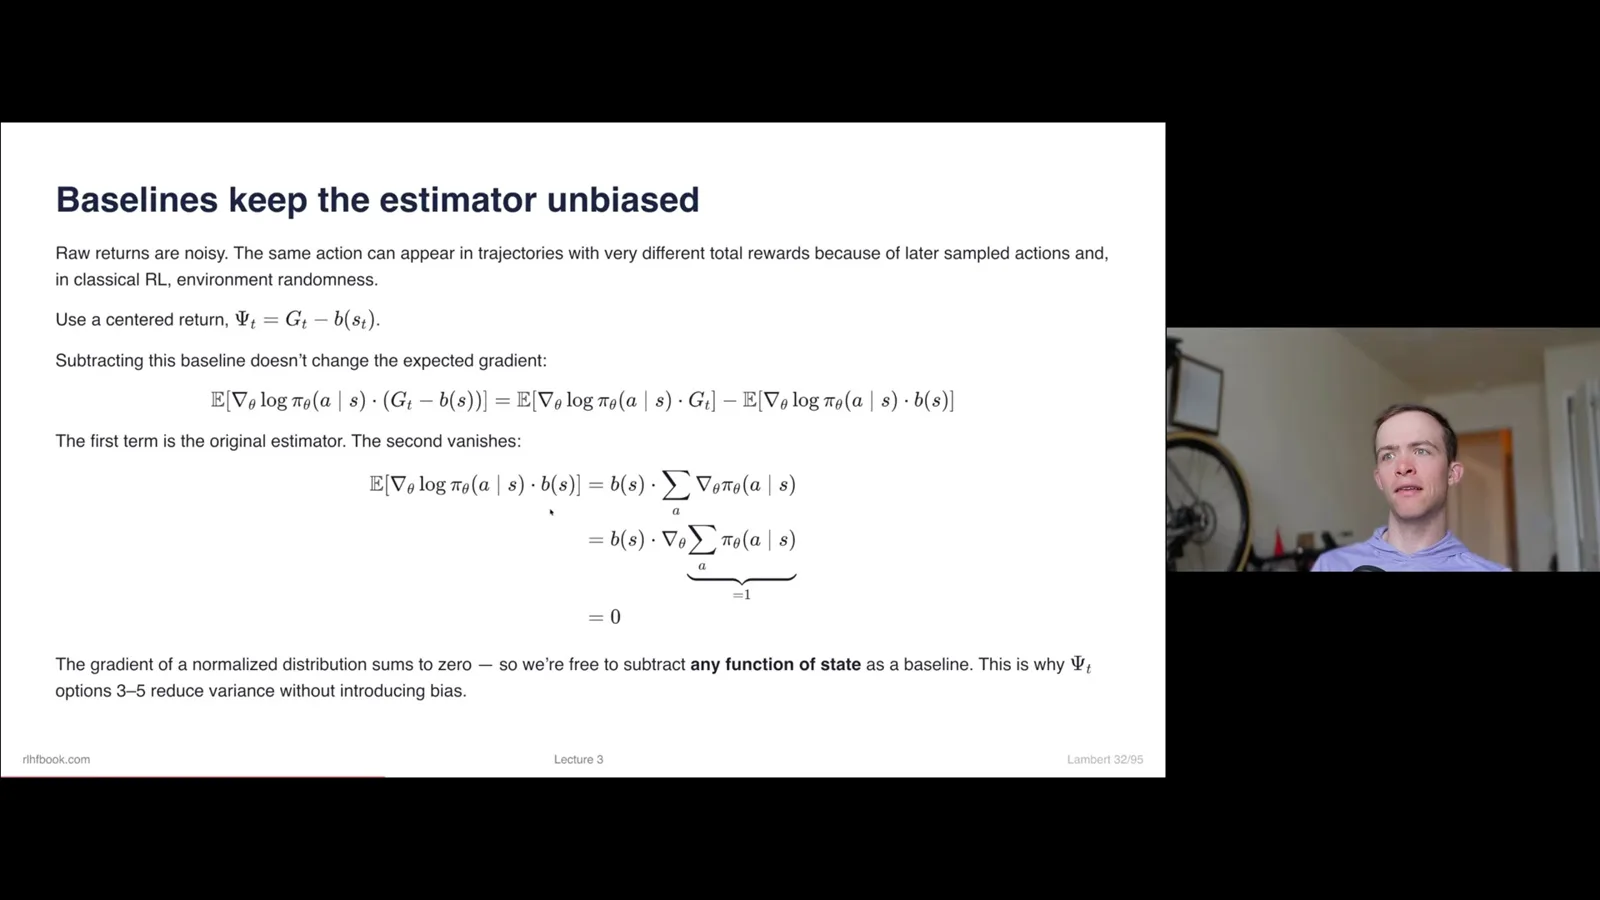
Instead of assigning the whole trajectory return to every action, reward-to-go uses future rewards relevant to each step. A baseline can further reduce variance by centering the return relative to a state-dependent estimate.
An action-independent baseline does not change the expected policy gradient: its contribution averages to zero under the policy. This gives a variance-reduction tool without changing the expectation under the stated assumptions.
RLHF and REINFORCE
Reference-policy regularization and leave-one-out baselines support practical policy updates.
In RLHF, a frozen reference model supplies a KL-based regularization signal against the starting policy. The old policy in PPO is different: it is the policy that generated the current batch. Confusing the batch-level old policy with the run-level reference causes implementation errors.
REINFORCE is a Monte Carlo policy-gradient algorithm: sample trajectories, compute returns and update the policy. Raw returns can be noisy, especially when states in a batch have very different expected values, which motivates a baseline.
REINFORCE leave-one-out samples multiple completions for a prompt. For each answer, the mean reward of the other answers serves as a baseline. This gives a relative signal without training a separate value model.
PPO and value estimation
Clipping permits sample reuse while a value model and GAE estimate advantages. KL regularization serves a separate purpose.
PPO was designed to reuse samples for multiple optimization steps while avoiding overly large policy changes. It compares the current policy’s action probability with the old policy that generated the data, using an importance ratio.
The PPO surrogate objective multiplies the ratio by an advantage and compares it with a clipped version. The clip range, often described using epsilon, prevents further improvement in the objective when an update pushes the ratio too far in the advantageous direction.
For a positive advantage, increasing the action probability helps until the upper clipping boundary is reached. For a negative advantage, decreasing its probability helps until the lower boundary is reached. With zero advantage the contribution is zero.
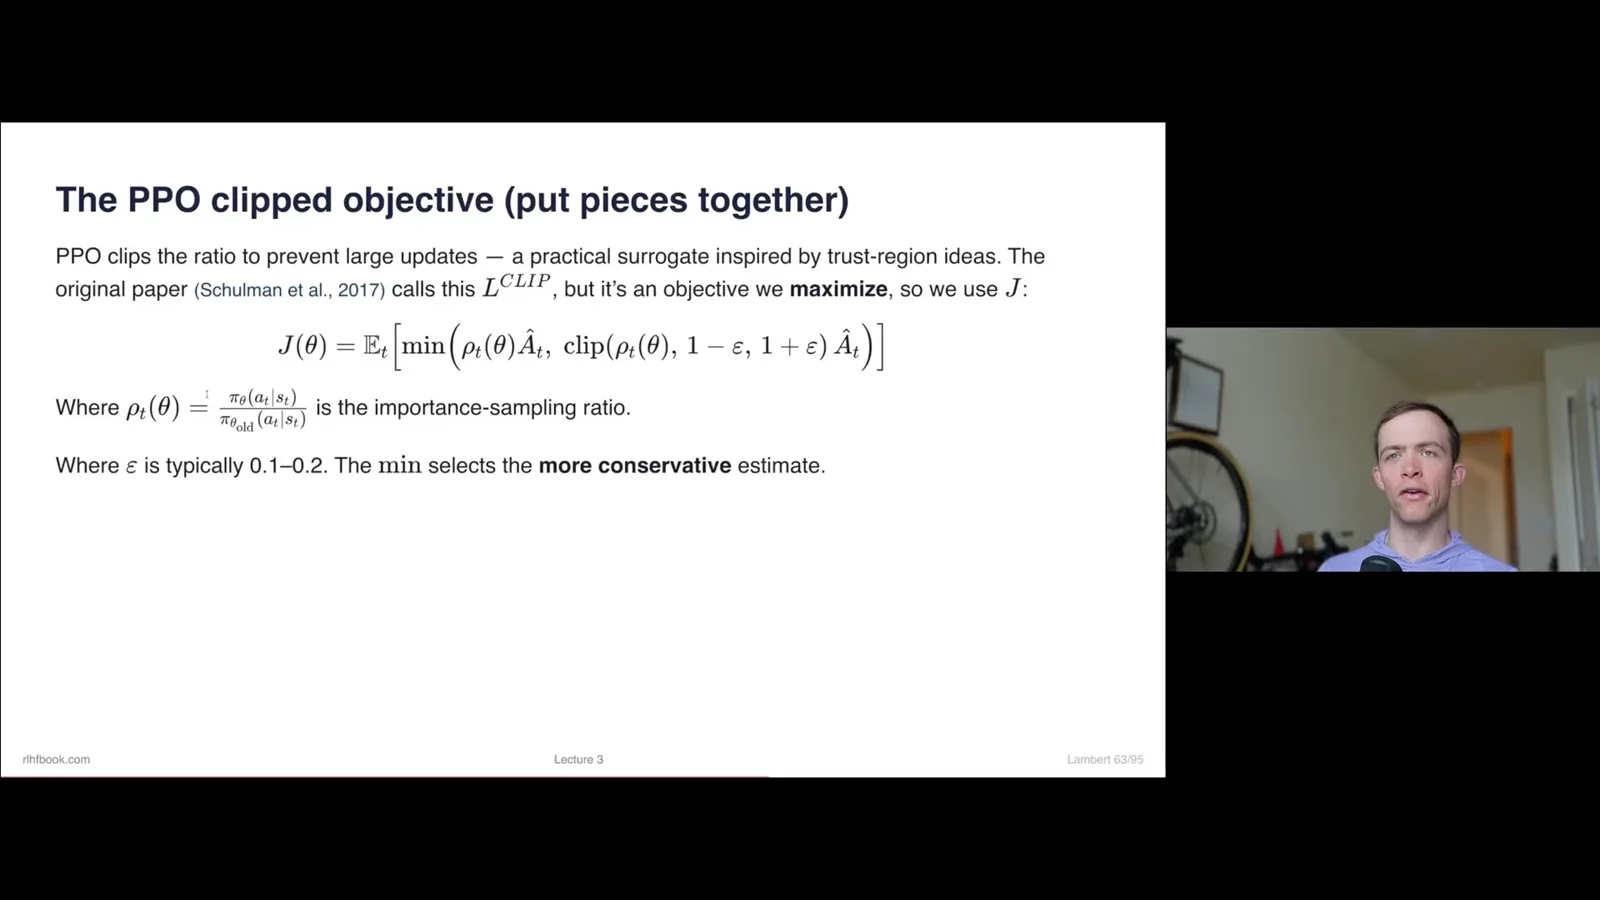
PPO commonly trains a value model alongside the policy. The value estimate serves as a learned baseline and can provide token-level credit assignment, at the expense of extra computation and implementation complexity.
In a typical RLHF implementation, the reward-model score is associated with the completion’s end and a KL term contributes at token positions. Generalized advantage estimation propagates credit backward using the value model.
The temporal-difference residual combines the observed reward, predicted next-state value and current-state value. A one-step estimate can have lower variance than a full sampled return but can be biased when the value model is inaccurate.
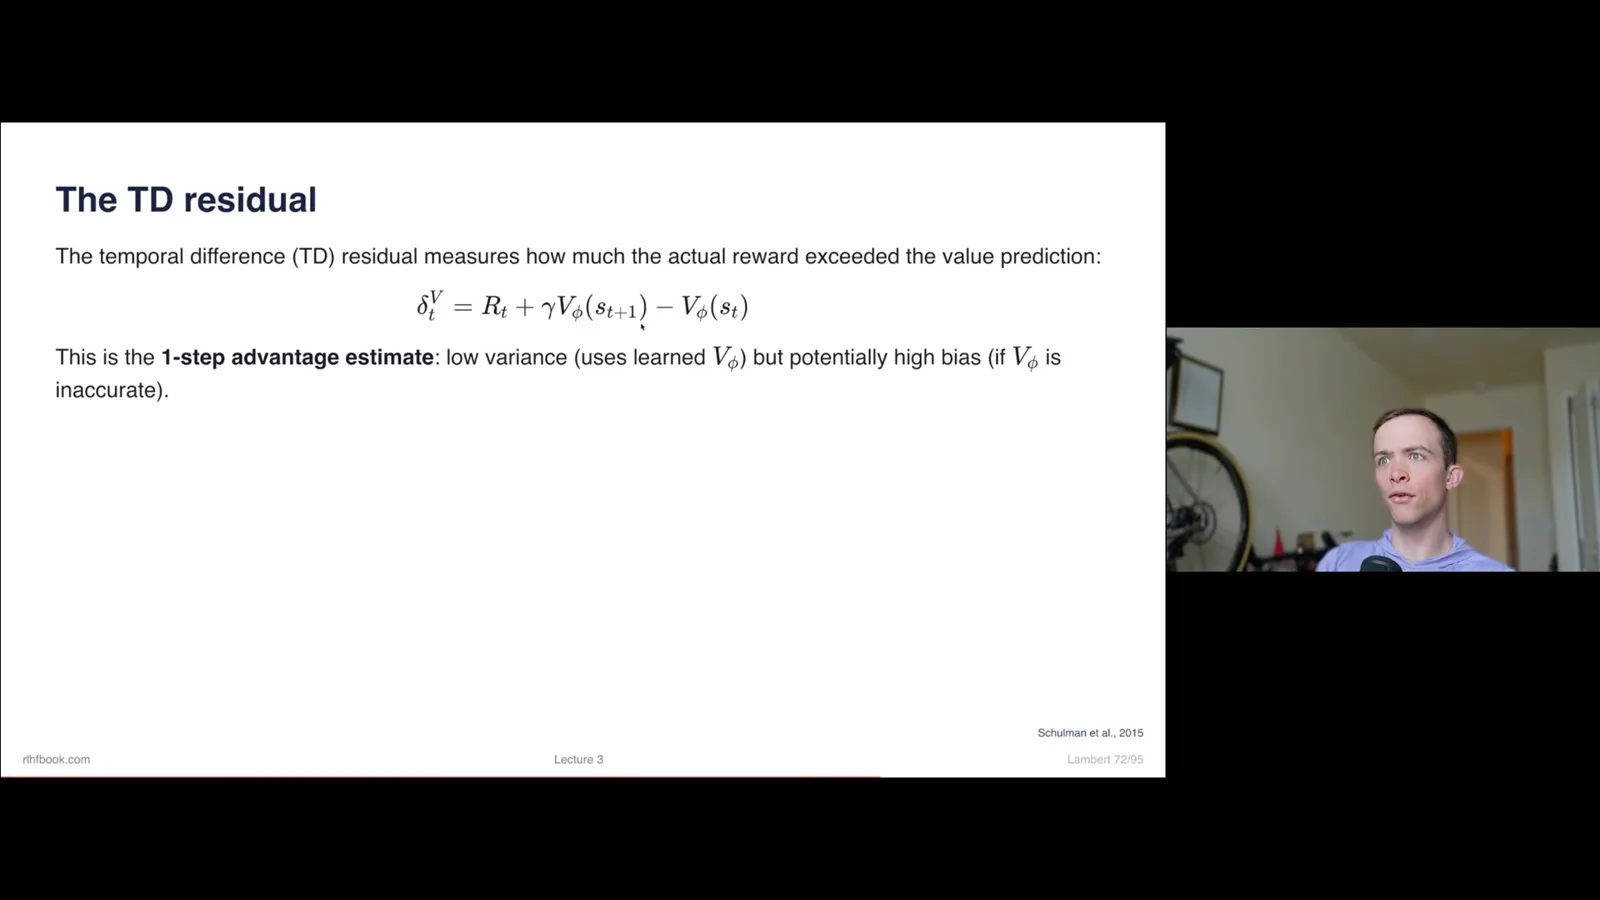
GAE combines multi-step estimates using lambda to balance bias and variance. The discount factor and lambda have different roles: language-model examples often use a discount near one, while lambda can downweight distant residuals.
PPO-style RLHF can contain two distinct controls: clipping within the policy update and a KL penalty relative to the reference. The conceptual loop generates and scores completions, estimates advantages, makes policy and value updates, then repeats.
A full PPO RLHF implementation may keep policy, reference, reward and value models in memory, updating the policy and value models while the others remain fixed. Shared backbones or other engineering choices can change this cost.
GRPO and newer variants
Group-relative advantages avoid a separate critic. GSPO and CISPO alter importance-ratio or clipping behavior.
GRPO retains a PPO-like clipped objective but computes advantages from a group of completions for the same prompt rather than a separate value model. The group mean and standard deviation provide the relative comparison.
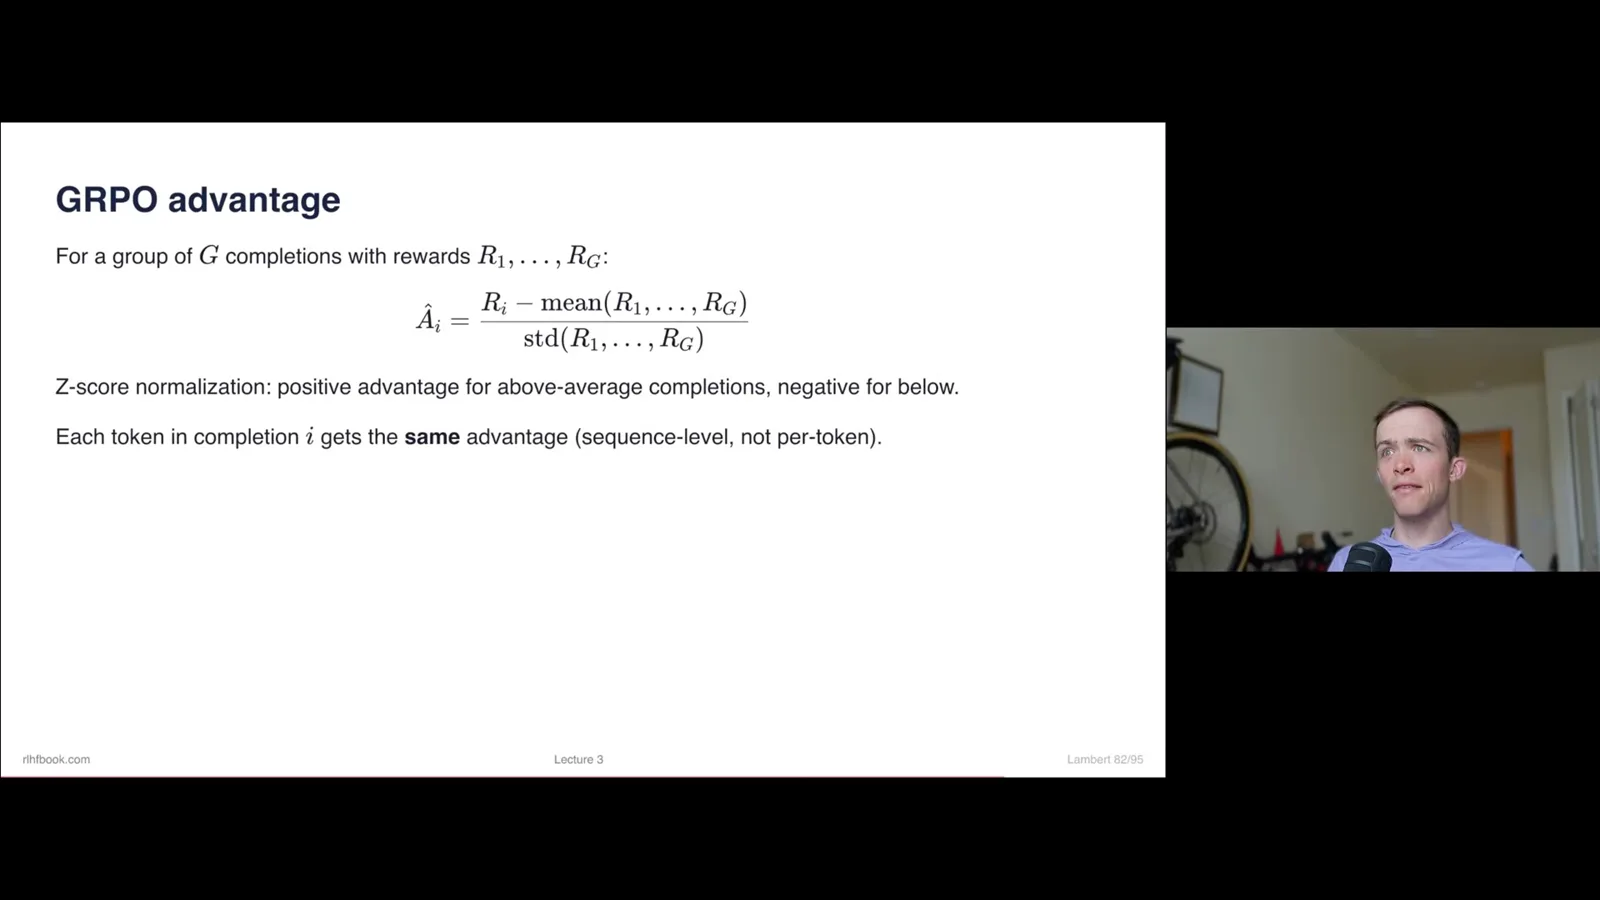
If every completion in a group receives the same reward, its relative advantages are zero and it provides no group-relative learning signal. When rewards vary, the group supplies an inexpensive alternative to a learned critic.
GRPO and REINFORCE leave-one-out are closely related in their use of multiple samples, but their baseline and loss details differ. Default GRPO formulations often put a per-token KL term in the loss rather than shaping rewards as in common PPO RLHF implementations.
GSPO changes the importance ratio to a sequence-level quantity, aiming to improve stability, including in mixture-of-experts models where individual token ratios can fluctuate. CISPO changes how importance weights are clipped while preserving a REINFORCE-like gradient term.
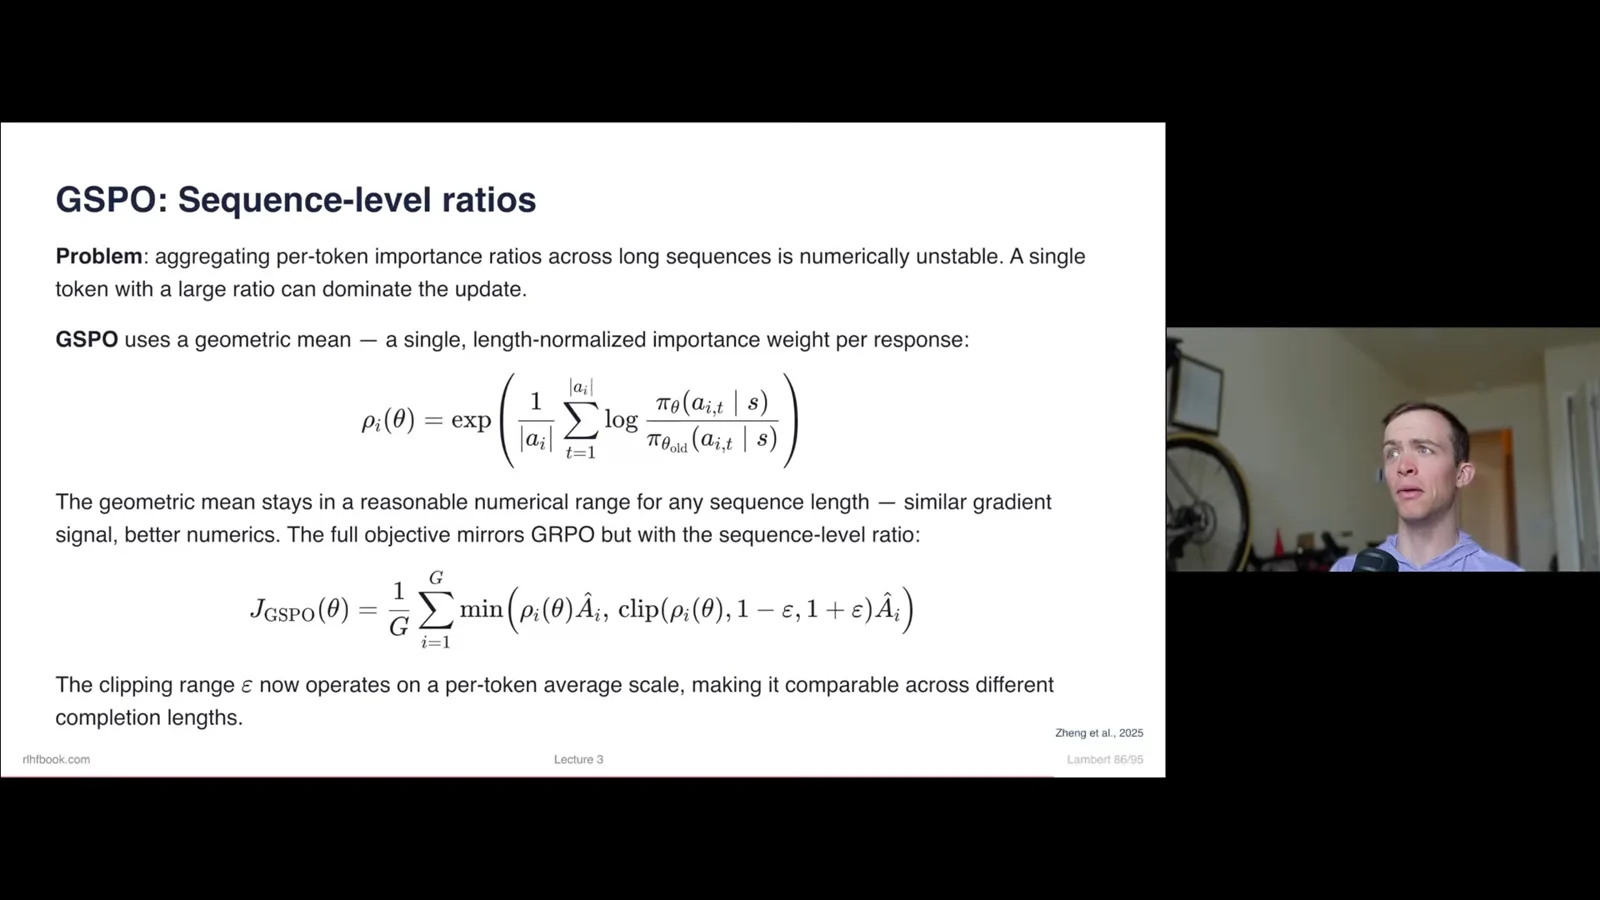
The central lesson is that different algorithms build on the same policy-gradient idea, then change how they estimate advantage, control updates or use samples. Lambert points readers to his RL cheat sheet and code repository; the next lecture works through implementation.
같은 채널의 다른 글
 16:48EN
 Nathan Lambert· 2026년 11월 2일Nathan Lambert on How Open Models Can Compete With Frontier LabsNathan Lambert · Allen Institute for AIOpen models are gaining use and closing capability gaps, but their builders need a sustainable economy and advantages beyond price.
 48:04ENNathan Lambert· 2026년 10월 26일Nathan Lambert on Open Language Models: History, Competition and RiskNathan Lambert · Allen Institute for AIA tour of open weights, research infrastructure, distillation, adoption and the choices facing model developers.
 46:42ENNathan Lambert· 2026년 10월 25일Nathan Lambert and Florian Brand on Kimi K3.1, Cyber Risk and AI AgentsNathan Lambert, Florian Brand · Allen Institute for AIThe Interconnects hosts discuss mixed model evaluations, a wave of security disclosures, and what a personal agent can do in everyday life.
 5:42ENNathan Lambert· 2026년 8월 12일Why the Shoggoth Became a Mascot for AI Post-TrainingNathan Lambert · Allen Institute for AINathan Lambert traces a creature from Lovecraft to a visual metaphor for language models, fine-tuning, and RLHF.
 32:56ENNathan Lambert· 2026년 8월 6일Nathan Lambert: An Introduction to AI Character TrainingNathan Lambert · Allen Institute for AIHow post-training shapes a model’s behavior, from constitutions and model specs to experiments with personality and activation steering.
 32:11ENNathan Lambert· 2026년 8월 5일Nathan Lambert on How Language Model Evaluation Has EvolvedNathan Lambert · Allen Institute for AIFrom few-shot prompts and pass@k to agent sandboxes, noisy scores and benchmark contamination.